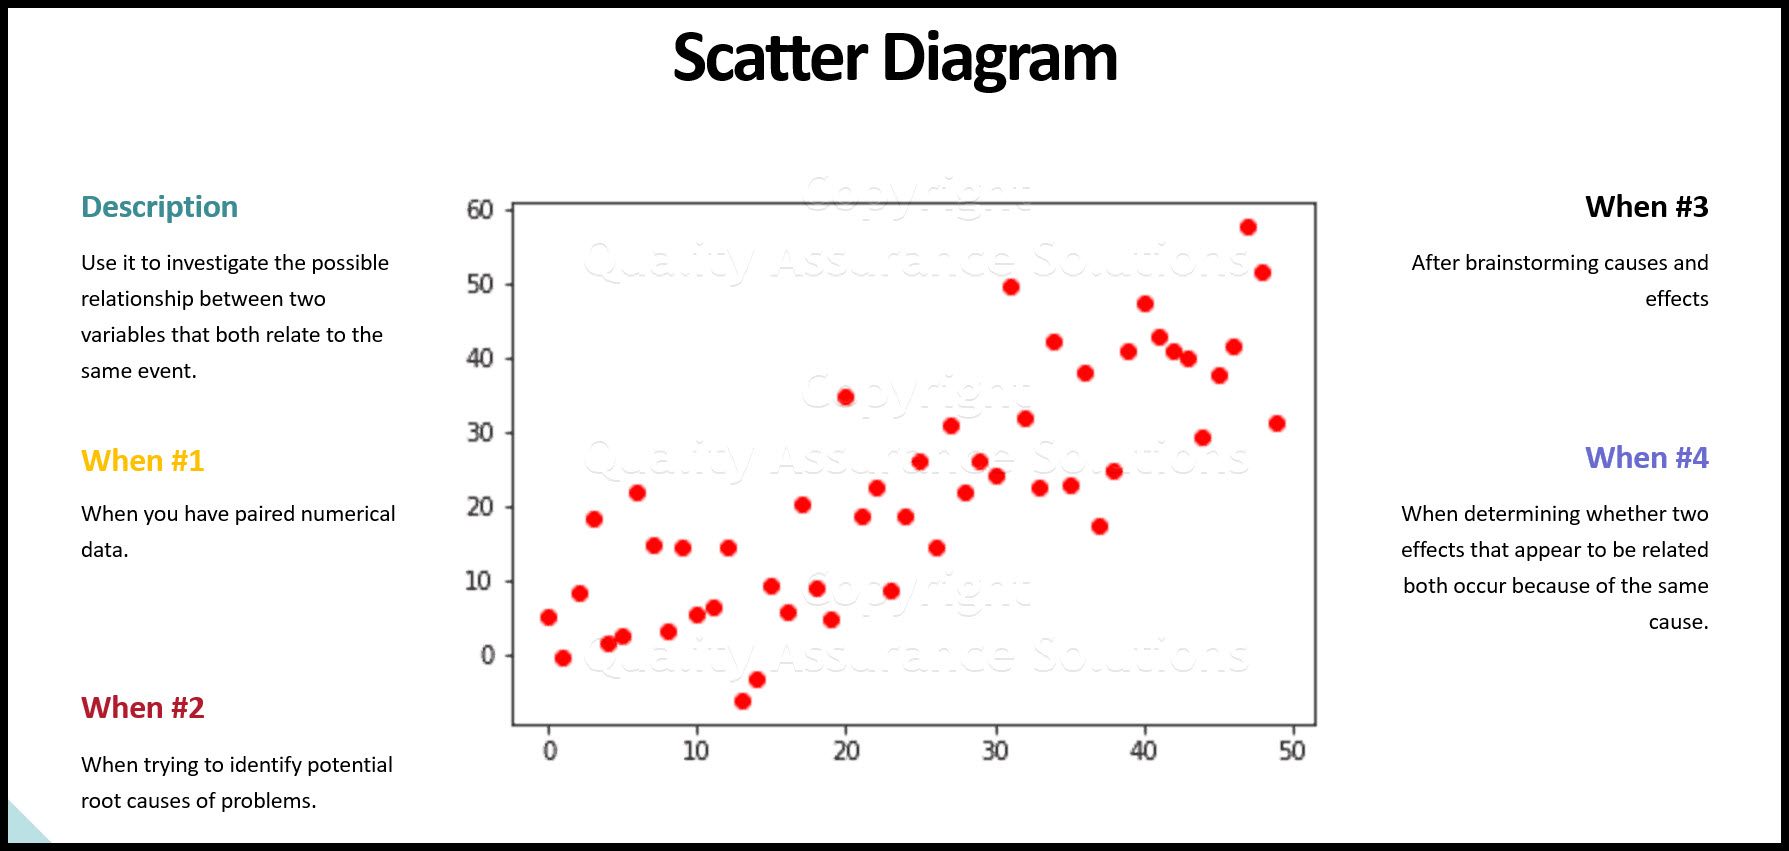
Scatter diagrams are basically point clouds with an agenda.
You put one variable on the horizontal axis and another on the vertical axis, then plot pairs of data as individual dots. That is the entire mechanic. Everything after that is about reading what the dots are trying to tell you, or realizing they are not telling you anything at all. I learned this the hard way in 2019 when I was analyzing latency data for a logistics platform. We had roughly 40,000 delivery records with GPS coordinates, timestamps, and weather conditions. My manager wanted to see if rain intensity correlated with delivery delays. I plotted it out and got what looked like a moderately positive correlation at first glance. Then I zoomed in. The real story was hidden in a small cluster of warehouse entries where our GPS tracker logged stale positions during overnight loading docks. Those points weren't weather-driven at all. They were sensor ghosts. I had to pull the raw event logs, filter out any record where the GPS signal had been held longer than 12 minutes without movement, and replot. The correlation basically vanished once the noise was gone. That experience ruined my faith in "just plot it and see." You always have to interrogate the data before you interrogate the pattern.
How To Make A Scatter Diagram
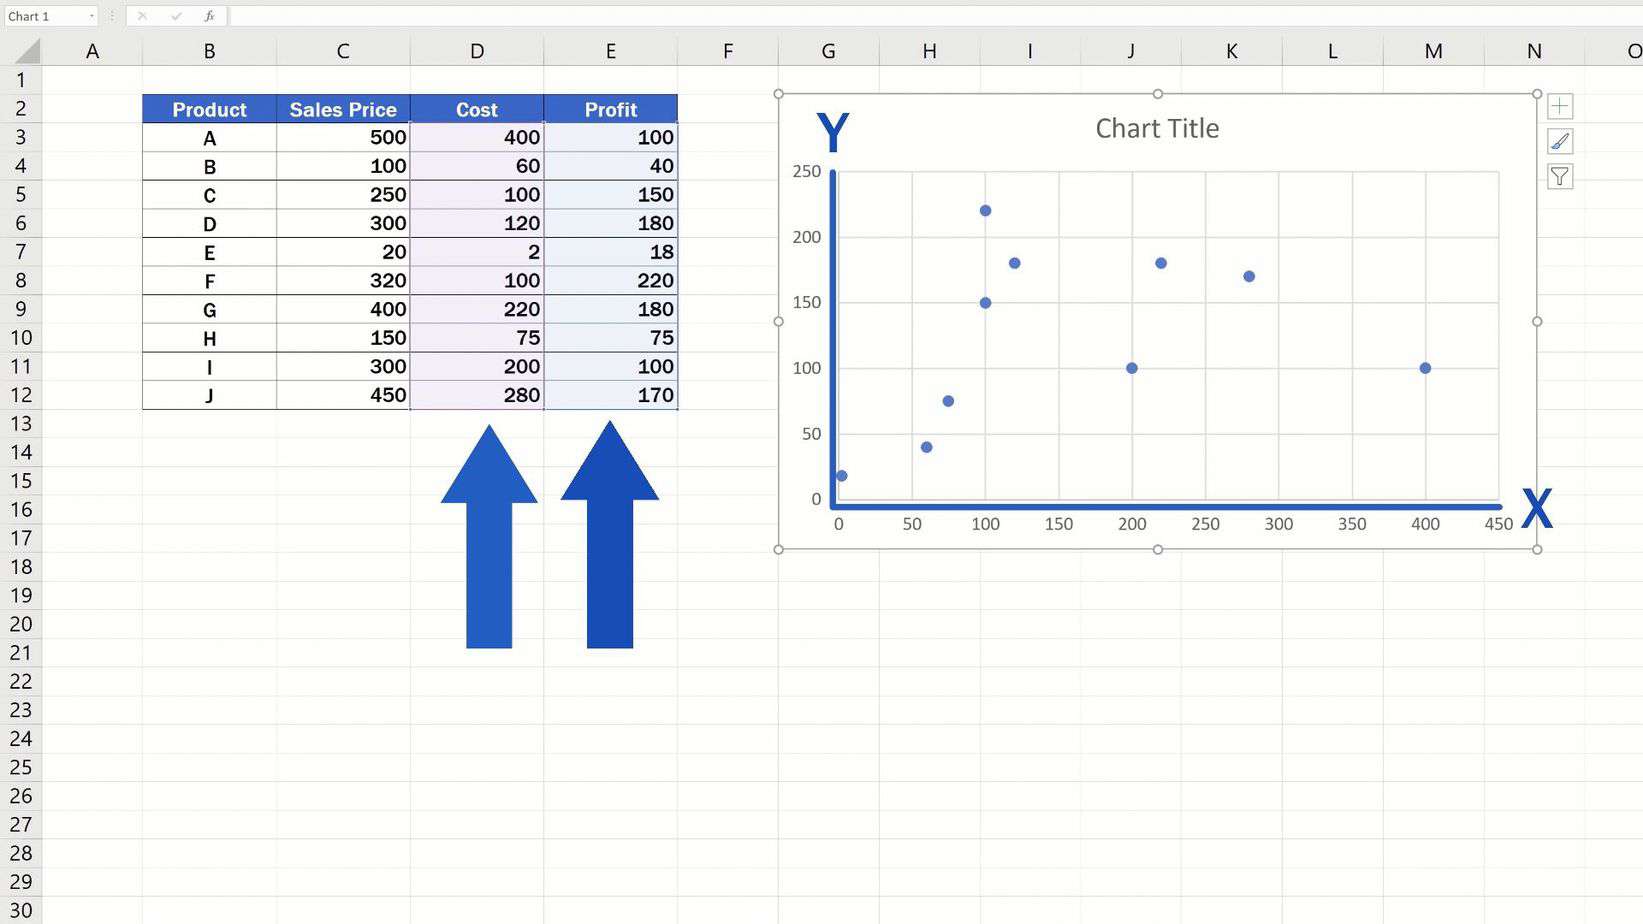
Start by deciding which two continuous variables you actually care about. This is where most people go wrong. They pick whatever columns happen to be closest together in the spreadsheet. Pick based on a causal question, not convenience. Are you trying to understand whether X changes Y, or whether X and Y just move around together? The answer shapes how you interpret the result, and if you pick the wrong pair to begin with, the whole exercise is waste. Once you have your two variables, dump them into a tool. Excel works fine for small datasets up to maybe 5,000 points. Python with matplotlib or seaborn handles anything larger. R is overkill unless you need statistical modeling built in. For quick internal work, I usually just use Google Sheets because it forces you to be fast and you can share the link without sending files around. The actual plotting steps are mechanical. Select both columns. Go to insert chart. Choose scatter. The software will assign the first selected column to the x-axis and the second to the y-axis by default. Verify this. I have spent twenty minutes trying to debug a "weird pattern" only to realize I had accidentally swapped the axes because I selected the columns in the wrong order. Always double-check axis assignment before you start interpreting anything.
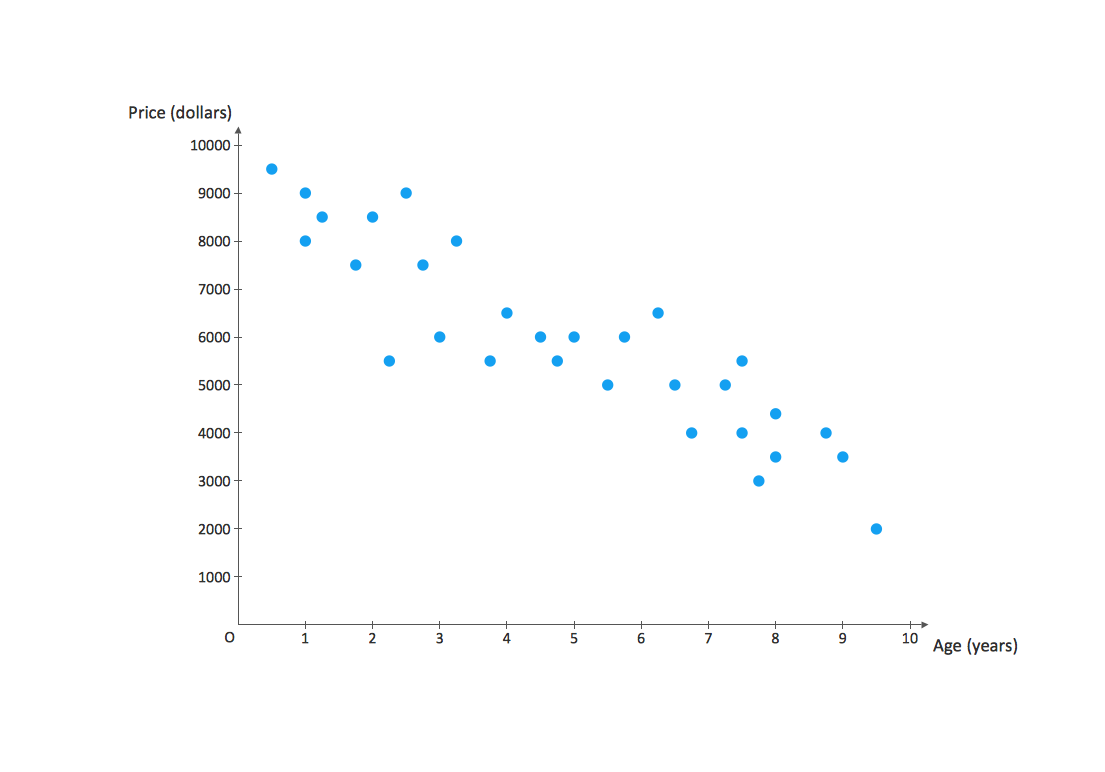
Add axis labels with units. This sounds obvious but people skip it constantly. A scatter plot without labeled axes is just abstract art. Someone looking at it has no way to know whether the x-axis is measuring temperature in Celsius or Fahrenheit, and that distinction completely changes the interpretation. Put the units in the label. Price (USD) is better than Price. Weight (kg) is better than Weight. Here is something most beginners miss. When you have more than about 200 points, scatter plots become useless because the dots overlap and create visual artifacts that look like patterns. This is called overplotting. The dots pile up in dense regions and form dark blobs that your brain interprets as structure, but the structure is an artifact of density, not of the actual relationship. If you hit this, switch to a hexbin plot or a 2D kernel density estimate. These show density rather than individual points. In Python, seaborn's hexbin function handles this in one line. In Excel, you are out of luck and need to export to Python or R. Another counter-intuitive thing about scatter diagrams: correlation does not equal causation is not just a bumper sticker. It is a practical warning. I worked on a project analyzing customer support ticket resolution times against agent seniority. The scatter plot showed a clear negative relationship. Senior agents resolved tickets faster. The intuitive conclusion was that experience makes you faster. The real explanation turned out to be that senior agents get assigned simpler tickets while junior agents handle the complex ones. The ticket complexity variable was completely absent from the plot. This is called confounding. A scatter plot can never show you a third variable that is driving both axes. If you only plot two dimensions, you are intentionally blinding yourself to everything else in the dataset. Always check whether a hidden variable might be responsible for the pattern you are seeing.
Get the Full Details
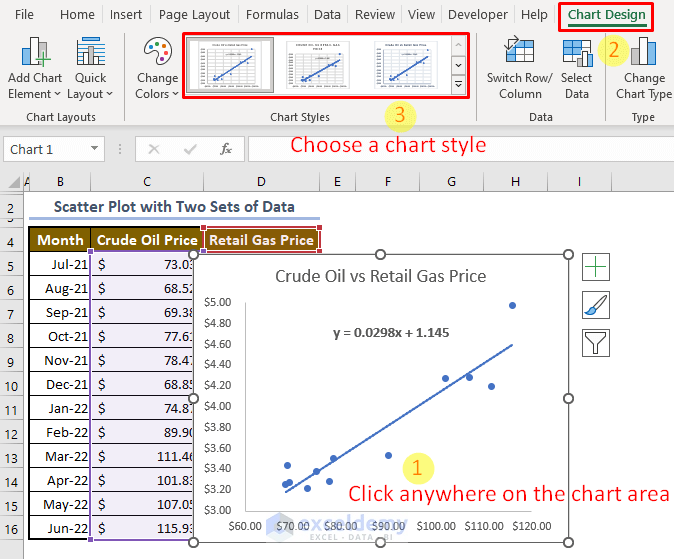
Outliers deserve attention but not panic. A single dot far from the main cluster is not automatically an error. It might be a legitimate edge case that contains the most useful information. I once found an outlier in a regression analysis of server response times that turned out to be a different region with a completely different network topology. Removing it improved the model fit but destroyed its external validity. Flag outliers. Investigate them. Don't delete them unless you have a documented reason. For trend lines, add a linear regression line if the relationship looks approximately linear. Most plotting tools have a built-in option for this. But look at the residuals first. Fit a line, then look at how far each point sits from that line. If the residuals show a clear curved pattern, your linear model is wrong and the trend line is misleading. A curved relationship plotted with a straight line creates the illusion of a weak correlation when the actual relationship is strong and nonlinear. In that case, try a polynomial trend line or transform one of the variables. Log transforms are common for exponential relationships. Square root transforms help with count data. There are real limitations to scatter diagrams. They only handle two variables at a time. If you need to include a third dimension, you either add color coding or size encoding to the dots, which works up to a point and then becomes visually noisy. You can use small multiples, which means creating several scatter plots side by side, each filtered by a category. This is more honest than trying to jam three dimensions into one plot. Scatter diagrams also fail when both variables are categorical. If you are working with categories, use a grouped bar chart or a mosaic plot instead. And for time series data, a line chart is almost always the right choice because the temporal ordering matters and dots alone don't convey it.
The whole process from raw data to a readable scatter diagram typically takes me about 20 to 40 minutes for a clean dataset. If the data needs cleaning first, which is most of the time, it can stretch to two or three hours. The plotting itself is rarely the bottleneck. Finding the right variables, cleaning the outliers, checking for confounders, and deciding whether a scatter diagram is even the right visualization for the question at hand is where the time goes. If you want a tool recommendation beyond Excel and Python, Plotly is worth looking at. It produces interactive scatter plots where you can hover over individual points to see their values, zoom into regions, and filter dynamically. This interactivity changes how you explore data compared to a static image. You catch patterns faster because you can drag a selection box around a cluster and immediately see the data behind it. The free tier handles datasets up to a few million rows, which covers most use cases. The core principle is simple. A scatter diagram shows you the relationship between two continuous variables as a cloud of points. Your job is not to make the plot. Your job is to figure out whether the cloud means anything, whether it means what you think it means, and whether there is a third variable you failed to account for. Everything else is just tool configuration.