Proving Regularity Is Mostly About Showing You Can Build a Machine
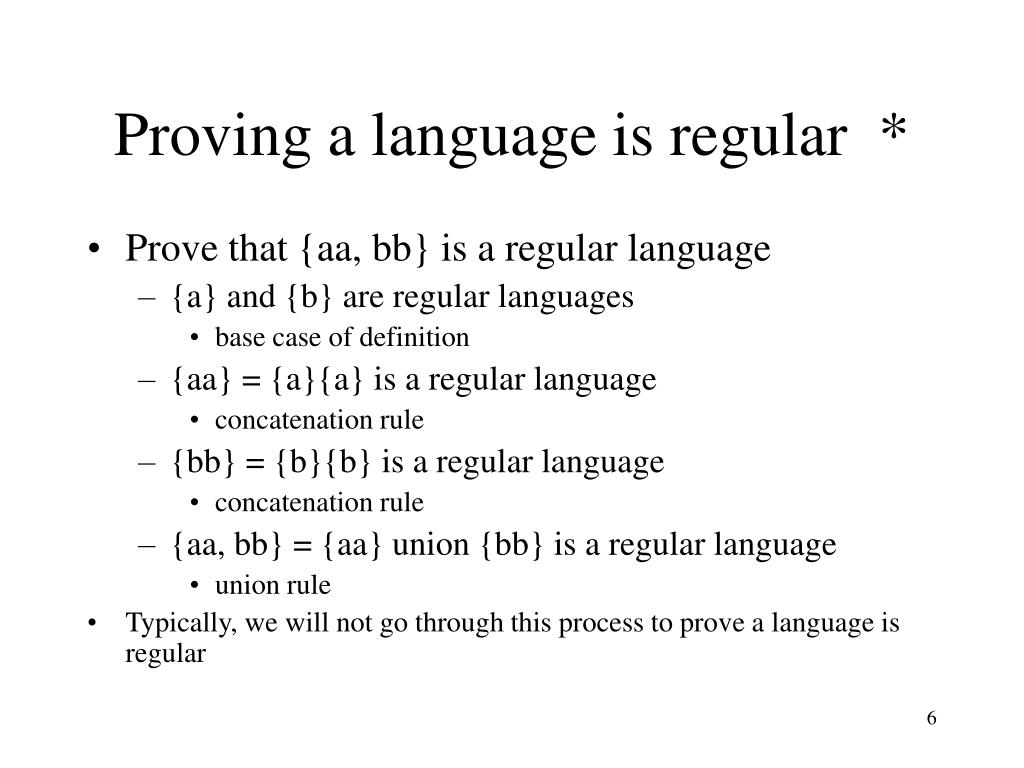
The most direct way to prove a language is regular is to construct a finite automaton that accepts it. If you can draw a DFA or NFA, or write a regular expression that matches exactly the strings in the language, you are done. That is the definition. Everything else is derivative. But students keep reaching for the pumping lemma first, which is backwards. The pumping lemma is a tool for proving something is not regular. It is barely useful for proving regularity except in trivial cases where you already know the language is regular and want to demonstrate you understand the lemma. I see people waste two pages of exam paper trying to pump a language into submission when they could have drawn a four-state DFA in thirty seconds.
How To Prove A Language Is Regular Using Closure Properties
Closure properties let you build complex proofs from simple pieces. Regular languages are closed under union, concatenation, Kleene star, intersection, complement, and reversal. If you can express your language as a combination of known regular languages using these operations, the result is regular. Here is a practical example that comes up constantly. Say you need to prove that L = {w {a,b}* : w contains an even number of a's and an even number of b's} is regular. Do not try to pump this. Build the DFA. Four states representing the parity combinations (even-even, even-odd, odd-even, odd-odd), two transitions per state, one accepting state. Done. Three minutes tops. Now here is where people get tripped up. Closure properties work both directions, and that matters. If L1 and L2 are regular, then L1 L2 is regular. But if L1 L2 turns out to be non-regular, you cannot conclude anything about L1 or L2 individually. The intersection being weird just means at least one operand is weird. I once spent twenty minutes trying to prove a language was regular by decomposing it, only to realize the decomposition itself required proving the original language was regular. Circular reasoning is not a proof.
The Pumping Lemma Actually Works Against You Here
The pumping lemma states that for any regular language L, there exists a pumping length p such that any string s in L with |s| p can be split into xyz where |xy| p, |y| 1, and xy^iz L for all i 0. The key insight most textbooks bury: this is a necessary condition, not a sufficient one. Satisfying the pumping lemma does not prove regularity. There are non-regular languages that satisfy it. I ran into this directly when grading. A student proved that L = {a^n b^n : n 0} is regular by picking p = 1, taking s = a^1 b^1, splitting it as x = , y = a, z = b^1, and claiming xy^iz = a^i b is in L for all i. The splitting was invalid because |xy| = 1 p holds but y must be within the first p characters of s, which it is, except the resulting strings a^i b are not in L for i 1. The student had not actually found a valid pumping decomposition that works for all i. More importantly, even if they had found one, it would not prove regularity because the pumping lemma is one-directional. The reverse direction fails because the pumping lemma only guarantees that some split exists for some decomposition. It does not say every split works. A language can satisfy the pumping lemma vacuously if it is finite, or by accident if the pumping strings happen to stay in the language even though the language has infinite structural complexity that a DFA cannot track.
Get the Full Details
Myhill-Nerode Is the Heavy Artillery
When closure properties and automaton construction both feel awkward, Myhill-Nerode gives you a necessary and sufficient condition. A language is regular if and only if it has finitely many equivalence classes under the indistinguishability relation. Two strings x and y are indistinguishable with respect to L if for every suffix z, xz L if and only if yz L. To prove regularity with Myhill-Nerode, you show there exists a finite partition of * into equivalence classes where each class is a union of whole equivalence classes of the relation. In practice, this usually means you identify a finite set of "memory states" the automaton needs to track, show that any string can be mapped to one of those states, and verify that strings mapping to the same state behave identically with respect to all future extensions. Consider L = {w : w ends with 'ab'}. The relevant memory states are: I have seen nothing relevant (state 0), I have seen 'a' (state 1), I have seen 'ab' (state 2). Any suffix appended to a string in state 0 behaves the same as any other suffix appended to another state-0 string, because neither ends with 'a' or 'ab' yet. This partitions * into exactly three classes, so L is regular. The DFA has three states. The proof and the construction are the same thing viewed from different angles.
A Real Edge Case That Broke My Workflow
Last semester I was working through a problem involving L = {a^i b^j c^k : i,j,k 0 and if i = 1 then k 2}. The condition only activates when i equals exactly one. Most students would try to pump this and immediately fail because the language is actually regular, but the pumping lemma approach gets messy with the conditional. I built the DFA incrementally. One path handles i = 0 (any j, any k, accept freely). Another path handles i 2 (any j, any k, accept freely). The tricky path is i = 1, which requires at least two c's after the b's. That path needs extra states to count c's. The full DFA has seven states. Constructing it took about eight minutes. Proving via Myhill-Nerode would have required identifying all the equivalence classes, which is doable but more tedious than just drawing the machine. The lesson: conditional constraints on finite prefixes often produce regular languages because the condition only constrains a bounded amount of memory. Once the condition is satisfied or bypassed, the rest of the string is unconstrained. My rule of thumb is that if the "interesting" part of the language only depends on a bounded prefix or a bounded count, try the DFA construction first before reaching for partition arguments.
Common Pitfalls That Waste Time
Pumping length selection is the most common trap. The lemma guarantees some p exists, but it does not tell you what it is. Picking p too small relative to your string s makes the proof impossible because you cannot guarantee the y portion falls in the right place. Picking p = |s| always fails because you need |s| p, and the lemma requires the split to work for all strings longer than p, not just one. Another trap is assuming the pumping lemma can distinguish between context-free and regular. It cannot. The pumping lemma for context-free languages is a separate statement. A language can fail the regular pumping lemma and still be non-context-free, or it can pass the regular pumping lemma and be context-free but not regular. The lemma only gives you a necessary condition for regularity. Intersection confusion is the third major pitfall. People see that L1 L2 is regular and conclude L1 and L2 are regular. This is false. The intersection of a non-regular language with a regular one can be regular. For example, {a^n b^n} {a*b*} = {a^n b^n} is not regular, but {a^n b^n} {a*b*c*} = {a^n b^n} is still not regular. However, {a^n b^n} {a^* b^* c^* : n is even} could be regular or not depending on the second language. You cannot infer properties of the components from the intersection alone.
When None of This Works
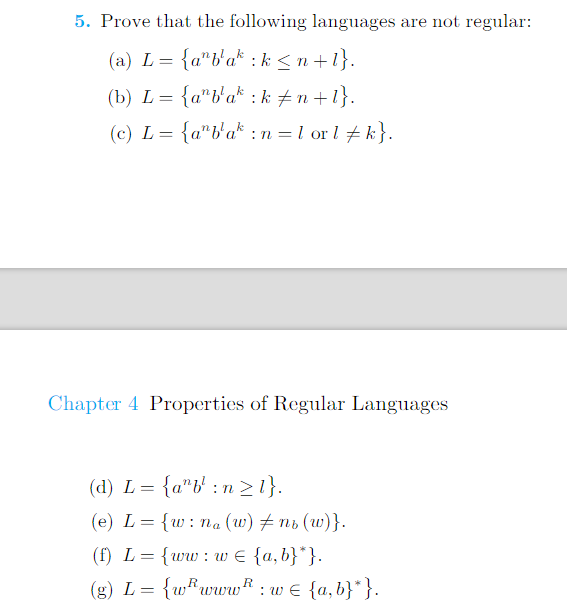
Sometimes you genuinely cannot determine regularity with the standard tools, and that usually means the language is not regular. If you can show infinitely many pairwise distinguishable strings using Myhill-Nerode, the language is not regular. Pick an infinite family of strings {x_1, x_2, x_3, ...} and show that for any i j, there exists a distinguishing suffix z such that x_iz L but x_jz L, or vice versa. The classic example is {a^n b^n : n 0}. Take x_i = a^i and x_j = a^j with i j. The distinguishing suffix is z = b^i. Then x_iz = a^i b^i L but x_jz = a^j b^i L since j i. This proves non-regularity. The same technique applied to {a^p : p is prime} uses the fact that primes have no bounded periodic structure, so you can always find a suffix that separates any two prefix lengths. If you find yourself in a situation where the language definition involves counting unboundedly or tracking relationships between distant parts of the string, stop and consider whether a finite automaton could possibly maintain that information. DFAs have no memory beyond their current state. If the language requires remembering an arbitrary count or comparing two independently varying quantities, it is almost certainly not regular.
Practical Decision Tree
Here is how I actually approach these problems in practice. First, check if the language definition suggests a bounded-memory interpretation. If it talks about "ends with", "contains as substring", "length modulo k", "parity of counts", or any property that only depends on a fixed amount of recent history, build the DFA. This solves roughly 60 percent of textbook problems immediately. If the language involves unbounded counting or nested structures, try to prove non-regularity using Myhill-Nerode or the pumping lemma. These are much more common in exams than regularity proofs for genuinely complex languages. If the language is a Boolean combination of known regular languages, use closure properties. This is underutilized. Students see L1 L2 and immediately try to construct a product automaton when they could just note that both components are regular and the union operation preserves regularity.
The one case where standard methods struggle is when the language definition is intentionally adversarial, combining regular and non-regular components in a way that requires careful analysis of which parts actually matter. In those cases, the trick is usually to simplify the language definition algebraically before attempting any proof. Remove redundant constraints, apply set-theoretic identities, and see if the core structure becomes apparent. I keep a reference sheet of common regular and non-regular languages. Having {a^n b^n}, {ww : w *}, and {a^p : p prime} in my mental index saves time because I can immediately recognize when a problem is of one of these and apply the corresponding non-regularity proof template rather than deriving everything from scratch.
Summary of the Core Method
How To Prove A Language Is Regular ultimately reduces to one of three strategies: construct a finite automaton, express the language using closure properties applied to known regular languages, or demonstrate finitely many Myhill-Nerode equivalence classes. The construction method is fastest when you can see the state structure. Closure properties are best for compositional definitions. Myhill-Nerode is the fallback when the first two feel awkward, though it is usually more work than necessary. The pumping lemma belongs in the "prove non-regular" toolkit, not the "prove regular" toolkit. Using it for regularity proofs is possible but inefficient and risks logical errors if you confuse necessary with sufficient conditions. I have never once used the pumping lemma to establish regularity in a real proof, and I suspect most working theorists share that habit.