Creating Box Plot.webp)
Understanding Box Plots Without Overcomplicating It
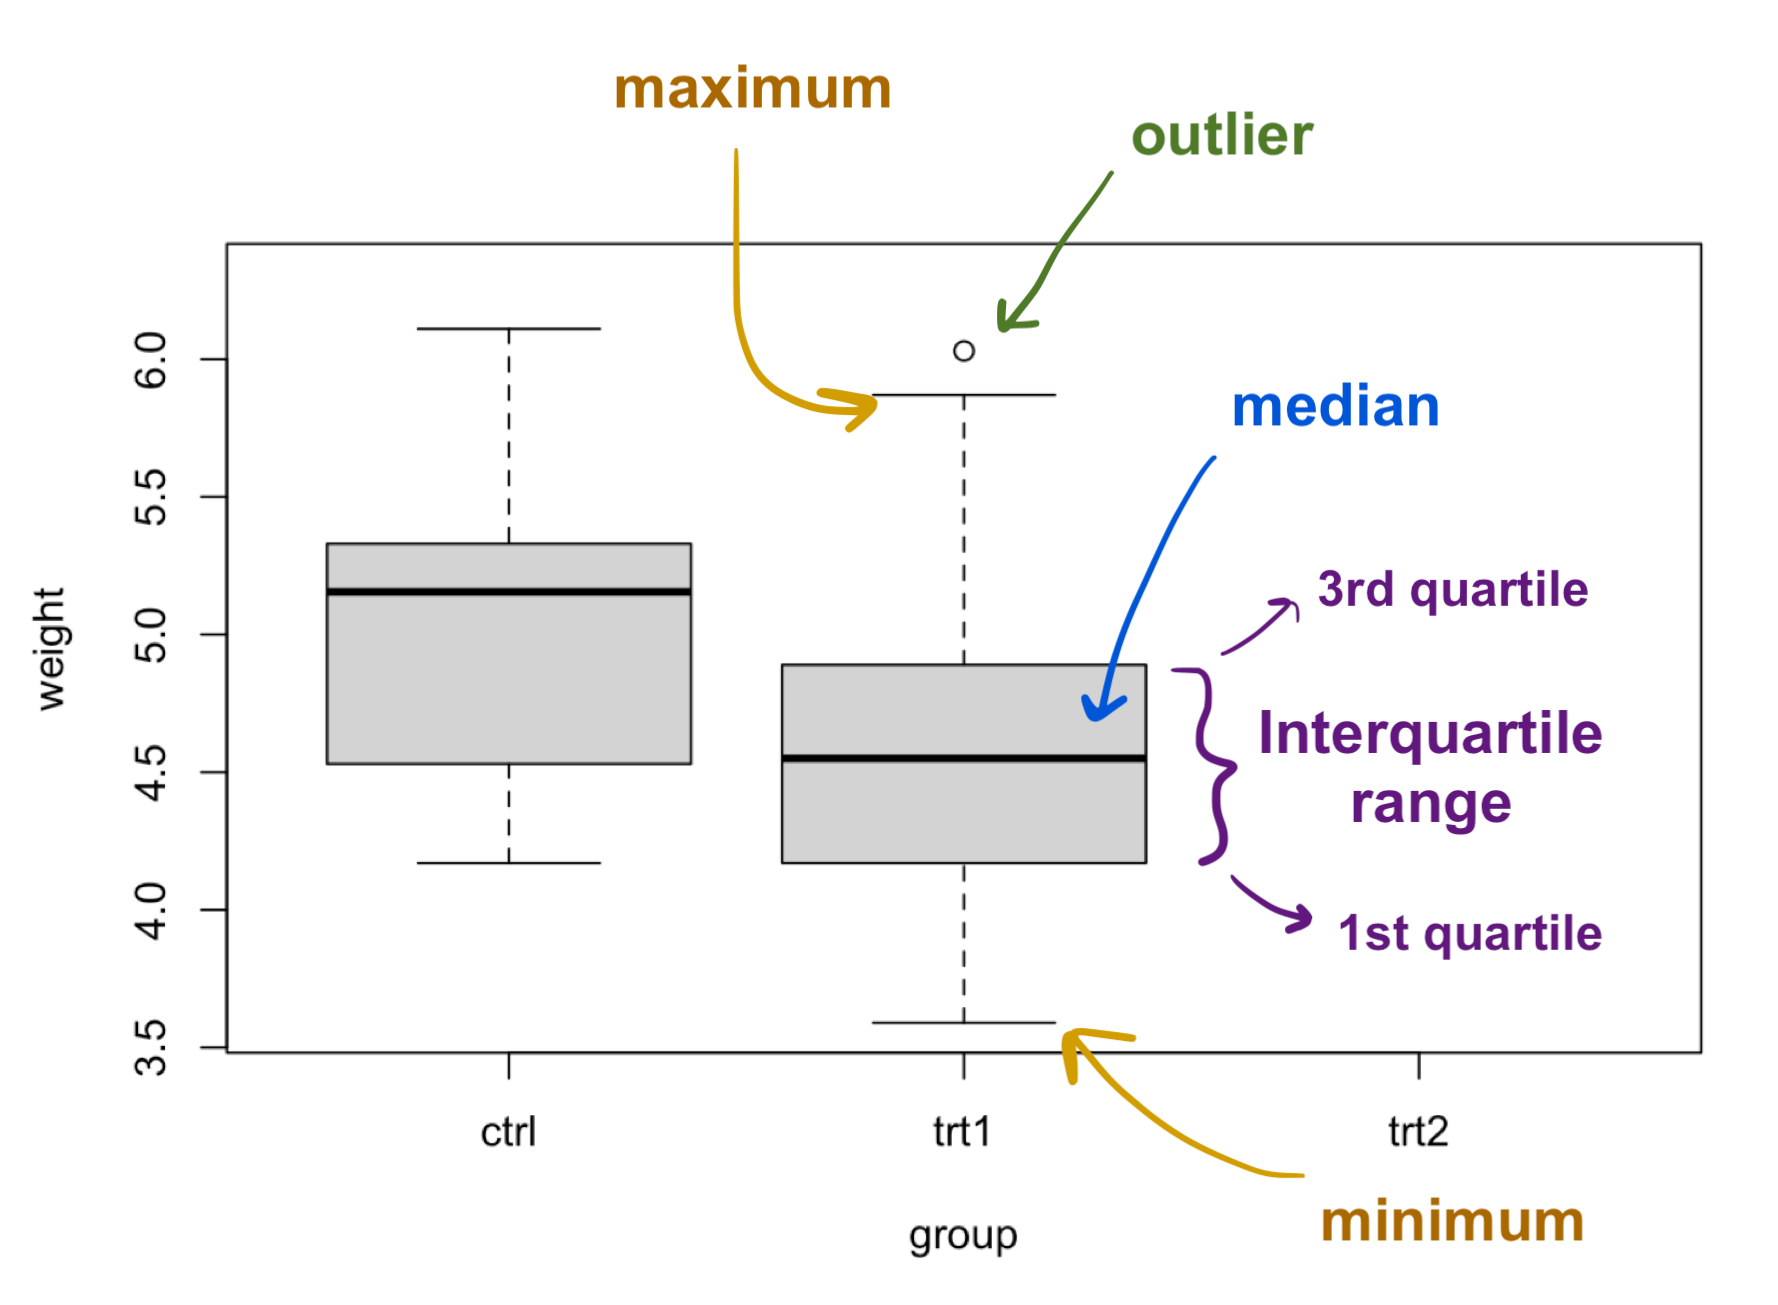
A box plot is a visual summary of a dataset that shows its distribution, central tendency, and spread in a single compact figure. That's about all there is to it. The box itself spans the interquartile range — from the first quartile (Q1) at the 25th percentile to the third quartile (Q3) at the 75th percentile — and a line inside the box marks the median. Whiskers extend from the box to the furthest data points within 1.5 times the IQR on either side. Anything beyond those whiskers is typically marked as an individual point, commonly called an outlier. I remember working on a supply chain project a few years back where we were comparing lead times across three suppliers. The raw data was a mess — thousands of entries with some wild spikes from customs delays and holidays. Plotting histograms for each supplier gave us a general sense, but we couldn't quickly compare their spread and skew across all three at once. A box plot let us see everything in about five seconds: Supplier A had the tightest middle 50% but a huge right tail, Supplier B was symmetrical but wide, and Supplier C was shifted higher overall. That comparison shaped the entire decision. When you're actually reading one, start with the box. A short box means most of your data is clustered tightly between the 25th and 75th percentiles. A long box means there's a lot of variability in the middle. The position of the median line within the box tells you about skew. If it's closer to Q1, the distribution is skewed right — a few large values are pulling the mean upward. If it's closer to Q3, it's skewed left. A centered median suggests something closer to symmetric, though not always — box plots don't show bimodality well, which is a common blind spot.
The whiskers matter too, but people tend to overlook them. They're not showing the full range unless you tell the software not to flag outliers. By default, most tools — matplotlib, R's base plotting, even Excel's quick stats — draw whiskers to the last actual data point within 1.5 * IQR. So a short left whisker paired with a long right one is your signal that the upper end is stretching out. And those individual dots past the whiskers aren't automatically errors or data entry mistakes. Sometimes they're the interesting part. One thing that trips people up constantly: box plots compress information. You can't see the exact sample size from the plot alone unless it's annotated. You can't tell if there's a gap in the data between Q1 and the lower whisker, or if the density is uniform within the box. I've seen analysts interpret a long whisker as "normal variation" when in fact there were only two or three observations out there, making that whisker length misleadingly smooth-looking. Always check the n value. If you're presenting box plots to stakeholders who aren't statistically literate, include a note about the count or use a swarm plot or strip plot overlaid on top. It takes about thirty seconds to add and prevents a lot of misinterpretation. Another nuance — and this one cost me a couple of hours once — is how different software handles the calculation of quartiles. There isn't a single universally agreed-upon method. R has nine different type options for quantile calculations. Python's numpy and pandas default to linear interpolation, which differs slightly from the method Minitab and SPSS use. In most cases the difference is negligible, but when your dataset is small and your quartiles land on actual data points rather than between them, the box can shift noticeably depending on which algorithm you're using. I learned this the hard way when our analysis team in London and our team in Singapore produced slightly different box plots from the same exported CSV. We spent forty minutes debugging what we thought was a data integrity issue before realizing it was purely a quartile calculation method mismatch. Switching both environments to the same method — either R's type 7 or the hyndman-fan method — resolved it immediately. If you're comparing box plots generated by different tools, verify the quartile method before you trust the visual.
When I need a reliable implementation, I reach for Python with seaborn. It's straightforward, and the default style is clean enough for reports without heavy customization. You can pull it from pip and get started within minutes. For people who prefer R, ggplot2 handles box plots well with geom_boxplot(), and you can layer in jittered points to address the sample size blindness I mentioned earlier. Here's a practical example. Say you have monthly customer support response times in seconds for a product team over the past year. You create a box plot and notice the median sits around 4,200 seconds, the box ranges from roughly 3,000 to 6,000, and there's a cluster of outlier points stretching past 12,000 seconds. The median is closer to the bottom of the box, indicating right skew. The lower whisker is short, meaning response times rarely dip below 3,000 seconds, but the upper tail is long and populated. This tells you the team is consistently hitting a baseline speed, but occasionally something — a complex bug report, a missing piece of information from the customer — causes massive delays. The fix isn't to optimize the average; it's to identify and eliminate whatever's causing those 12,000-second outliers. A box plot pointed you at exactly that problem without you needing to scan a thousand individual tickets. Box plots also fall apart in certain scenarios. If you're working with a dataset smaller than about twenty observations, the box plot becomes unreliable. With few data points, the quartiles are unstable, the whiskers collapse, and outliers dominate the visual to the point where the plot stops being informative. In those cases, a simple dot plot or even a ranked list is more honest. Similarly, if your data is heavily multimodal — say, two distinct customer segments with completely different response time distributions — the box plot will flatten both modes into one ambiguous box, hiding the real structure. A violin plot or a faceted histogram would serve you better there.
Get the Full Details

The takeaway is simple: box plots are a quick, effective tool for summarizing distribution shape and comparing groups, but they are not a substitute for understanding your data more deeply. Use them for what they do well, recognize when they're hiding something, and pair them with additional visualizations when the situation calls for it. That's usually enough to get you through most work without overthinking it.