Creating Consistent Toothless Renders for HTTYD 2 Content
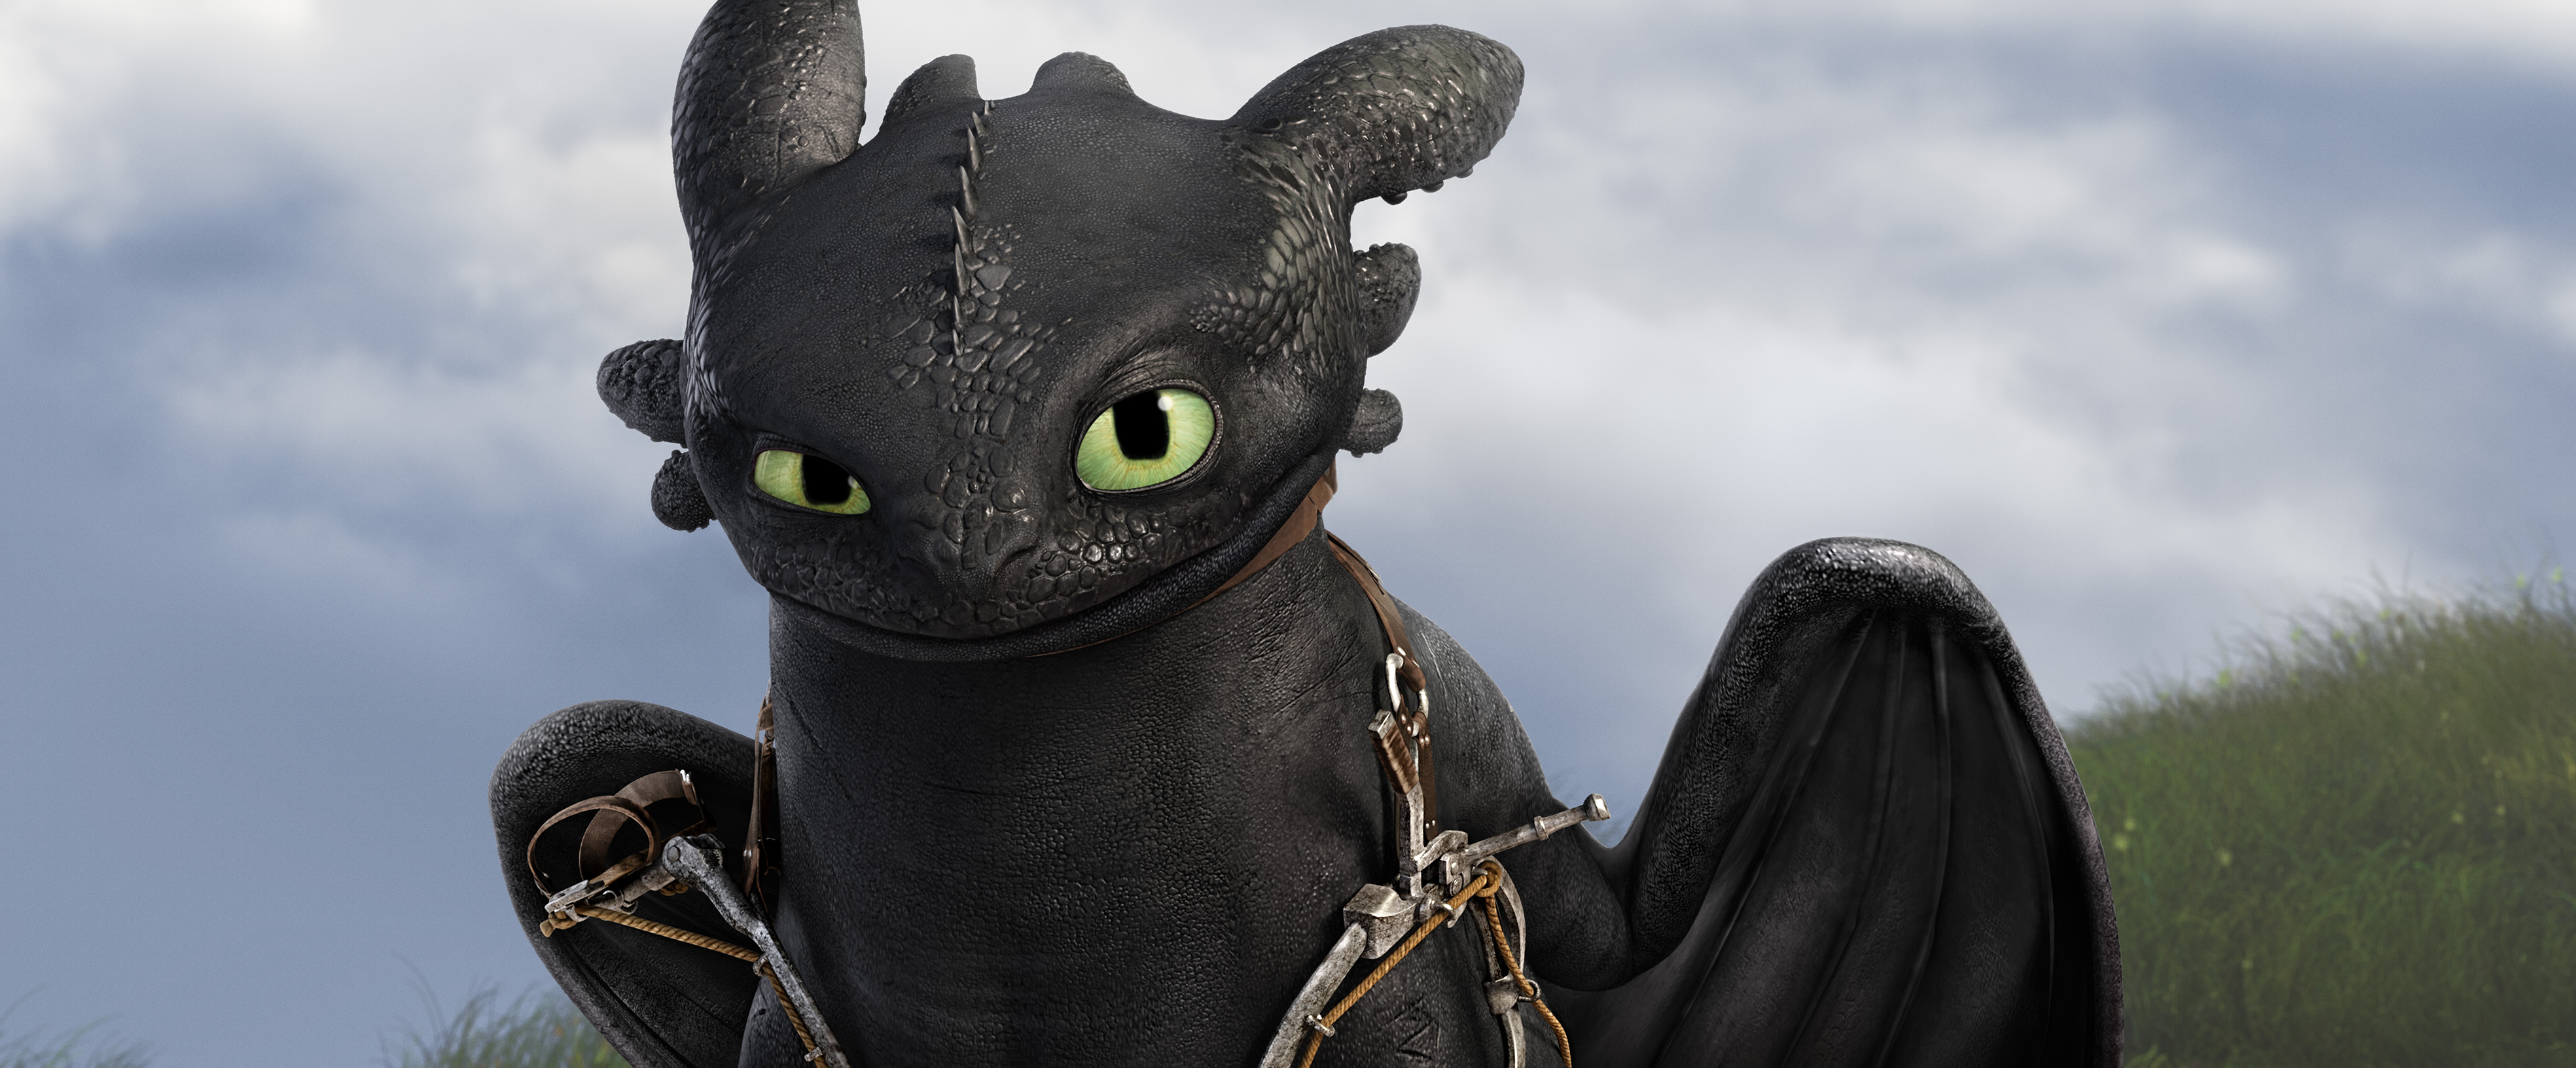
I've spent a lot of time trying to get AI-generated images of Toothless from How To Train Your Dragon 2 to actually look right. Most people just prompt it and accept whatever comes out, but the results are usually garbage - wrong proportions, weird color values, sometimes just a generic dragon. I needed him consistent across multiple shots for a fan project, so I ended up going down a pretty deep rabbit hole. Toothless in the second film has a few distinct design changes from the original. His wing membrane has a slightly more tattered appearance in some shots, his eye color shifts between green and yellow depending on lighting conditions, and his body proportions are a bit larger and more imposing. The sleek black skin should have a subtle blue-purple sheen under certain lighting. Getting these details correct in generation matters because once you introduce inconsistencies, everything downstream falls apart. The most common mistake I see people make is using the same base model they use for general anime or fantasy dragons and hoping the reference will correct it. It doesn't. The foundation matters more than anything else.
My Setup and Approach
I run Stable Diffusion XL locally on a machine with an RTX 4090. For this kind of work, I'd recommend SDXL over the older 1.5 models because the base understanding of character references and lighting is significantly better. You're going to need a decent amount of VRAM either way, though. Here's the workflow I settled on after about three weeks of trial and error: First, I built a small reference dataset of about forty still frames from the movie, mostly close-ups of Toothless's face and full-body shots. I used these to train a LoRA rather than trying to generate from scratch. The training took roughly four hours on my setup. You don't need a massive dataset for character consistency - in fact, more data beyond forty images tends to start blending features from different movies and characters into the output, which is worse than having too little.
The LoRA training settings I used were fairly conservative: resolution set to 512x512 (SDXL handles this fine), learning rate of 1e-4, and about eight hundred training steps. Going beyond that with a small dataset just overfits you into memorization. I also enabled a captioning step using BLIP to auto-tag each image, which saved me maybe three hours of manual caption writing.
Get the Full Details
Loading and Using the Model
Once the LoRA was trained, loading it into your inference pipeline is straightforward. In ComfyUI or any SDXL-based interface, you drop the .safetensors file into your custom_nodes or models/loras directory depending on your setup. The trigger word I used was "th2dragon" - keep this short and unique. Longer trigger words tend to interfere with your base model's understanding of other concepts. When generating, I start with a strength value between 0.6 and 0.8 for the LoRA weight. Below 0.6 and the character starts drifting toward generic dragon territory. Above 0.8 and you get artifacts around the wing edges and the eye area tends to look warped. The sweet spot depends on your base model version too - different checkpoints respond differently to the same LoRA. I usually pair the LoRA with a ControlNet depth map or Canny edge setup when I need specific poses. This is where the process gets finicky. The edge detection often picks up noise from the background in movie stills, so I learned to manually clean up reference frames before running them through ControlNet. Took me about two days to figure that out by brute force.
A Specific Problem I Ran Into
One issue that drove me crazy for a week: whenever I generated Toothless in flight poses, the wing membrane would sometimes fuse with his body or render as a solid mass instead of a translucent pattern. This happened consistently at higher resolutions above 768 pixels wide. The problem wasn't the LoRA - switching to a completely different pose still produced the same artifact at those dimensions. The workaround was generating at 512x768 and then upscaling with a dedicated detailer pass. I set up a UPScale+ section in ComfyUI that first generates the base image at the lower resolution with the LoRA applied, then runs it through a 4x detailer using a separate checkpoint focused on texture fidelity. This added maybe ninety seconds to the total generation time but solved the wing fusion issue completely. The detailer pass also fixed a lot of the smaller rendering problems like claw definition and scale texture.
Pitfalls and Where This Approach Fails
This method works well for static images and simple animations. It breaks down if you're trying to do frame-by-frame animation at scale - you'll get consistency drift between frames that no amount of seed manipulation fixes. If that's your end goal, you're better off using a video-specific model or investing time in training a Dreambooth model instead of a LoRA, though Dreambooth requires significantly more GPU memory and training time. Another limitation: the LoRA captures the movie design, not the book design or any alternate interpretations. If you need the dragon to look like the novel description instead, this approach won't help. You'd need separate training data and a different trigger word. Also worth noting that movie stills have copyright restrictions. For personal projects this is generally fine, but distributing generated content commercially could run into issues with DreamWorks or Universal. That's on you to sort out legally, not something I'm going to advise you on.
Resources
For the base SDXL model, use the official Stability AI release or a well-reviewed community fork like Juggernaut XL. The ControlNet extensions are available through the standard ComfyUI node repositories. My trained LoRA files aren't something I'm sharing publicly since they're tied to specific training data I assembled, but if you follow the same process with your own reference frames, you should hit similar results within a day or two of training. The key takeaway is that character consistency in image generation isn't really about prompting harder. It's about training the right lightweight adapter and understanding where your generation pipeline needs additional constraints. Everything else is just tuning parameters.