The Practical Reality of Working With SAS
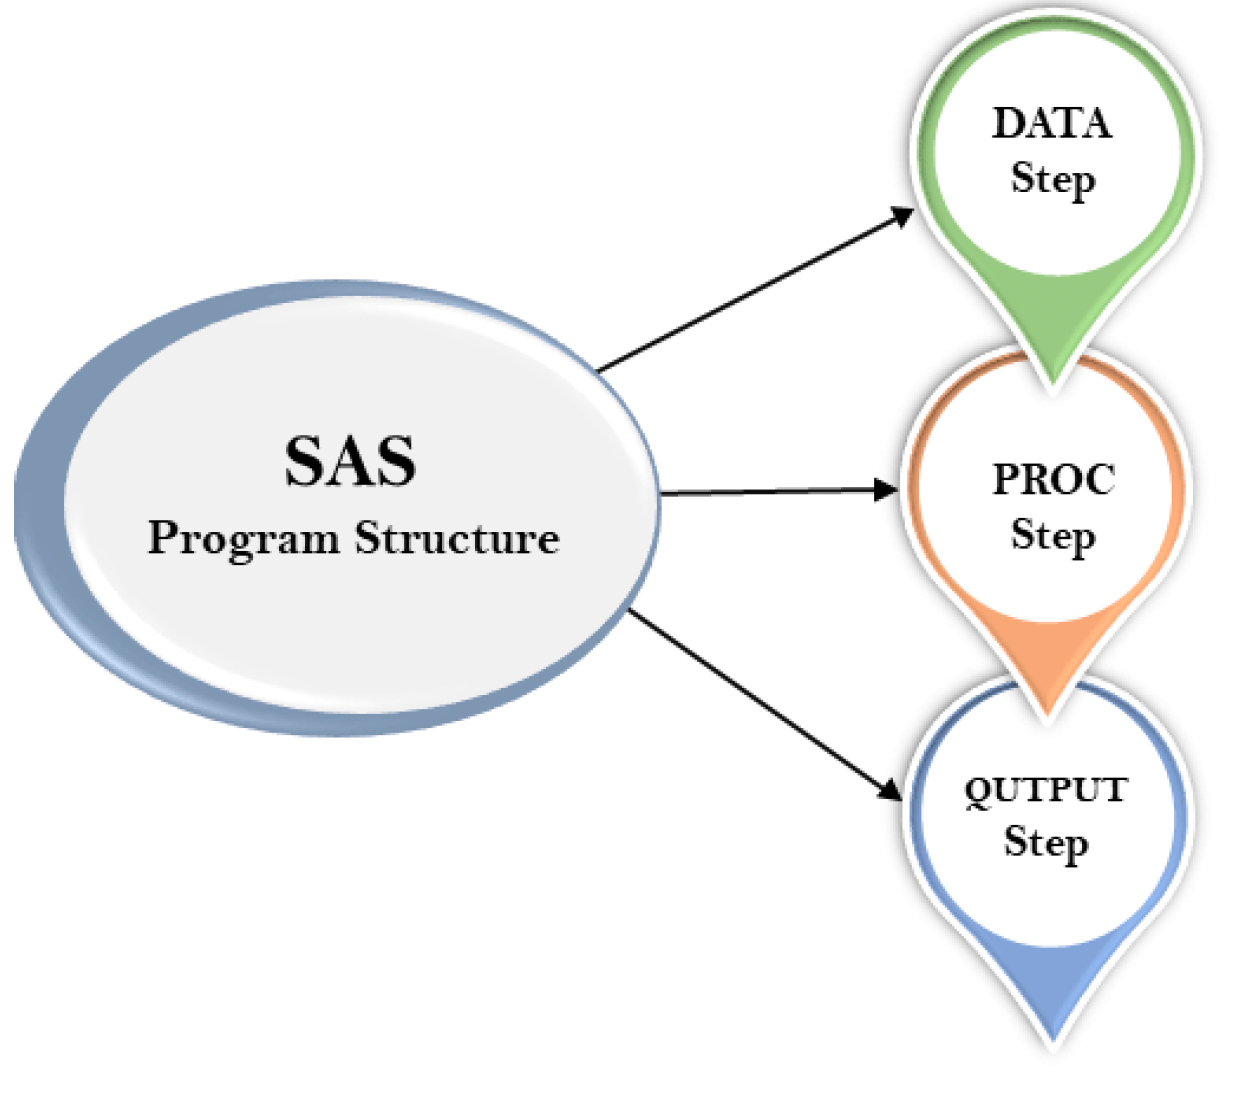
SAS is old. It has been around since the late 1960s, and that shows in a lot of ways. The interface feels like it belongs in another decade, the syntax reads differently than Python or R, and the learning curve is not forgiving. But people still run massive financial models, clinical trials, and government datasets through it every single day. Here is how you actually get something useful done with it. Start with the data step. That is where everything begins, and most beginners skip straight to procedures because they want quick results. A PROC means something, but without understanding the data step, you will hit walls later. The data step reads raw data, transforms variables, filters rows, and handles missing values in a way that PROCs simply do not. Here is what a basic data step looks like when you are working with a messy real-world file. data work.clinical_clean;
infile '/data/clinical_raw.csv' dlm=',' dsd firstobs=2; input patient_id $ visit_date date9. age bmi response_code $ weight_kg; format visit_date date9.;
if missing(age) then age = .; if response_code = 'N/A' then response_code = ''; keep patient_id visit_date age bmi response_code;
Get the Full Details

run; The dlm and dsd options on the infile statement tell SAS that your file is comma-separated and that quoted strings should be handled properly. The firstobs=2 skips headers. Without those two flags, your variable names become literal values and your analysis breaks quietly, which is worse than it breaking loudly. I spent three hours once debugging a dataset where the header row had been treated as data because I forgot dsd and the file contained commas inside quoted fields. The numbers looked plausible until I compared them against the source system.
Understanding the Two Programming Modes
SAS has two distinct modes, and you need both. The data step handles transformation. Procedures handle analysis, reporting, and output. They are separate by design, not by accident. Beginners often try to cram everything into one block and end up confused when their PROC call fails or returns nothing useful. Think of the data step as a workshop where you build and clean your objects, and PROCs as the inspection station where you measure what you built. You do not inspect raw ore. You do not weld in the inspection room.
Where Most People Go Wrong
The biggest mistake is assuming SAS behaves like Python or SQL. It does not. There is no implicit iteration over rows in a PROC. When you use PROC MEANS or PROC FREQ, SAS already has the full dataset in memory. You cannot easily add custom row-by-row logic inside those procedures. If you need that kind of control, go back to the data step. Another common trap is misusing the SET statement. Some people write multiple SET statements in a single data step expecting a merge. That is not how SAS works. A multiple SET statement creates a lateral read, not a join. If you need to combine datasets, use PROC SQL or the explicit MERGE statement with BY variables after sorting. I ran into this when a colleague pasted two SET statements side by side expecting a full outer join. The output had duplicate records and missing values everywhere, and it took me twenty minutes to spot the issue because the code looked plausible at first glance.
Essential Procedures You Actually Need
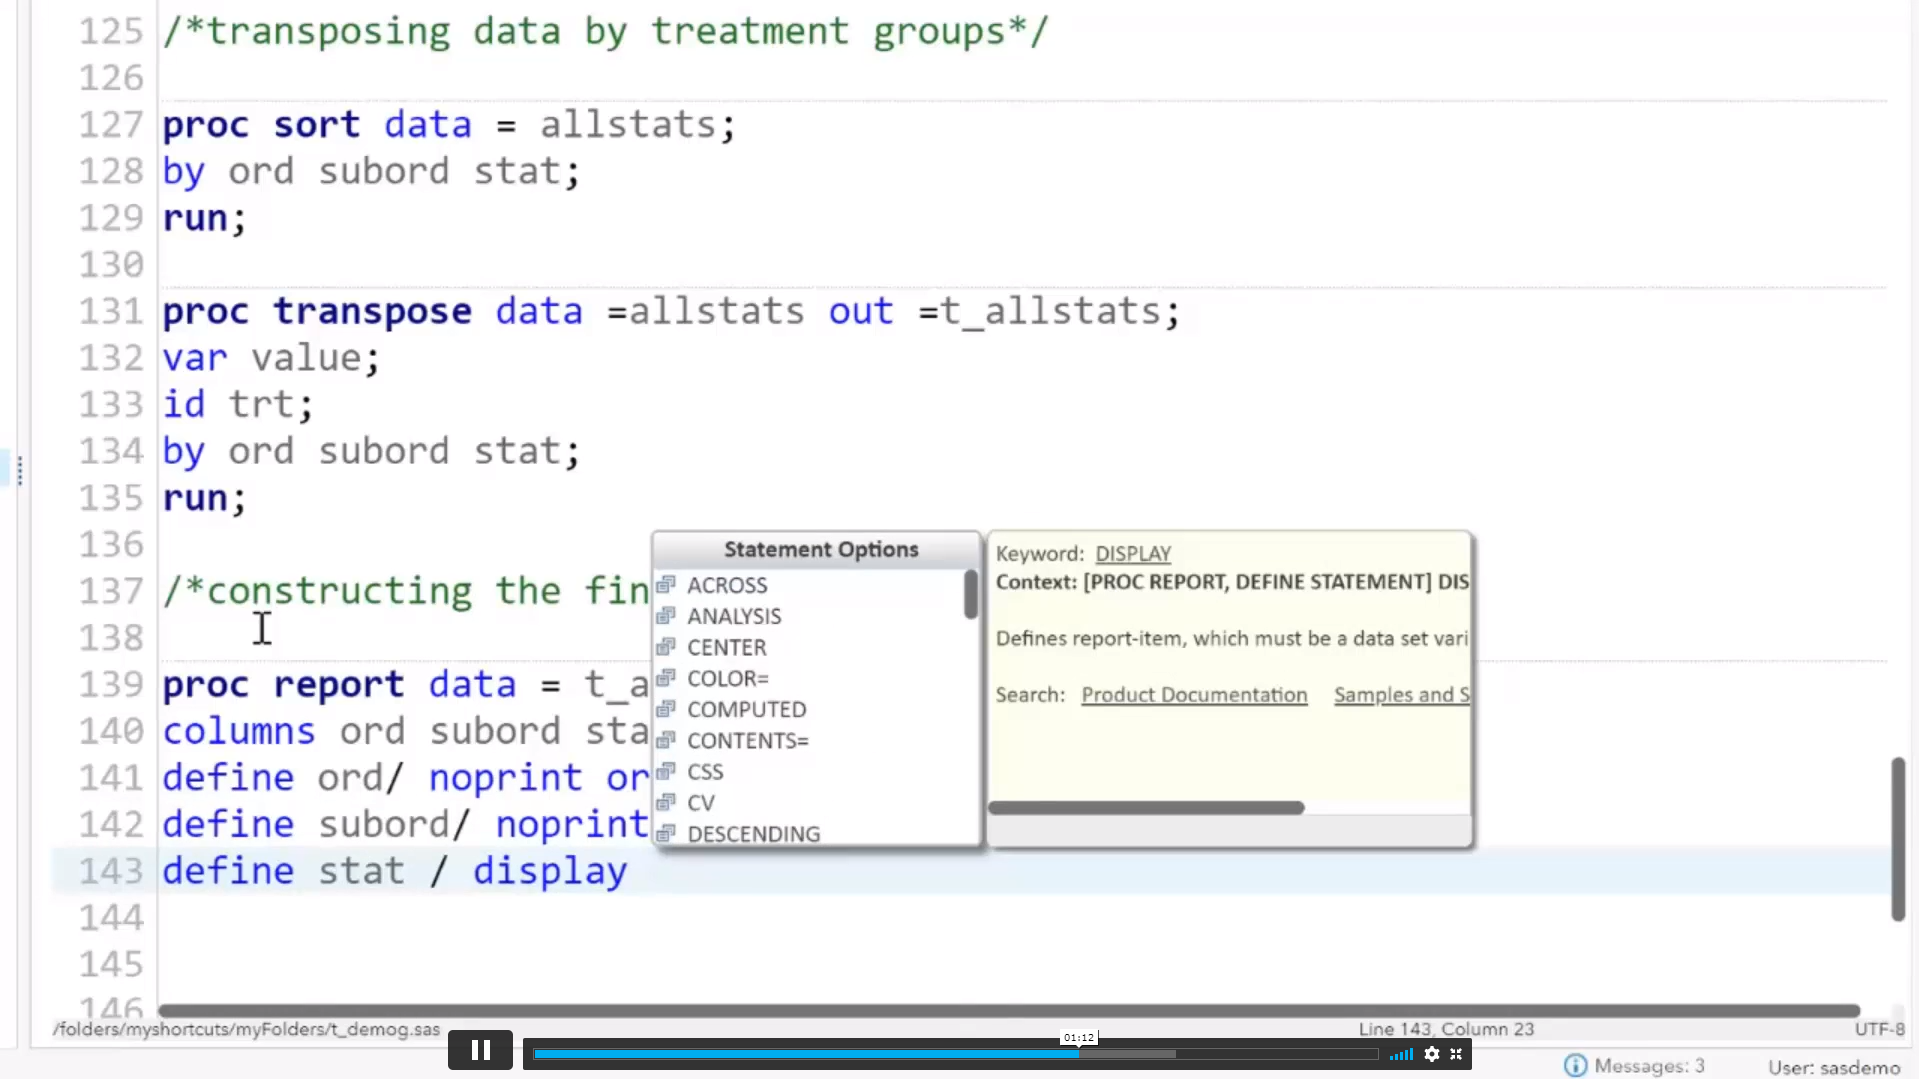
You do not need to memorize every PROC. Focus on the ones that handle the bulk of real work. PROC SORT is non-negotiable. Many procedures require sorted data. If you skip sorting, you get errors or silently wrong results depending on the procedure. The nodupkey option removes duplicate observations based on the BY variables, which saves you from manual deduplication later. PROC FREQ gives you cross-tabulations and frequency counts. It is the fastest way to understand the distribution of categorical variables. Add the CHISQ option for chi-square tests and the MISSING option so missing categories do not disappear from your output.
PROC MEANS or PROC SUMMARY handles numerical summaries. The difference between them is subtle: PROC MEANS prints output by default, while PROC SUMMARY does not unless you add the PRINT option. If you are working in a batch environment and do not want log clutter, use PROC SUMMARY. I switched to PROC SUMMARY years ago after realizing I was generating thousands of pages of printed output on every run. PROC SQL is available in SAS and it works well for joins, subqueries, and when you already know SQL. It is slower than a data step for massive datasets, but it is readable and familiar. For ETL-style transformations on large files, stick to the data step. For ad-hoc analysis on moderate data, PROC SQL saves time.
Handling Large Datasets Efficiently
SAS is designed to process data in a single pass whenever possible. This is both its strength and its constraint. If your dataset is larger than available RAM, SAS will write temporary files to disk, which slows things down significantly. I once processed a 400-gigabyte clinical dataset on a server with 128 gigabytes of RAM. The job took six hours because SAS was constantly swapping. The same query on a properly sorted and indexed subset ran in eleven minutes. The workaround was straightforward: filter aggressively before analysis, create SAS indexes on frequently used BY variables, and use the COMPRESS=YES option when creating permanent datasets to reduce I/O overhead. Compression costs CPU cycles but typically reduces disk reads enough to be a net win on large tables.
The Macro System Is Necessary But Painful
Macros let you parameterize code. They are not a programming language. They are a text substitution engine that runs before your code is compiled. This means macro errors often appear as syntax errors in the compiled code, which makes debugging frustrating. Here is a simple macro that runs PROC MEANS on any dataset and any variable you specify. %macro summarize_data(ds=, var=);
proc means data=&ds n mean std min max; var &var; run;
%mend; %summarize_data(ds=work.clinical_clean, var=bmi); The double ampersand syntax resolves macros in two passes. You will see this pattern everywhere. It is confusing at first, but it is consistent once you internalize it. I recommend using %put statements liberally while developing macros so you can see what the text substitution actually produced. The SAS log will show you the resolved code, and that is your best debugging tool.
When SAS Is the Wrong Tool
Be honest about when to use SAS and when not to. If you are doing exploratory data analysis with millions of small transformations, Python with pandas or polars will be faster and more flexible. If your team already has a Python ecosystem with scikit-learn and pandas, forcing SAS into that pipeline adds friction without benefit. SAS excels at regulated environments where audit trails, reproducibility, and validated code matter. Clinical trials, banking compliance, and government reporting are classic cases where SAS remains the standard. SAS also struggles with unstructured data. Text mining, image processing, and natural language tasks are not its domain. There are packages like SAS Text Miner, but they are expensive and not as mature as open-source alternatives. If your work involves that kind of data, use SAS for the structured part and something else for the rest.
Practical Workflow That Actually Works
Here is a realistic sequence I use when starting a new analysis project in SAS. First, write a short data step that reads your source file, inspects variable types, and logs basic metadata. Use PROC CONTENTS to verify that character and numeric variables are assigned correctly. A dataset with a numeric column stored as character because of a stray letter in the source file will break every PROC that follows, and the error messages are rarely obvious. Second, clean the data in the data step. Handle missing values explicitly. Create flags for outlier ranges if your domain requires it. Write the cleaned dataset to a permanent library with a compression option.
Third, run your analysis procedures. Use ODS (Output Delivery System) to route results to Excel, PDF, or HTML instead of relying on the Results window. In a batch environment, the Results window does not exist, and ODS is the only way to capture output. Fourth, validate your results against a known subset. Pull a small sample, run the same code manually or in another tool, and compare. Discrepancies at this stage are cheap to fix. Discrepancies after publication are not.
A Specific Edge Case That Costs People Days
DATE9. format and informats are a common source of hidden bugs. SAS stores dates as integers representing days since January 1, 1960. If you import a date field as character and do not apply the correct informat, SAS treats it as text. Your subsequent date arithmetic fails silently or produces missing values. I inherited a project where the analysis run had been producing correct-looking statistics for weeks until someone noticed the primary date variable had zero valid observations. The informats had been swapped between MMDDYY10. and DATE9. due to a copy-paste error. Replacing the informat and re-running the data step fixed it in minutes, but the downstream analysis had already been cited in a report. The fix is simple: always validate date variables immediately after import with a small frequency count or a sample print. Check that the date range makes sense. If your data spans twenty years and PROC FREQ shows all missing values for the date variable, something is wrong before you write a single line of analysis code.
Getting Started With SAS
SAS offers a few entry paths. SAS University Edition used to be the free route, but SAS retired it. The current accessible option is SAS OnDemand for Academics, which runs in a browser and requires no local installation. If you are working professionally, your organization will likely provide SAS Viya or SAS 9.4 access through IT. Both have different interfaces and different performance characteristics, but the underlying syntax is the same. For learning, install the free OnDemand environment, grab a public dataset, and write the data step and three PROC calls from scratch. Do not rely on point-and-click menu tools while you are learning. The menus hide the code, and you will not understand what is happening when you encounter an error that the menus cannot resolve. Read the log. The log is where SAS tells you exactly what went wrong. Most beginners ignore the log and stare at the output window, which is backwards. SAS is not glamorous. It is not trending. It is also reliable, validated, and deeply embedded in industries where mistakes are expensive. If you need that reliability, learning how to use SAS for data analysis is a reasonable investment. Start with the data step, respect the sorting requirements, validate your variable types early, and keep the log open.
