What Implicit Bias Training Actually Looks Like
Most people think bias mitigation is a single step you run before deployment. That's wrong. Implicit Bias Training is a continuous process woven into model development, data collection, evaluation, and post-deployment monitoring. The real work happens in the messy middle where datasets are messy and edge cases multiply. I spent three years building hiring algorithms for a mid-size tech company. We thought we'd caught every bias vector until a candidate from a regional university kept getting scored lower than peers from target schools, even with identical experience. The model had learned to associate "prestige" with geographic clusters in our training data. Fixing it required reweighting samples, not just adding a fairness constraint.
The Reality of Implicit Bias Training
Here's what nobody tells you about Implicit Bias Training: it rarely produces clean metrics. You'll chase demographic parity or equalized odds and end up with a model that performs worse on every slice. That's expected. There's always a tradeoff between accuracy and fairness. The goal isn't perfection, it's direction. I've seen teams spend weeks on adversarial debiasing only to discover the red flag wasn't in the features—it was in the labeling pipeline. Annotators from certain backgrounds were more likely to mark ambiguous cases as negative, and the model just learned those patterns. We ended up switching to stratified review with conflict resolution instead. Cost went up 40 percent, but the model actually worked after deployment. The techniques you'll encounter fall into three buckets. Pre-processing methods like reweighing and sampling adjust the training data before the model sees it. In-processing methods bake fairness constraints directly into the optimization objective, often using adversarial networks to strip protected information from hidden layers. Post-processing methods like calibrated equalized odds adjust predictions after training without touching the model itself.
Each approach has failure modes. Pre-processing can destroy signal if you overcorrect. In-processing is computationally expensive and often unstable. Post-processing doesn't address the root cause and can create new inconsistencies when distributions shift over time. I usually start with post-processing because it's cheapest to experiment with, then move upstream if the model still underperforms on protected groups. The hardest part isn't picking a method. It's defining what "bias" means for your specific use case. Loan approval, criminal risk assessment, and medical triage all have different ethical frameworks. The same model behavior might be acceptable in one domain and catastrophic in another. I learned this the hard way when a healthcare team tried to reuse a criminal justice bias mitigation strategy without adjusting the threshold logic. Another counter-intuitive insight: fairness metrics don't compose. A model that's fair across gender and fair across race isn't necessarily fair across both simultaneously. This is the intersectionality problem, and most toolkits ignore it. If you're working with Protected Attributes like race, gender, age, or disability status, you need to test every combination, not just individual slices.
Get the Full Details
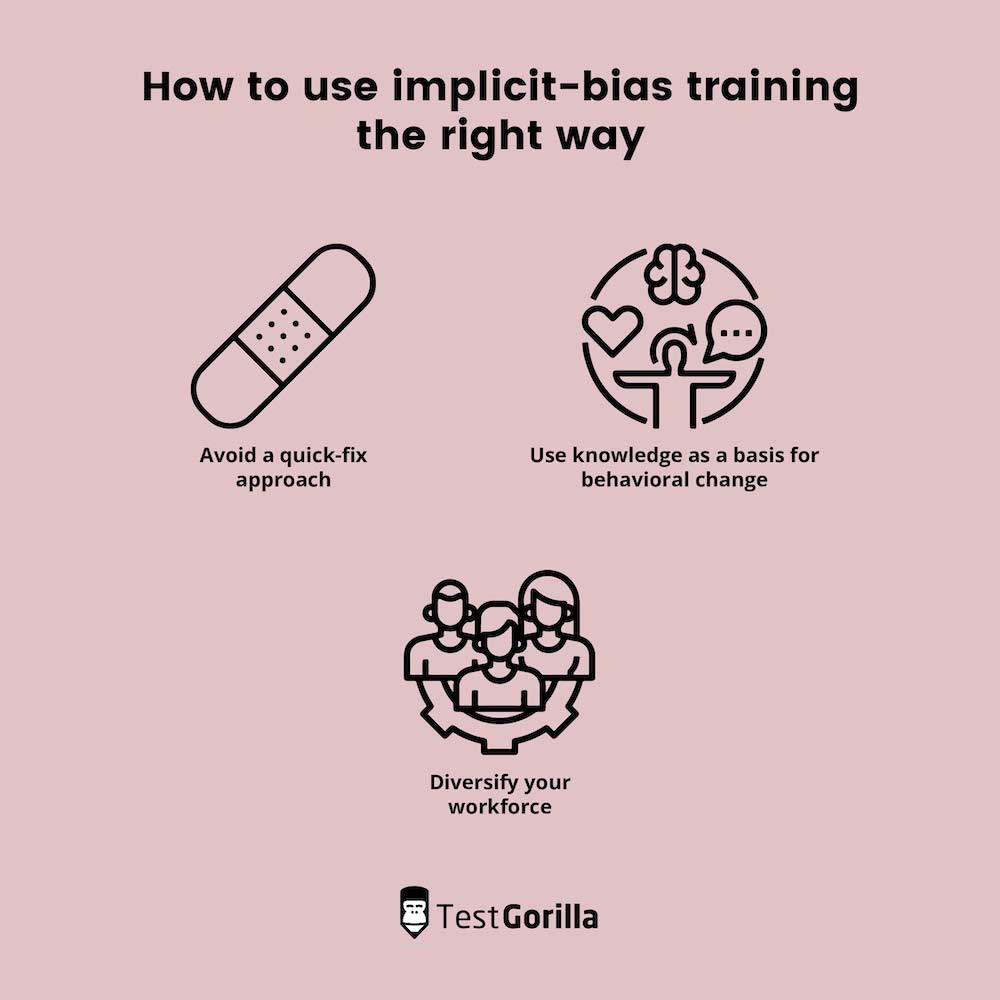
Here's a practical workflow I've used successfully. First, audit your existing model with disaggregated performance metrics. Look at false positive rates, recall, and calibration across every Protected Attribute and their intersections. Second, identify where disparities exceed your tolerance threshold—usually 5 to 10 percent depending on the domain. Third, pick the least invasive mitigation technique that addresses the gap. Fourth, re-audit. Fifth, repeat until you hit diminishing returns. The tools available include Fairlearn from Microsoft, AIF360 from IBM, and adversarial debiasing implementations in PyTorch. They're useful but incomplete. Most assume static populations and ignore distributional drift. If your data changes over time, which it will, you need monitoring pipelines that re-evaluate fairness metrics continuously, not just once at deployment. I've also found that business stakeholders often misunderstand what fairness means. They'll ask for "equal outcomes" when they actually need "equal opportunity" or vice versa. The distinction matters legally and ethically. Pay attention to regulatory language in your jurisdiction. The EU AI Act and US state-level regulations have different requirements, and they change frequently.
One more thing: implicit bias in training data isn't always obvious. Surface-level features like zip codes can proxy for race through redlining patterns. Timestamps can encode socioeconomic status. Even seemingly neutral features like "years of experience" can carry bias if certain groups had structural barriers to accumulating it. You need domain expertise to catch these, not just statistical tests. If you're starting fresh, begin with documentation. Keep a record of every dataset, annotation guideline, and fairness metric you compute. When something breaks in production, which it will, you need to know what changed. I maintain a bias audit log for every model I touch, even internal experiments. It saved me during a compliance review last year. The bottom line is that Implicit Bias Training isn't a feature you ship and forget. It's a discipline that requires ongoing attention to data, models, and outcomes. The techniques exist, the tools exist, but the judgment call—that's on you. Pick your metrics carefully, acknowledge the tradeoffs, and monitor continuously. That's the only way to build systems that don't quietly fail the people they're supposed to serve.