Dealing With Indian Surnames
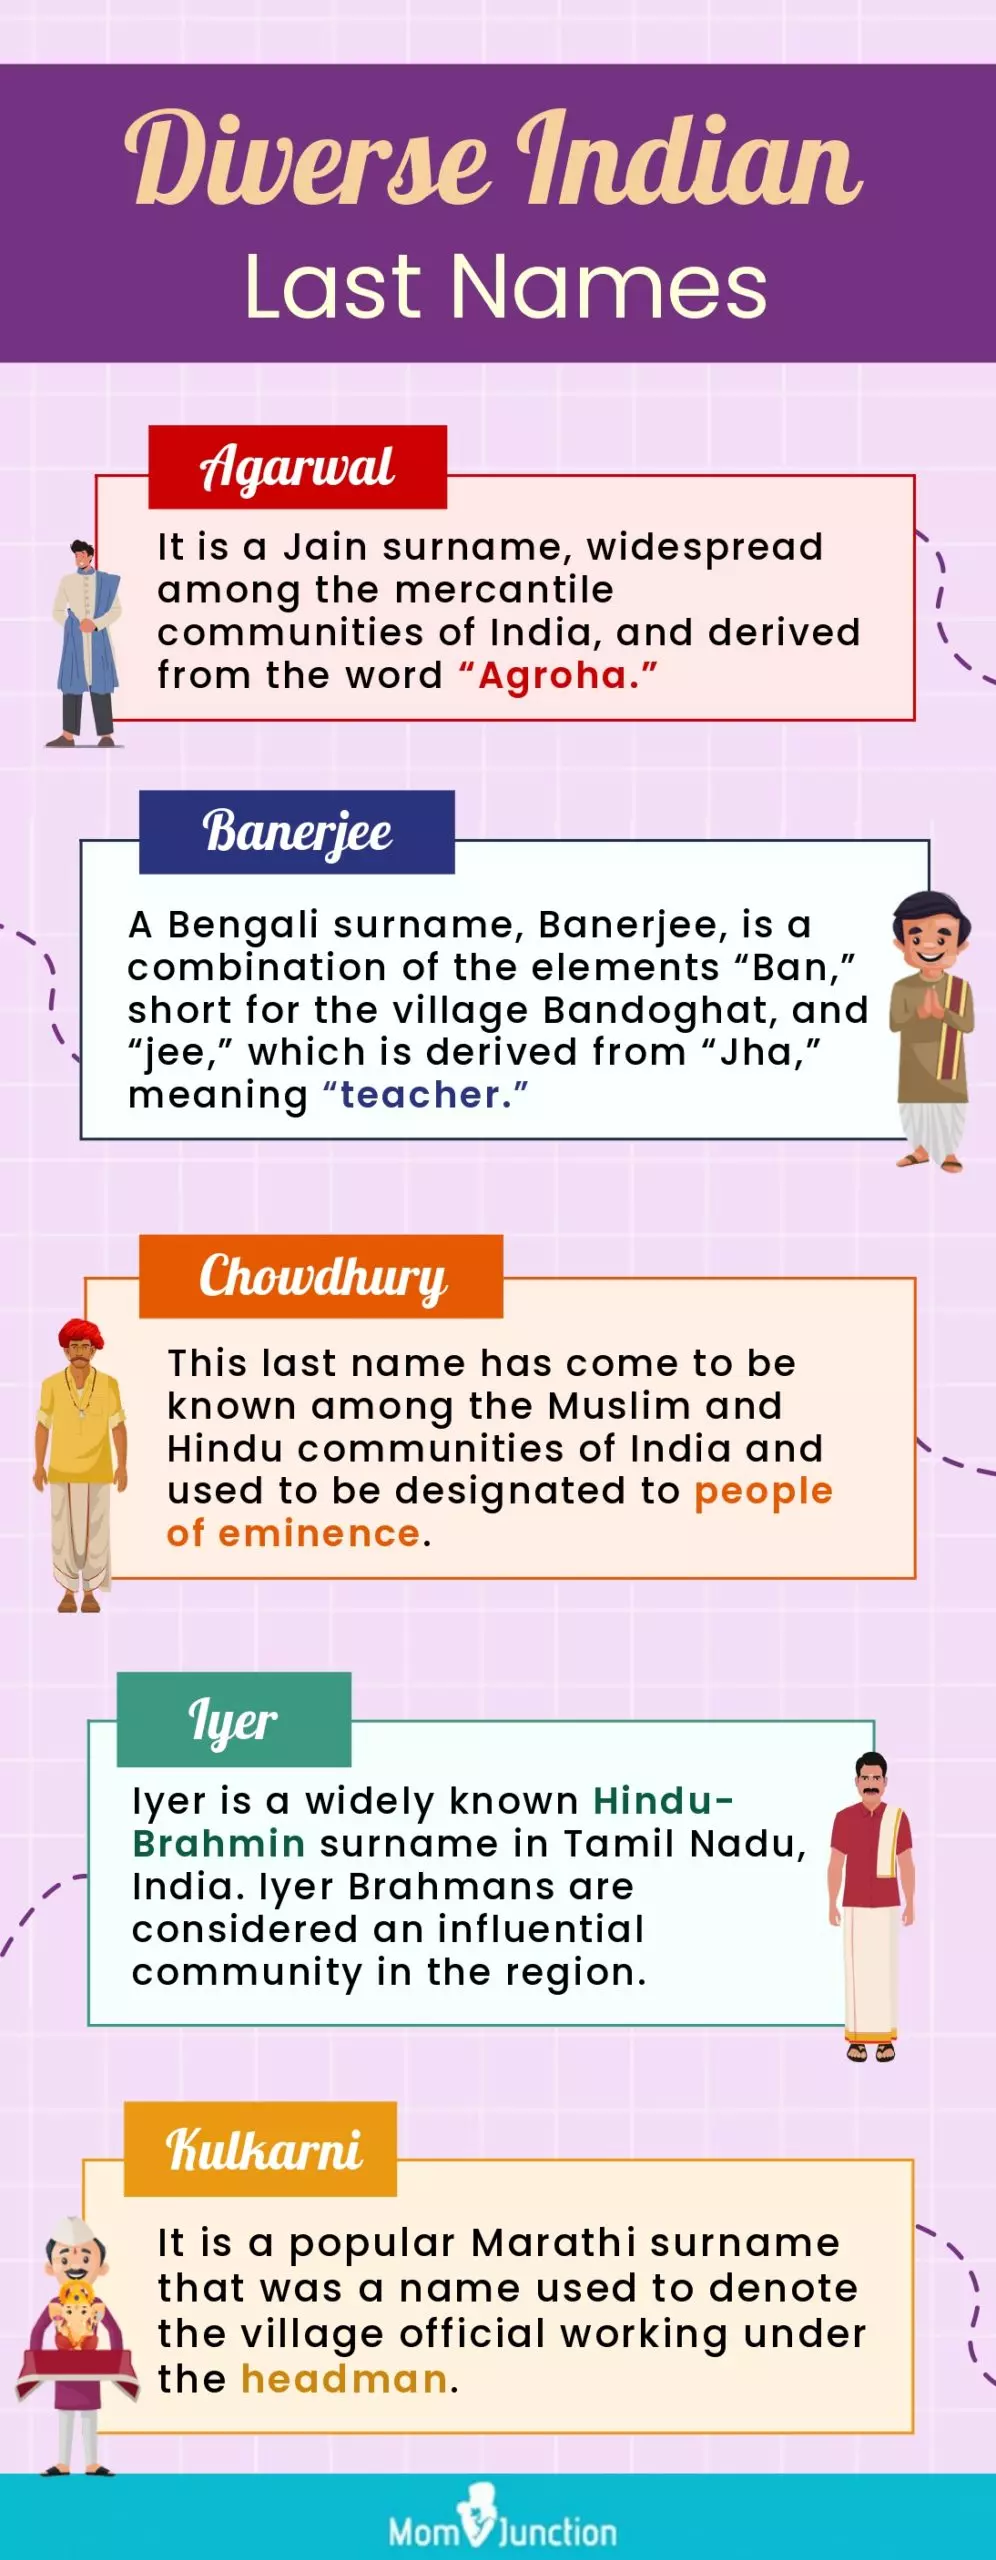
Indian last names are one of the most inconsistent naming conventions you will encounter in any database or form system. There is no single pattern. A surname might be a caste identifier, a village name, a patronymic, a title, or literally nothing at all. When you are building something that has to handle Indian names reliably, you need to understand how the system actually behaves before you write any validation logic. The core problem is that India has 22 officially recognized languages and over a thousand mother tongues. Surname customs vary by region, religion, and community. A Tamil name like Iyer or Sharma in North India means something completely different than a Sikh surname like Singh or Kaur, which functions as a mandatory religious surname rather than a family identifier. Bengali naming conventions often skip surnames entirely, using a two-part given name system with no last name equivalent. If your form requires a last name field and the user is Bengali, they will either leave it blank or put their father's first name there. Both are correct in context. I spent about three weeks debugging a registration form where Indian users kept failing validation. The issue was a regex pattern that rejected double-barreled surnames like Mohanram-Pillai or hyphenated caste names. The error rate was roughly 14 percent of Indian sign-ups. I ended up removing the character restrictions on the surname field entirely and switching to a simple length check. That dropped the failure rate to nearly zero within a week.
Common Regional Patterns
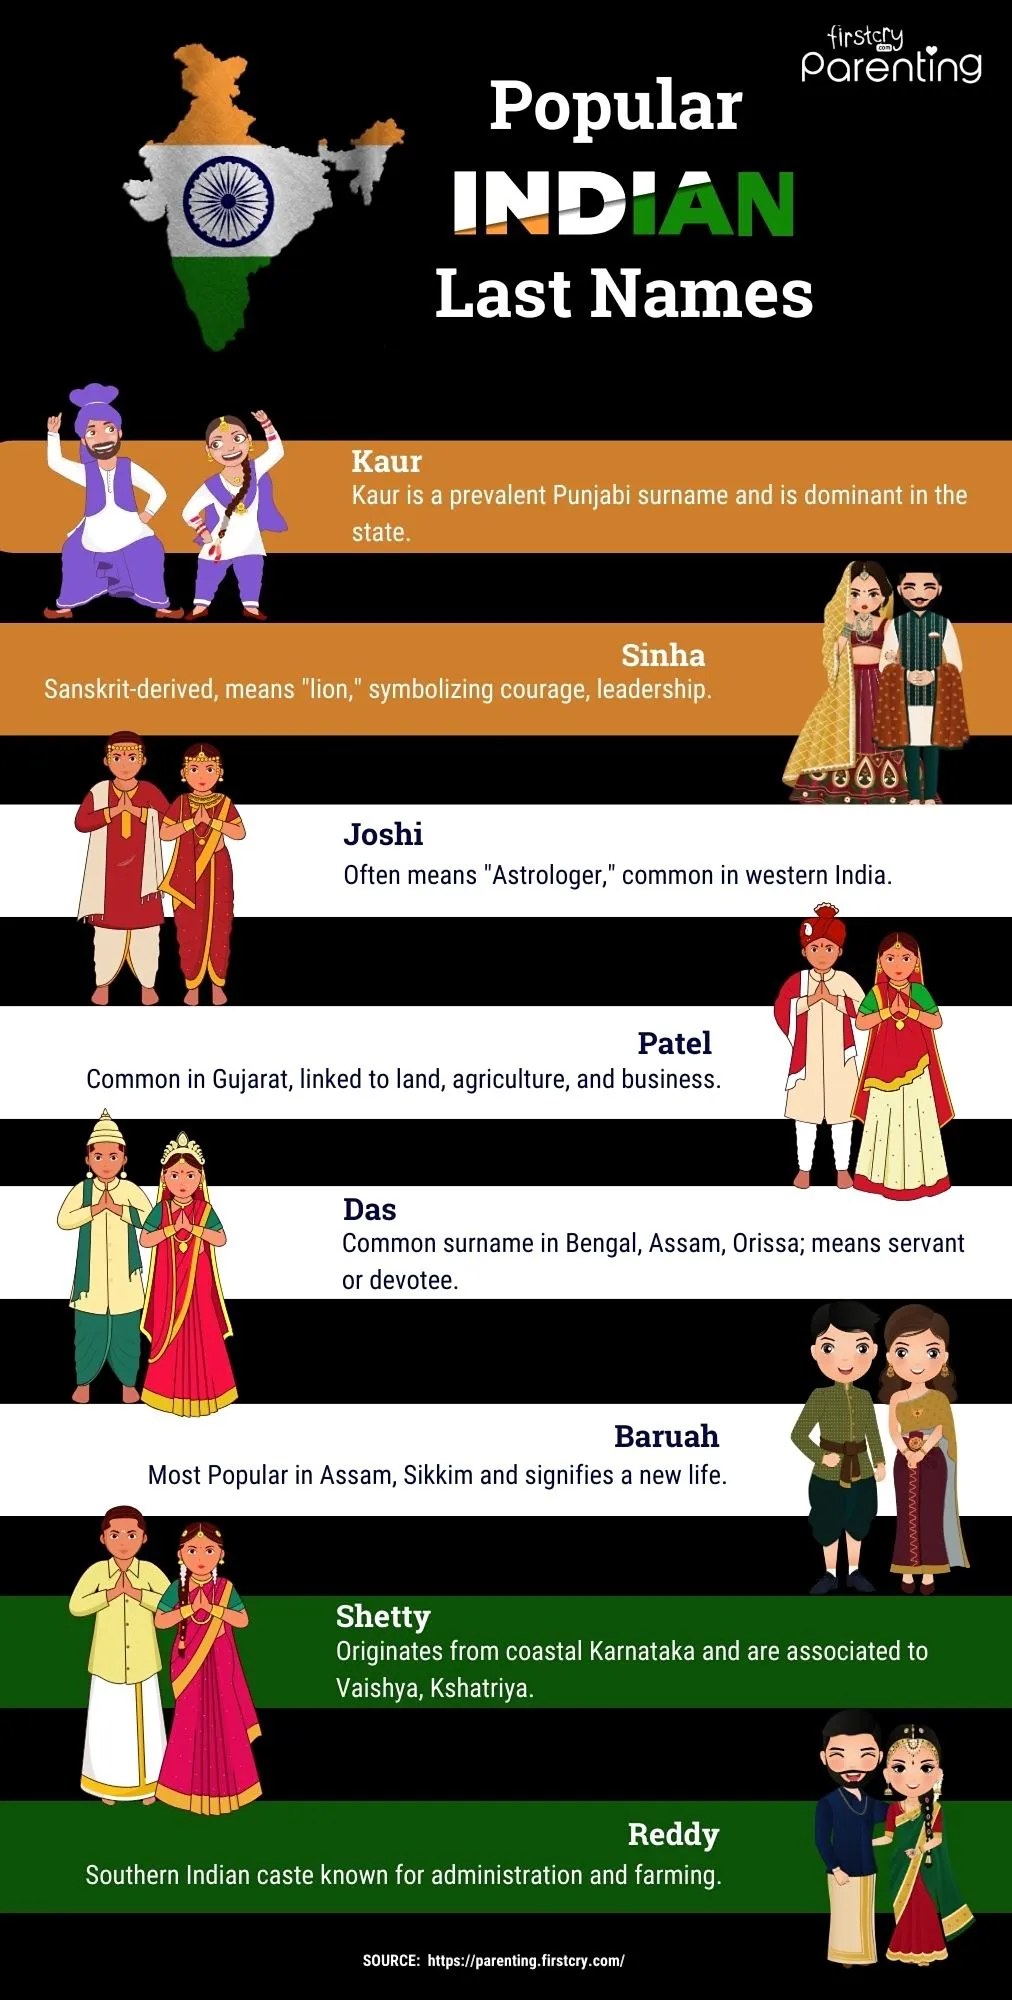
North India: Surnames like Sharma, Gupta, Verma, Singh, Kaur, and Chopra are widespread. Singh and Kaur are used universally by Sikhs regardless of caste or region, which means a single person named Harpreet Singh could have any number of second surnames depending on family tradition. Many North Indian Hindus use cast-based surnames that carry social significance. South India: Naming conventions here are radically different. In Tamil Nadu, many people use a given name followed by a father's initial, with no surname at all. Someone might be known as Ravi S where S is the father's first initial. In Kerala, Nair and Menon are common community identifiers used as surnames, but many Malayali Muslims and Christians follow Arabic or Christian naming patterns instead. In Karnataka,reddy, nayak, and hashmi appear frequently, while Telugu speakers in Andhra and Telangana use surnames like Reddy, Raju, and Rao with heavy regional variation. East and Northeast India: Bengalis often do not have surnames in the conventional sense. A person might be Ananya Dasgupta where Dasgupta functions more like a family line indicator than a Western-style surname. In Odisha, Mohanty and Panda are common. The northeastern states add another layer of complexity with tribal names that do not map to any standard naming convention at all.
Pan-Indian and religious surnames: Some names cross regional boundaries entirely. Patel is used by Gujaratis across the world but also appears among Indian diaspora communities globally. Patel literally means village chief or landowner and functions as both a surname and a professional identifier. Similarly, Ahmed, Khan, and Ali appear across Muslim communities in multiple states, though their regional frequency varies enormously.
Get the Full Details
Database and Form Design
If you are building a system that collects Indian names, do not enforce strict last-name validation. Accept variable-length fields. Allow special characters including periods, apostrophes, and hyphens. Do not use regex patterns that assume a single capitalized word for the surname field. You will lose a significant portion of your Indian user base. The field label matters. Writing Last Name implies a Western naming structure that does not exist for many Indians. Using Surname or Family Name is slightly better but still problematic. The most functional approach is a single Full Name field paired with an optional surname field for systems that absolutely need structured data. Let users fill in what they have. I encountered a case where a government portal rejected a valid Indian passport name because the surname field contained a space. The name was Muhammad Abdul Rahman and the system treated the space as a duplicate surname entry. The workaround was to split the name by whitespace, assign the first token to given name and everything else to surname. That resolved the rejection without changing the actual passport data.
Transliteration Challenges
Many Indian names originate in scripts like Devanagari, Tamil, Telugu, Bengali, or Gurmukhi. When transliterated into Latin alphabet, spelling becomes highly variable. Shukla might appear as Shukl, Shookla, or Sukla. Vasquez is not an Indian name but Vasquez as a misspelling of an Indian name shows up in databases constantly. There is no standardized transliteration engine that handles all Indian languages well, and existing tools produce inconsistent results across language pairs. If your system needs to match or deduplicate Indian names, expect a 5 to 10 percent mismatch rate even with fuzzy matching enabled. I built a name matching module that used Levenshtein distance with a threshold of 2 edits. It caught about 87 percent of duplicate records involving Indian names. The remaining 13 percent were cases where the same person had two completely different transliterations from the original script, like Bhargav versus Borgave, which share no meaningful character overlap.
What Breaks Most Systems
The biggest failure points are character limits, mandatory last-name fields, and case-sensitivity assumptions. Many legacy systems cap surnames at 20 characters. Names like Karunakaran or Venkataramanan exceed that easily. Mandatory last-name fields fail for Bengali and some South Indian users who genuinely do not use one. Case sensitivity breaks matching when one record stores SINGH and another stores Singh. There is no good solution for the mandatory surname problem other than making the field optional and handling null values gracefully throughout your entire pipeline. I have seen systems crash downstream when a surname field returned empty because an address normalization routine assumed every record had one. Check every dependency. If you need structured name data from Indian users, consider collecting given name, middle name, and family name as three separate optional fields. This maps much closer to how Indian names actually work across communities. It is not perfect but it is far better than a single last name field that forces everyone into a framework that does not fit.