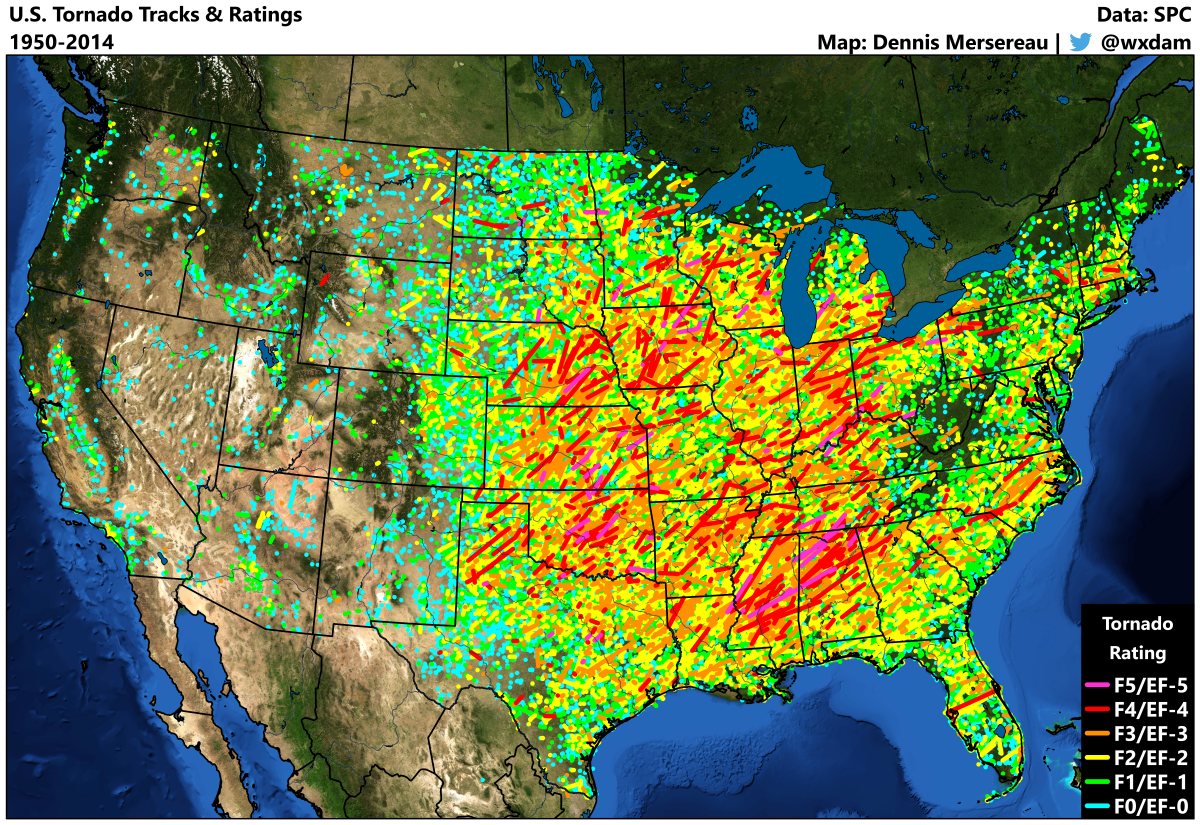
Building an Interactive Tornado History Map
I've spent way too many afternoons wrestling with tornado sighting databases and Leaflet maps. The NOAA Storm Prediction Center's SPC database is the standard source for U.S. tornado data, and it's free, but getting it into something you can actually click through takes some real effort. Here's how the process works when you do it properly. The data itself lives as a CSV on the SPC site. Each row is a single tornado event with fields like start latitude, start longitude, length, width, F-scale or EF-scale rating, and date. The catch is that the coordinate system isn't always clean — some older entries have approximate locations, and a few have invalid geometry that will crash your map if you don't filter them out. I learned that the hard way when my browser tab threw a JavaScript error during a demo and I had to figure out which record was causing it.
Setting Up the Interactive Tornado History Map
You're going to need a few things. First, grab the latest SPC dataset from their website. It's usually updated annually with the previous year's full season data. Download the CSV and open it in whatever text editor you use. Second, pick your frontend library. Leaflet is the simplest option if you're just doing points and circles on a map. For something more capable with clustering and time sliders, MapLibre GL JS gives you better performance with large datasets. Here's the part most people skip: parsing the CSV into GeoJSON. You can't just dump raw CSV onto a map library and expect it to work. You need to convert each tornado record into a GeoJSON feature with a Point or LineString geometry depending on whether you're plotting the start location or the full path. A single Python script with pandas and geojson libraries can handle this. I usually write something like this:
import pandas as pd
import geojson

df = pd.read_csv('spc_tornadoes.csv')
df = df.dropna(subset=['STARTLAT', 'STARTLON'])

features = []
for _, row in df.iterrows():
    features.append(geojson.Feature(
        geometry=geojson.Point((float(row['STARTLON']), float(row['STARTLAT']))),
        properties={
            'date': row['STARTDATE'],
            'ef_scale': row.get('EF_SCALE', 'Unknown'),
            'length': row.get('LENGTH', 0),
            'width': row.get('WIDTH', 0),
            'injuries': row.get('INJURIES', 0),
            'deaths': row.get('DEATHS', 0)
        }
    ))

geojson_data = geojson.FeatureCollection(features)
with open('tornadoes.geojson', 'w') as f:
    f.write(geojson.dumps(geojson_data))
This basic script takes about ten minutes to write and handles the conversion in under two seconds for the full dataset of roughly 10,000+ tornado events. Once you have the GeoJSON file, you load it into your map. Color-code by EF scale. Red for EF4-EF5, orange for EF2-EF3, yellow for EF0-EF1. Add a size dimension based on path length if you want the markers to communicate severity beyond just color. Users should be able to click a marker and see the full event details pulled from the properties. The time component is where this becomes genuinely useful. Add a year range slider so people can filter by decade or individual year. The 1950s have far fewer records because the reporting standards were different — not because fewer tornadoes occurred. That's an important distinction to note somewhere on the page, or people will draw the wrong conclusion about historical trends. The same applies to the pre-satellite era. Spatial coverage was incomplete, especially in rural areas.
Get the Full Details

I ran into a specific problem once where the clustering library started merging nearby tornado events from different dates into a single cluster that showed an averaged property value. It made 1974 Super Outbreak look less severe than it was because clusters were blending it with surrounding weaker events. The workaround was turning off clustering and using a heat map layer instead for the dense outbreak periods, then falling back to individual markers with lower opacity for quiet years. That configuration loads fine even with all twelve thousand records visible at once.
Data Quality Issues You'll Hit
The SPC data has known inconsistencies. Before the Enhanced Fujita scale replaced the original Fujita scale in 2007, there's a period where both ratings appear in the dataset and they don't always align. Some tornadoes rated F2 under the old scale might be EF1 under the new one. Don't try to automatically convert between them — the relationship isn't consistent enough. Just show both values side by side and let people decide. Another issue: casualty numbers are often zero or missing for older events, not because no one was hurt, but because the data wasn't collected or reported. A map that uses injury count as a visual variable without accounting for missing data will systematically underrepresent older tornadoes. Flag this on the page with a brief note about data completeness by era. Coordinate accuracy is another factor. Early tornado paths were estimated from newspaper reports and farmer phone calls. The lat/lon pairs for 1970s events can be off by several kilometers. This doesn't matter much for national-level pattern analysis, but it will frustrate anyone trying to pinpoint where a specific tornado touched down near a particular town.
Performance Considerations
If you're serving all twelve thousand markers on a single page, expect slow initial load times. Split the data into yearly chunks and only load the selected year's events into the DOM. A typical modern browser can handle about five thousand markers before canvas-based rendering becomes necessary. Once you cross that threshold, switch to WebGL rendering with a library like deck.gl or Mapbox GL's built-in WebGL support. The visual difference is minimal for this use case, but the frame rate improvement is dramatic. Hosting the GeoJSON file is straightforward. GitHub Pages works fine for a static version. If you want to add search functionality or let users draw custom boundaries to filter events, you'll need a backend. A simple SQLite database with spatial indexing answers those queries in milliseconds for a dataset this size. PostGIS overkill here.
What This Tool Is Good For
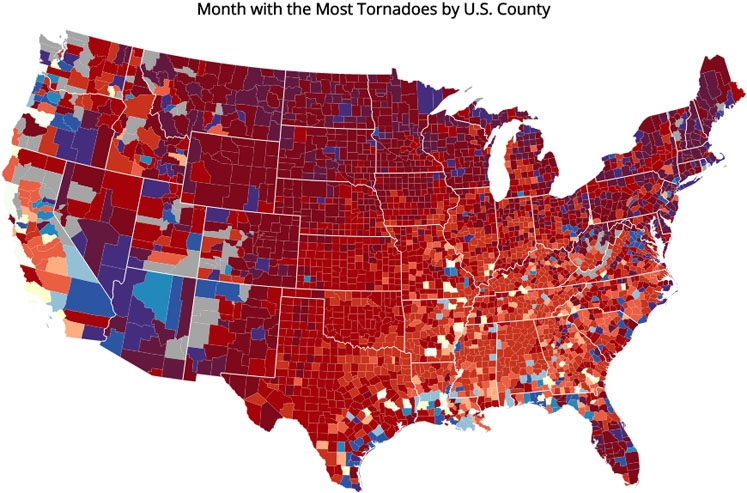
An Interactive Tornado History Map works well for education, journalism, and personal research. It lets people see the spatial clustering around Tornado Alley, the seasonal migration of activity from spring to summer in northern states, and the clustering of major outbreaks along specific corridors. It's less useful for anything requiring millimeter-precise path accuracy or for drawing causal conclusions about climate trends without consulting peer-reviewed research that accounts for reporting bias. The biggest limitation nobody mentions is that tornado occurrence has increased in the historical record primarily because we're better at detecting and reporting them. More Doppler radar, more storm chasers, better cell phone coverage. The map will show an upward trend in numbers, and without context that trend is misleading. Put a disclaimer near the legend explaining this, and you save a lot of confused readers from drawing incorrect conclusions. There are a few existing implementations out there. The NOAA visualization tools and the National Weather Service's own tornado maps cover the basics. But building your own gives you control over the design choices that matter — how you represent uncertainty, what filtering options you offer, how you handle the data quality problems I mentioned. Takes a weekend to get something functional. A few more weekends to get it right.


