What an Ecological Data Interpretation Key Actually Is
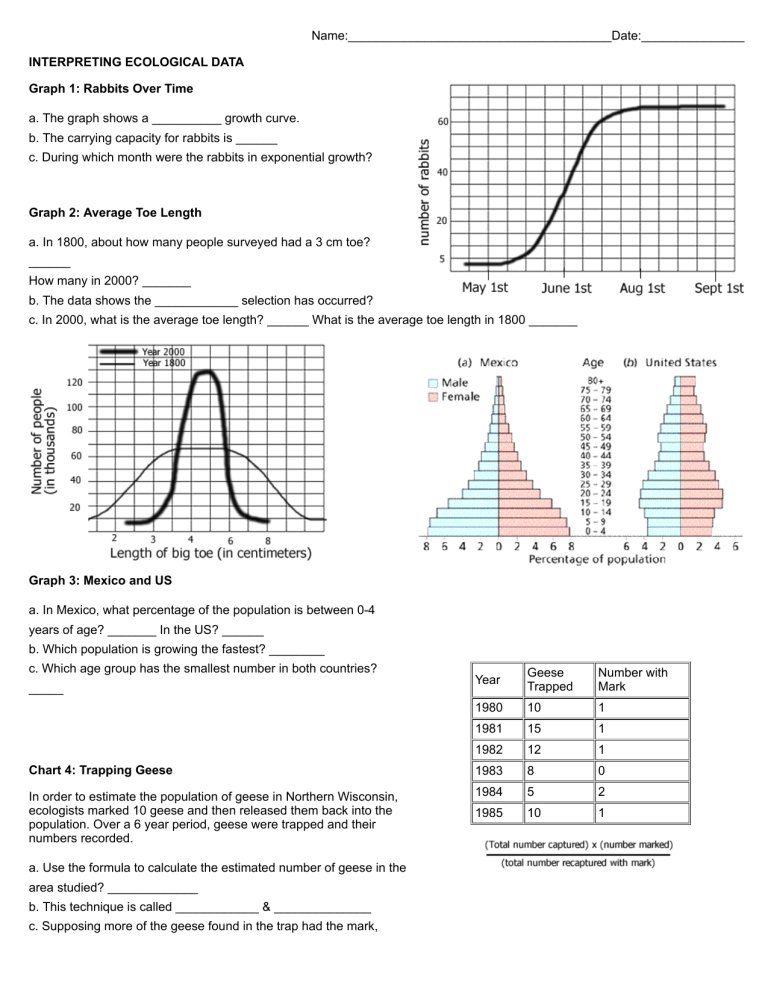
An Interpreting Ecological Data Answer Key is basically a reference document that tells you whether your statistical choices, calculations, and conclusions are on the right track. It comes up most often in university courses where students run biodiversity surveys, species abundance analyses, or community composition tests and then need to check their work. Some instructors provide them upfront. Others expect you to reverse-engineer answers from raw data tables yourself. Either way, knowing how to read and use one properly saves you from wasting half a day on a dataset with a fundamental error you should have caught earlier. The answer keys I have encountered across multiple semesters of teaching and grading tend to cover the same core areas. They check whether you selected the right test for your data structure, whether you handled non-normal distributions correctly, whether your p-values and confidence intervals make sense together, and whether your conclusion actually matches what the numbers say rather than what you hoped they said. That last point matters more than most students realize going into it.
Interpreting Ecological Data Answer Key
Here is what a solid answer key should contain, and what you should be able to produce if one is not handed to you. The structure is not as rigid as it sounds because ecological data varies enough that no single template covers every case. Ecological datasets fall into a few familiar categories, and mixing them up is the single most common mistake I see students make. Abundance data counts individuals per species per plot. This is discrete, integer-valued, and almost never normally distributed. biomass data measures mass per unit area and tends to be continuous but heavily right-skewed. Presence-absence data is binary and usually gets analyzed with different methods entirely than count data. Species diversity indices like Shannon or Simpson are continuous but bounded and have their own distributional quirks. I spent an entire graduate lab session once debugging a student's analysis only to discover they had run a parametric ANOVA on species richness counts across three wetland sites. Richness data is overdispersed by nature. The variance was roughly equal to the mean multiplied by a dispersion parameter greater than one. Using an F-test on that produced a p-value of 0.03 when the correct approach, a negative binomial GLM or at minimum a Kruskal-Wallis test, gave a p-value of 0.21. The answer key in that course would have flagged the test selection immediately, but the student had no way to know without either guidance or prior exposure.
Tests and When They Apply
You need to match the statistical test to three things: the response variable type, the experimental design, and the distributional properties of your data. Here is the practical breakdown without the textbook fluff. Chi-squared goodness-of-fit or test of independence applies when you have categorical data, like observed versus expected species frequencies across habitat types. Your sample size needs to be large enough that expected cell counts are generally above five. I once saw a student apply chi-squared to a rare orchid survey with twelve plots and four species where three cells had expected values below one. Fisher's exact test would have been the correct call, though with that sample size the power was essentially zero regardless. Mann-Whitney U and Kruskal-Wallis are your go-to non-parametric options for comparing groups with ordinal or non-normal continuous data. Kruskal-Wallis is the one-way analogue of ANOVA. If you have a factorial design with two or more independent variables, you need either a non-parametric parallel like the Quade test or a permutation-based approach. Standard software rarely implements these well out of the box, which is why many answer keys default to transformed parametric tests with a note about the approximation.
Get the Full Details
Regression and correlation in ecology rarely means simple linear regression on raw data. Species-area relationships are logarithmic. Dose-response curves are sigmoidal. Distance-decay patterns are often best modeled with exponential or negative exponential functions. If you fit a straight line to a species-area dataset, your R-squared will look reasonable but your predictions will be garbage outside the observed range. Log-transforming both axes usually fixes this, and a correct answer key should show that step explicitly. Multivariate methods like NMDS, PCA, and PERMANOVA come up when you are dealing with community composition data. These are where answer keys get most useful because the output tables are dense and easy to misread. An NMDS stress value above 0.2 generally means the ordination is not trustworthy. Below 0.1 is fine. Between 0.1 and 0.2 sits in a grey zone where the pattern might be real but you should be cautious. Most students skip reading the stress value entirely and move straight to interpreting group separation that may not exist.
How to Use an Answer Key Effectively
The hardest part is not finding the right answer, it is checking whether your process matches the one the key assumes. Two people can reach the same conclusion through different valid paths, and a poorly designed answer key will mark both wrong. Here is how I recommend working through it. First, write down your null hypothesis and alternative hypothesis before you touch any software. I know this sounds like a rote exercise, but it forces you to articulate exactly what question you are answering. Then run your analysis and record the test statistic, degrees of freedom, p-value, and effect size. An answer key that only lists the p-value is incomplete. Effect size tells you whether a statistically significant result is ecologically meaningful. A study might find a significant difference in invertebrate biomass between two stream reaches with a p-value of 0.001, but if the difference is 2 milligrams per square meter, nobody should care. Next, compare each component of your output against the key. If your test choice differs from the key's recommendation, do not immediately assume you are wrong. Check your data structure against the assumptions of both tests. If yours fits the alternative approach better, document why. I have lost points on assignments before for using a Welch's t-test instead of a standard independent t-test when variances were unequal, only to find out later that the instructor's answer key was technically applying a test that violated its own assumptions. Pointing that out with a citation is better than silently conforming to a wrong method.
When the key shows a confidence interval, check whether it aligns with your point estimate. A 95% CI that does not include the null value should correspond to a p-value below 0.05. If your p-value says significant but your CI includes zero, you have made a calculation error or you are comparing results from different models. This mismatch is actually a very useful diagnostic that most people ignore until they are halfway through peer review.

Edge Cases That Break Standard Answer Keys
Not every ecological dataset behaves nicely. Here are a few scenarios where a standard answer key will mislead you and what to do instead. Spatial autocorrelation is the first thing that goes wrong. Samples taken close together in space are more similar than samples taken far apart, which violates the independence assumption of nearly every standard test. I worked with a stream macroinvertebrate dataset where the first ten samples were clustered within fifty meters of each other. Running a standard ANOVA on those samples gave a p-value under 0.001 for a habitat comparison that was actually non-significant once I accounted for spatial structure using a Moran's I correction and then a spatially explicit mixed model. The answer key provided with the assignment had no mention of this because the dataset was artificially clean. Real data is not. Zero-inflated distributions are the second common trap. When you sample insects with a sweep net, most samples contain zero individuals of a given rare species. Standard Poisson or negative binomial models struggle with excess zeros. Zero-inflated models or hurdle models are the correct tools, but they are rarely covered in introductory courses. If your answer key uses a standard GLM and your residuals show a massive spike at zero, the model is misspecified. Switching to a zero-inflated Poisson model changed my AIC by forty points in one project. That is not a marginal improvement.
Repeated measures and temporal pseudoreplication appear constantly in ecological studies. Taking the same ten plots every month for a year and treating those thirty-six samples as independent is pseudoreplication. The correct analysis requires a repeated measures ANOVA or a mixed model with plot as a random effect. I have seen this error in published papers with sample sizes in the hundreds. Answer keys for undergraduate labs sometimes bake this mistake in because the experimental design was flawed from the start. Flag it early. Small sample sizes with high variance produce wide confidence intervals and low power. A common answer key trap is presenting a non-significant result as evidence of no effect. The correct interpretation is that the data are insufficient to detect an effect of the observed magnitude. Reporting a confidence interval alongside the p-value makes this distinction clear. If the interval ranges from a trivially small effect to a large ecologically important effect, you simply do not know, and the answer key should reflect that uncertainty rather than forcing a binary yes or no.
Building Your Own Key When One Does Not Exist
Sometimes no answer key is available, especially with novel datasets or independent research projects. In those cases, constructing your own verification framework is straightforward. Start by documenting every decision: data transformations, outlier handling rules, test selections, software versions, and parameter settings. Then run a simulation or bootstrap exercise to check whether your pipeline recovers known parameters under controlled conditions. If you simulate data from a negative binomial distribution with a known mean and dispersion, your model should estimate those values within reasonable error bounds. If it does not, your pipeline has a bug or a misspecification. Cross-check your results against at least one alternative method. If a Kruskal-Wallis test and a negative binomial GLM give qualitatively similar conclusions, you can have moderate confidence. If they disagree, you need to investigate which assumption each method is violating in your specific case. I spent two weeks reconciling a situation where a PERMANOVA showed a significant community difference but individual species analyses showed nothing significant. The resolution was that the community-level signal was driven by coordinated shifts in several rare species that individually lacked power. Both results were correct, but they answered different questions.

Finally, keep a running log of discrepancies between your expectations and your results. Ecological data is messy, and the gap between what you thought the data would show and what it actually shows is where the learning happens. Answer keys compress that process into neat boxes, but real research does not work that way. The most valuable skill is not recognizing the right answer, it is understanding why a plausible wrong answer keeps coming up and how to adjust your approach accordingly. If you want a practical reference document, search for supplementary materials attached to recent papers in journals like Ecological Indicators or Methods in Ecology and Evolution. Those often include reproducible scripts and interpreted outputs that function as de facto answer keys for similar datasets. They are usually more accurate than anything an instructor generates from scratch because they have survived peer review.