How to Actually Learn Computer Networking Without Losing Your Mind
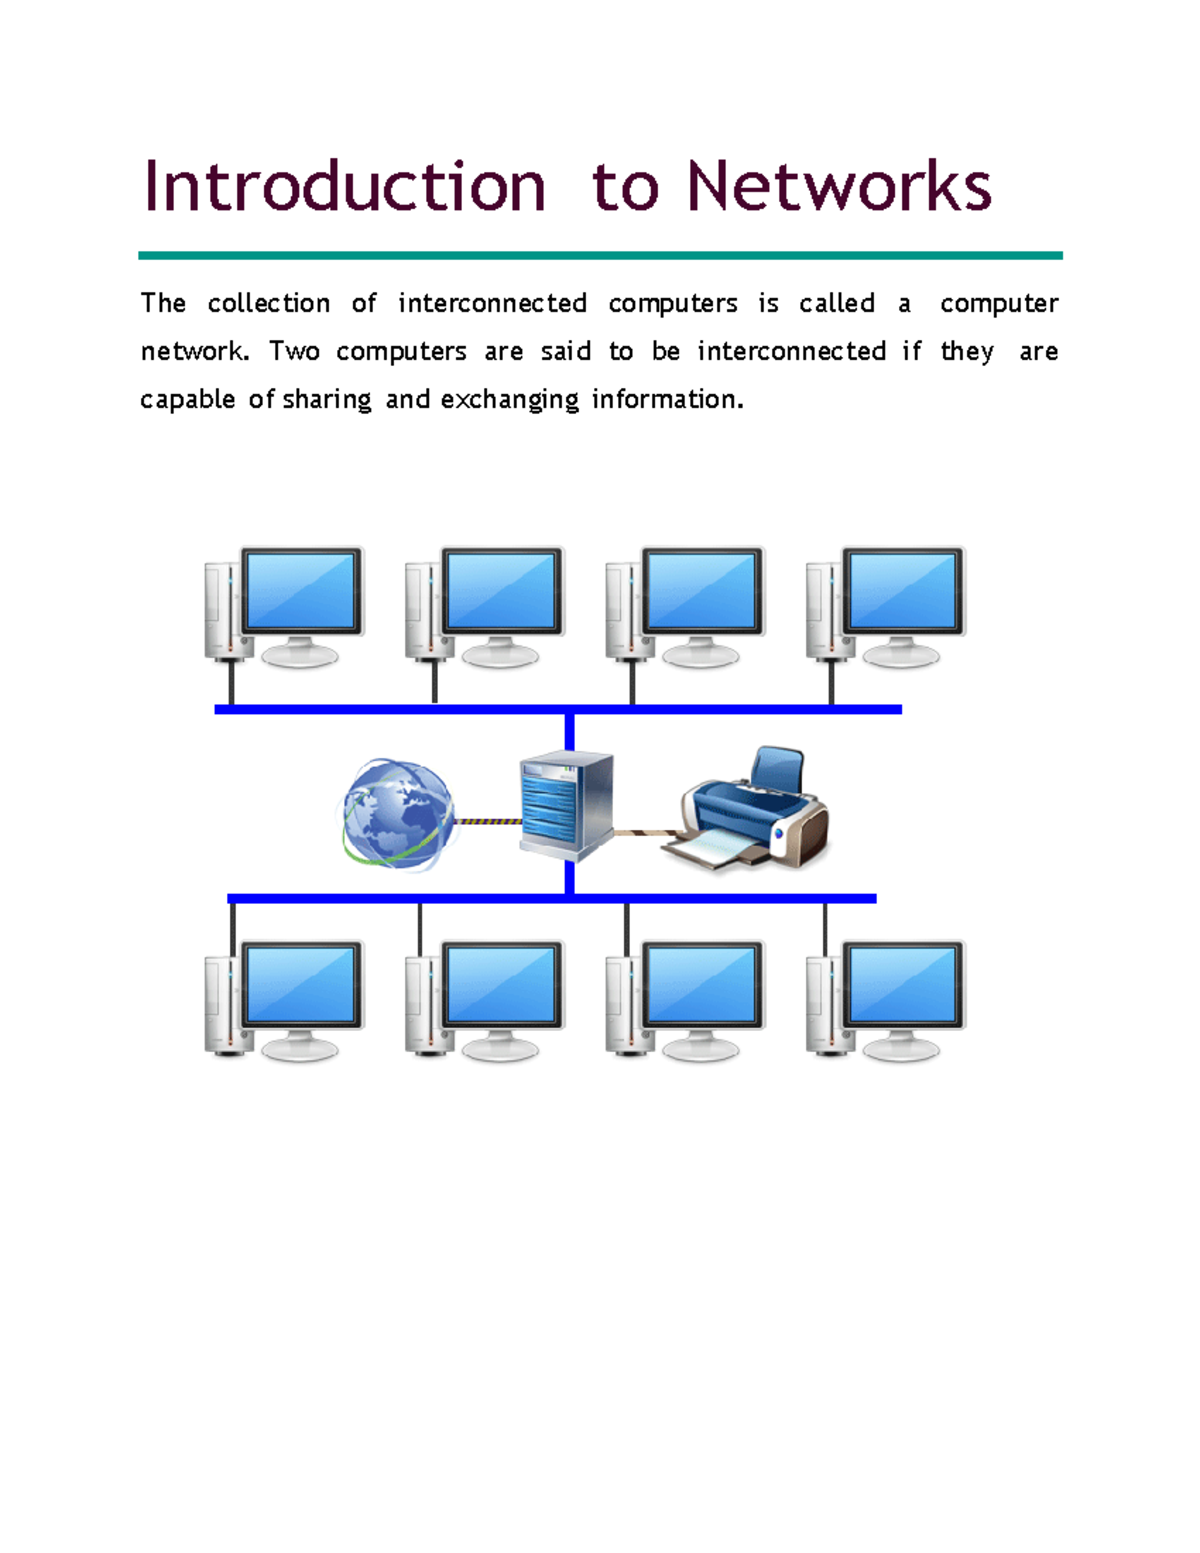
Most people approach networking by memorizing the OSI model layers. That helps with vocabulary, but it does not prepare you for what happens when a production database query times out at 2am and every layer is potentially the culprit. I learned this the hard way in 2018 while debugging a persistent TCP retransmission issue on a Kubernetes cluster that was spread across two availability zones. The application logs showed nothing wrong. The DB team swore the queries were fine. The network team insisted the infrastructure was healthy. I spent three days tearing my hair out before I realized the MTU on the overlay network did not match the underlying physical interface, causing packet fragmentation that silently corrupted certain DNS resolutions for service discovery. A simple ping -f -l 1472 against the gateway would have solved it in ten minutes.The core of any Introduction To Computer Networking Concepts course should not be the seven layers of the OSI model repeated until you are numb. You need to understand how data actually moves from one machine to another, where it gets stuck, and how to prove it. IP addressing is the foundation, but not in the way most tutorials teach it. Yes, you need to know what 192.168.1.0/24 means. What you do not get from most beginner material is an intuitive grasp of subnetting under pressure. I keep a quick-reference table taped to my monitor for converting between CIDR notation and subnet masks. When someone tells you a /27, you should immediately know that without doing arithmetic — that is 32 addresses, 30 usable. /23 is two contiguous /24s merged together. This mental fluency saves enormous time during capacity planning and troubleshooting sessions where you are being asked questions in real time. TCP and UDP are not just "reliable" and "unreliable." That oversimplification will trip you up. TCP provides ordered, acknowledged delivery through a handshake process, window-based flow control, and congestion avoidance algorithms. UDP is a datagram protocol — it sends packets and walks away. The reason UDP exists at all is because some applications, like DNS lookups or real-time video conferencing, would suffer more from TCP's retransmission delays than they would from occasional packet loss. If you send a DNS query over TCP, your resolution time goes from sub-100ms to potentially several seconds in edge cases. That single design choice matters when you are diagnosing why a microservice appears to hang on startup.
Routing and switching form the next critical piece. A switch operates at Layer 2, using MAC addresses to forward frames within a broadcast domain. A router operates at Layer 3, using IP addresses to move packets between networks. The default gateway on any host is simply the router interface that belongs to the host's local subnet. When you configure a server and forget to set the gateway, it can talk to machines on its own subnet but cannot reach anything beyond. I once spent forty-five minutes debugging why a newly provisioned compute instance could not resolve external hostnames. It turned out the DHCP lease had given it a correct IP and DNS server but omitted the gateway field entirely. The instance was functionally isolated.
Protocols That Actually Matter in Practice
DNS is the single most misunderstood protocol in enterprise networking, and also the single most common source of intermittent failures. A DNS record is not a direct mapping — it is a cached, TTL-bound approximation of reality. When you see a "server not found" error, it is almost never because the server does not exist. It is because a recursive resolver returned a cached negative response or a stale A record pointing to an IP that was recently rotated. The workaround I use consistently is to bypass the local resolver cache entirely by querying authoritative servers directly with dig @ns1.example.com hostname A. This tells you what the record actually is right now, separate from whatever your ISP or CDN has cached locally. HTTP and HTTPS deserve more than the surface-level treatment they usually get. The difference between an HTTP/1.1 connection and HTTP/2 is not just a performance footnote. HTTP/1.1 opens separate TCP connections for each request unless keep-alive is explicitly used, and browsers limit parallel connections per host to six. This means a page loading twenty resources over HTTP/1.1 creates connection overhead that HTTP/2 eliminates through multiplexing over a single TCP stream with binary framing. Understanding this distinction explains why migrating a legacy application from HTTP/1.1 to HTTP/2 often produces a visible latency improvement without any code changes on the backend. ARP resolves IP addresses to MAC addresses on a local network segment. When your machine needs to send a packet to 10.0.0.5, it first checks its ARP cache. If there is no entry, it broadcasts an ARP request asking "who has 10.0.0.5?" The owner replies with its MAC address, and the frame is addressed accordingly. This is why you can have a IP conflict on a small LAN without either machine being able to communicate properly — both respond to ARP requests with different MAC addresses, and the switch's MAC address table becomes unstable, causing intermittent connectivity that looks random but is actually deterministic once you understand the ARP tables involved.
Get the Full Details
The Tools You Should Actually Learn
tcpdump and Wireshark are not optional. They are the primary diagnostic instruments for network issues that cannot be explained by looking at logs or running standard connectivity tests. tcpdump runs on the server and captures raw packets at the kernel level with minimal overhead. Wireshark provides a graphical interface for analyzing those captures interactively. The key skill is knowing what filter to apply so you are not drowning in irrelevant traffic. A typical useful filter might look like tcp port 443 and host 192.168.1.10, which shows only HTTPS traffic to a specific server. Without filters, you will capture thousands of packets per second on any active interface. traceroute and tracert show the path packets take through intermediate routers. Each hop increments the TTL (Time To Live) field by one, and routers send back an ICMP "time exceeded" message when the TTL reaches zero. This reveals where packets are being delayed or dropped along the route. I use it constantly to determine whether a latency issue is internal to my infrastructure or somewhere in the transit path between networks. If the first three hops are fast and the latency spikes at hop seven, the problem is upstream. If every hop shows high round-trip times, the issue is likely within your own network segment. netstat and ss show active connections and listening ports on a local machine. The ss -tupn command gives you TCP connections with process names and PIDs, which immediately tells you which application is holding a particular port or maintaining a suspicious number of connections. During that same incident in 2018 I mentioned earlier, I found that a single background process had opened over two hundred ESTABLISHED connections to the database server, consuming the entire connection pool and causing timeouts for everything else. The process was not a daemon — it was a developer's local script that had been left running after a deployment script failed partway through.
Curl is far more useful than people give it credit for. The curl -v flag shows the full HTTP transaction including headers, while curl --resolve lets you test DNS resolution independently of the system resolver. I regularly use curl to verify that an API endpoint is returning expected responses from different network paths, or to check whether TLS certificates are correctly configured without opening a browser.
Common Pitfalls That Beginners Miss
The first and most costly mistake is assuming that firewalls block traffic in both directions. A firewall rule allowing inbound SSH on port 22 does not mean outbound traffic from the server on port 22 is also allowed. More importantly, stateful firewalls track connection state. Once an outbound SYN-ACK is sent in response to an inbound SYN, the firewall allows the return traffic. But if you are setting up a new service and only open the inbound port without verifying that the server can initiate outbound connections to dependency services, you will see applications that appear to work partially and then fail unpredictably. The second pitfall is ignoring the difference between latency and bandwidth. A fat pipe does not help if the round-trip time between client and server is two hundred milliseconds. TCP throughput is directly limited by latency through the formula: throughput equals window size divided by round-trip time. If your window size is capped at 64KB and your RTT is 200ms, your maximum theoretical throughput is roughly 2.6 megabits per second regardless of how wide your physical link is. This is why database queries that fetch large result sets over high-latency links feel painfully slow even on infrastructure that theoretically has plenty of bandwidth. The third pitfall is assuming that NAT (Network Address Translation) is transparent. NAT modifies IP headers and TCP checksums as packets traverse the boundary between private and public address spaces. This means that any diagnostic tool relying on IP address consistency — packet captures, logging, load balancer health checks — will show different addresses on either side of the NAT. During a migration where I moved a service from a static public IP to behind a load balancer with NAT, all the internal DNS records and firewall rules referencing the old IP became stale. Applications that had hardcoded the IP address began failing. The solution was to systematically audit every reference to the old address and update it to use DNS names instead, which took approximately four hours of work spread across three days.

A fourth pitfall involves proxy configuration. Most operating systems and applications respect the HTTP_PROXY and HTTPS_PROXY environment variables, but not all of them do. Java applications, for example, require explicit system properties or a manual proxy configuration in the JVM arguments. Python requests library respects environment variables by default, but the built-in urllib does not in all versions. When diagnosing connectivity issues through a corporate proxy, the first thing to verify is whether your specific tool is actually using the proxy at all. A simple test is to set the proxy to a non-existent address and observe whether the connection failure includes proxy-related error messages or generic timeout errors.
How to Structure Your Own Learning Path
Start by setting up a small lab. Two virtual machines connected through a virtual switch, one acting as a server and one as a client. Install a web server on one, generate traffic from the other, and watch it with tcpdump. Configure a static route on the server to send traffic for a specific subnet through the client. Break something and fix it. This takes about three hours and will teach you more than any textbook chapter on routing tables. Move on to understanding how common services work at the protocol level. Use curl to make an HTTP request and watch the TCP handshake with tcpdump running in another terminal. Use dig to query DNS and observe the UDP exchange. Use ssh and watch the key exchange happen in real time. These are not abstract exercises — they build the mental model you will rely on when something breaks in production and you need to reason through the layers quickly. Learn the difference between what is controlled by your organization and what is not. Your company controls your internal DNS, your firewall rules, your routing tables, and your server configurations. It does not control the public internet paths between your datacenter and your users' ISPs, it does not control third-party DNS resolvers, and it does not control the uptime of cloud provider transit links. When things go wrong, you need to know which layer you are responsible for and which layer requires escalation or workarounds.
Read RFC 791 for IP, RFC 793 for TCP, and RFC 1035 for DNS. Not cover to cover — just read the sections that define the packet formats and the core state machines. Understanding that an IP header has a "Fragment Offset" field explains why oversized packets cause problems. Understanding that TCP has a three-way handshake with SYN, SYN-ACK, and ACK states explains why connection establishment takes time. These documents are the primary source. Everything else is interpretation.
What Networking Cannot Solve
It is worth being explicit about the limitations of network-layer knowledge. No amount of subnetting expertise will fix an application that makes synchronous calls in a loop instead of batching them. No understanding of BGP will prevent a database from deadlocking under concurrent write load. Network tools diagnose transport problems, not architectural ones. I have seen teams spend weeks tuning TCP window sizes and enabling TCP Fast Open on a service whose actual bottleneck was N+1 query patterns generating thousands of database connections per second. The network was healthy the entire time. The application was the problem, and the metrics from the network tools had already indicated this through abnormally high connection counts and short-lived transfers that suggested bursty rather than streaming traffic patterns. Reading those indicators correctly — knowing when the network is fine and the problem lives elsewhere — is as important as knowing how to debug the network itself. Similarly, IPv6 deployment remains incomplete despite being standardized since 1998. Dual-stack configurations introduce their own failure modes, particularly around DNS return path asymmetry where a client resolves an AAAA record, receives an IPv6 address, but the return traffic from the server traverses an IPv4 path due to routing policies or intermediate device behavior. This asymmetric path handling is a known issue in mixed IPv4/IPv6 environments and can produce connectivity failures that appear random to anyone not actively monitoring both address families simultaneously. The field moves slower than most people expect. The fundamental protocols — IP, TCP, UDP, DNS, HTTP — have changed very little in two decades. The tools have improved, the deployment models have shifted toward cloud and containers, but the underlying mechanics remain the same. This is not a weakness. It means that the knowledge you build now will remain relevant for the rest of your career, which is unusual in this industry.