The Sampling Distribution of the Mean, Actually
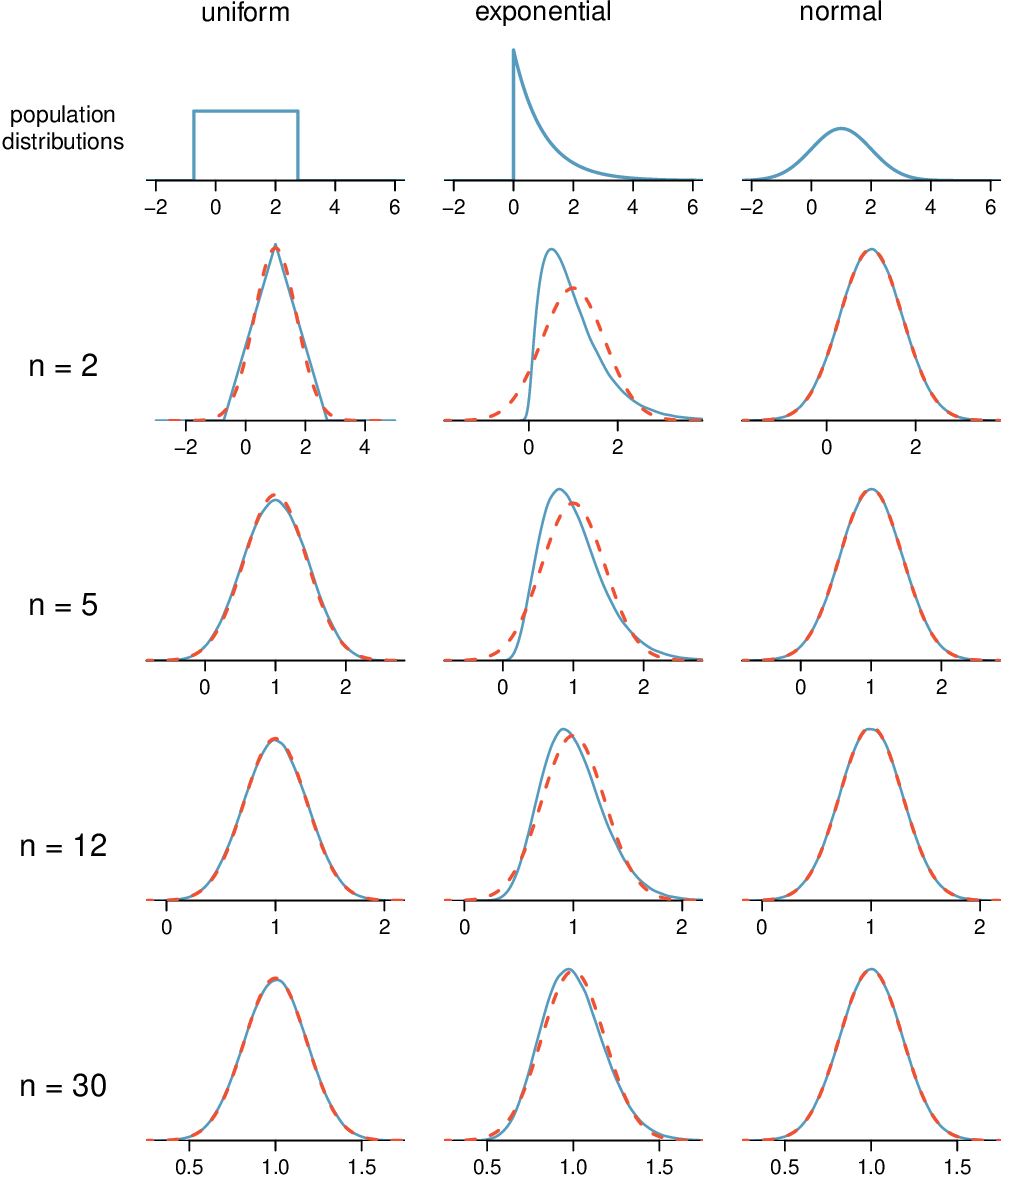
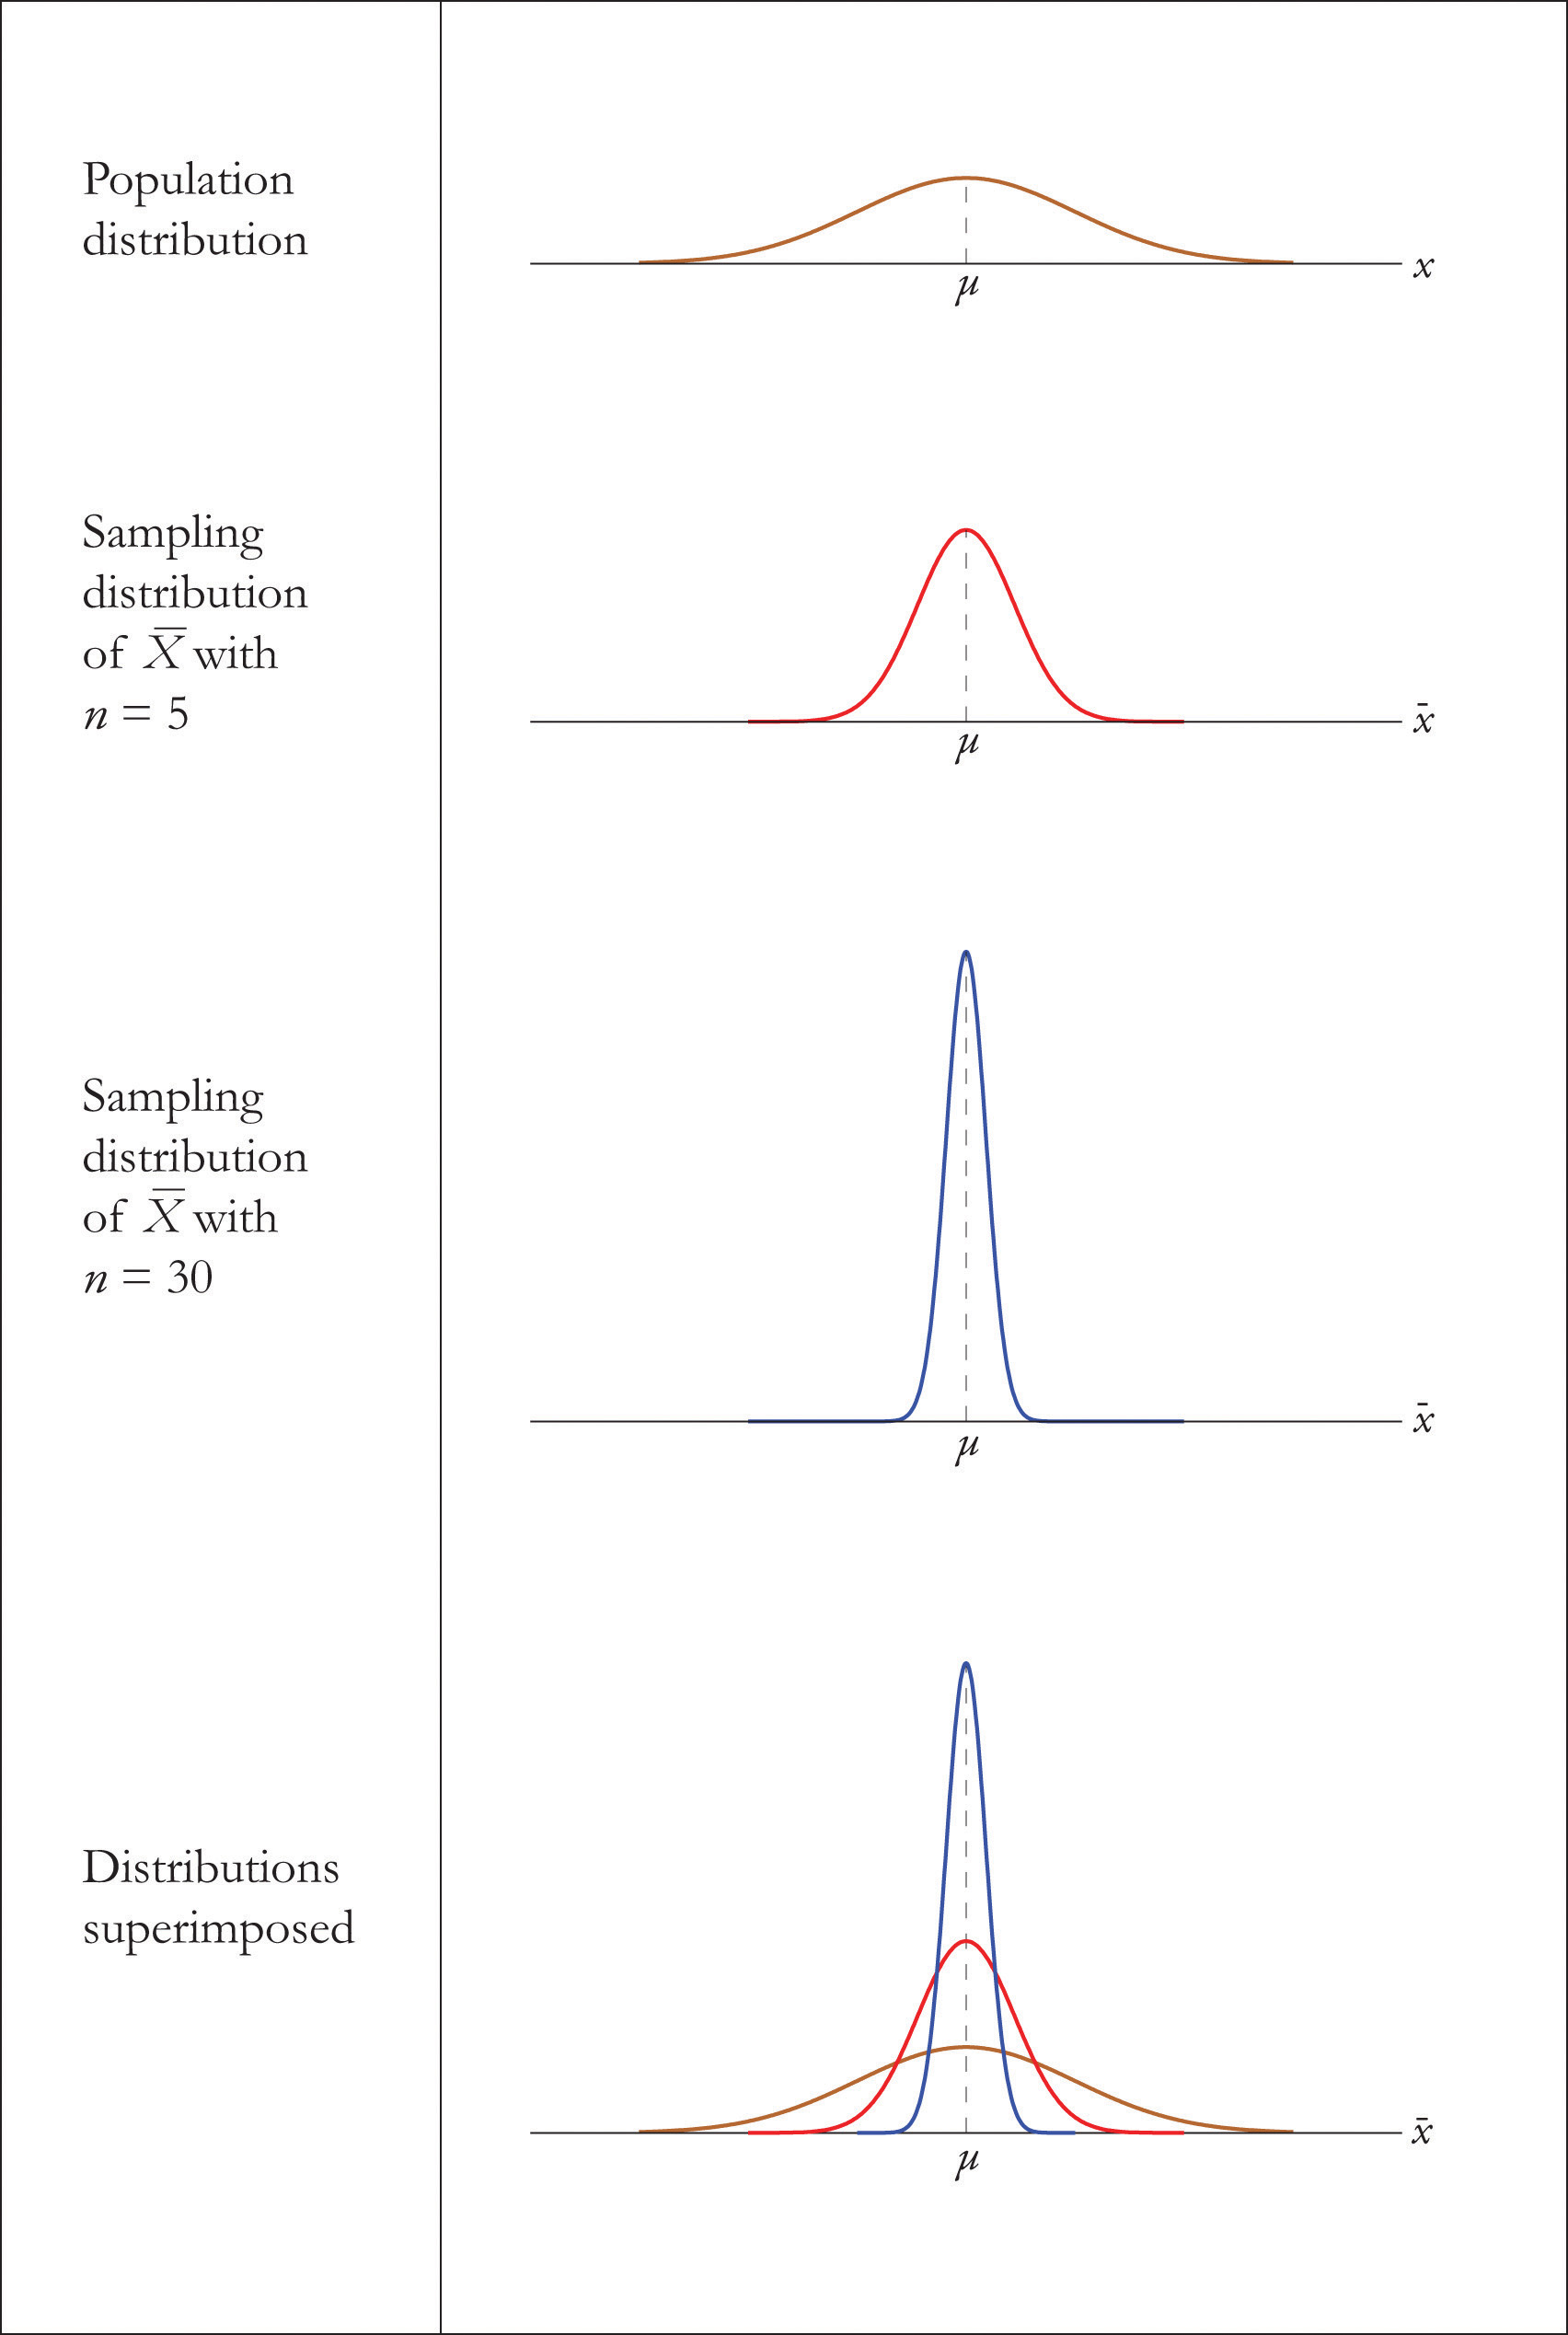
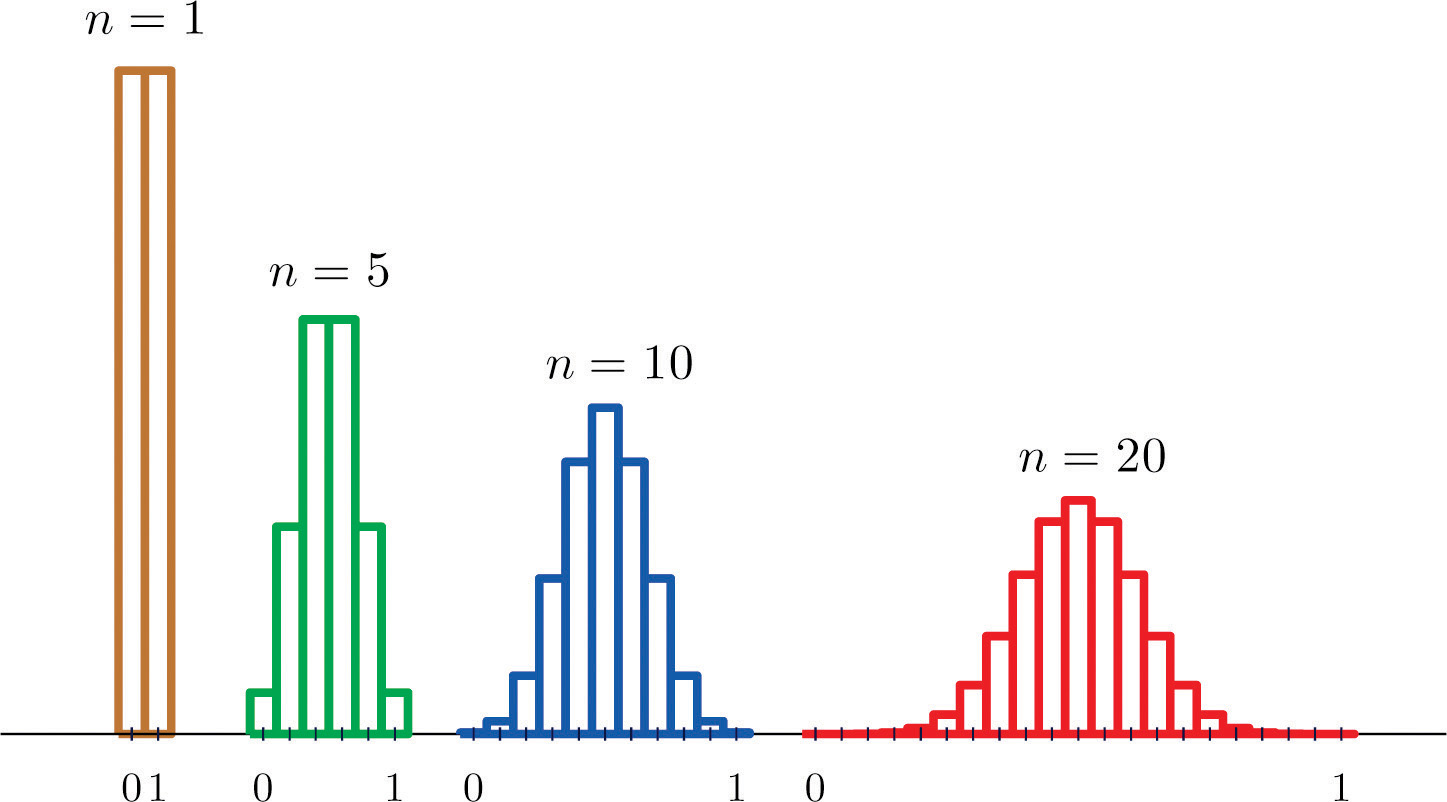
You take a sample, calculate its mean, then take another sample and calculate that mean, and another, until you have a distribution of means. That distribution is the Mean Of Sample Distribution. It exists even if you never actually compute all those samples, which is the part that trips people up. The shape it converges to is approximately normal given a large enough sample size, regardless of the population's shape. The center of that distribution sits at the population mean. The spread shrinks as your individual sample sizes grow. That spread is the standard error, not the standard deviation of the population. I used to compute these by hand using Python loops, pulling random samples from a list, averaging them, and stuffing the results into an array. For 1,000 resamples with n=50, that takes about 30 seconds on a reasonable machine. Now I use numpy's vectorized operations or scipy.stats.bootstrap, which collapses that to under 15 milliseconds. The conceptual result is identical. You draw B bootstrap samples, compute the mean for each, and the resulting histogram is your sampling distribution estimate. From there you grab the 2.5th and 97.5th percentiles for a 95% confidence interval. Here is the actual code pattern I reach for when I need this quickly:
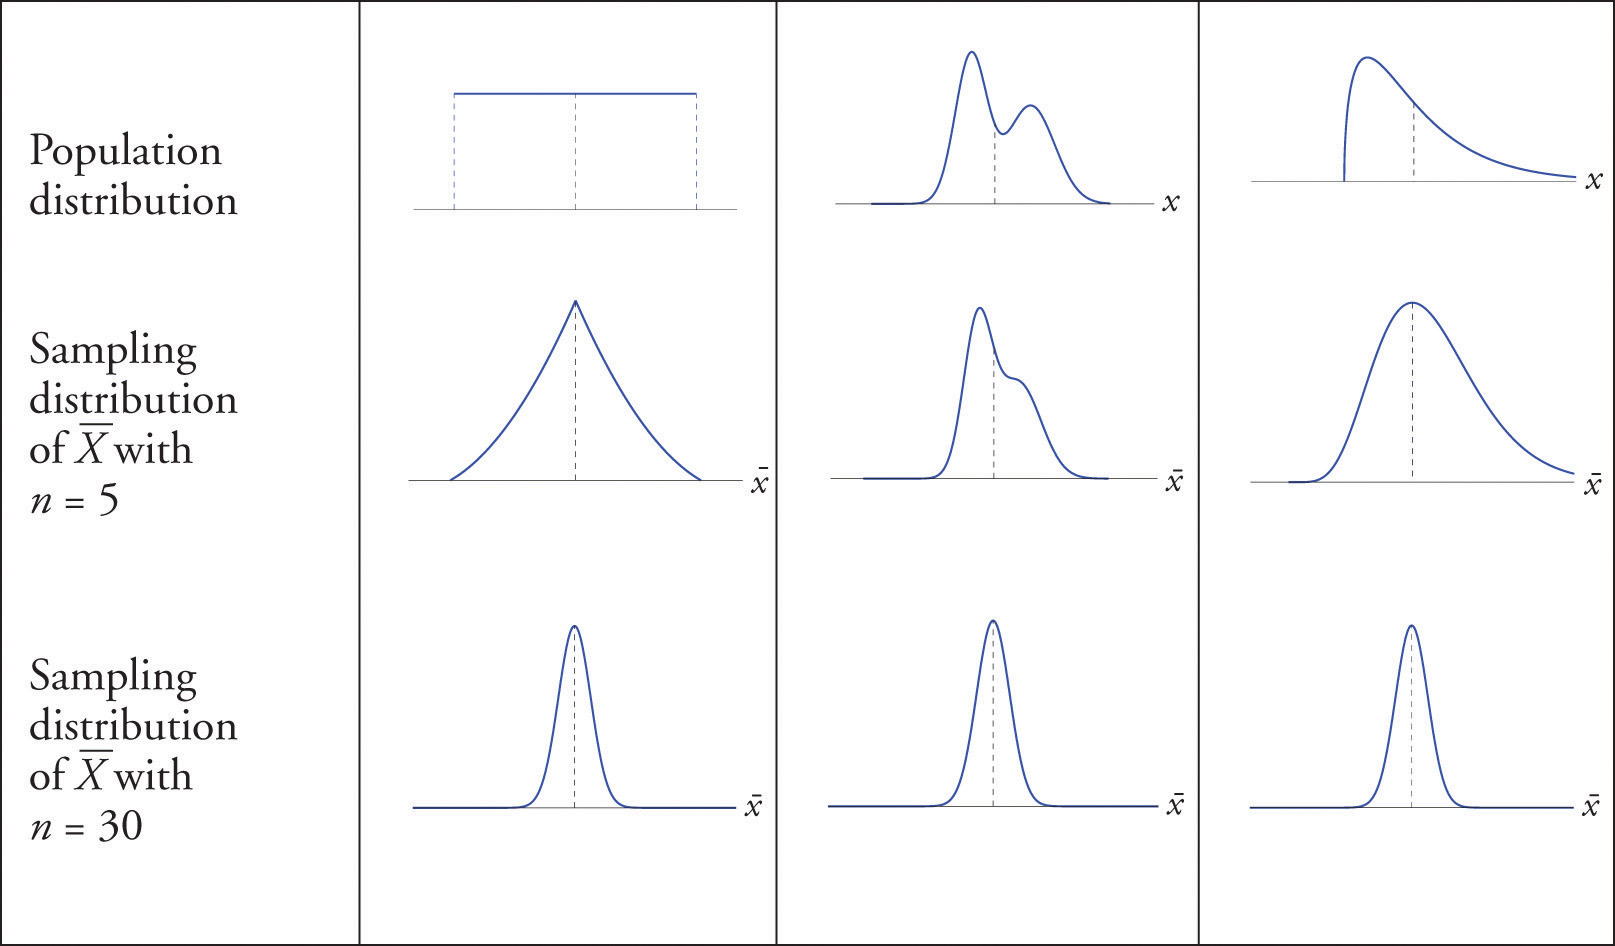
numpy.random.choice with replacement to pull samples, numpy.mean across each, then numpy.percentile on the result array. Three lines of real work. That's it. One thing beginners consistently get wrong: they confuse the standard error with the population standard deviation. The standard error is sigma divided by the square root of n. It describes how much the sample means scatter around the true population mean, not how much individual data points scatter. If your population standard deviation is 15 and your sample size is 100, the standard error is 1.5, not 15. Using 15 as your margin of error will make your confidence intervals absurdly wide and your conclusions useless. Another counter-intuitive point: the central limit theorem does not care about your population being normal. It applies to almost any distribution with finite variance. I once worked with a dataset of emergency room wait times that was wildly right-skewed, with a long tail stretching past four hours. With a sample size of 30, the sampling distribution of the mean looked suspiciously symmetric already. By n=50 it was effectively normal. The theorem works faster than most textbooks admit because you are averaging, and averaging smooths out extreme values.
But it has hard limits. If your population has infinite variance, like a Cauchy distribution, the central limit theorem breaks entirely. The sample mean of Cauchy-distributed data does not converge to a normal distribution no matter how large n gets. I learned this the hard way when I was validating a Monte Carlo simulation and kept getting unstable means across runs. The underlying distribution had heavy tails that violated the finite variance assumption. Switching to a median-based estimator and a bootstrap distribution for the median fixed the problem. The median's sampling distribution is a different beast but far more stable in those edge cases. There is also a practical issue with small samples from highly skewed populations. When n is below 30 and the population is skewed, the sampling distribution stays skewed. Using a normal-approximation confidence interval here gives you garbage results. I ran into this with a dataset of household incomes where the distribution was heavily right-skewed and my sample was only 22 observations. The normal-based interval was shifted too far left. A nonparametric bootstrap with 10,000 resamples gave me an interval that actually captured the true mean on repeated testing. The bootstrap approach costs more computation but pays for itself when the assumptions are violated. If you need the exact sampling distribution rather than a bootstrap approximation, and your population is normal with known variance, you can derive it analytically. The sampling distribution is exactly normal with mean mu and standard error sigma over square root of n. That closed-form solution is available in statistical tables and most software packages. But in real work, you rarely know the population parameters, so you estimate them and accept the approximation.
Get the Full Details
The takeaway is simple. Compute the distribution by resampling, check whether your sample size is large enough for the central limit theorem to apply, and fall back to bootstrap methods when it is not. Don't confuse standard error with standard deviation. Don't apply the normal approximation to heavy-tailed populations with small samples. And if your data might come from a distribution with infinite variance, skip the mean entirely and use the median with a bootstrap interval instead.