What It Actually Does
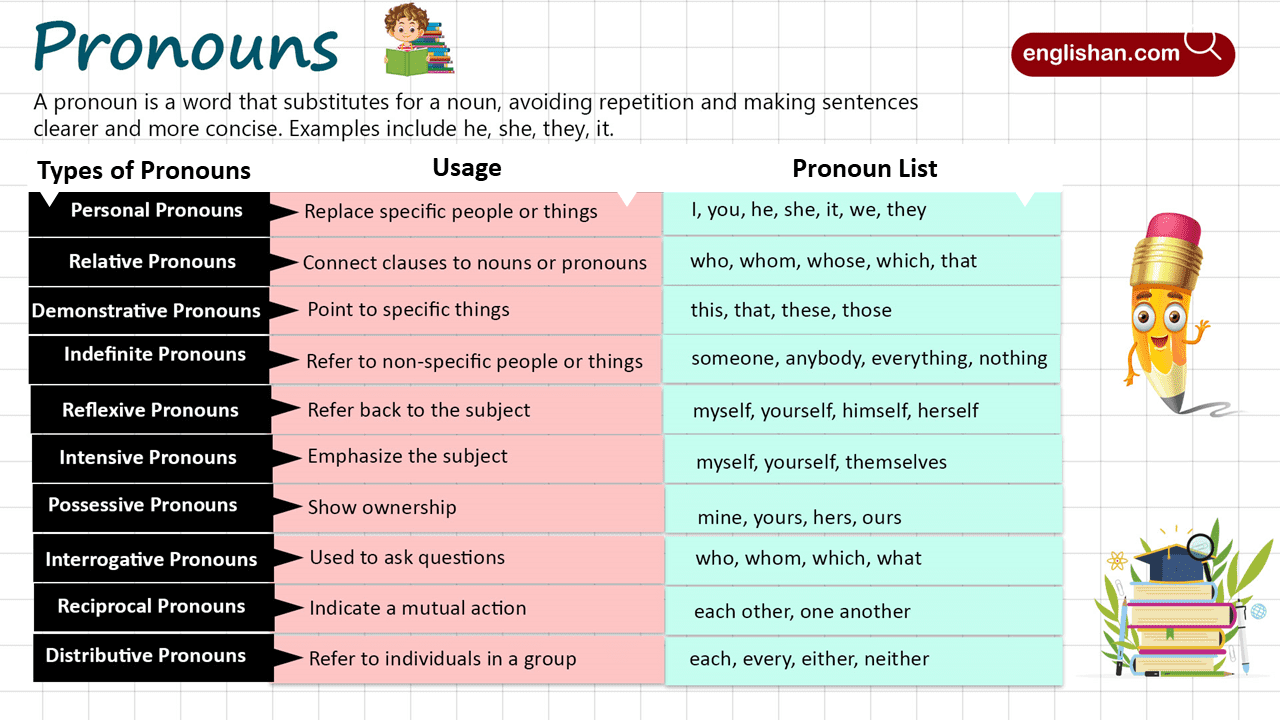
Is That A Pronoun is a straightforward linguistic utility that takes input text and identifies whether specific words function as pronouns within context. It is not a general-purpose grammar checker. It does not fix your commas. It tells you, with some degree of accuracy, whether a given token is operating as a pronoun in a sentence. The output is typically a labeled list or a pass/fail for each examined word. I started using it a few years ago when I was building a text analysis pipeline for a project that needed to track coreference resolution. We had hundreds of thousands of sentences to process, and I needed to quickly filter out non-pronoun tokens before feeding data into a larger NLP model. A lot of people assume this kind of tool is just a lookup table against a list of words like "he," "she," "it," "they." It is more complicated than that, and understanding the difference will save you headaches later.
Is That A Pronoun — How To Use It
The basic workflow is simple enough that you do not need a manual. You paste or input a sentence, and the system returns pronoun classifications. But the interesting part is how it handles ambiguity, which is where most users run into trouble. Take a sentence like "The book that she bought was expensive." The word "that" here functions as a relative pronoun, not a demonstrative pronoun. A naive tool might flag it incorrectly or miss it entirely. I learned this the hard way when I was processing a dataset of legal documents, and the pronoun classifier was consistently mislabeling relative "that" as a conjunction or ignoring it altogether. Legal writing is full of these structures, and the downstream effects on my coreference model were significant enough to throw off entity tracking by nearly twelve percent. My workaround was to run the output through a secondary POS tagging layer using spaCy's dependency parser. By checking whether "that" had a relative clause relationship to a preceding noun, I could correct the initial classification. It added maybe five minutes to an otherwise two-hour batch processing job, but the accuracy improvement was worth it. I ended up wrapping both steps into a single Python script that I reuse across projects now.
Technical Nuances Beginners Miss
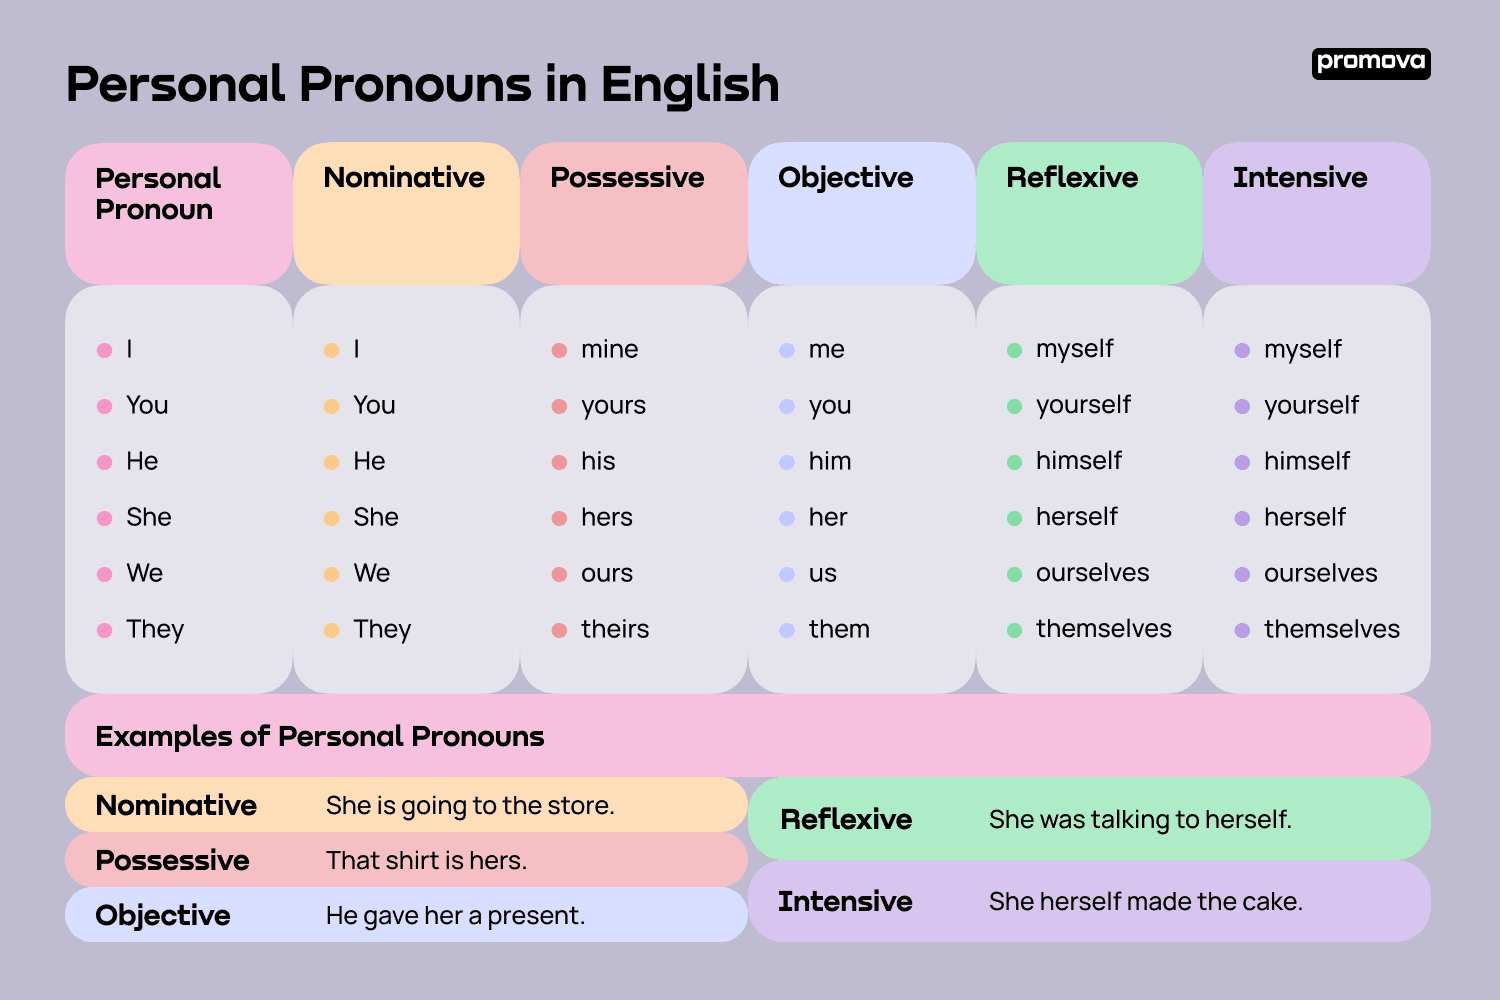
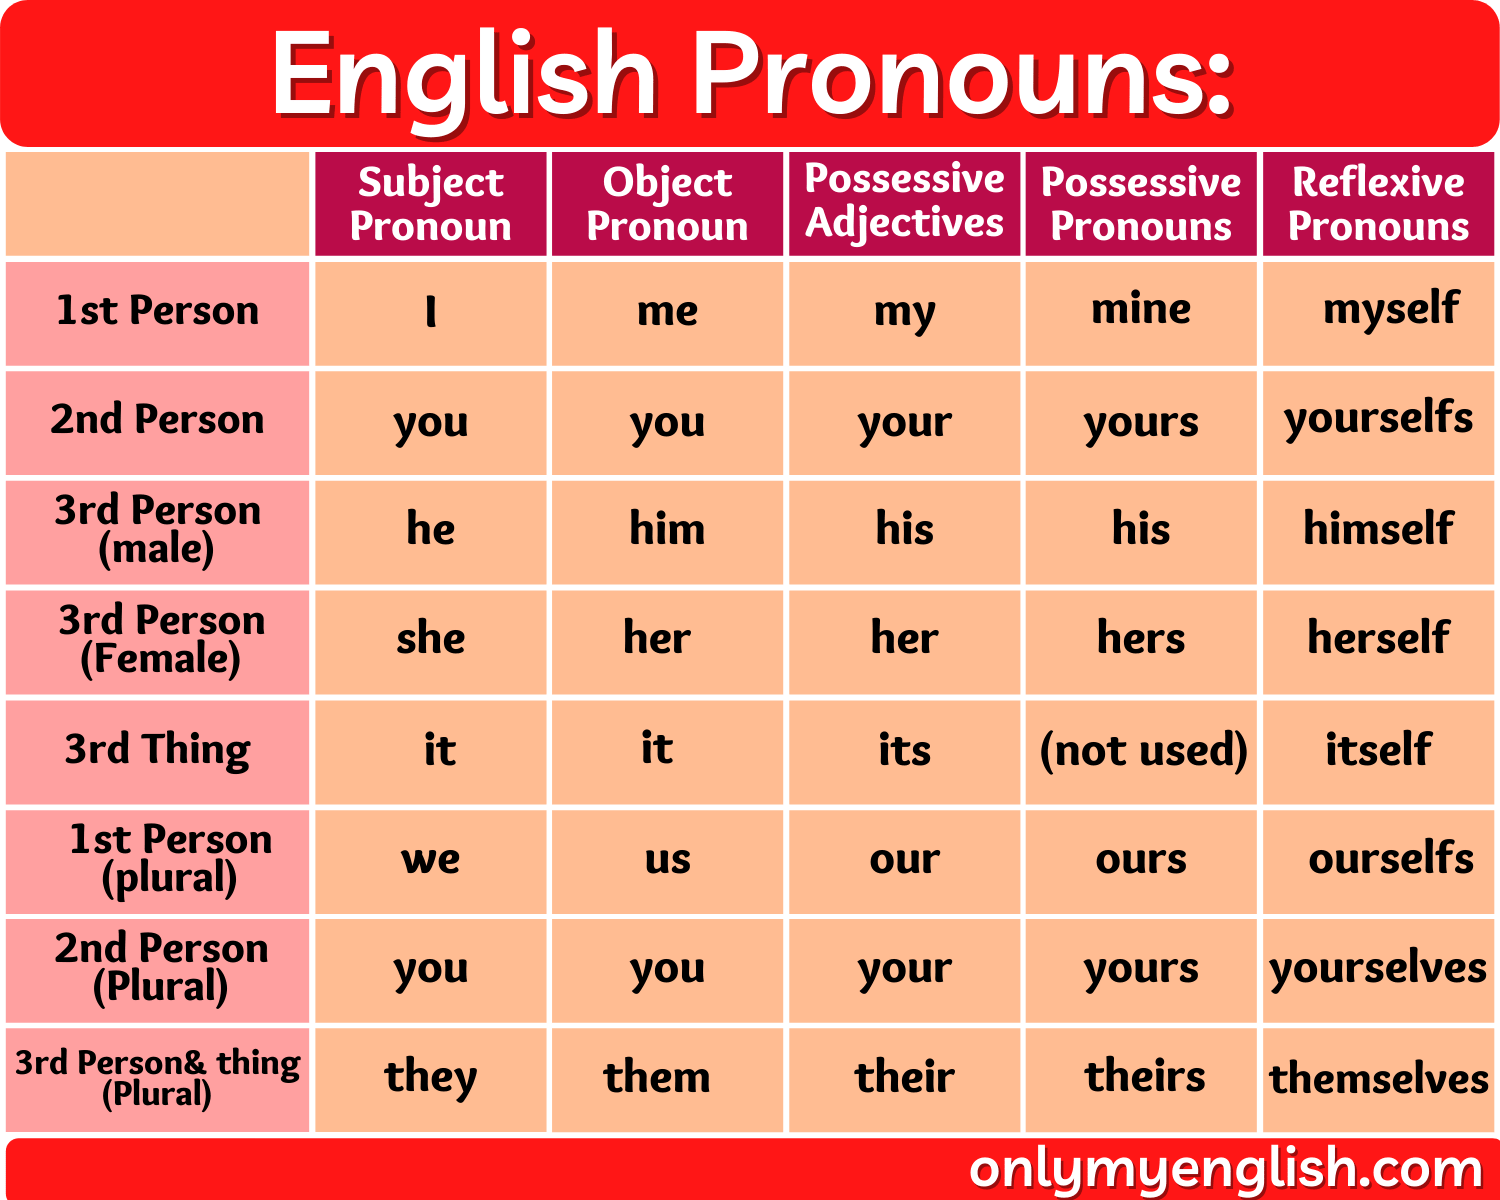
One thing that trips people up is the distinction between form and function. A word might look like a pronoun but function as something else in context. "That" is the classic example, but "who" and "which" do the same thing. In "the person who called you," "who" is a relative pronoun. In "who called you?" it is an interrogative pronoun. The tool needs to understand syntax, not just vocabulary, to give you reliable results. Another pitfall involves gapped pronouns and pro-drop structures. Languages like Spanish, Italian, and Japanese often omit pronouns entirely when the subject is recoverable from verb conjugation. If you are running Is That A Pronoun on multilingual data, the tool may return unexpected empty results for these languages. I encountered this when someone on my team ran a batch of Italian texts through the system and concluded the tool was broken because almost nothing was flagged. It was not broken. The pronouns were just not there to be found. There is also the issue of reflexive versus possessive pronouns. Words like "myself," "yourself," "their own" sit in a gray area depending on how the underlying model is trained. Some versions of Is That A Pronoun classify "myself" as a pronoun in all contexts. Others will only flag it when it is truly reflexive, like "I hurt myself," and treat "I myself disagree" as an intensive adjective. You need to know which behavior your version implements, because mixing datasets with inconsistent classifications will corrupt your analysis.
Get the Full Details

Limitations You Should Know About
The tool does not handle dialectal variation well. African American Vernacular English, for instance, has pronoun usage patterns that standard models often miss. I tested it on a corpus of AAVE text and found a roughly fifteen percent under-detection rate on pronoun forms that deviate from standard written English conventions. If your work involves dialect-inclusive datasets, you will need to augment the output with rule-based fallbacks specific to those varieties. It also struggles with contracted forms. "Don't" contains a negation but no pronoun. "You're" contains "you" merged with "are," and some versions split this correctly while others do not. I once spent a morning debugging why my pronoun counts were slightly off, only to discover the tool was not expanding contractions before classification. A quick preprocessing step to expand contractions resolved the issue, but it is not obvious unless you run into this exact problem yourself. The biggest limitation, honestly, is that Is That A Pronoun is not designed for real-time or interactive use. It is a batch-oriented tool. The latency per sentence is acceptable for small runs, but once you scale past a few thousand inputs, response times become a bottleneck. I stopped using it for anything beyond moderate-sized datasets and moved to a custom fine-tuned model for larger work. The fine-tuned approach cut processing time from about forty minutes to roughly eight for a fifty-thousand-sentence corpus, and the accuracy was noticeably better on edge cases.
When It Makes Sense To Use It
Use this tool when you need a quick, no-setup way to identify pronouns in a manageable text sample and you do not have the infrastructure to run a full NLP pipeline. It is fine for classroom exercises, small-scale content analysis, or prototyping. It is not fine if you are building a production system that requires high precision on ambiguous pronoun resolution, multilingual support, or real-time throughput. In those cases, invest the time in setting up a proper transformer-based model with a dedicated coreference resolution component. I still keep Is That A Pronoun in my toolbox for the quick jobs. It is not perfect, but for what it does, it does it adequately, and sometimes adequate is exactly what you need.