Finding the pI Without Losing Your Mind
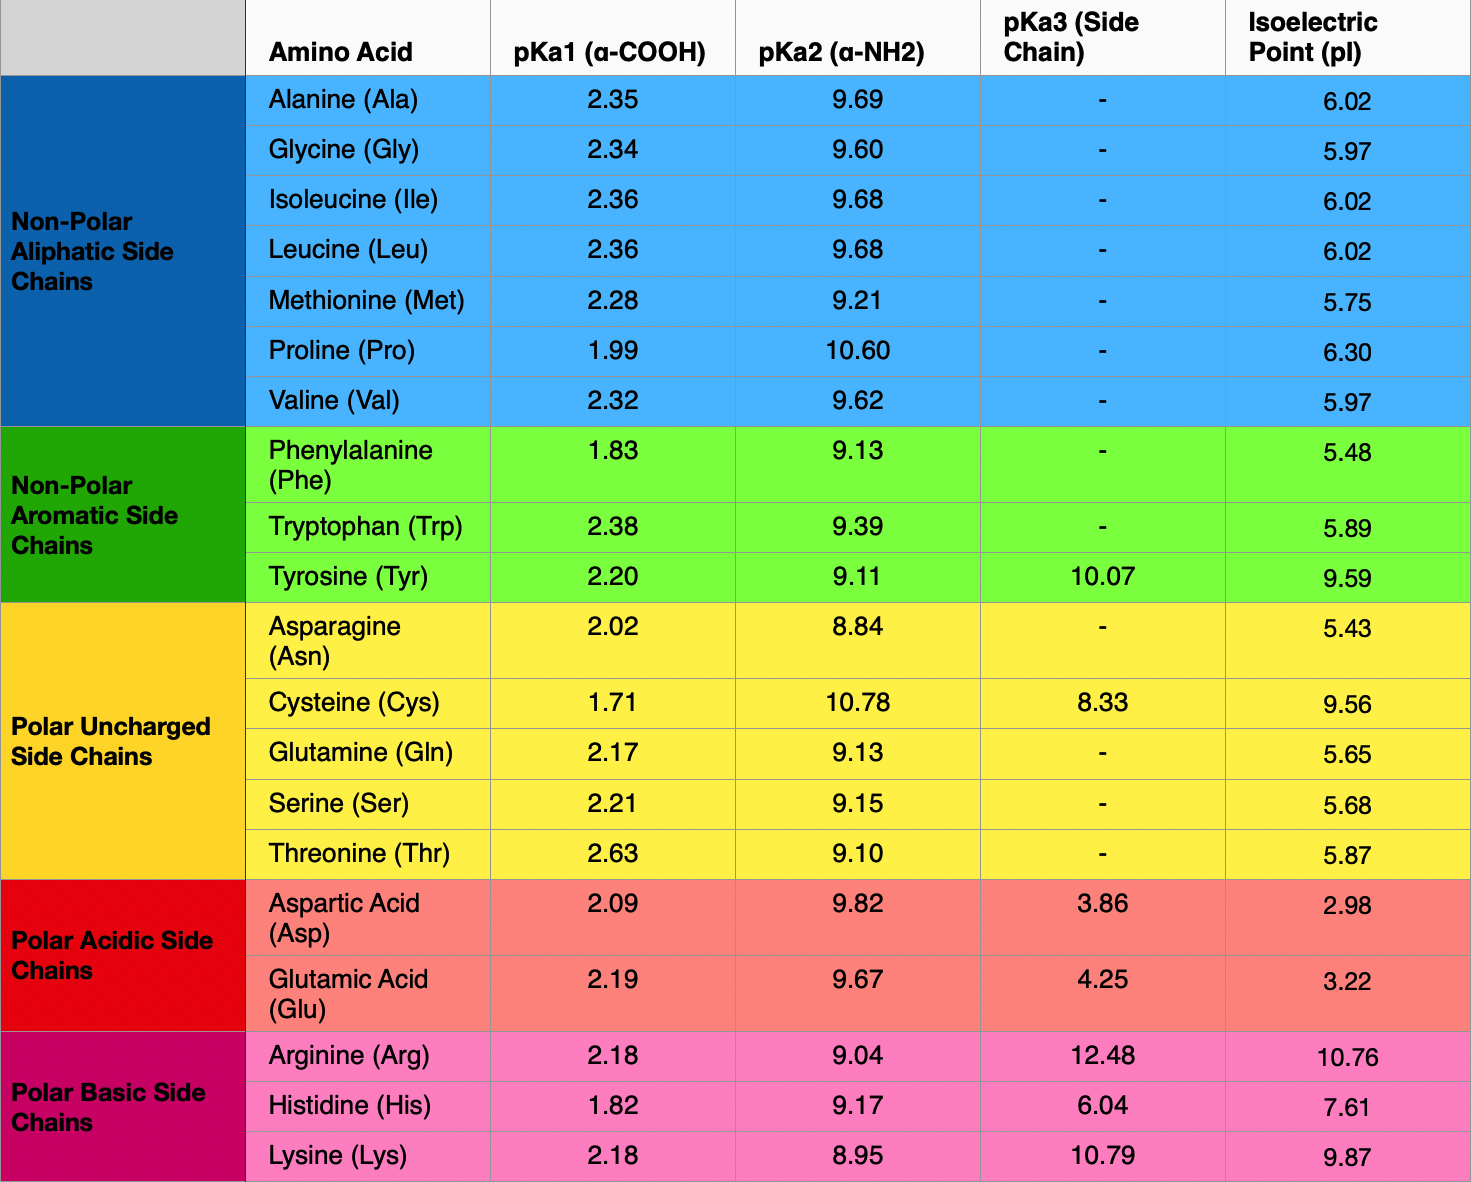
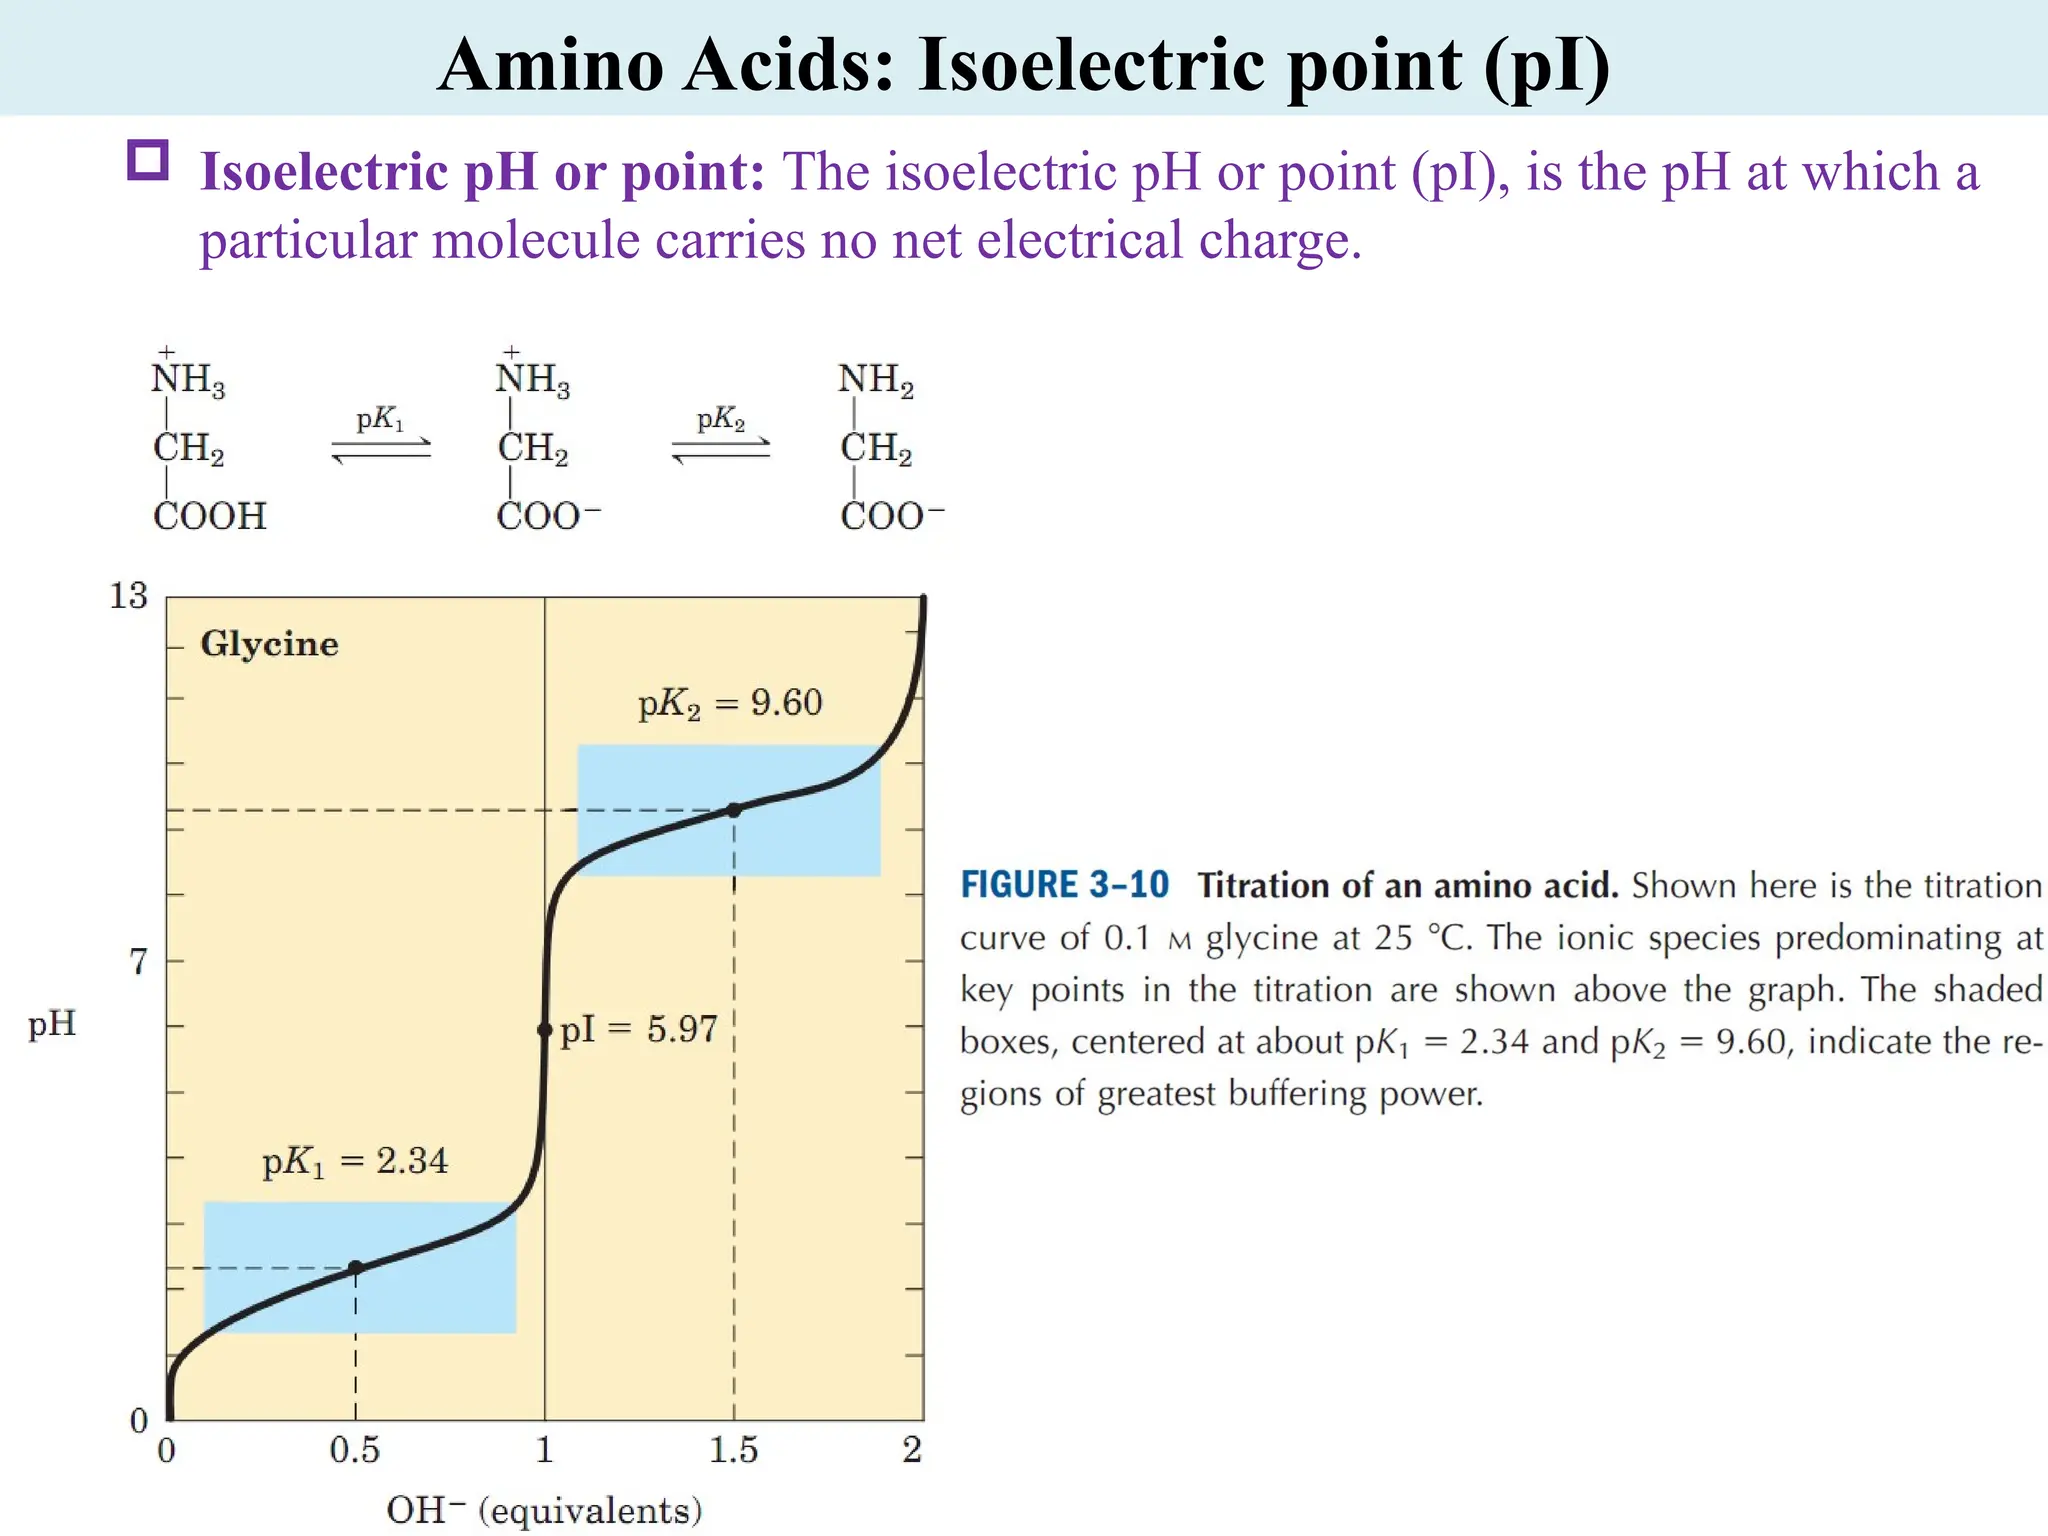
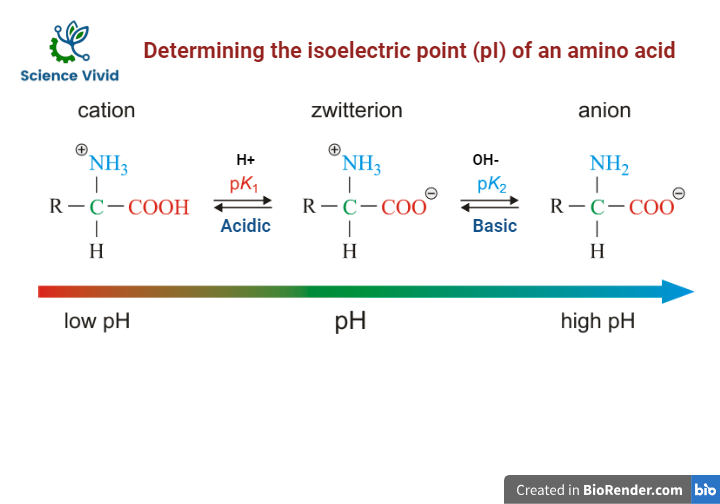
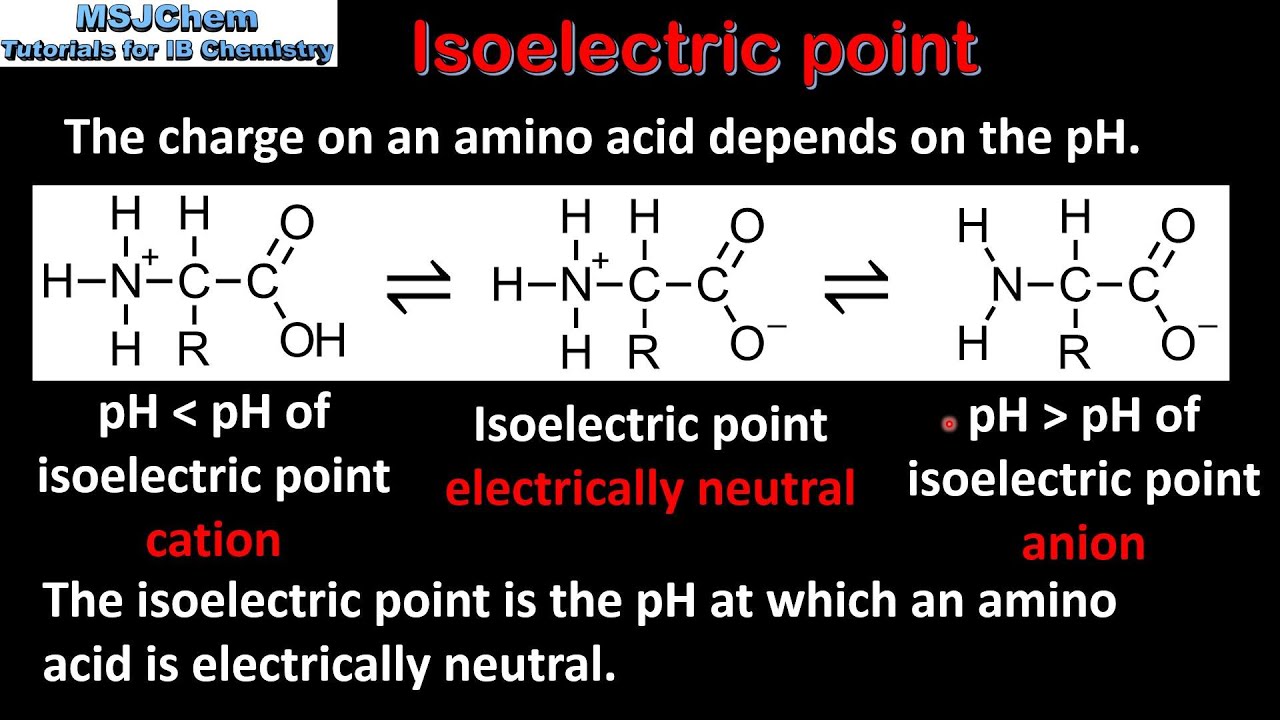
The isoelectric point is the pH where a molecule carries no net electrical charge. For standard amino acids with two ionizable groups, you average the two pKa values that bracket the neutral species. For amino acids with a third ionizable group on the side chain, you still average the two relevant pKa values, but picking which two is where most people trip up. Take glycine as the simplest case. It has a carboxyl group at pKa1 = 2.34 and an amino group at pKa2 = 9.60. The zwitterion exists between those two values. Average them: (2.34 + 9.60) / 2 = 5.97. That's the pI. Done. For alanine it's nearly identical. For glutamic acid, the side chain carboxyl has a pKa around 4.25, so the three pKa values are roughly 2.19, 4.25, and 9.67. The neutral species sits between 2.19 and 4.25, so the pI is (2.19 + 4.25) / 2 = 3.22. You average the two lowest pKa values for acidic amino acids. For basic amino acids like lysine, with pKa values around 2.18, 8.95, and 10.53, the neutral species is between 8.95 and 10.53, giving a pI of about 9.74. You average the two highest. This works fine on paper. In practice it gets messier fast.
What Actually Happens in the Lab
When I first started working with peptide purification, I treated pI calculations like exact numbers. They aren't. The pKa values you find in textbooks are measured for free amino acids in dilute aqueous solution at 25 degrees Celsius. The moment you put a residue inside a peptide chain, every adjacent side chain shifts the effective pKa by anywhere from half a unit to a full unit. Neighboring charges matter. Local dielectric environment matters. Hydrogen bonding networks matter. The calculated pI becomes a rough estimate at best. I spent two days trying to optimize an ion-exchange step for a 14-residue peptide because my calculated pI didn't match the experimental behavior. The sequence had two adjacent lysines near the C-terminus. The textbook pI calculation said the peptide should be positively charged at pH 8.5. It wasn't. The local electrostatic repulsion between those two lysines pushed the effective pKa of one of them down enough that the net charge at pH 8.5 was barely positive. I ended up running a pH gradient from 6.0 to 9.0 instead of targeting a single pH, and that's when things actually separated cleanly. A broad gradient takes about ten minutes on a prep HPLC system. A single pH target based on a bad pI guess can waste an entire morning with nothing to show for it.
When the Textbook Math Breaks Down
The biggest gap between theory and reality involves modified amino acids. Phosphoserine, phosphothreonine, and phosphotyrosine each add a phosphate group with pKa values around 1.0 and 6.5. A singly phosphorylated residue drops the pI dramatically. A peptide that would normally elute at pH 7 on a cation exchange column will bind tightly to an anion exchange column instead. I ran into this repeatedly during a project on post-translational modification mapping. Without knowing the modification status, my pI predictions were completely wrong and my chromatography method kept failing. Cysteine matters too. Free cysteine has a thiol pKa around 8.3, but in most peptides it's either oxidized to a disulfide or modified with an acrylamide group. Neither state contributes a chargeable group at physiological pH. If you calculate pI assuming a free thiol, you'll overestimate the pI for any peptide where cysteine is already modified. The difference is small for most peptides but it adds up with multiple cysteines.
Get the Full Details
Practical Workflow for Estimating pI
Use the ProtParam tool on ExPASy or a similar calculator for quick estimates. It handles standard residues fine. For non-standard residues, you need to supply your own pKa values or use a tool that lets you define custom parameters. I prefer to run the calculator, then manually adjust for any modifications I know are present rather than trusting a fully automated prediction on a sequence with phospho- or glycosylation sites. For peptides longer than about 20 residues, the simple averaging method gets worse because the N-terminus and C-terminus become less influential relative to the side chains. The charge state stabilizes and small pKa shifts have proportionally less effect on the overall pI, but calculating it by hand becomes tedious. A quick script that sums the fractional charges at a given pH and finds where the net charge crosses zero is more reliable than manual averaging for anything beyond tripeptides. I wrote a short Python script that does this in about fifteen lines, and it cuts my setup time for new purification methods from an hour down to maybe ten minutes. The script approach also lets you see the charge state across a pH range instead of just getting a single number. That matters more than the pI itself for method development. You want to know whether your peptide stays charged across a useful window or whether it hits a charge-neutral zone where precipitation becomes likely. I learned that lesson the hard way with a hydrophobic peptide that had a pI of 6.8. At exactly pH 6.8 the peptide aggregated and clogged my column. Running at pH 5.5 or pH 8.0 kept it soluble and moving. The pI told me where the trouble was but not how to avoid it.
Known Limitations
pI prediction tools assume ideal conditions. Temperature changes shift pKa values by roughly 0.01 to 0.03 units per degree Celsius. Organic solvents used in reverse-phase chromatography shift them further, sometimes by a full unit. Salt concentration changes the activity coefficients and shifts the apparent pI. If your method uses acetonitrile or methanol, forget about matching your mobile phase pH to a water-only pKa table. The numbers don't translate directly. The biggest limitation is that pI doesn't predict solubility or aggregation. Two peptides can have nearly identical pIs but completely different precipitation behavior because one is more hydrophobic or has exposed aromatic residues that stack. I've seen peptides with matching calculated pIs behave entirely differently during concentration steps. The pI calculation is a starting point, not a guarantee. Always run a small solubility check at your target pH before committing a full purification to the method.