Getting a Handle on Language Maps for South America
The first thing most people get wrong about the Language Map Of South America is assuming it is a single resource you can download and trust. It is not. What you end up with is a collage of overlapping datasets from Glottolog, Ethnologue, the Endangered Languages Project, SIL International, and various national census bureaus that do not talk to each other. I spent about three weeks trying to reconcile these sources for a project on Quechua dialect boundaries in southern Peru, and the best approach was to stop looking for one map and instead build your own composite in QGIS. Download Glottolog. The current version has the most reliable phylogenetic classification of South American languages, including the better-documented families like Quechuan, Aymaran, Tupian, and Cariban, plus the dozens of isolate languages in the Amazon basin that have no accepted genetic affiliation. Glottolog does not give you nice colored polygons on a map. It gives you latitude-longitude point data for each documented language variety and a CSV export you can load directly into QGIS. That is where the work starts. Ethnologue is worth using alongside it for population estimates and ISO 639-3 codes, but be aware that Ethnologue sometimes conflates dialects with separate languages in the Andean zone. The Quechua IUPA (International Quechua Union) standardization map and the actual speech patterns on the ground do not align in predictable ways. I ran into this exact problem when my initial overlay placed what Ethnologue labeled a single Quechua variety across three separate provinces in Cusco. The workaround was to pull the Glottolog entry for each variety and match it against municipal census data from INEI in Peru and DNEI in Bolivia to see which administrative zones actually had self-identification matching those language labels.
The Data Layers You Actually Need
There are three layers that matter and several that will waste your time if you try to use them as primary sources. The first layer is the language occurrence points from Glottolog. These are sourced from fieldwork, older missionary records, colonial documents, and census counts. The dates range from the 1600s to 2024, which means a point labeled from 1742 may reflect a language that has since gone extinct or shifted significantly. I flagged all pre-1950 points in my project and gave them half weight when calculating speaker density. It is not perfect, but it kept old data from inflating the apparent vitality of languages like Yurakaré and Movima in the Bolivian lowlands. The second layer is national census data. Brazil's IBGE, Peru's INEI, Bolivia's INE, Colombia's DANE, and Ecuador's INEC all publish language censuses at different intervals and with different question formats. Some ask about language spoken at home. Some ask about ancestral language. Some ask both and the numbers do not correlate. When I pulled the 2017 Peruvian census language data against the 2022 Bolivian census, the self-identification rates for Aymara and Quechua differed by roughly eighteen percentage points even in border municipalities where the same communities were counted. Use census data as directional guidance, not as definitive speaker counts.
The third layer is the atlas of endangered languages from the UNESCO Atlas of the World's Languages in Danger. It is useful for understanding which languages are documented as vulnerable, endangered, or critically endangered, but the categorization criteria are vague and the listings are not updated consistently. I stopped using it as a primary source and only referenced it when I needed a quick way to flag languages that most linguists consider at risk. For actual conservation decisions, you need peer-reviewed sociolinguistic studies, not the UNESCO list. The layers you can ignore are the Google Earth community uploads, most government tourism websites that feature indigenous languages, and any dataset labeled as a "language map" on a personal blog without a methodology section attached. These tend to reproduce each other's errors.
Get the Full Details
The Amazon Problem
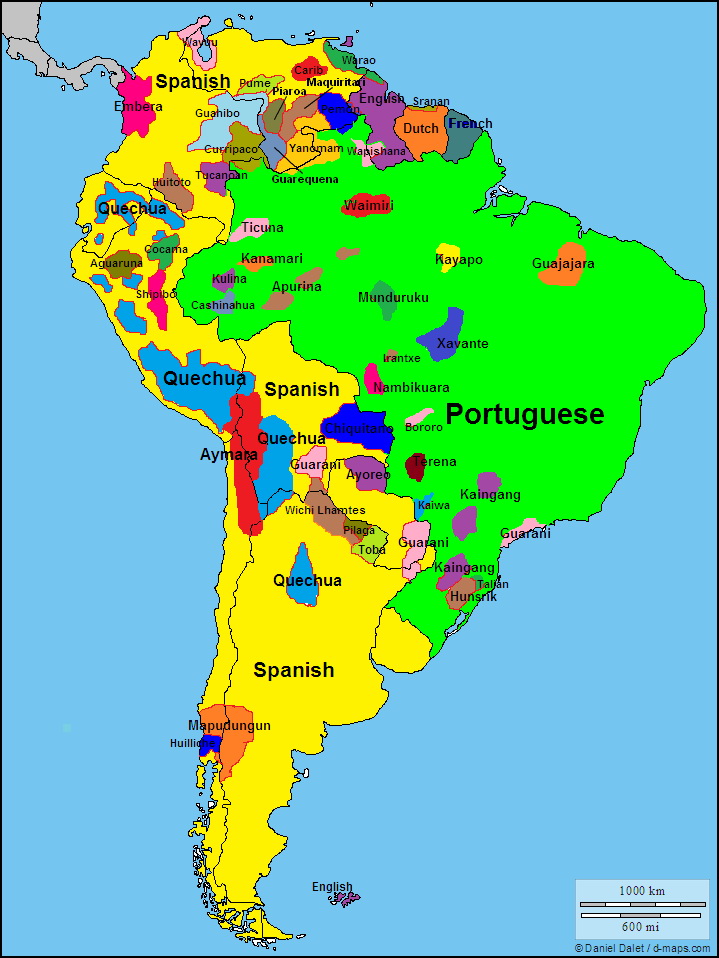
Here is the part nobody warns you about: the western Amazon has thousands of languages with minimal documentation, and the point data you find online is heavily skewed toward languages near roads, rivers, and mission stations. The interior forest regions between the Andean foothills and the Brazilian shield have far fewer recorded language points than the actual linguistic diversity there probably warrants. When I tried to fill gaps in the Ucayali and Huallaga river regions of Peru, I ended up relying on a mix of Sil International ethnographic reports, the Language Endangerment Database at ELDP, and a handful of PhD dissertations that had GPS coordinates in their appendices but nowhere else in the published text. The workaround I used was to run a kernel density estimation in QGIS on the known language points, then overlay it with ecological zone data and Indigenous territory boundaries from ORPIA in Bolivia and APIB in Brazil. The resulting heat map showed where the documented points were thinnest relative to the number of recognized indigenous territories. Those thin areas are where new fieldwork is needed, not where you should confidently place a new language boundary on a map.
Common Pitfalls That Will Cost You Time
Coordinate systems are the first trap. Most of the point data uses WGS84, but a few older census datasets use SAD69 or SIRGAS. If you mix them without reprojecting, your points will drift by up to two hundred meters in certain regions of Brazil and northern Argentina. Reproject everything to WGS84 before you start combining layers. Language names are the second trap. Guaraní has multiple standardized orthographies depending on whether you are working in Paraguay, Bolivia, Argentina, or Brazil. The same applies to Quechua, which splits into Southern, Central, and Northern variants with internal subdivisions. If you search for a language name without the ISO code, you will pull mismatched results. Always use the Glottolog identifier when cross-referencing. The third trap is political boundaries. Many indigenous language areas cross national borders, but the map layers you download from government sources often stop at the border. The Aymara-speaking area spans Peru, Bolivia, and Chile. The Quechua area spans five countries. The Tupi-Guarani family spans most of the eastern half of the continent. Any map that cuts cleanly at a national border is already distorting the data.
What the Maps Actually Show
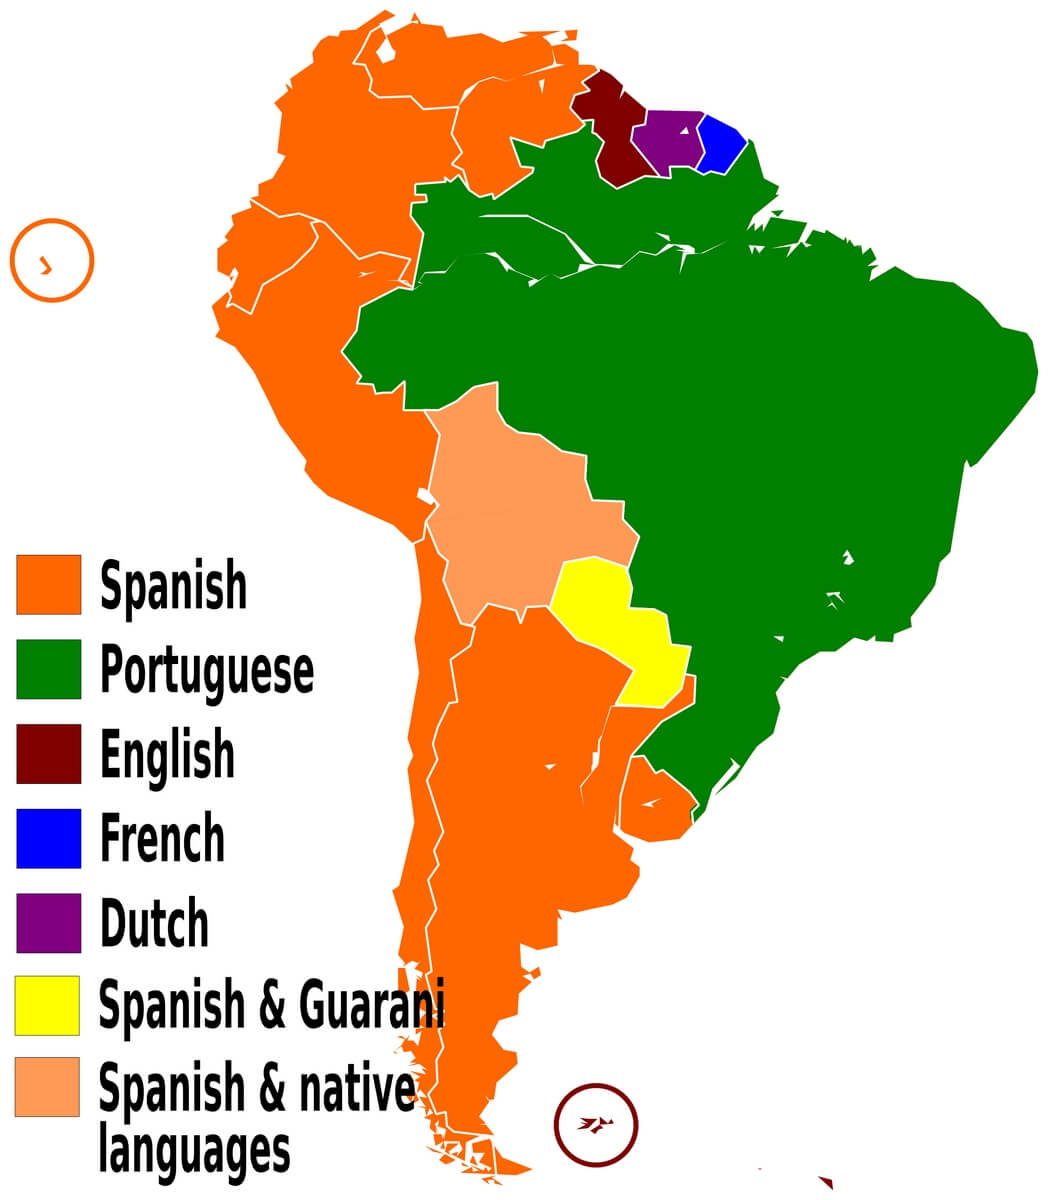
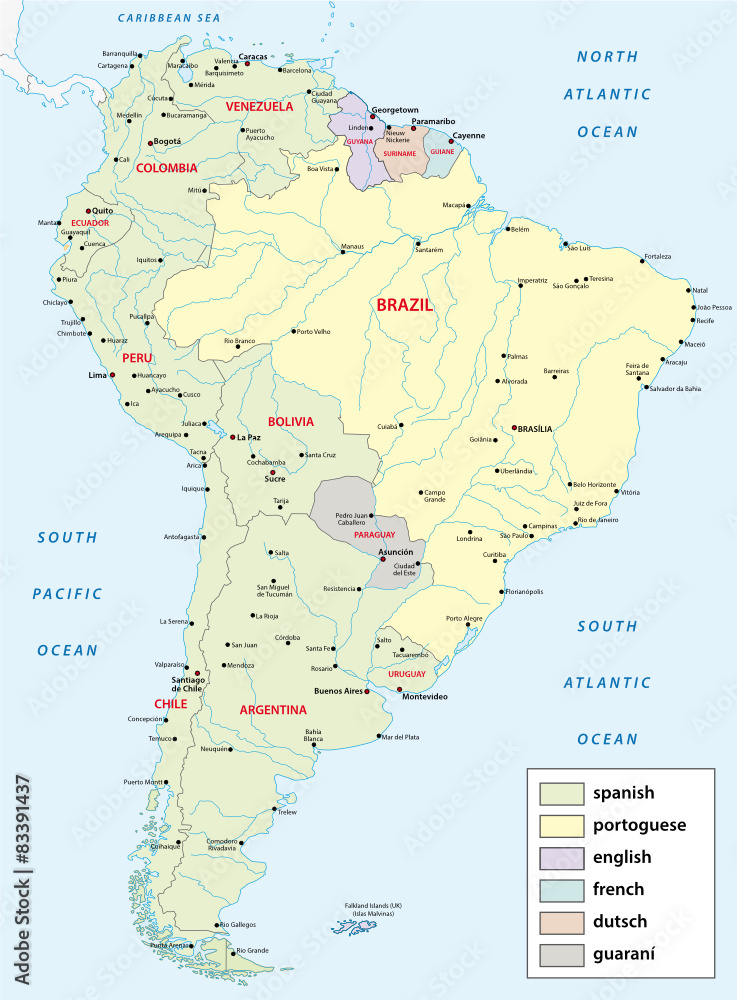
Once you have the layers sorted, the pattern is clearer than most introductory sources suggest. Spanish and Portuguese form the dominant linguistic base across nearly the entire continent at the national and urban level, but the indigenous language layer is not confined to remote areas. Quechua and Aymara have large, stable speaker populations in the highlands of Peru and Bolivia. Guaraní is an official language in Paraguay and has millions of speakers there and in parts of Bolivia, Brazil, and Argentina. In Colombia, Nasa Yuwe and Wayuunaiki have significant speaker bases with active literacy programs. In the Brazilian Amazon, a handful of languages like Yanomam and Kayapó have thousands of speakers despite being documented only in the last few decades. The areas with the most uncertainty are the Gran Chaco region, the Llanos of Colombia and Venezuela, and the southern cone of South America where indigenous languages were suppressed more completely by colonial and post-colonial policy. The southern cone is not empty, but the remaining languages like Mapudungun and Mapuche Spanish dialects operate in very different sociolinguistic conditions than the Andean languages, and any map that treats them the same way will mislead you.

How Long This Actually Takes
If you know QGIS and spend a focused day sourcing and cleaning the data, you can produce a working composite map in about six to eight hours. If you are learning the software while you work, expect a full week. The bottleneck is always the census reconciliation, not the mapping itself. Every country handles language questions differently, and the metadata is rarely consistent enough to write a clean script that automates the merge.
When to Abandon This Approach
If you need a simple reference map for general education or a classroom presentation, do not build a custom composite. Use the static maps from Glottolog's web interface or the Ethnologue interactive map. They are inaccurate in known ways, but they are published, peer-reviewed at a basic level, and updated regularly. The custom approach I described is worth the effort only if you are doing research, policy analysis, or language documentation work where the accuracy gap between public maps and reality matters.