Getting Started with Models on Hugging Face
I spent about three months actually using models from Hugging Face in production before I stopped treating it like a simple download page. The platform is not an Amazon store for AI models. It is more like a sprawling warehouse where half the boxes are labeled wrong and the rest need you to open them yourself to see what is inside. You will figure this out eventually, but starting at the right point saves time. The basic unit is the model card. Every model has one, and they range from well-maintained documentation to pages that just say "works for me" with a link to a GitHub issue. The cards contain the architecture type, training data notes if they exist, hardware requirements, and usually a license section that most people skip past and then get confused about later. Look at the license field carefully. Some models are fine for commercial use. Others are explicitly research-only and will bite you if you deploy them into anything that makes money. Behind every model card is a repository. That repository holds the actual weight files, the tokenizer configuration, and sometimes preprocessing scripts. The repository is versioned. If you load a model today and a developer pushes a fix or a better quantization tomorrow, your code will still be pointing at the old version unless you specified the commit hash. I learned this the hard way when a model started producing noticeably different outputs between my training script and my deployment script because one was pulling from main and the other was pinned to an older tag.
Downloading and Loading a Model
The standard way to get a model is through the transformers library from Hugging Face. You install it with pip and then call AutoModelForCausalLM or a similar class depending on what task you need. But the actual download process involves more than just hitting run. First, decide whether you want the full precision weights or a quantized version. Full precision models like Llama 3 8B or Mistral 7B in bf16 take up substantial GPU memory. A quantized version using QLoRA or GGUF can run on much less hardware with acceptable quality loss. I run most of my inference on 4090s now, so quantized models are the default for me. The quality difference is barely noticeable on most tasks, and the memory savings are significant enough to matter for batching. Here is a practical example of loading a model:
from transformers import AutoModelForCausalLM, AutoTokenizer
model_name = "mistralai/Mistral-7B-Instruct-v0.3"
tokenizer = AutoTokenizer.from_pretrained(model_name)
model = AutoModelForCausalLM.from_pretrained(model_name, torch_dtype=torch.bfloat16, device_map="auto") The device_map="auto" parameter tells the library to split the model across available GPUs if there is more than one. It does not always do what you expect though. When I first used it, the model loaded onto GPU 0 and left the other three completely idle because something in the model architecture had a hardcoded reference to cuda:0. Switching to explicit device placement solved it. You can map specific layers to specific GPUs manually. It takes a bit of setup but it is worth it if you are running multi-GPU.
Get the Full Details

The Real Work: Tokenization and Prompt Formatting
Loading the model is the easy part. Getting useful outputs requires understanding how each model expects its input. The instruct-tuned models on Hugging Face have conversation templates baked into their tokenizer config. You do not need to manually format the prompts for most of them if you use the chat template. But not all of them are set up correctly. I ran into this with a lesser-known Chinese model where the chat template was missing from the config entirely. My prompts were being treated as raw text instead of structured conversations, and the output quality dropped to garbage level. Adding the proper chat template manually fixed it immediately. The documentation for fixing templates is scattered across different GitHub repos and model cards. You will need to search. For model generation, control parameters like temperature, top_p, max_new_tokens, and repetition_penalty are where most experimentation happens. Temperature controls randomness. Higher values like 0.9 make the output more creative but less focused. Lower values around 0.1 make it more deterministic. Most people leave temperature at 0.7 by default and move on, but it often makes sense to tune it for your specific use case. I usually run at 0.3 for code generation because I want consistency, and at 0.8 for creative writing tasks because the variety helps.
Inference Optimization and Bottlenecks
When you start serving models at scale, latency becomes the problem. Raw transformers inference is slow for production use because it loads everything into Python and runs greedy decoding one token at a time by default. I spent weeks dealing with response times that were too long for a real-time API. The solution was switching to vLLM or TGI depending on the workload. vLLM uses PagedAttention to manage memory more efficiently and supports continuous batching. It can handle many concurrent requests without reloading the model into memory each time. For a batch of 50 requests, vLLM cut our average latency from about 3.2 seconds per request down to roughly 0.8 seconds. That is a meaningful difference when users are waiting on the other end. The tradeoff is that vLLM has its own limitations. It does not support every model architecture, and some custom modeling code will break under it. You need to check the supported architectures list before committing to it. TGI is another option from Hugging Face itself. It is purpose-built for serving models and has built-in support for quantization, tensor parallelism, and streaming responses. I prefer TGI for public-facing APIs because it has better logging and error handling out of the box. vLLM is better when you need maximum throughput and are comfortable debugging the occasional architecture incompatibility.
Fine-Tuning with LoRA and QLoRA
Fine-tuning gives you control over the model's behavior without retraining from scratch. LoRA, which stands for Low-Rank Adaptation, is the standard approach now. Instead of updating all the model weights, you insert small trainable matrices into the attention layers and keep the base model frozen. This reduces memory usage dramatically. QLoRA takes it further by quantizing the base model to 4-bit precision before applying LoRA, which lets you fine-tune large models on consumer hardware. My typical workflow uses the unsloth library for faster training and lower memory consumption. It optimizes the attention implementation and reduces peak memory by about 30 percent compared to standard transformers training. For a 7B model, this means I can fine-tune on a single 4090 instead of needing an A100. The training speed gain is also noticeable, usually 2x to 3x faster depending on the dataset size. A common mistake is overfitting quickly because the dataset is too small. I once fine-tuned a model on about 200 examples and it started repeating the same phrases after the second epoch. Reducing the learning rate and adding early stopping fixed it. You should validate on held-out data after every epoch and stop when the validation loss plateaus or starts rising.
Common Pitfalls
One issue that catches people often is context length confusion. Many models claim to support 32k tokens but the actual usable context is shorter because of how the positional embeddings are interpolated. Mistral 7B technically supports 32k but the quality drops noticeably past about 8k tokens without additional RoPE scaling modifications. If you need longer context, look for models specifically designed for it, like YaRN-enhanced versions or dedicated long-context models. Another problem is the licensing landscape. Some models use licenses that restrict commercial use even though they are freely downloadable. Open Llama had this issue early on. Mistral models are commercially usable but with restrictions on number of monthly users for their larger versions. Always read the license on the model card before using anything in a product. Hardware mismatch is also common. People see a model listed as "runs on 8GB VRAM" and assume their GPU will handle it. Those numbers are usually for quantized models at small batch sizes with low resolution. Running a model at full precision or with high batch sizes requires significantly more memory. Use a VRAM calculator or just test with a small batch first and monitor usage.
Where to Find Models
The Hugging Face Hub at huggingface.co/models is the primary source. You can filter by task type, framework, language, and license. The trending section shows what is currently popular. The papers section has models tied to academic work. For community fine-tunes and specialized models, search by base model name plus your use case. The model quality varies wildly, so check the metrics, the number of likes, and recent updates before committing to one. For pre-trained base models, stick to well-known families like Llama, Mistral, Qwen, and Gemma. They have better documentation, larger communities for troubleshooting, and more third-party tooling support. Obscure models can work well for niche tasks, but you will spend more time getting them to run correctly.
Practical Resources
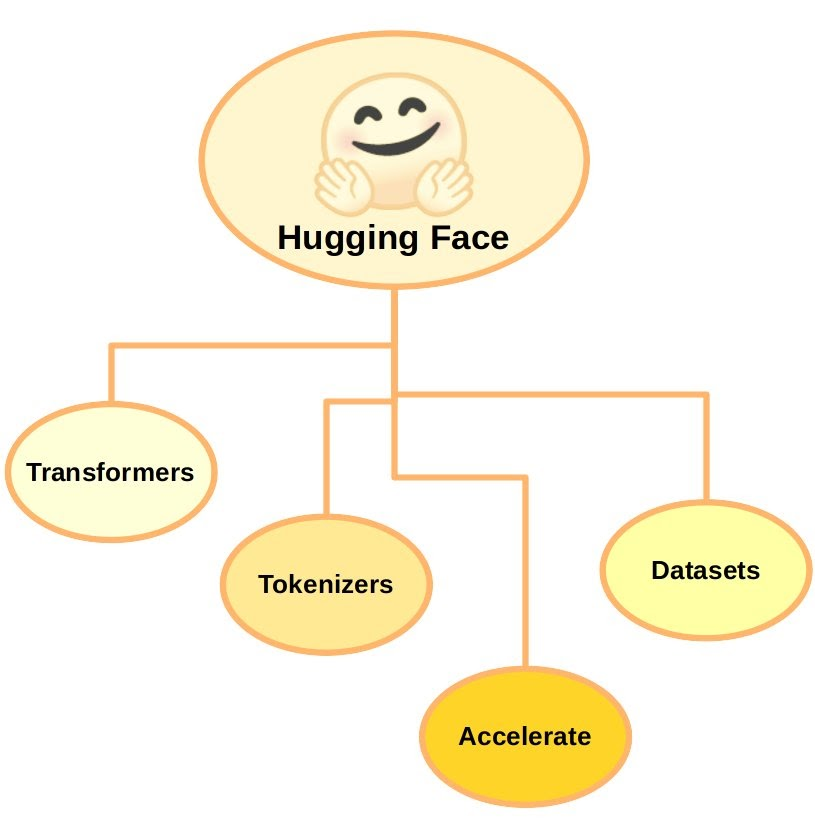
The transformers documentation at huggingface.co/docs/transformers is the reference most people need. It covers model loading, tokenization, training, and inference. The examples directory has runnable scripts for common tasks. The accelerate library handles multi-GPU and mixed precision training. The peft library manages parameter-efficient fine-tuning methods like LoRA and adapters. These three libraries cover most of what you need for working with models on the platform. For production serving, the TGI container on Docker is the simplest deployment path. It handles model loading, batching, and API serving with minimal configuration. Just pull the image, mount your model files, and set the environment variables for your model name and quantization level. There is no shortcut to getting good at this. You will download broken models, fight with tokenizer configs, and waste hours on hardware issues. But once you have the patterns down, the platform becomes quite capable. Most of the friction is in the first few weeks. After that, it is just work.