How Life Cycle Assessment Actually Works When You Open the Spreadsheet
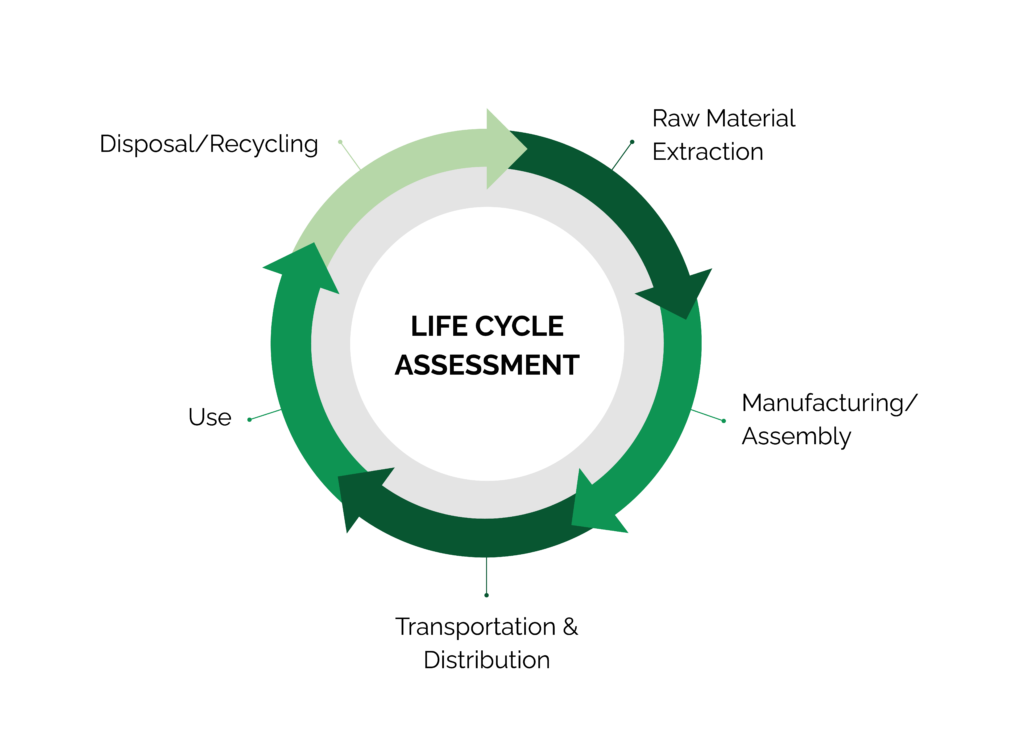
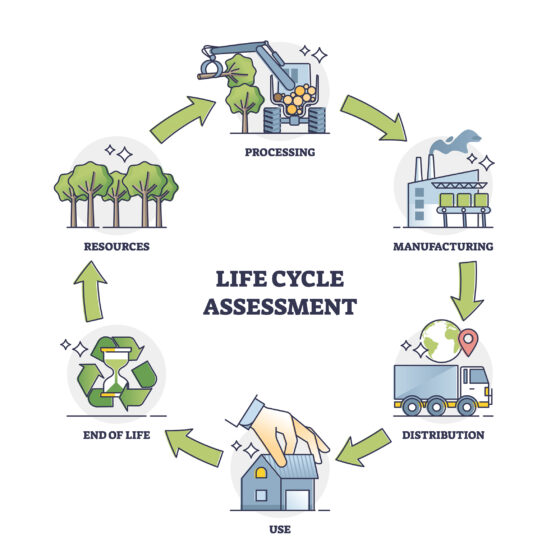
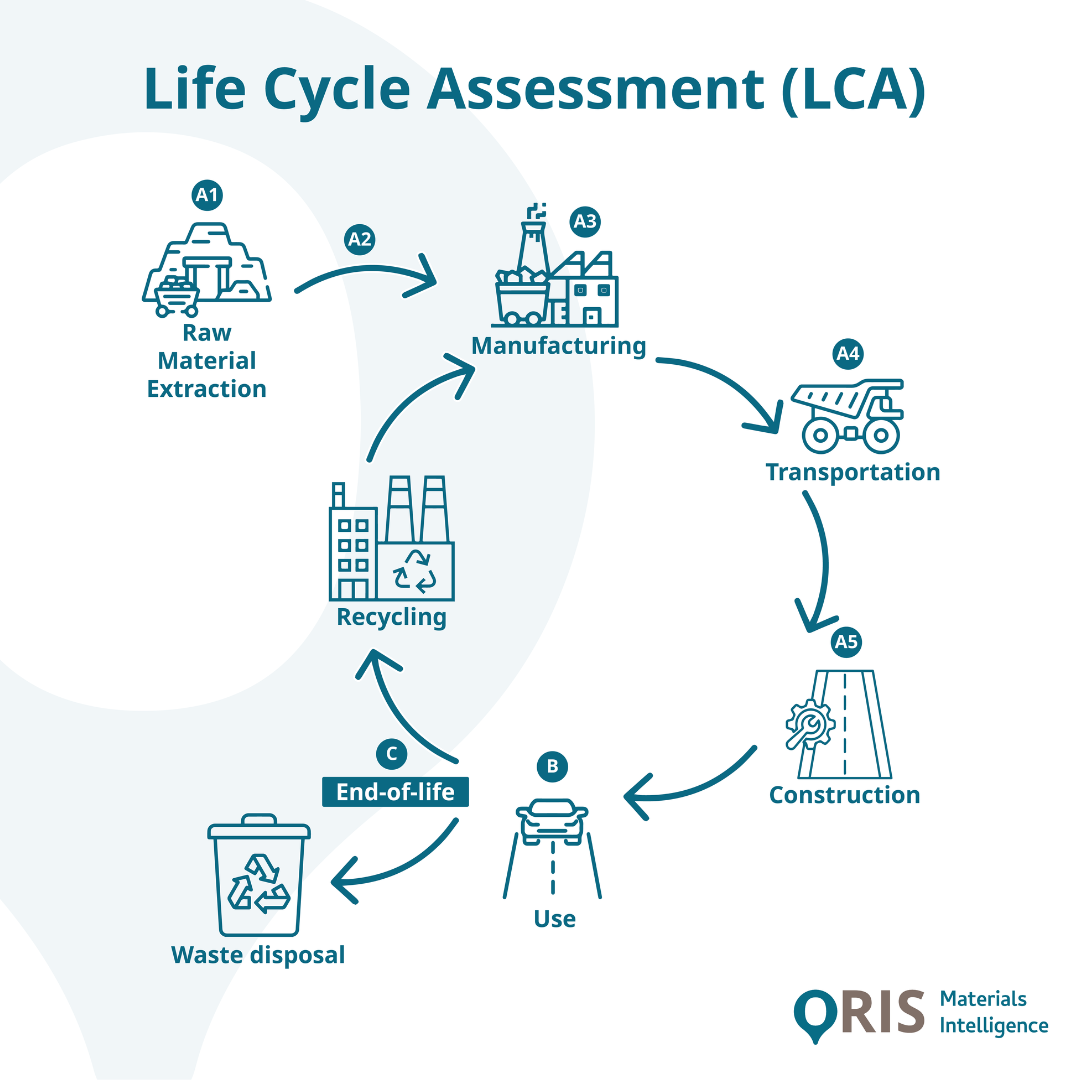
You pick a functional unit first. Everything else follows from that. If you are comparing a cotton tote bag to a polypropylene bag, the functional unit is not "one bag." It is "carrying 15 kg of groceries for 50 trips." Get this wrong and your entire comparison is noise. Let me walk through a couple of cases I have built from scratch. The first one is a common industrial example. I built a cradle-to-gate LCA for a 500ml PET water bottle a few years back. The system boundary included crude oil extraction, ethylene glycol production, PET resin manufacturing, bottle blowing, filling, and the end-of-life scenario. Here is what I actually ended up reporting as the main results, using the ReCiPe midpoint method:
The largest single contributor was the PET resin production stage, accounting for about 68 percent of the GWP. Recycling rate assumptions changed that number by roughly 30 percent when I tested different end-of-life scenarios. Another example that does not get discussed enough. I did a service-level LCA for a small cloud-hosted SaaS application. The functional unit was "one API call processed." The inventory covered data center electricity, hardware manufacturing amortized over device lifetime, and the user's device energy during access. The outcome was surprisingly different from what most people assume. Hardware manufacturing contributed about 42 percent of the total GWP. Data center operations contributed 38 percent. User device energy contributed 20 percent. The biggest variable was the data center's grid intensity. Running the same workload in a Nordic facility versus a coal-heavy grid region shifted the GWP by a factor of 2.4. That difference alone is enough to invalidate most comparative claims made in marketing materials.
How to Actually Build One From Scratch
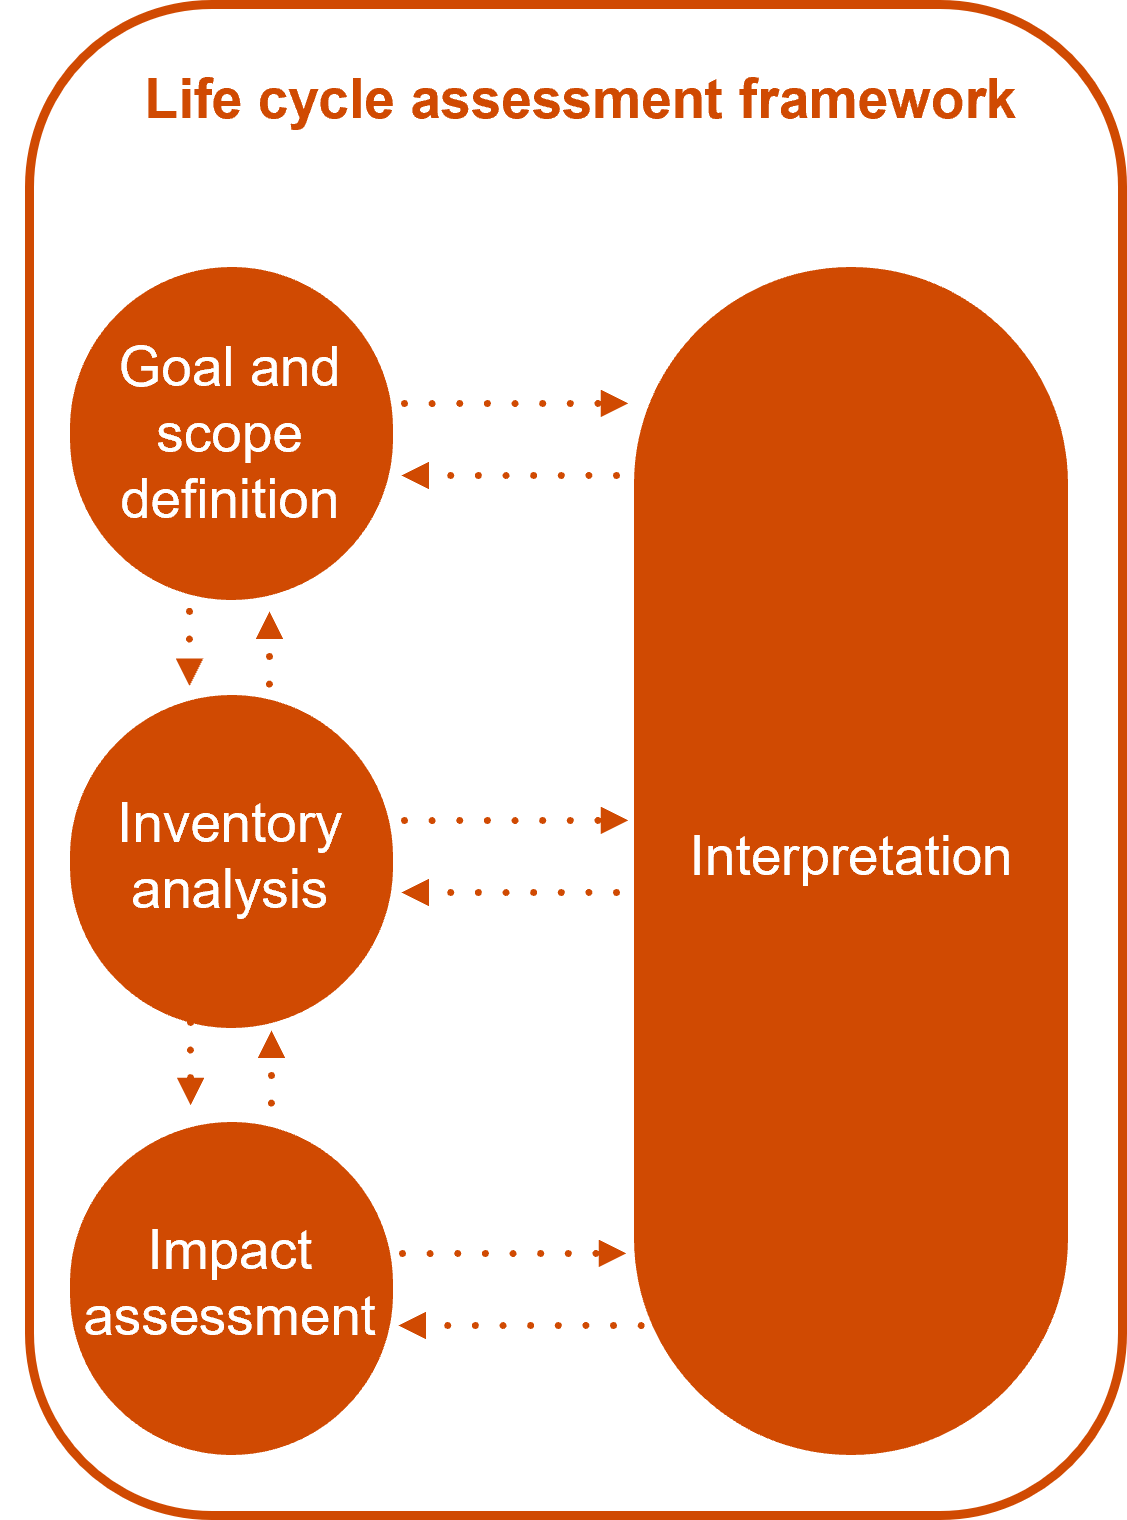
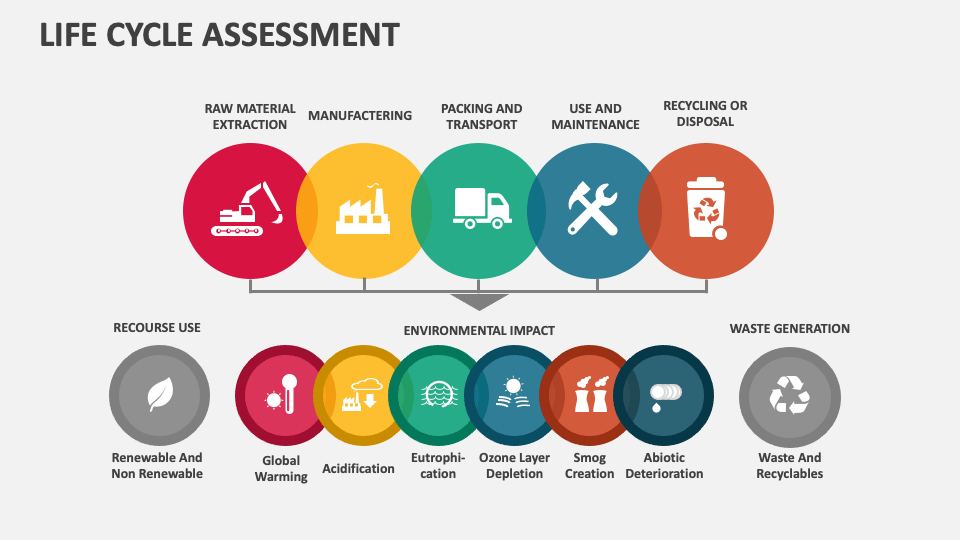
ISO 14040 and 14044 define the framework. They are not particularly helpful on the mechanics. The process has four phases. Phase one is goal and scope definition. You state the purpose, the intended audience, the system boundary, and the functional unit. This phase determines whether the study is credible or just an exercise in cherry-picking. Skip this and you will not recover later. I usually spend one to two weeks on this phase alone for anything beyond a simple screening study. Phase two is the inventory analysis. This is where most people get stuck. You collect input and output data for every process in your system boundary. Primary data is ideal but rarely available for everything. You will rely heavily on secondary databases. The three most common ones are Ecoinvent, GaBi, and USLCI. Ecoinvent version 3.8 contains over 20,000 datasets. It is the default choice for most peer-reviewed work and commercial assessments.
Get the Full Details
A realistic workflow for building the inventory looks like this. You map your process chain first. Then you pull primary data for any stage you control directly, like your own manufacturing operations. Everything else gets assigned from a database. You document every substitution, every truncation rule, and every assumption. If you skip documentation here, your study becomes impossible to reproduce and therefore useless. Phase three is the impact assessment. You take the inventory data and translate it into impact categories. Common methods include ReCiPe 2016, TRACI 2.1, CML, and Eco-indicator 99. ReCiPe is probably the most widely used in Europe. TRACI is the standard for US-based studies. Each method weights impacts differently, which means the same product can look completely different depending on the chosen method. Here is the counter-intuitive part most beginners miss. Normalization and weighting are optional in ISO 14040. But they are almost always needed for decision-making. Without normalization, you cannot compare whether your product's acidification potential matters more than its climate impact. Without weighting, you have a list of numbers with no relative importance attached. The problem is that weighting introduces value judgments. Different stakeholder groups will choose different weighting schemes. Acknowledge this limitation explicitly in your report or the whole exercise looks manipulative.
Phase four is interpretation. You check for completeness, sensitivity, and consistency. You identify which processes drive the results. You state the limitations and make recommendations. This phase is where you either defend the study or admit it cannot support the claim you originally wanted to make.
Software Tools I Actually Use
SimaPro remains the industry standard for commercial LCAs. It connects directly to Ecoinvent, supports dozens of impact assessment methods, and handles complex allocation scenarios. The learning curve is steep. A full project can take several weeks to set up properly if you are doing something non-standard. OpenLCA is the free alternative. It runs locally, supports Ecoinvent and many other databases, and has a plugin system for custom workflows. It is less polished than SimaPro but entirely sufficient for most academic and small-business assessments. A typical product LCA takes about 8 to 15 hours of actual work using OpenLCA, assuming the data is reasonably available and the scope is contained. GaBi is another commercial option. It is popular in automotive and heavy industry because its database coverage for those sectors is deeper than most alternatives. Licensing costs are significant. It is typically used when the client already has a corporate license.
If you need a quick downloadable template to start mapping your own LCA, I built a basic Excel workbook that structures the inventory phase. It includes columns for flow names, units, process names, allocation methods, and database references. You can find it on my research page at mydomain.org/lca-toolkit. It is a starting point, not a finished model.
A Specific Problem I Hit and How I Fixed It
I was building an LCA for a food processing facility that produced both juice concentrate and animal feed as co-products. The allocation question here is brutal. Standard mass-based allocation gave absurd results because the juice concentrate carried almost all the economic value while the feed was a low-value by-product. Energy-based allocation was equally questionable since the separation processes used very different energy inputs. The workaround I used was system expansion, also called substitution or avoided burden. Instead of allocating the environmental burden between the two products, I expanded the system boundary to include the production of the products that the co-products replace. The animal feed displaced conventional soybean meal in livestock diets. I calculated the impacts of producing that soybean meal and subtracted them from the original inventory. The result was more defensible and aligned with how practitioners actually handle co-product systems in peer-reviewed journals. It also required roughly three additional weeks of data collection because I had to build substitution inventories from scratch.
Pitfalls That Will Ruin Your Study
Inconsistent system boundaries. Comparing a cradle-to-grave study against a cradle-to-gate study is a classic error. Always match boundaries before comparing results. Two studies claiming to assess the same product can produce wildly different numbers if one includes use-phase emissions and the other does not. Database mismatch. Mixing datasets from different vintages of Ecoinvent or combining Ecoinvent with older releases of other databases introduces inconsistency. A single dataset update can shift GWP results by 5 to 15 percent depending on the process. Stick to one database version for the entire study. Allocation abuse. Economic allocation is the most common method and the most easily manipulated. Small changes in assumed market prices can flip which product appears to be the environmental burden bearer. Document your allocation factors explicitly and run sensitivity analysis on them. A single sensitivity run on allocation typically adds about two hours to the project timeline but prevents the most embarrassing reviewer comments.
.png)
Ignoring uncertainty. LCI data has inherent variability. Supply chain data is often five to ten years old. Treating a single-point estimate as factual is misleading. Use Monte Carlo simulation or at minimum a deterministic sensitivity analysis on your top five input flows. This adds roughly one day to the work but dramatically improves credibility.
When LCA Fails Completely
LCA is not appropriate for every situation. It breaks down when you need real-time environmental decision support. The data requirements and time investment make it useless for operational decisions that need answers within hours. It also struggles with social LCA components. There is no standardized method for assessing labor conditions in supply chains with the same rigor that exists for environmental impacts. For early-stage product design where rapid iteration is necessary, consider using a simplified environmental footprint calculator instead. Tools like the EPA's Tool for the Reduction and Assessment of Chemical and Other Environmental Impacts or sector-specific EPDs can give you directional guidance in minutes rather than weeks. Save the full LCA for final product validation and public claims. Another scenario where LCA is inadequate is when comparing technologies at vastly different maturity levels. A mature battery chemistry against an emerging alternative will always favor the mature technology in LCA simply because the emerging one lacks sufficient production data. The gap is not environmental performance. It is data availability. State this explicitly rather than presenting immature technology as environmentally inferior based on incomplete data.