What actually happens when vectors stop being independent
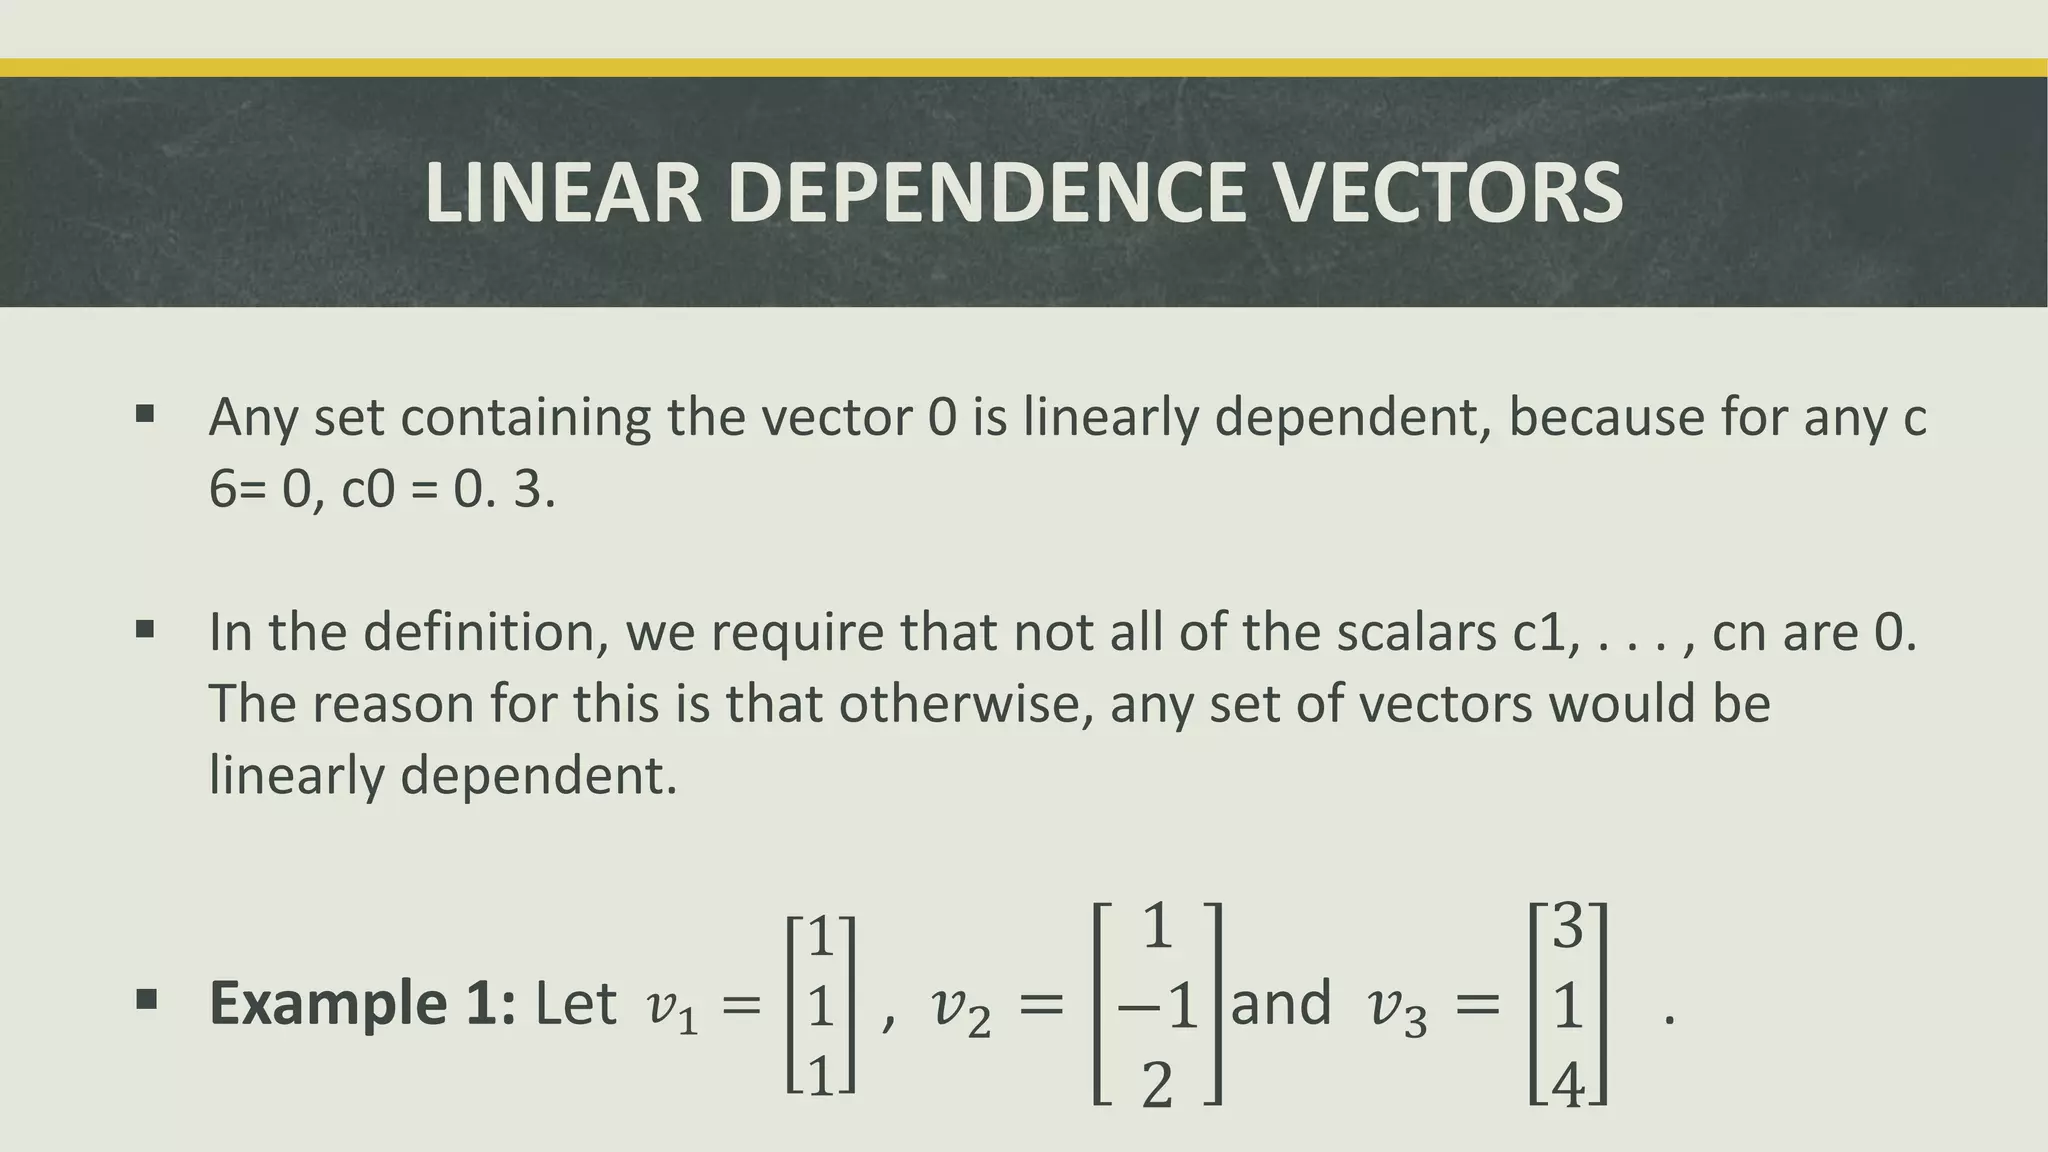
Linear Dependence And Independence is the foundation of almost every linear algebra problem you'll ever touch, but it's also where people get confused for years because textbooks explain it in a way that sounds precise until you try to apply it. You have a set of vectors. Each vector is just an ordered list of numbers. The question is whether any one of them can be built by adding together scaled versions of the others. If yes, the set is dependent. If no, it's independent. Here's the definition that actually matters in practice:
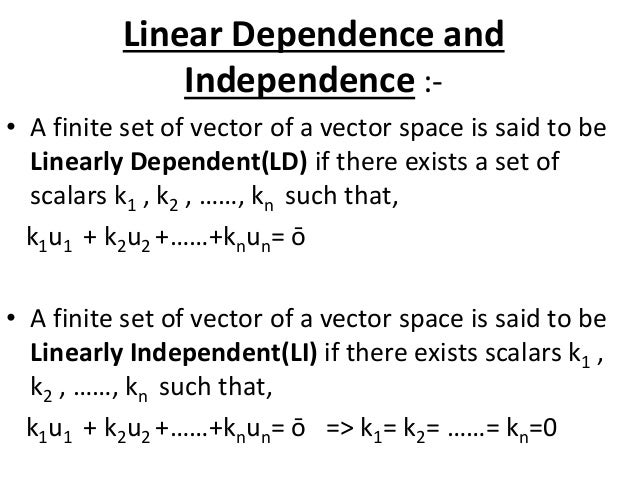
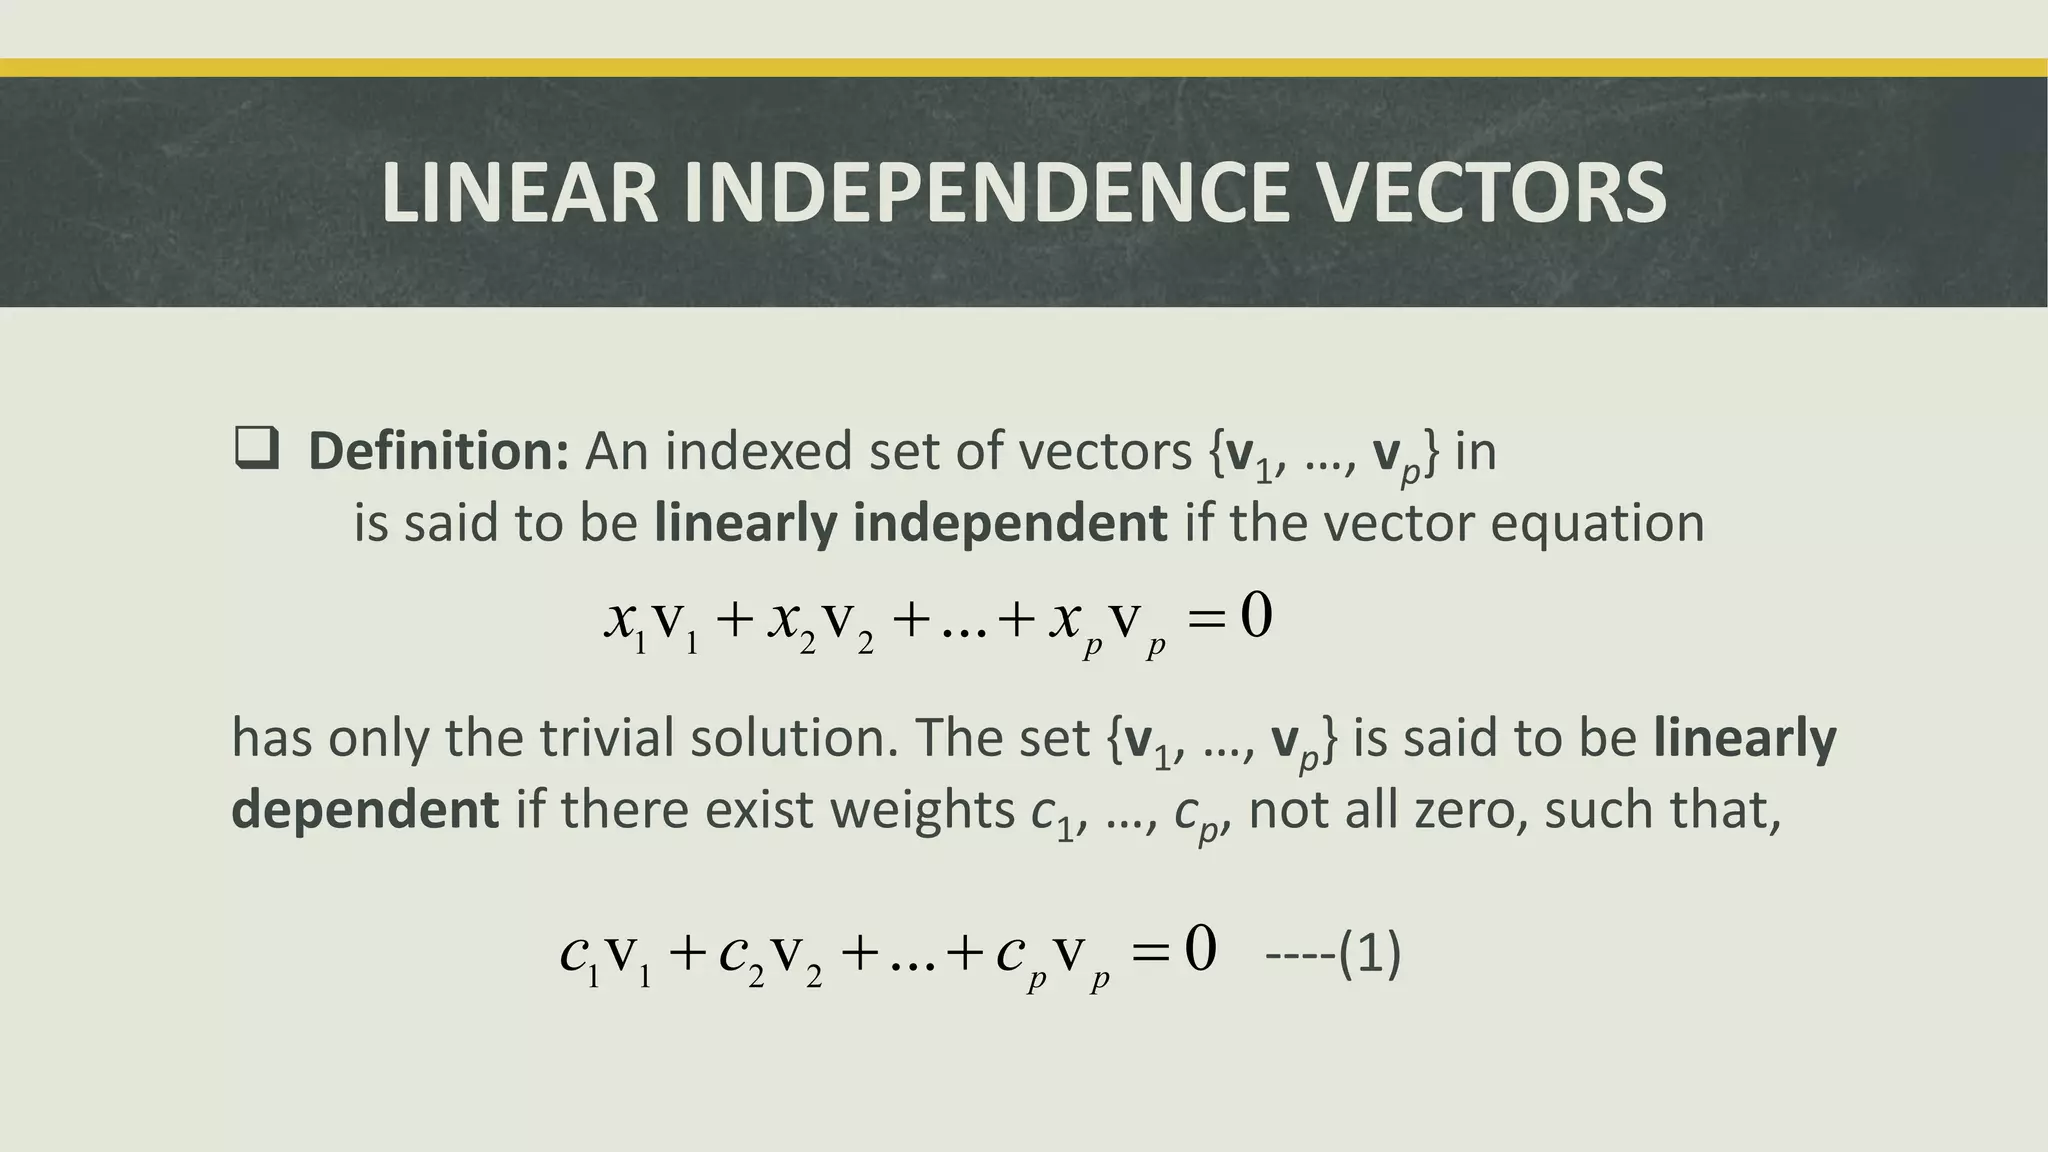
A set of vectors is linearly dependent if there exist scalars c, c, ..., c, not all zero, such that cv + cv + ... + cv = 0. That zero on the right side isn't arbitrary — it's the origin in whatever space you're working in. If the only way to make that equation true is by setting every scalar to zero, then the vectors are linearly independent. Try reading that twice. It sounds simple but the implications are heavy.
How I actually check this in code
When I'm working with real data — not the clean five-vector examples from a textbook — I don't compute determinants by hand. Determinant-based approaches blow up numerically past 10×10 matrices on most machines. Instead I form a matrix from the vectors as columns and run a rank check via QR decomposition with pivoting, or just look at the singular value decomposition if the matrix is already in a good numerical form. Here's a minimal Python snippet I've kept in my toolbox for years:
Get the Full Details
import numpy as np
from scipy.linalg import qr

def is_independent(vectors):
    A = np.column_stack(vectors)
    q, r, p = qr(A, mode='economic', pivoting=True)
    Count non-zero diagonal entries of R
    tol = max(A.shape) * np.finfo(float).eps * abs(r[0, 0])
    rank = np.sum(np.abs(np.diag(r)) > tol)
    return rank == A.shape[1]
The tolerance line is doing the real work here. You can't compare floating point numbers to zero without a threshold, and the standard machine epsilon multiplied by matrix dimension and the largest singular value is a reasonable default. I learned this the hard way. I was working on a computer vision pipeline that estimated camera intrinsics from correspondences across frames. I had a design matrix with six columns — the standard parameter grouping for a pinhole camera with skew and distortion coefficients. I thought the parameters were independent because no two of them looked obviously related when I plotted them. They weren't. What I missed was that three of the six columns were nearly collinear in practice due to the image geometry — not by construction, but because the test scenes I used had almost parallel features at similar depths. The matrix rank was numerically six but practically four. My estimates were returning plausible values with enormous variance that I didn't catch because I was only looking at the point estimates.
The workaround was straightforward once I knew what to look for: compute the condition number of the normal matrix AA and set a floor on acceptable conditioning. If (A) exceeded about 10, I dropped the observation from that batch and tried a different scene configuration. I also switched to a Levenberg-Marquardt solver with explicit damping on the ill-conditioned directions rather than trusting the raw normal equations. That constraint-cutting step alone stabilized the pipeline. The whole diagnostic added maybe ten lines to the codebase but saved me from shipping a model that would have appeared correct on paper.
Common mistakes beginners make
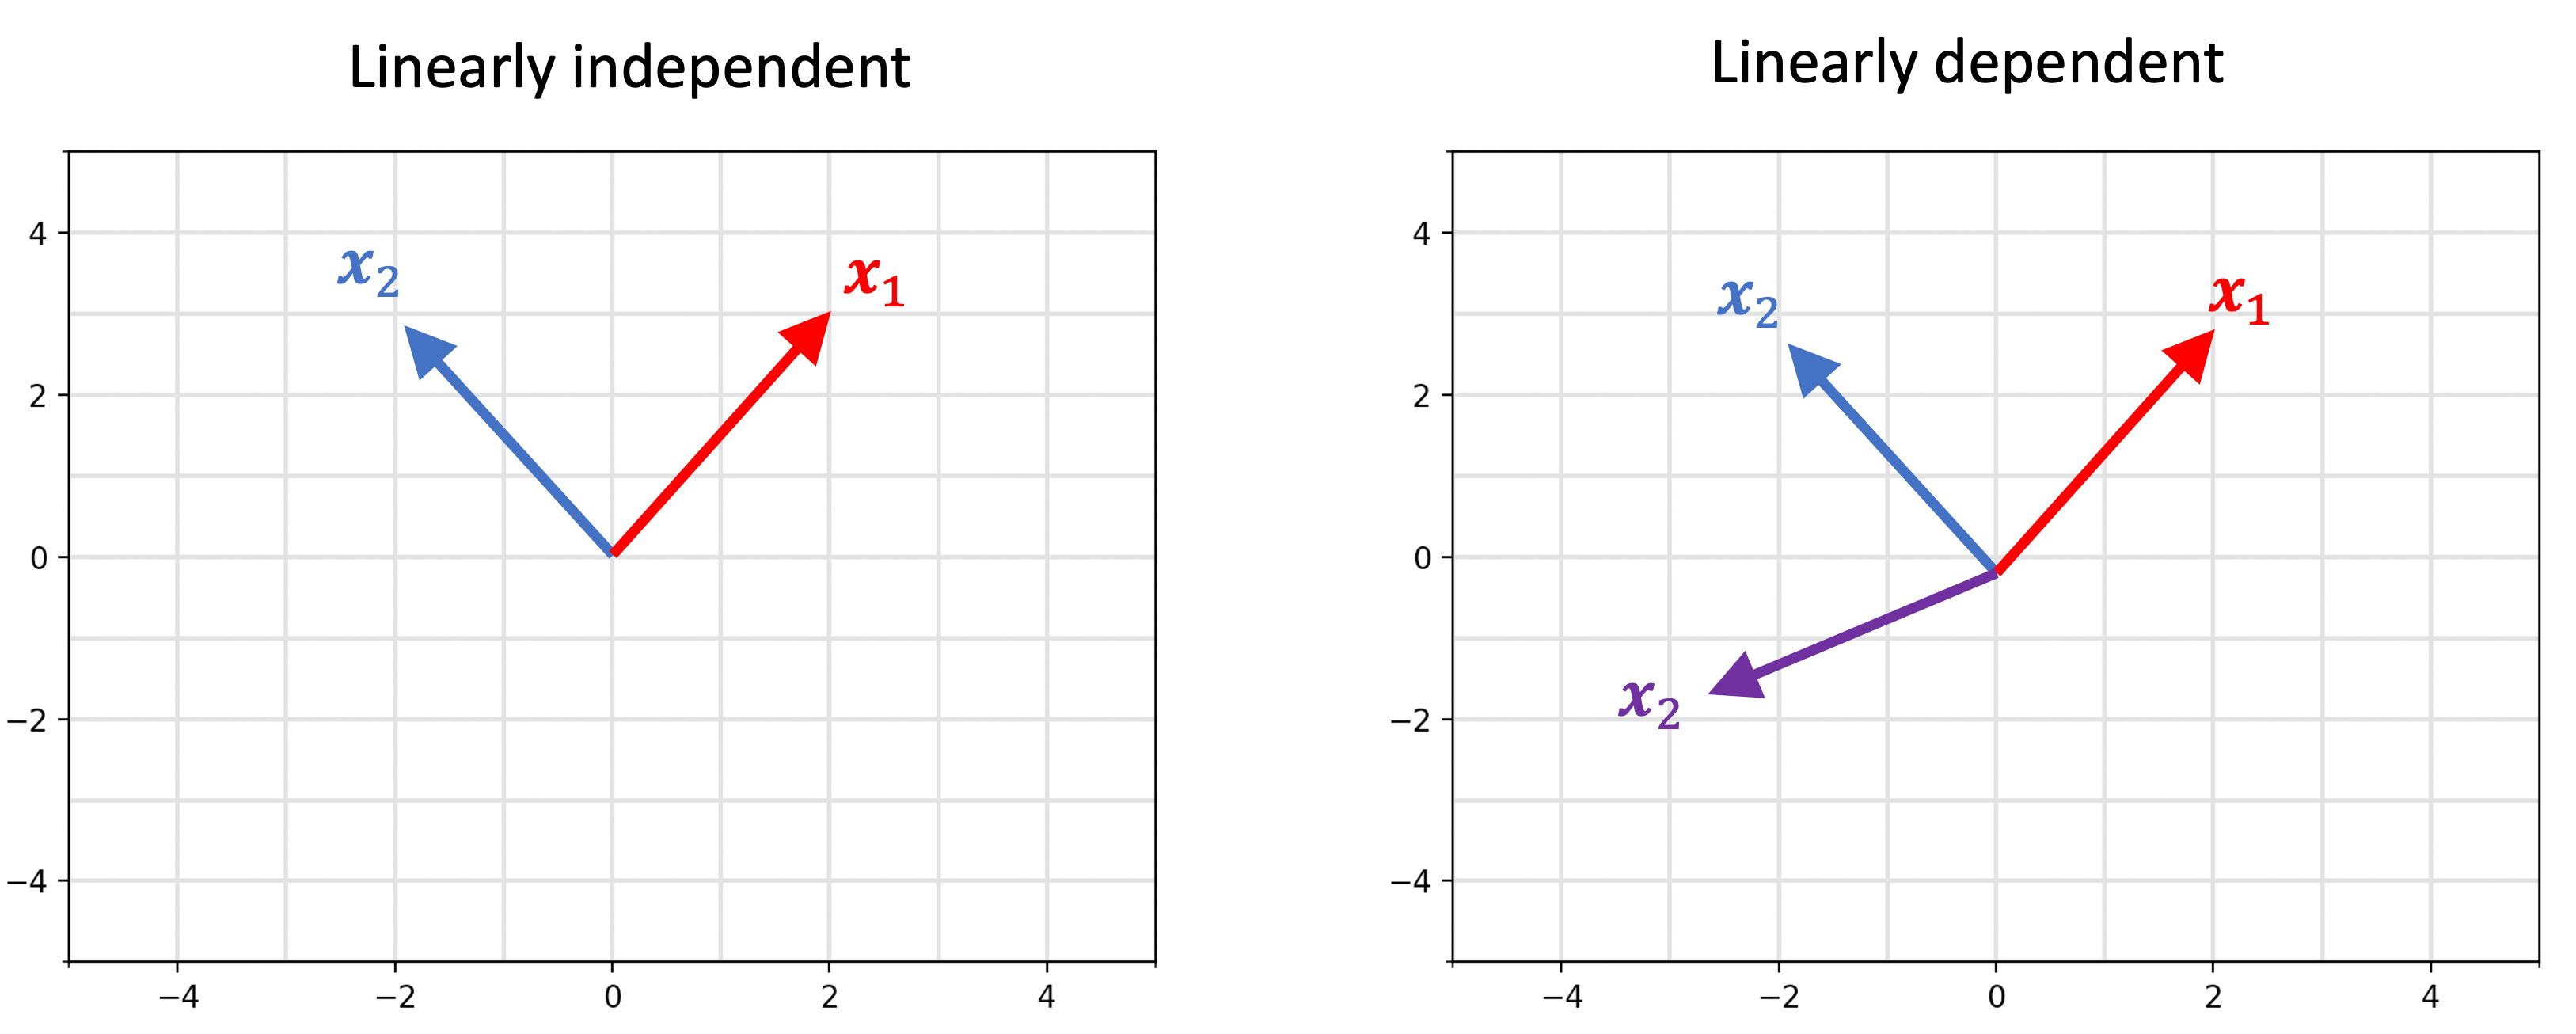
People often think linear independence means the vectors point in different directions. That's close but wrong. Two vectors can point in somewhat different directions and still be dependent — they just need to be scalar multiples of each other. Three or more vectors can have wildly different directions and still be dependent if one sits in the span of the others. Another mistake is conflating geometric independence with functional independence. In approximation theory, functions like sin(x), sin(2x), sin(3x) are linearly independent over the reals, but a naive numerical check on a finite sample can mislead you if your sample points happen to align with a false dependence. Here's a counter-intuitive fact: a set of fewer vectors than the ambient dimension can still be dependent. Two vectors in ℝ³ can be dependent if one is a scalar multiple of the other. The converse — that n vectors in ℝ are always independent — is also false. Put two identical columns in a 2×2 matrix and you get dependence immediately.
Why this matters beyond homework problems
In machine learning, linear dependence among features is what creates multicollinearity. It doesn't break gradient descent, but it makes the Hessian ill-conditioned and slows convergence dramatically. Regularization like ridge regression works by shifting the eigenvalues away from zero, which is essentially an implicit independence enforcement. In signal processing, the columns of a dictionary matrix need to be near-independent for sparse recovery algorithms like OMP or LASSO to work reliably. When atoms become too correlated, the algorithm picks the wrong one and the reconstruction collapses. The restricted isometry property formalizes this, but in practice I just check the mutual coherence — the maximum absolute inner product between normalized atoms. If it exceeds roughly 1/n for an n-atom dictionary, things are going to get ugly. In numerical linear algebra itself, basis vectors for subspaces should be orthonormal precisely because orthonormal sets are automatically linearly independent and well-conditioned. Gram-Schmidt produces such a basis, though I prefer Householder QR for production code because it's more numerically stable.
When linear independence is the wrong tool
Sometimes you don't actually need independence. In kernel methods, you work in a space that's implicitly high-dimensional where exact linear dependence is rare, but near-dependence is the real problem. There you care about the effective rank — how many singular values are above some noise floor — rather than a strict yes-or-no independence test. In control theory, the controllability matrix needs full row rank, not column independence in the naive sense. The distinction matters because you're checking whether the system can reach any state, which maps to a rank condition on a differently structured matrix. For time series, unit root tests check whether a process is stationary. That's a different kind of dependence — temporal dependence — and conflating it with linear dependence among regressors is a frequent source of spurious regression results. Two independent random walks regressed against each other will produce a significant coefficient with near-certainty. This is Engle and Granger's whole contribution and it's worth understanding because it's a genuine failure mode that looks like success.
A practical checklist
When you're given a set of vectors and need to determine their status, do this: First, verify the vectors live in the same space. Comparing a 3D vector with a 4D vector and asking about independence is a type error, not a math problem. Second, form the matrix and compute the rank. Use a tolerance. Don't use `np.allclose(r_diagonal, 0)` without a threshold — you will get wrong answers.
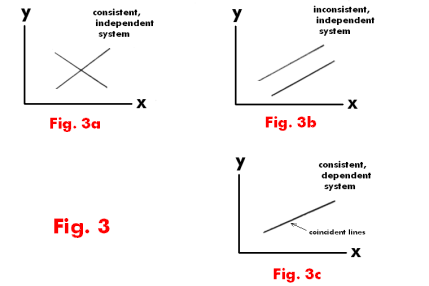
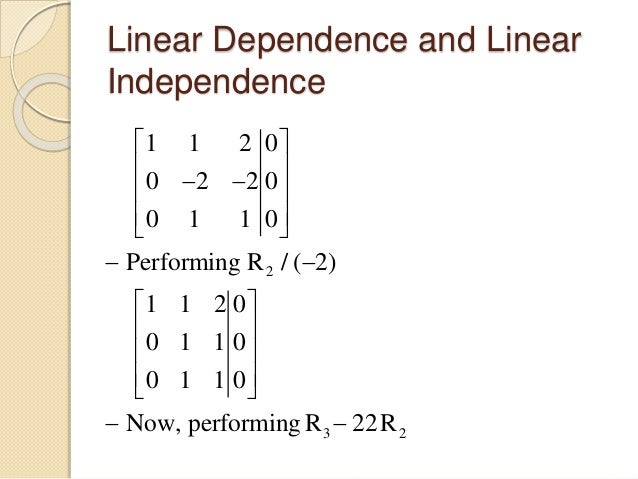
Third, if the rank equals the number of vectors, they're independent. If not, they're dependent, and the null space of the matrix gives you the exact coefficients that express the dependence relation. I keep a small function that returns those coefficients because knowing which vectors are causing the problem is more useful than just knowing the set is dependent.
def dependence_coefficients(vectors):
    A = np.column_stack(vectors)
    null_vecs, s, _ = np.linalg.svd(A)
    tol = max(A.shape) * s[0] * np.finfo(float).eps
    dependents = np.sum(s = tol)
    if dependents == 0:
        return None
    return null_vecs[:, -dependents:]

Fourth, check the condition number. A matrix can pass a rank test and still be so ill-conditioned that numerical operations on it are unreliable. If (A) > 10¹², treat the independence result with suspicion and consider regularization or a change of basis. Linear independence is really about information content. Each independent vector contributes something the others don't have. Dependent vectors are redundant — they're just old information dressed up differently. In a basis, every vector is independent by definition because you need exactly the right amount to span without waste. Overcomplete systems, like frames in signal processing, drop the independence requirement intentionally to gain robustness. Understanding this distinction — independence versus overcompleteness versus undercompleteness — changes how you approach problems. It's not just a definition to memorize. It's a lens for deciding whether to add more features, remove redundant ones, or reparameterize entirely.