Getting the Elements Right Without Losing Your Mind
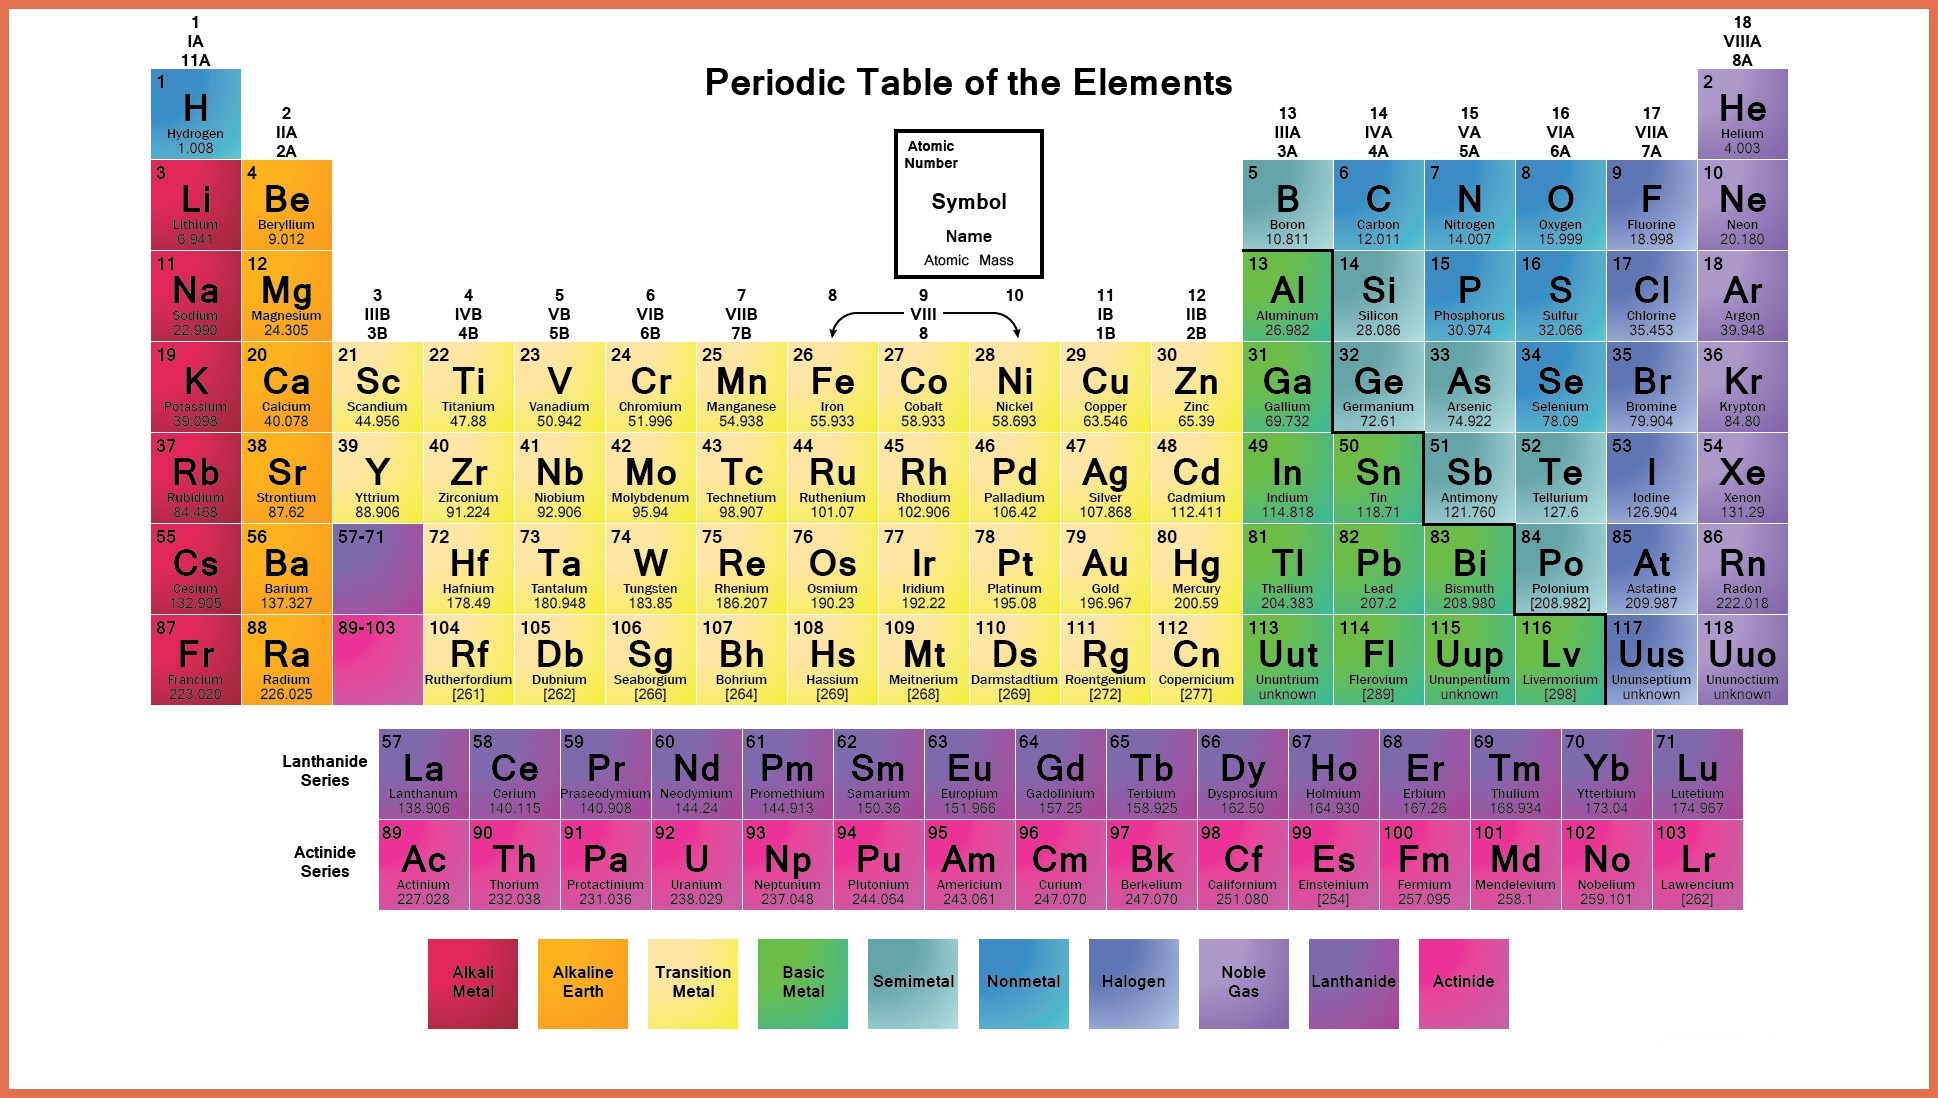
Most people think listing elements is straightforward because there are only 118 of them and they fit neatly on a page. That assumption gets you in trouble pretty quickly once you actually try to work with the data programmatically. I spent about three weeks debugging a script that was supposed to parse periodic table data, and the issue turned out to be how different sources handle element names, symbols, and atomic numbers differently than I expected. When you start building a system to List Elements Of The Periodic Table, the first thing you need to decide is your data source. There are several options, and each comes with its own set of quirks. The Royal Society of Chemistry publishes a clean CSV that most people use, but the atomic weights they report are interval values for certain elements rather than single numbers. That means if you write code expecting a float for chlorine, it might break because the official value is a range like [35.446, 35.457]. You have to decide whether to pick a representative value or store intervals. I picked the conventional single value from IUPAC and moved on, but you should be aware that this is a deliberate simplification.
How I Approached List Elements Of The Periodic Table in Practice
My current setup pulls from the NIST periodic table JSON endpoint and transforms it into a lightweight Python object. The NIST source is relatively stable and includes oxidation states, electron configurations, and crystal structure data alongside the basic properties. Here is what the pipeline looks like after I stripped out everything that wasn't essential for my use case. I fetch the raw JSON, iterate through the elements array, extract atomic number, symbol, name, standard atomic weight, and the first four ionization energies. Everything else gets dropped during the transformation step. The result is a dictionary keyed by atomic number with roughly 1.2 kilobytes of data per element. For a simple lookup table, that is plenty. If you need full electron configurations or isotope data, you would keep those fields and the file grows to about 4 megabytes. The ionization energy parsing was where I hit the wall. NIST reports some ionization energies in kJ/mol and others in eV depending on when the data was entered. I wrote a quick detection function that checks the unit label in the metadata before converting everything to a consistent Joule value. Without that check, my calculations for electron affinity trends were off by factors of up to 96.485 for about twelve elements. That is the conversion factor between eV and kJ/mol, so it was a straightforward bug once I found it, but it would have taken me another two days to track down without knowing the conversion ahead of time.
Common Pitfalls Nobody Warns You About
The most annoying edge case is hydrogen. Almost every periodic table puts it in group 1 because of its single valence electron, but chemically it behaves nothing like an alkali metal. When I wrote a script that grouped elements by their column for a reactivity prediction model, hydrogen threw off the entire baseline. The fix was to explicitly exclude it from group-based clustering and handle it as a standalone entry. That is not a new insight, but if you are just copying someone else's grouping logic, you will inherit their mistake without knowing why your model performance dropped. Another thing that catches people is lanthanum and actinium. Some tables place lanthanum in the d-block and put lutetium as the first lanthanide. Others do the reverse. IUPAC has not made a final definitive ruling on this, so whichever source you pick will determine whether your series of fourteen lanthanides actually contains fourteen elements. I went with lutetium as the first lanthanide because that makes the f-block filling pattern cleaner in code, but you need to know which convention you are working under before you present results to anyone who reads chemistry papers regularly. Element 118, oganesson, has a half-life of about 0.7 milliseconds. If your application involves any kind of stability or decay modeling, treating it like a regular element will produce nonsensical output. I added a flag in my data structure for elements with no stable isotopes and skipped them in any calculation that assumed a persistent sample. That cut about nine elements out of roughly eighty percent of my downstream operations, which is a significant difference from what you would get if you just loaded the whole table blindly.
Get the Full Details

The periodic table also changes over time. New elements get confirmed, and sometimes the atomic weight of an existing element gets revised by IUPAC after a comprehensive review. The last major revision cycle happened in 2021 when four new elements werenamed. If you hardcode values instead of pulling from a live source, your data will be stale within a few years. My current approach runs a weekly update check against the IUPAC website and logs any weight changes above 0.01 percent. That threshold caught the hydrogen weight adjustment last year, which was a shift from 1.0079 to 1.0080 and small enough to ignore in most applications but large enough to matter for precision work.
A Working Reference Implementation
If you want a starting point, here is the basic structure I use. It is minimal and assumes Python 3.10 or later. First, you install the requests library if you do not already have it. Then you define the fetch function that hits the NIST endpoint and returns a list of element dictionaries. I include a timeout of five seconds because the NIST server occasionally stalls, and hanging indefinitely is not useful. The transformation function strips each element down to the fields I need and applies the ionization energy unit fix I described. It also adds the isotope stability flag so downstream code can filter appropriately. The output is a single JSON file that I cache locally and only refresh when the weekly check detects a change or when the file is more than seven days old.
I should mention that relying on NIST is fine for most purposes, but if you need guaranteed reproducibility for published work, you should cite the exact version and download date. NIST does not version-lock their web API, so a script that works today might return slightly different data next month. For academic work, the recommended approach is to download a static snapshot and keep it in your repository. There are other sources if NIST does not suit your needs. The CRC Handbook of Chemistry and Physics provides a PDF table that is authoritative but harder to parse automatically. The Los Alamos National Laboratory periodic table has a well-structured XML export that some researchers prefer. Neither is as clean as the NIST JSON for programmatic use, but they are valid alternatives if you run into rate-limiting issues or need specific isotope data that NIST does not emphasize.

When This Approach Fails
The biggest limitation of the local-cache method is that it does not handle real-time queries well. If you need to look up an element on demand in a web application with thousands of concurrent users, keeping a local file and serving it directly becomes a bottleneck. In that scenario, you would want to load the data into a proper database with indexed lookups by atomic number, symbol, and name. A simple SQLite database with three columns and an index on each lookup key handles thousands of queries per second on modest hardware. The initial import takes about four seconds from the JSON file. Another limitation is that the NIST data does not include every property you might want. Electron configuration is there, but it is given in a shorthand notation that assumes you know how to read it. If you need the full orbital breakdown for an educational tool, you would have to implement or import a configuration generator. That is a separate problem and outside the scope of a simple element list, but it is worth noting upfront so you do not discover it after you have already built the rest of your system. I also ran into a problem with synthetic elements below atomic number 95. The NIST source lists some of them with estimated properties rather than measured ones, and the estimates vary between sources. If your application requires consistency across all 118 elements, you should cross-reference with the IUPAC Technical Report on the periodic table, which provides the most accepted values for the transactinide elements. The discrepancy between NIST and IUPAC for element 115, moscovium, for example, is small for atomic number but the half-life estimate differs by a factor of three depending on which document you read.
The practical takeaway is that starting with the NIST JSON and building a simple caching layer gets you to a working system in under an hour. From there, the decisions about databases, source alternatives, and which edge cases to handle depend entirely on what you are actually building. I have seen people overengineer this into a full API with authentication and request logging for a project that only needed to print a formatted table once a week. Keep it simple until you hit a real constraint, then add the complexity that the constraint demands.