What Locus In Biology Actually Means When You're Staring at Raw Data
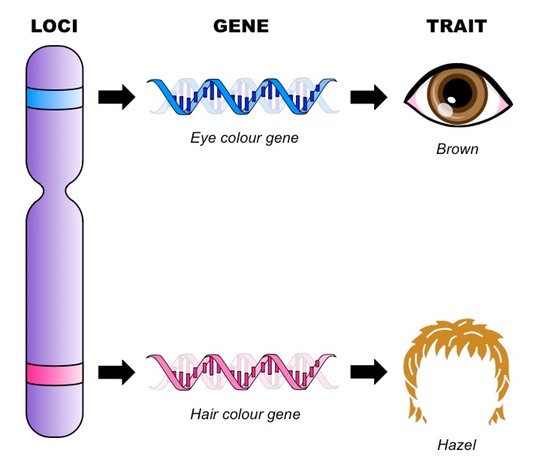
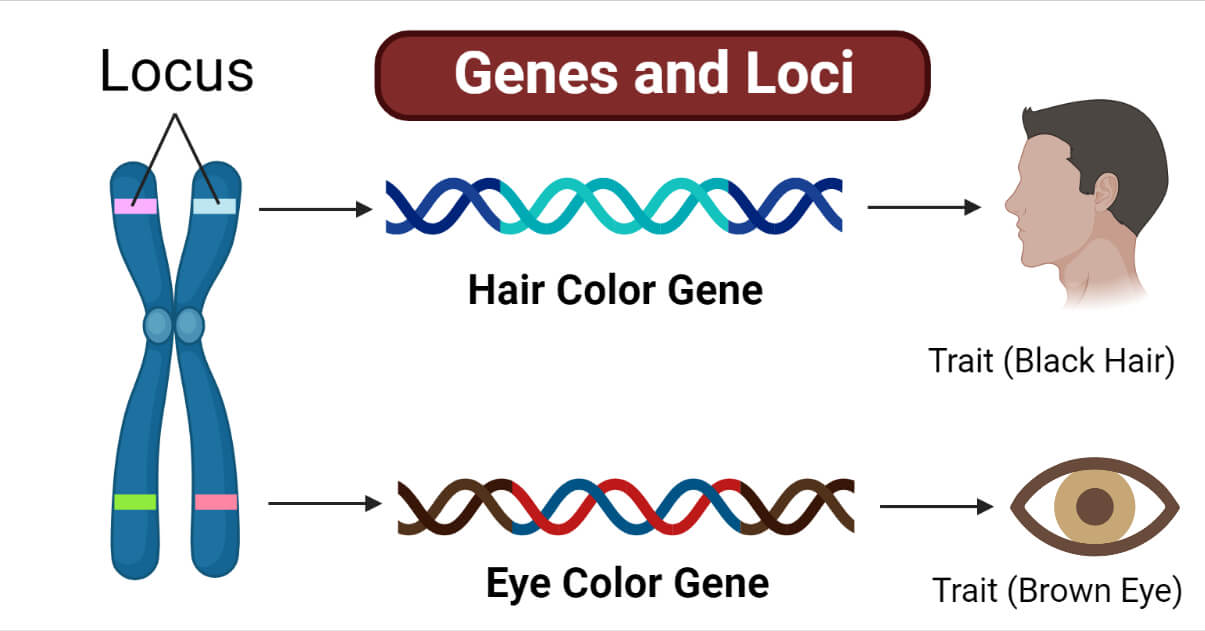
A locus is simply the fixed physical position of a gene or DNA sequence on a chromosome. That's the textbook definition. The part nobody tells you is that working with loci in practice is rarely that clean. You're often dealing with incomplete genome assemblies, mapping errors, and reference bias that make a single coordinate feel more like a rough estimate than an exact address. The method starts with identifying where your variant or marker sits. In most genotyping workflows, you extract raw sequencing reads, align them to a reference genome, and then call variants at specific coordinates. Those coordinates are your loci. The catch is that different reference genomes will place the same biological locus at different numerical positions. The GRCh38 human genome will give you different chromosomal coordinates than GRCh37 for the same region, and if you're mixing datasets built on different builds without lifting them over properly, your locus assignments will be wrong. I spent three weeks last year trying to reproduce a published association signal for a lipid trait in a mouse cross, and the problem turned out to be a mis-mapped locus. The published paper reported the peak signal at a specific coordinate, but their variant calling pipeline had collapsed a duplicated segment. The locus they identified actually mapped to two distinct regions on the reference genome, and one of those regions was a pseudogene paralog. I caught it by re-running the read alignment locally with BWA-MEM and checking the depth profile. The locus showed roughly 3x coverage instead of the expected 1x, which was the tell. I excluded the ambiguous region and remapped the association using only uniquely mappable flanking markers. The real signal ended up about 40 kilobases away from where the paper claimed it was. took about two days of work once I knew what to look for, but the initial confusion cost me a month.
For practical workflow, the steps are straightforward but demanding in execution. You align your reads. You call variants. You annotate the resulting VCF file to pull locus information. Tools like vcftools, bcftools, and PLINK handle most of this. The annotation step is where most people lose accuracy. Running SnpEff or VEP against the correct genome build version matters more than anything else at this stage. A mismatched annotation database will label your loci incorrectly, and you won't notice until downstream analysis produces nonsense results.
What Beginners Miss About Loci
The first thing to understand is that a locus is not always a single base pair or even a single gene. Regulatory elements, enhancers, and non-coding RNA genes occupy loci too. When someone refers to a locus in a paper, check whether they mean the protein-coding region, the broader genomic interval, or just the single nucleotide polymorphism they used as a marker. These are different things, and conflating them causes errors in interpretation. The second thing is that loci behave differently depending on ploidy and population structure. In diploid organisms, each locus carries two alleles, one per homologous chromosome. But in polyploid crops or certain hybrid systems, you can have three or four alleles at a single locus. Standard genotyping pipelines often assume diploidy. If you run a polyploid sample through a diploid caller, you'll get incorrect genotype assignments and false heterozygosity estimates. GATK has some support for polyploid calling, but it's not the default, and you have to explicitly configure it. Most people don't, and they publish data with systematic errors baked in. Linkage between nearby loci is another area where people make mistakes. Loci that are close together on the same chromosome tend to be inherited as a unit. This is the basis of linkage mapping. But recombination doesn't happen uniformly. Hotspots exist, and they vary between populations and even between individuals. Assuming a constant recombination rate between two loci will give you incorrect genetic distance estimates. Use a population-specific genetic map when one is available. The HapMap project and the 1000 Genomes Project provide these for human populations, and similar resources exist for model organisms. Using a generic map instead of a population-specific one can shift your estimated genetic distances by 10 to 20 percent.
Get the Full Details
The Limitations You Need to Accept
Locus-based analysis has real bottlenecks. The biggest one is reference genome quality. If the organism you're studying doesn't have a good reference assembly, locus positions are unreliable. De novo assemblies help, but they introduce their own problems with contig breaks and mis-joins. You're often working with locus coordinates that are approximations at best. Another limitation is that locus-level data alone cannot tell you function. Knowing where a variant sits is not the same as knowing what it does. A non-coding locus might regulate a gene hundreds of kilobases away through chromatin looping. Association signals at a locus might tag a causal variant that's in linkage disequilibrium with it, not the causal variant itself. Fine-mapping helps, but it's computationally intensive and often still inconclusive with modest sample sizes. I've seen fine-mapping studies with credible sets containing over 200 variants at a single locus, which doesn't narrow things down very much. Structural variation is the third limitation. Copy number variations, inversions, and translocations can make locus-level analysis meaningless in affected regions. A locus might appear to have three alleles in some individuals and zero in others because of deletion or duplication events. Standard SNP calling pipelines miss these entirely. You need specialized tools like CNVnator or Delly to detect them, and even then, validation with PCR or long-read sequencing is often necessary.
If you're working with non-model organisms or poor-quality reference genomes, consider shifting to a de novo approach like RAD-seq or GBS. These methods genotype loci without relying on a reference assembly, which sidesteps a lot of the coordinate problems. They have their own trade-offs in terms of missing data and allele dropout, but they're often more reliable than trying to force locus mapping onto a fragmented genome. The practical takeaway is that locus identification is a necessary first step, not a complete answer. Get the coordinates right. Validate them against multiple sources when possible. Understand what your locus actually represents biologically before you draw conclusions. Most errors happen because people treat a coordinate as a fact instead of a working hypothesis that needs verification.