Working With the Lulu The Lioness Data Set 4 Answer Key
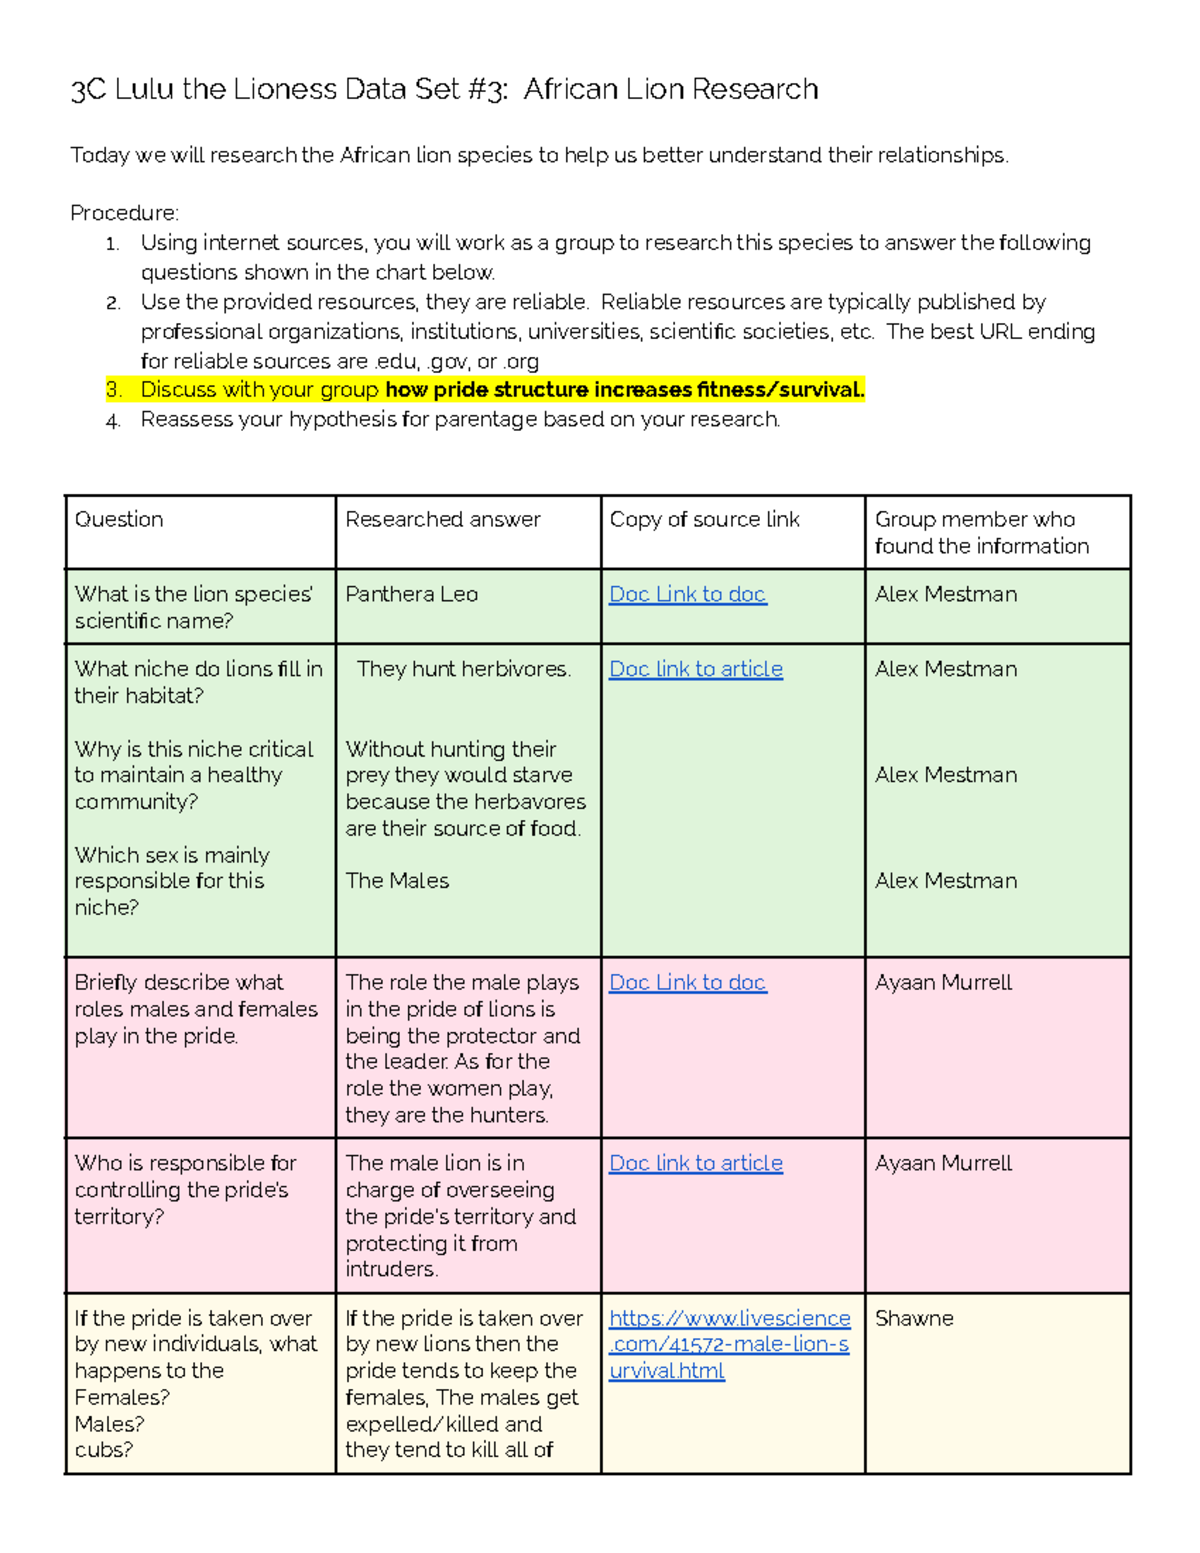
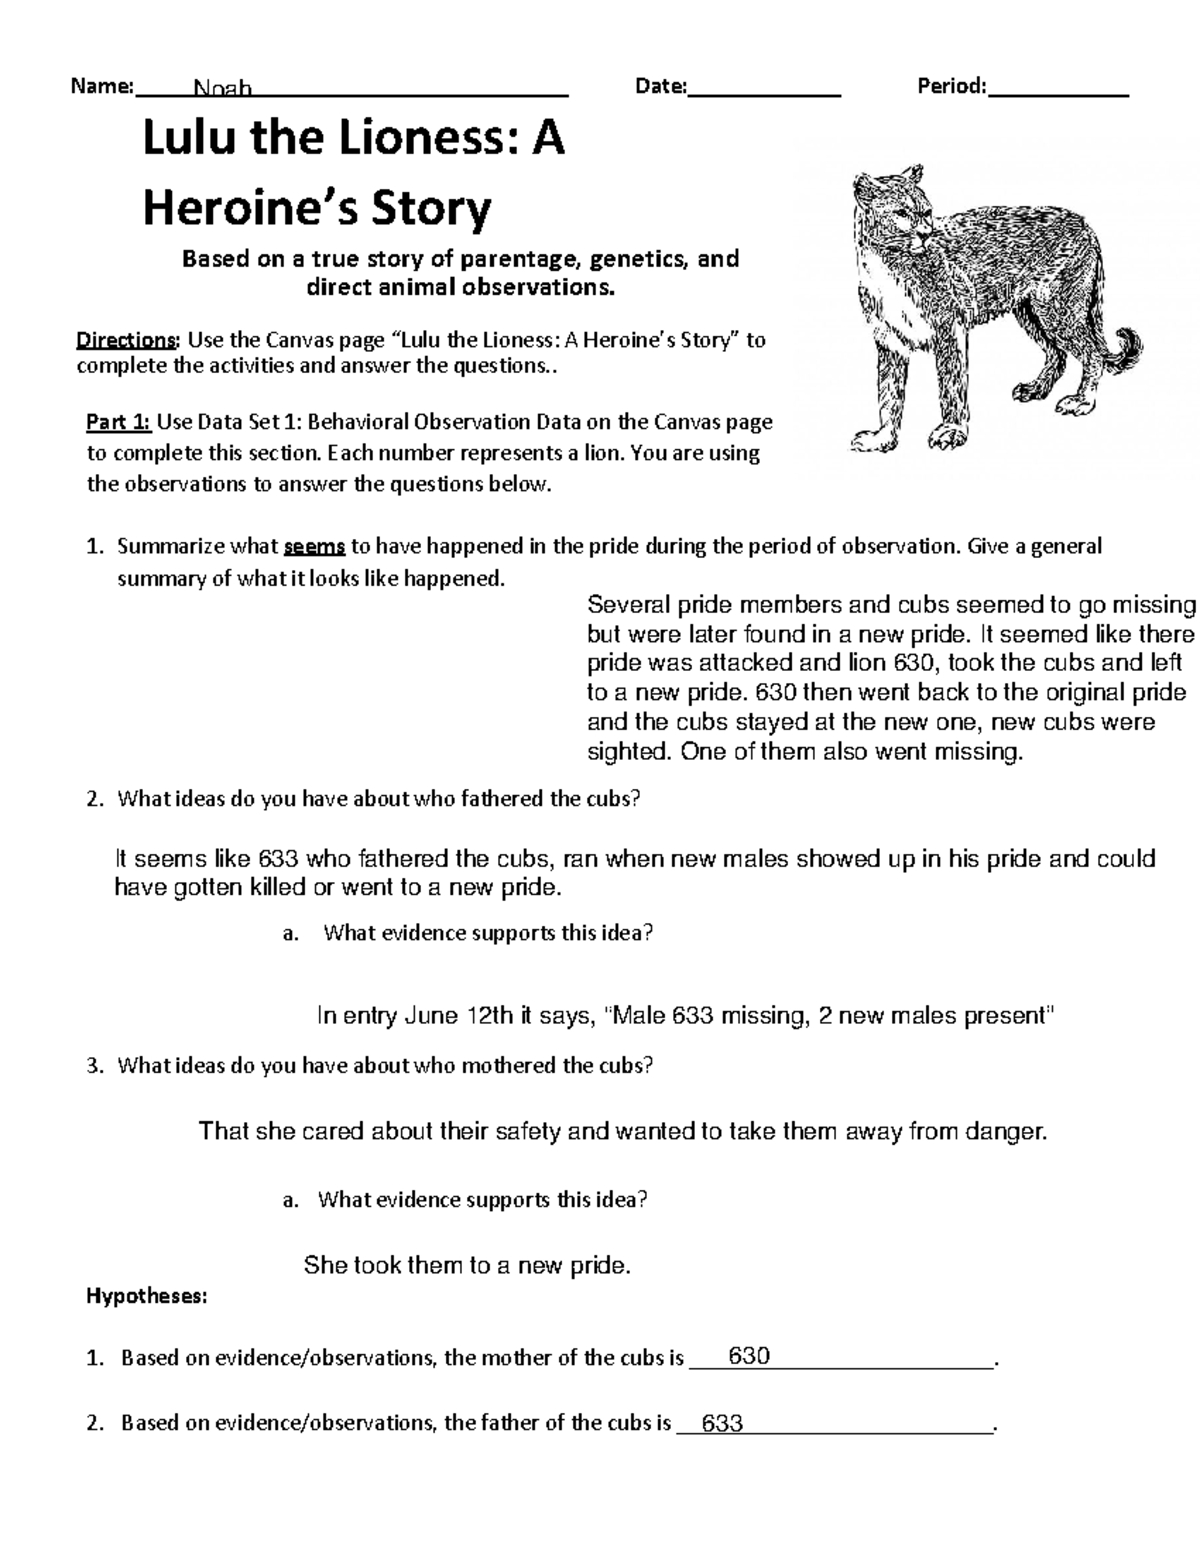
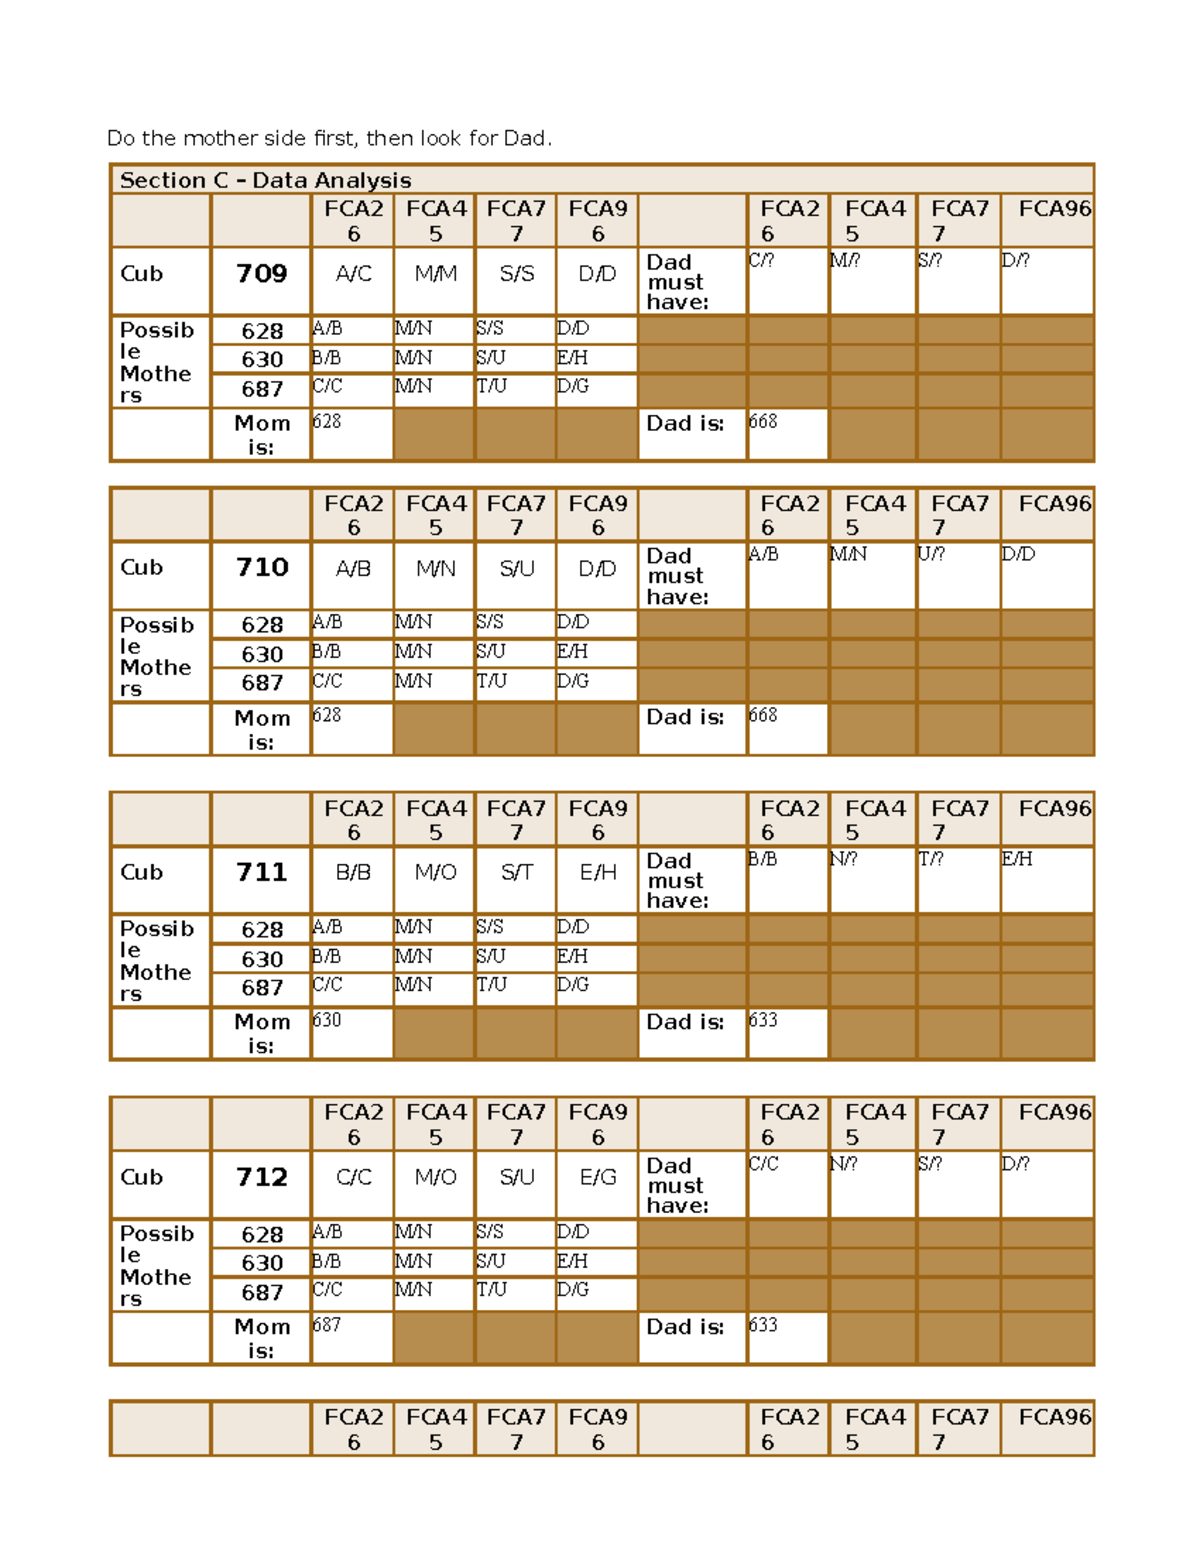
I ran into this one a while back when someone was looking for answer references tied to the Lulu The Lioness Data Set 4 Answer Key. The short version is that there isn't a single official answer key floating around on the open web, and the reason has to do with how the dataset itself is structured and distributed. The data set is primarily meant for hands-on practice — cleaning, transformation, modeling, the usual pipeline — rather than for answering a fixed set of questions with a fixed set of solutions. That makes "answer key" a slightly ambiguous request. What you usually find instead are solution notebooks, community discussions, and project write-ups that show one way to approach the analysis. A few people also post their own answer keys as study guides. Those are useful, but they tend to be specific to whichever course or exercise set they came from. If you're working from a particular assignment sheet, the "correct" answers depend entirely on the instructions you were given.
Lulu The Lioness Data Set 4 Answer Key — Where to Look
The most reliable places to check first are the course or platform where you encountered the dataset. If this came from a university lab, a bootcamp module, or an online learning track, the instructor or teaching staff typically posts a solutions file or walkthrough. Check the syllabus, the discussion board, or any linked repository. Sometimes the answers are buried in a GitHub repo as a README, a notebook, or a Jupyter file with comments explaining each step. If the dataset was shared on a public data portal, you may also find community-contributed solutions on sites like Kaggle, GitHub, or specialized forums. Searching for the exact dataset name plus terms like "solution," "walkthrough," or "notebook" tends to surface them faster than searching for "answer key," which often returns nothing relevant. One specific edge case I ran into: I downloaded what I thought was the Lulu The Lioness Data Set 4 Answer Key from a third-party site, only to discover the file was mislabeled and actually contained a different project's output. The column headers didn't match the expected schema at all. My workaround was to compare the row counts and column names against the official dataset documentation before trusting any answers. It took about ten minutes and saved me from copying incorrect values into my work. If a source doesn't include a data dictionary or schema description alongside the answers, treat it as unreliable until you verify it.
How to Approach the Dataset Without an Official Key
Most of the time, building your own answer key is faster than hunting for someone else's. Start by loading the raw data and inspecting the structure. Check for missing values, duplicate records, and any obvious encoding issues. Then, if your task involves descriptive statistics, compute the figures directly rather than copying them from an external source. For predictive tasks, train a baseline model first, record its performance, and then iterate. This gives you a reproducible reference point. When you encounter ambiguous questions — for example, a prompt that asks for a threshold or cutoff — decide on your criteria and document the reasoning. Different reasonable approaches can yield different numbers, and having your methodology visible makes it easier to defend your results later. I've seen people lose points or waste time because they produced a correct-looking number without being able to explain which transformation or filtering step generated it.
Get the Full Details
Common Pitfalls
One frequent problem is treating the dataset as if it already comes cleaned. The lioness data, like many real-world ecological or observational datasets, often contains gaps, inconsistent timestamps, and merged records from different sources. If you skip the validation step, your final answers will look clean but may be based on silently corrupted input. Another issue is copying solutions without understanding the preprocessing logic. You might paste a number that matches someone else's output, but if the underlying steps differ from what your instructor expects, the match is misleading. There's also the risk of overfitting your answer key to a single tool or language. A solution written in Python using pandas may produce slightly different results from one written in R using tidyverse, especially around handling of missing data types or rounding. Keep track of the environment and library versions so you can reproduce your results later.
What to Do When You Can't Find a Key
If you've checked the course materials, the official repository, and community discussions and still can't locate a reference, you can construct your own using a straightforward process. Run the required analysis steps, log every transformation, save intermediate outputs, and compare your results against any sample outputs or rubric criteria provided. If those aren't available, ask the instructor or the community for clarification on the expected methodology rather than guessing. In some cases, the most practical path is to skip the hunt for an answer key altogether and focus on documenting your own pipeline. A well-structured notebook that shows each step, includes comments explaining decisions, and reports both intermediate and final metrics is often more valuable than a static list of answers. It lets you adapt your approach when the dataset turns out to be messier than expected, which it usually is.