How to Build Cheat Sheets People Actually Use
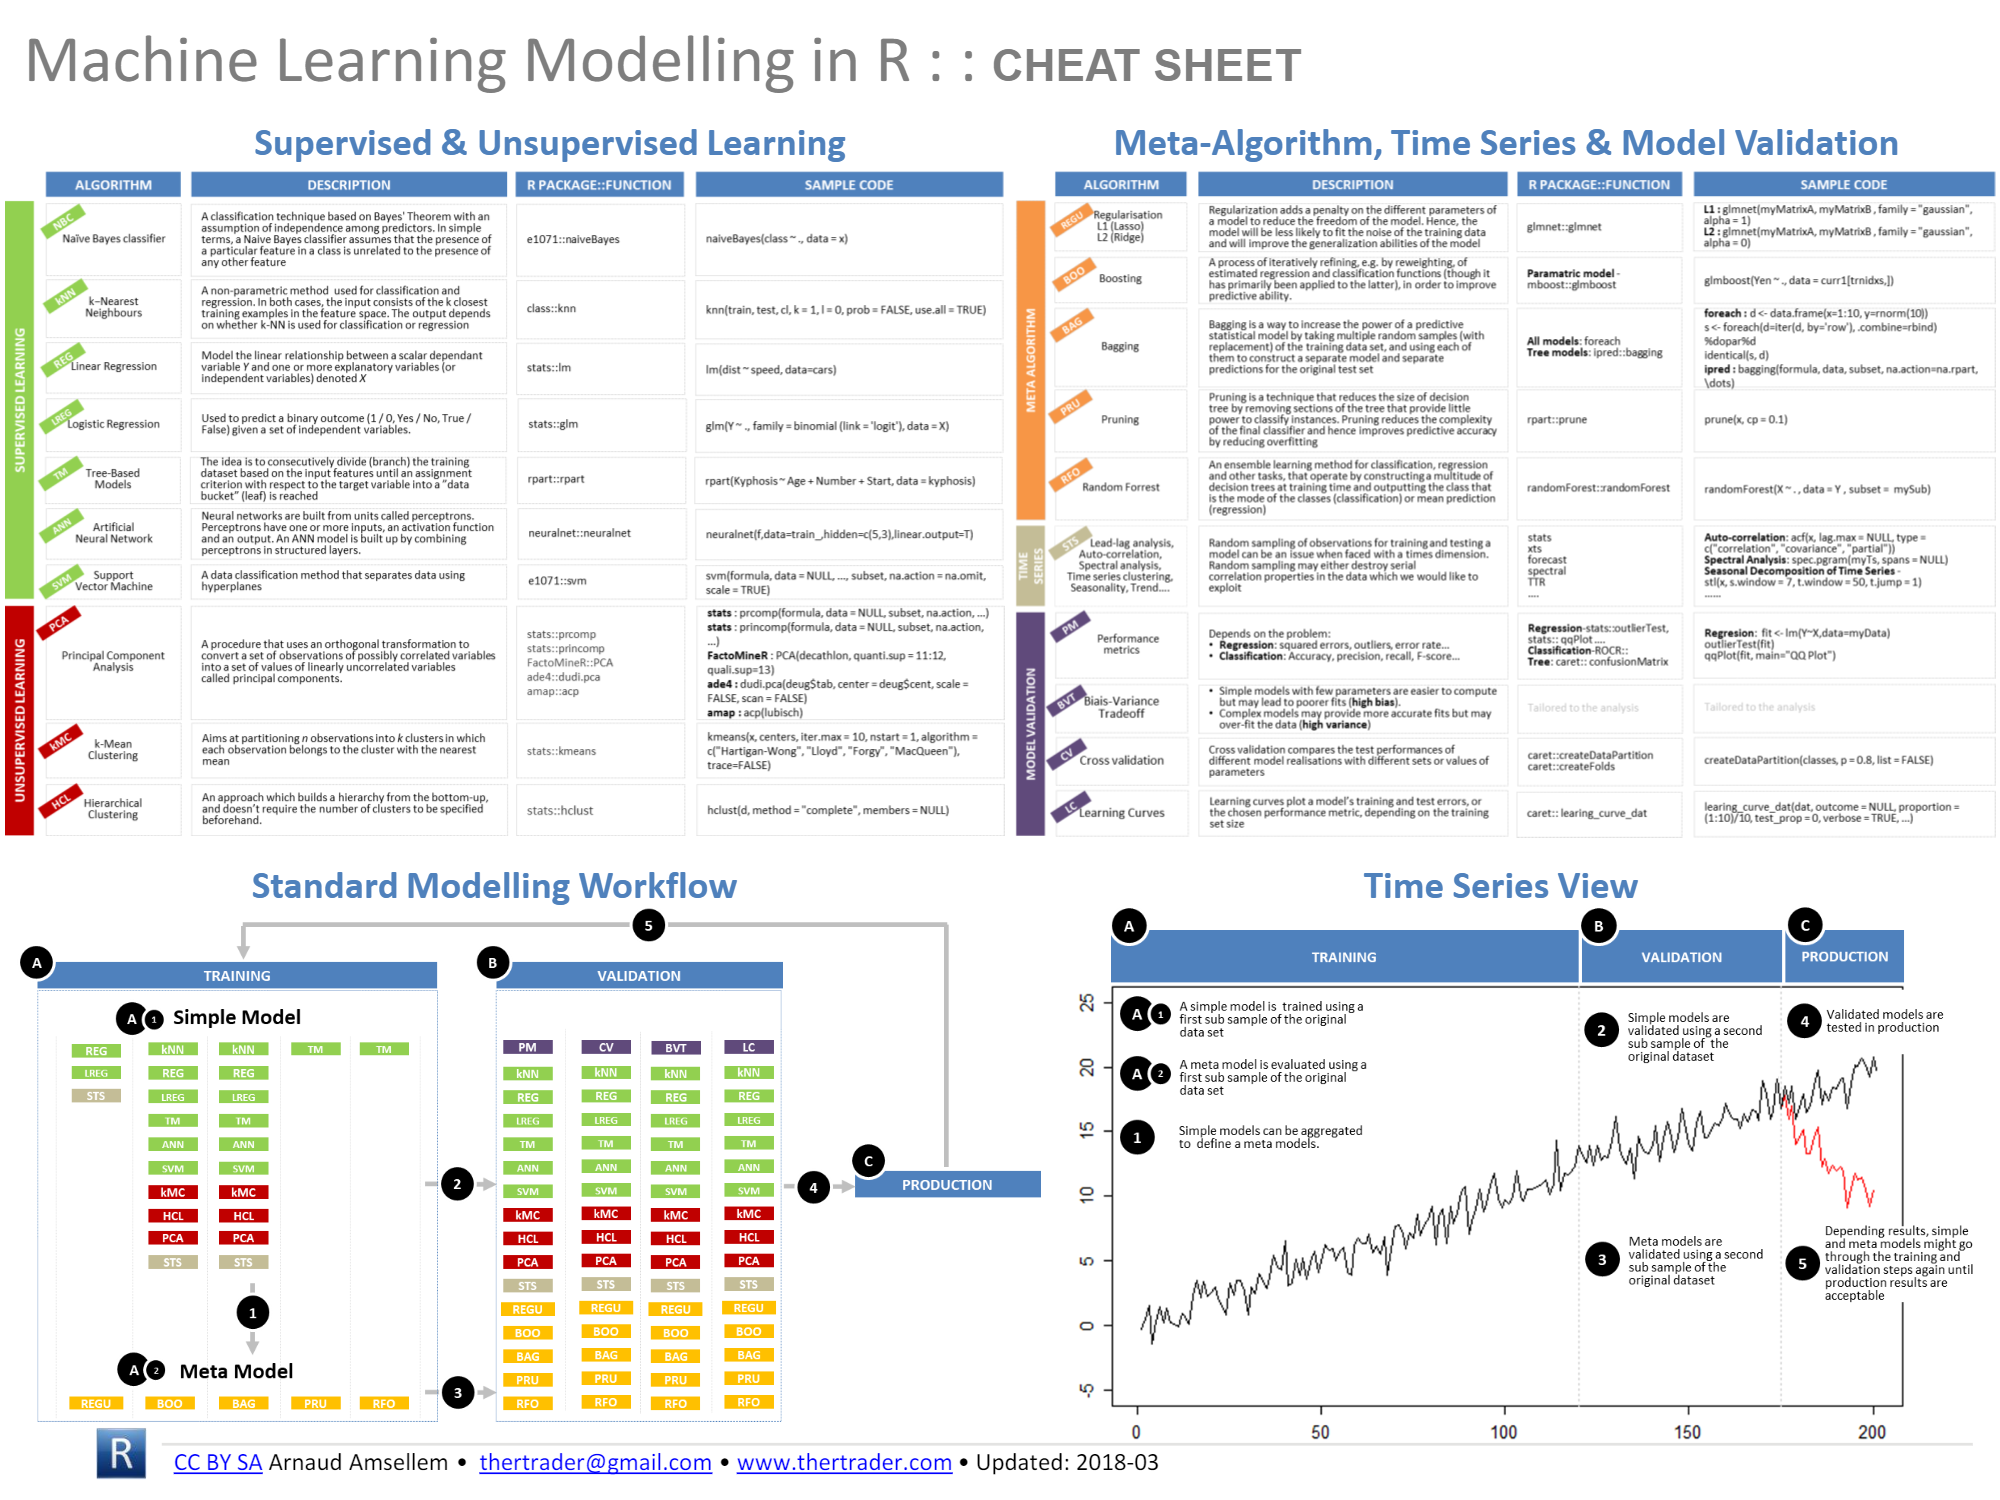
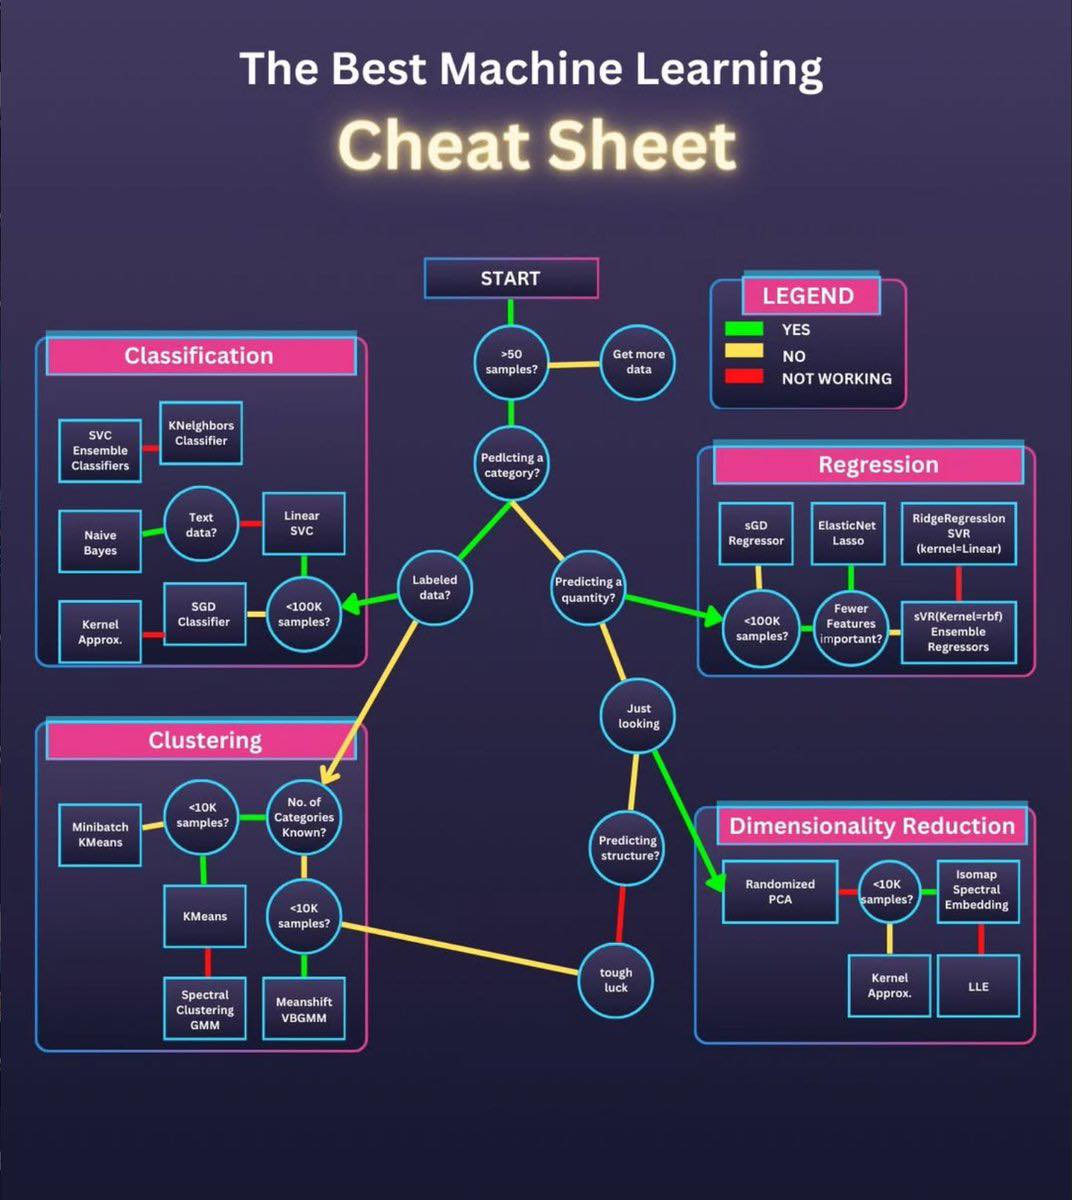
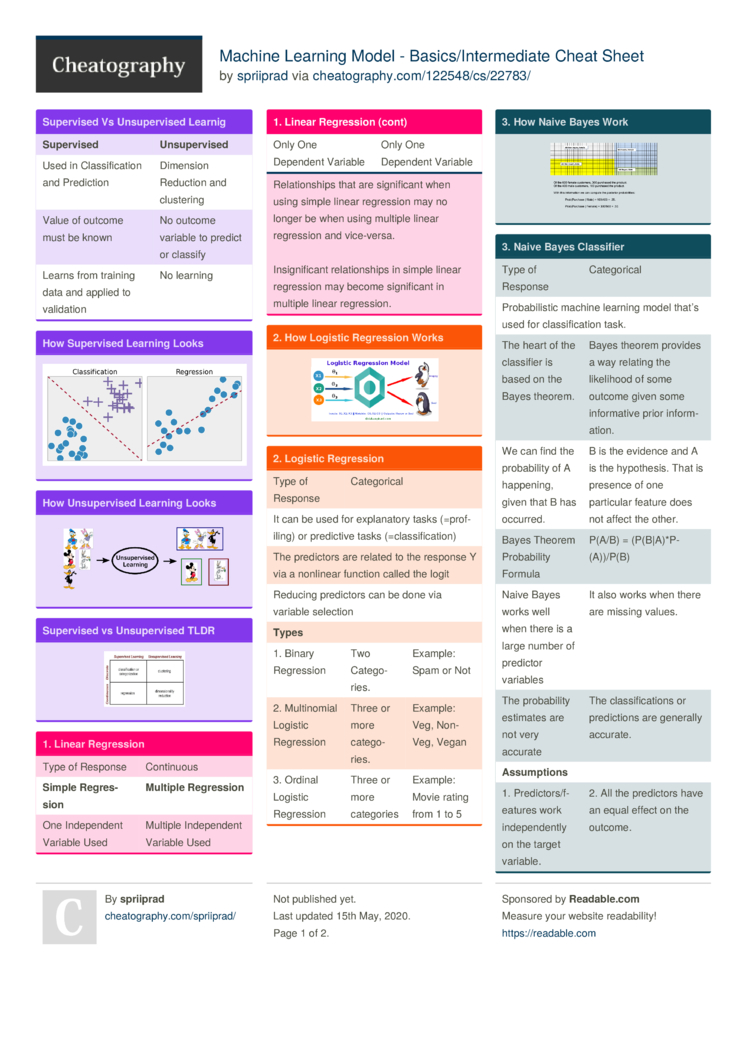
I've made enough of these to know the pattern. You open your browser and see another Machine Learning Cheat Sheet Aesthetic post showing some beautiful, impossible-to-read infographic that's been shared on LinkedIn three thousand times. The thing is, most of those look fantastic as posters and absolutely fail when you need to actually find something during a debugging session at 11pm. Let me explain how I approach this, because the process matters more than the final image. I start with the tools first. My workflow is Obsidian for content structuring, then I export to Markdown, render formulas with KaTeX or MathJax depending on the output format, and finally lay it out in CSS Grid or a simple HTML template. I don't use Figma or Illustrator anymore because the moment you move to a design tool, you start optimizing for visual appeal instead of information density. The result is always a chart that looks nice but doesn't save you any time.
The Machine Learning Cheat Sheet Aesthetic That Actually Works
Here's the thing about the aesthetic that nobody talks about: the most effective ones I've ever seen are ugly. Not terrible, just deliberately plain. Dark text on a light background, monospace font for code, a single accent color for highlighting critical differences between similar algorithms. The popular pastel flat-design trend with rounded corners and soft shadows? That's designed for Pinterest, not for someone scanning for the difference between L1 and L2 regularization while their training script crashed. The structural mistake everyone makes is organizing by topic instead of by decision. A cheat sheet should answer "which model do I reach for first" before it answers "how does this model work." I structure mine with a quick-decision tree at the top: categorical data, time series, small dataset, large dataset, and so on. Then underneath, each algorithm gets its own consistent block with the same five elements every time: the core equation, one-line intuition, when to use it, when not to use it, and the typical hyperparameters with their default values. I learned this layout through iteration, not theory. My first attempt was organized by mathematical properties, which meant anyone who didn't already know whether their problem was convex or linear had to read every single entry to figure out which one applied. That took me forty-five minutes to navigate once. The second version, organized by problem type, cut that down to about four seconds. The difference wasn't in the content. It was entirely in the entry points.
There's a specific edge case that drove me crazy for months. I was building a cheat sheet covering ensemble methods and tried to show the mathematical relationship between bagging, boosting, and stacking in a single visual diagram. The diagram was correct but unreadable at any size smaller than 4K resolution. What actually worked was abandoning the unified diagram entirely and instead creating a comparison table with three rows and five columns, each cell containing a one-sentence distinction. The table took up less visual space but conveyed the information faster because the eye doesn't have to trace connections across a complex diagram. It's a small thing but it shifted how I think about information architecture in these documents.
Get the Full Details

Common Pitfalls and What I Do Instead
The biggest pitfall is including every variant of every algorithm. I see cheat sheets that list thirty versions of gradient boosting and four types of neural network layers. That's not a cheat sheet. That's a textbook appendix. A cheat sheet needs to include the algorithms you reach for, not the algorithms that exist. If you've never used LightGBM in production, don't give it the same visual weight as XGBoost on your sheet. Another issue is the default hyperparameter values. Most cheat sheets list common defaults like learning rate of 0.1 or 100 estimators, but those defaults are wildly outdated for modern implementations. XGBoost's default learning rate changed years ago. LightGBM's default objective is different from what most tutorials claim. I cross-reference the current documentation for each library version and note the actual defaults, not the ones from a blog post written three years ago. This matters because if someone copies the wrong default into their code, their model might perform worse than a simpler baseline. Color choice is where most aesthetic decisions go wrong. The standard rainbow palette used in popular cheat sheets creates false ordering. When you see red next to orange next to yellow, the brain interprets that as a sequence or gradient when the categories are actually discrete. I use categorical color encoding with maximum three colors for grouping and reserve high-contrast accent colors only for warnings or critical differences. A cheat sheet about regularization should highlight the difference between L1 and L2 in red, not use a gradient from blue to green across eight different models.
The Tradeoffs You Should Know About
Printed cheat sheets have a fundamental limitation: you can't update them. The moment you finalize a PDF and share it, some library version changes a default parameter or deprecates a method and your sheet is slightly wrong. Digital versions solve this but introduce their own problems—links rot, hosted images disappear, and people hoover them up without contributing corrections. My workaround is maintaining the source in a public GitHub repository with a README that points to a rendered PDF, but making the rendered version a snapshot rather than a live build. That way people can use it offline without being confused by stale information, and the source stays correct because it's version-controlled. There's also a cognitive load tradeoff that most people ignore. A dense, information-rich cheat sheet requires working memory to decode. A sparse, minimalist one feels elegant but might force the reader to hold three pieces of information in their head simultaneously to understand a single concept. The sweet spot, from what I've observed across dozens of revisions, is roughly one screen's worth of content per page. Anything denser and people stop reading. Anything sparser and they flip ahead, missing the nuance in the section they skipped. If you're starting from scratch, don't design the visual first. Write the content. Structure it for lookup speed. Then apply a plain, high-contrast visual treatment that doesn't compete with the text. The aesthetic should serve the function, not the other way around. I've spent about twenty minutes on the visual styling of my current sheet and about three weeks refining the information architecture. The ratio is intentional.
The source repo is open if anyone wants to fork it and improve a section they know better than I do. That's the point of these things anyway.