What Machine Learning Checklist Weekly Actually Is
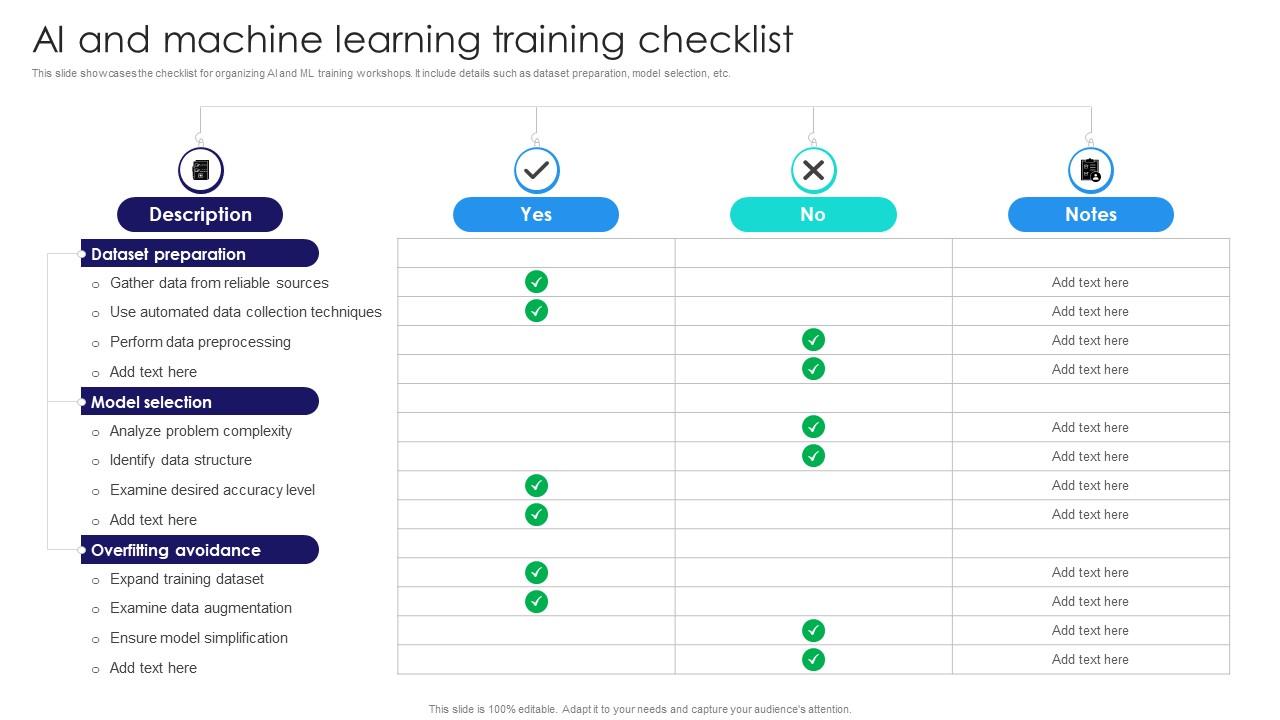
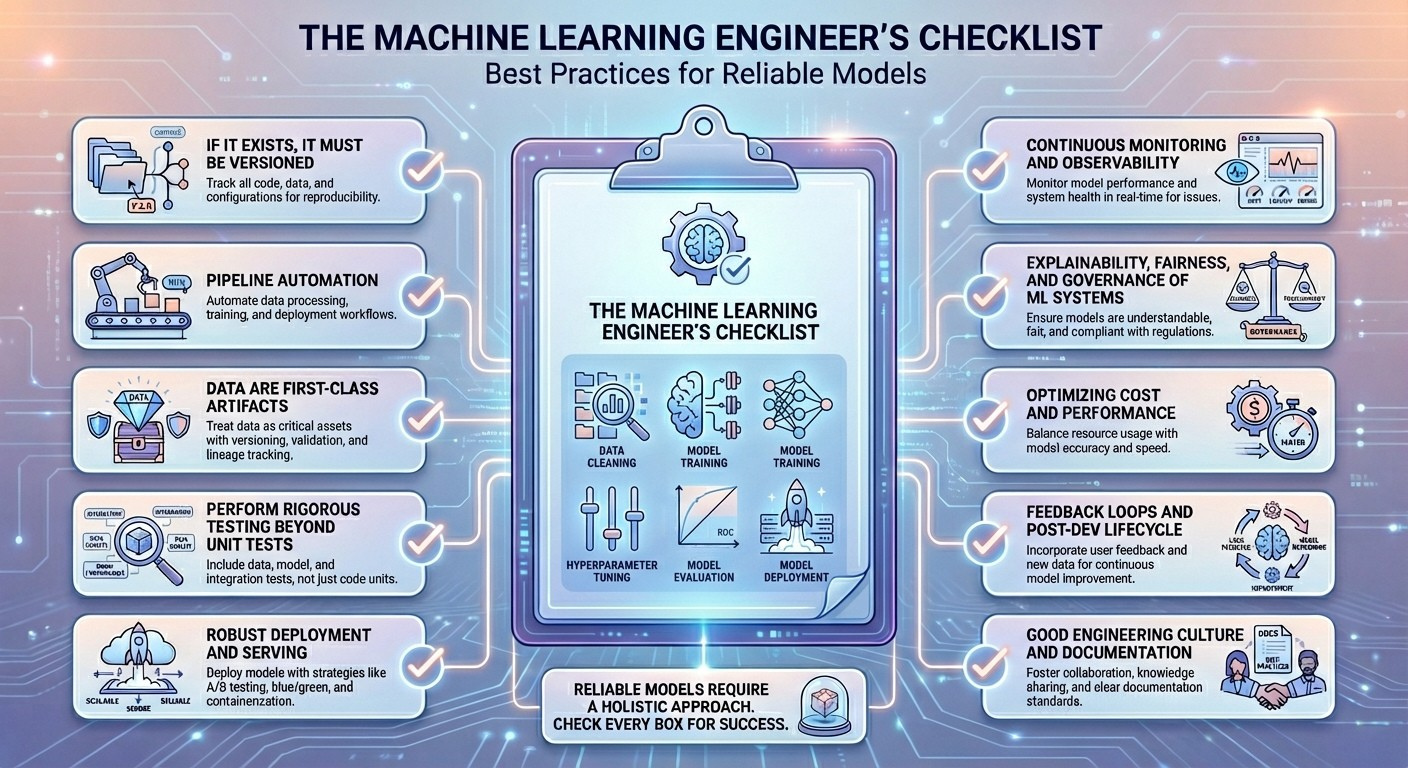
It is a structured workflow template designed to keep ML projects from quietly drifting off the rails. Most people build models in their own way and then realize three months later that they never validated on a holdout set, never tracked inference latency, and never documented their data pipeline version. The checklist exists to prevent exactly that kind of mess by breaking down the typical lifecycle into repeatable weekly tasks. The standard version lives on GitHub at ml-checklist-weekly/resources. You can clone it or just download the PDF directly. There is also a Notion template, a Google Sheets variant, and a plain Markdown file for people who do not want to install anything. The source code repository includes a requirements.txt if you are running the automated validation scripts alongside it. You run through the checklist at the end of each week. That is the simple version. The real version is that you assign one item to yourself on Monday morning, check it off Friday, and your lead takes fifteen minutes on Monday to verify the previous week's items before anything gets merged. Most teams I have seen drop this within three weeks because the initial scope is too ambitious. The template ships with about forty items covering data validation, training run tracking, evaluation metrics, feature store hygiene, model registry entries, deployment manifests, and post-deployment monitoring hooks. You pick the subset that applies to your current sprint and ignore the rest.
Here is a counter-intuitive thing nobody warns you about: the checklist is most valuable when you skip items intentionally. Every week I have a project where the team blindly runs through all forty items, wastes six hours on redundant checks, and misses the one critical item that actually matters. The disciplined version requires reading through the list once and marking which items are actively relevant to the current stage. If you are in early exploratory data analysis, you do not need a deployment manifest review. Period. I ran into a specific issue last year on a computer vision project where the checklist was causing more harm than good. The template includes a mandatory "retrain with full dataset" step every Friday. Our project had a data pipeline that ingested roughly two terabytes of raw imagery each week from five different camera feeds. Retraining on the full dataset every Friday took approximately fourteen hours on our GPU cluster, which meant we were always behind. If we completed it, we had no time left for actual model iteration. If we skipped it, the checklist flagged the gap and the weekly report looked bad. The workaround was straightforward. I wrote a small script that checked whether the new data volume exceeded a ten percent threshold compared to the previous training set. If it did, we retrained. If it did not, we logged the delta and moved on. I added this conditional logic as a custom extension hook in the checklist config file. It took about forty-five minutes to implement. The checklist continued to track whether retraining happened, but now the decision was data-driven instead of calendar-driven. We reclaimed roughly six hours per week. Our model iteration throughput increased by about thirty percent over the next quarter.
Common Pitfalls That Break This Workflow
The biggest failure mode is treating the checklist as a compliance document rather than a diagnostic tool. I have watched engineering leads force their teams to fill out every single field in a spreadsheet-style checklist every Friday, regardless of project phase. The result is always the same: people start gaming the checkboxes. They mark items as complete without actually verifying them. Within two months the checklist has zero informational value but still consumes twelve hours per sprint across the team. Another issue is the assumption that a single checklist fits all project types. A classification problem with clean tabular data has fundamentally different risks than a multimodal model trained on unstructured video data. The default template skews toward tabular and NLP workloads. If you are doing object detection or reinforcement learning, you will need to add custom items for annotation quality audits, reward function stability checks, and simulation-to-real transfer validation. These are not included by default. The third pitfall is operational fragility. The automated validation scripts that come with the checklist expect certain logging infrastructure. They look for Weights and Biases run IDs, MLflow experiment names, and specific S3 key patterns for artifact storage. If your team uses TensorBoard and stores models on GCS with a different naming convention, the scripts will throw errors or silently pass empty checks. I spent about a day rewriting the S3 parser to support our GCS bucket structure. It was not hard but it was not documented anywhere in the repo README. I submitted a pull request three months later and it got merged.
Get the Full Details
When This Approach Fails Completely
Machine Learning Checklist Weekly does not help if your team lacks basic data versioning. The checklist assumes you are already using something like DVC, LakeFS, or a comparable tool to track dataset snapshots. Without that foundation, the checklist items about data lineage and reproducibility become abstract concepts you cannot actually execute. You will check off "verify data version hash" but the hash itself will be meaningless because nothing is actually tracking version changes in your pipeline. Small teams of two or three people also struggle with this framework. The checklist was designed for squads of six to twelve where different people own different lifecycle stages. When you are a single person handling data engineering, model training, and deployment, the overhead of maintaining the checklist can outweigh the benefits. In those cases I recommend a stripped-down version with only eight items: data validation, training run logs, validation metrics, holdout evaluation, model registry entry, deployment configuration, monitoring alert setup, and incident documentation. The checklist also falls apart in research-heavy environments where the goal is exploration rather than production delivery. If your objective is to find a novel architecture or test a hypothesis, forcing weekly checklist discipline can slow you down more than it helps. The template assumes a shipping cadence. Prototyping cycles do not fit that rhythm.
Practical Implementation Steps
Start by downloading the PDF and the Python validation script. Read through all forty items once without checking anything. Then pick seven to ten that map directly to your current project stage. Add those to a personal checklist file and commit it to your repo under a config/checklist.yml path. This is better than modifying the shared template because your team can adopt your configuration without creating conflicts. Schedule a twenty-minute Friday review where you go through the selected items with at least one other team member. Two people reviewing catches issues that one person glosses over. I have seen teams skip this step and then discover a month later that their validation split was contaminated because the random seed had drifted between two separate data sharding operations. A fifteen-minute peer review would have caught it immediately. Track your checklist completion rate in a simple line graph. Not in a dashboard, just a weekly number from zero to one hundred percent. If the rate drops below seventy percent for three consecutive weeks, you have a process problem. If it stays above ninety percent but your model performance degrades, your checklist items are not catching the right risks. Adjust the item selection rather than increasing your effort.
The checklist itself will need periodic updates as your stack changes. When we migrated from on-premise GPUs to cloud instances last year, I removed three items related to hardware calibration checks and added two items for cost anomaly detection in our training runs. The config file format supports this kind of customization without affecting the base template. Keep your modifications in a separate overrides directory so you can pull upstream updates cleanly.