So you want to get serious about machine learning. Here's what actually happens.
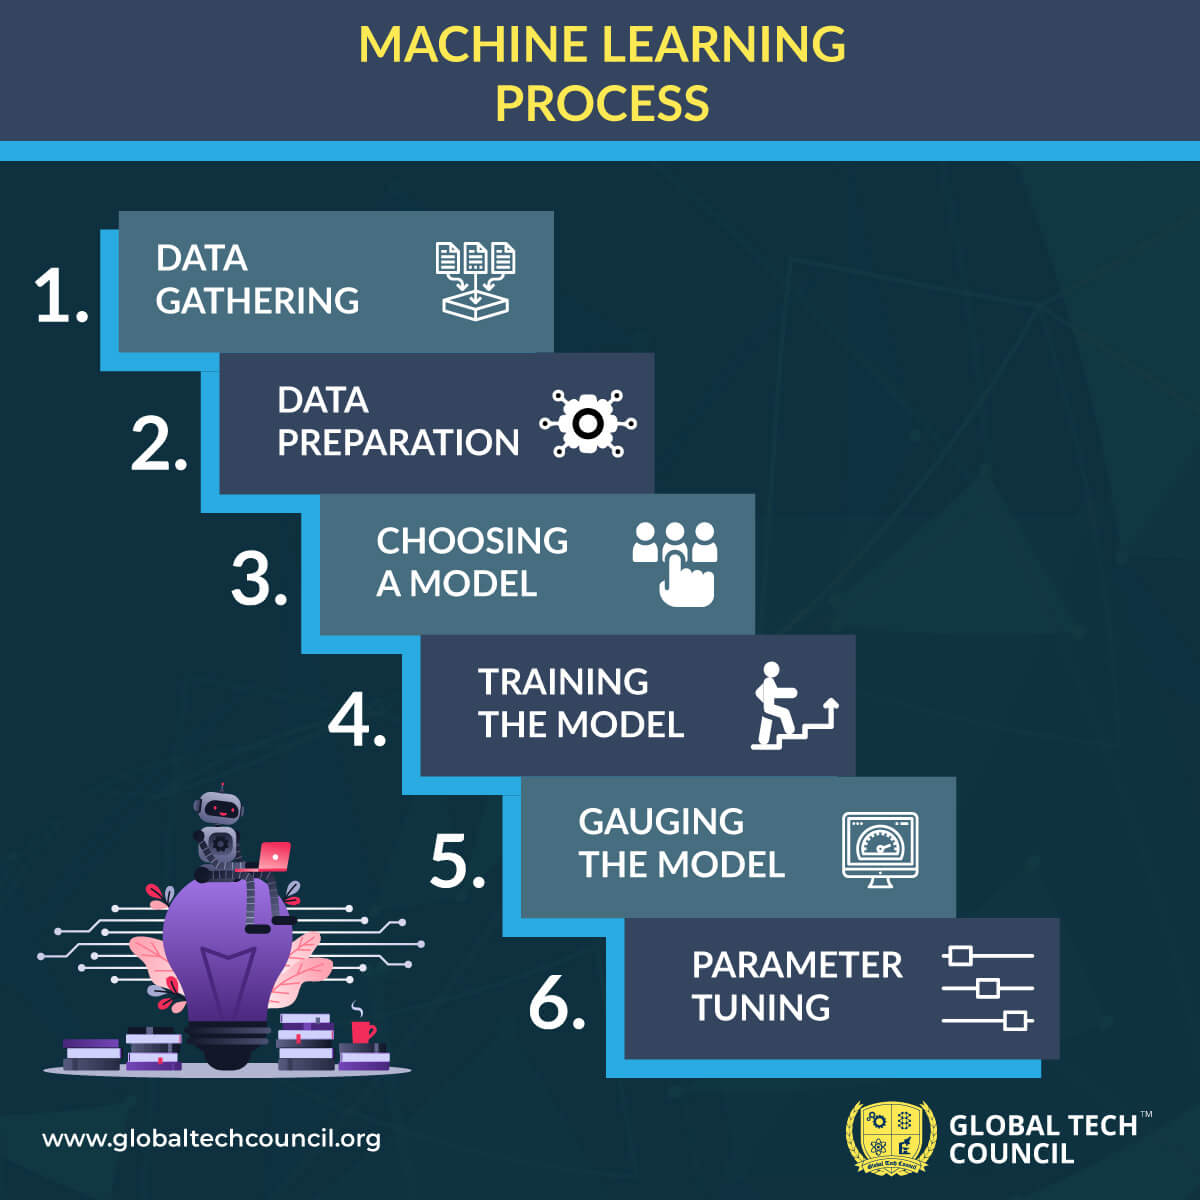
You open a tutorial. It works perfectly. Your model trains, your accuracy goes up, everything looks great. Then you try to deploy something real and it falls apart immediately. This is normal. Most people bounce off machine learning at this exact point because they never learned how the pieces fit together outside of a controlled notebook environment. I've watched this happen repeatedly over the years. A proper entry point needs to cover more than importing sklearn and fitting a model. You need to understand data preprocessing at a fundamental level, feature engineering, model selection, hyperparameter tuning, evaluation beyond accuracy, and deployment considerations. Most free resources stop at the fitting step. That's like teaching someone to drive in an empty parking lot and then expecting them to navigate rush hour traffic. The single most useful book I've found is Aurélien Géron's "Hands-On Machine Learning with Scikit-Learn, Keras & TensorFlow." Third edition covers modern deep learning properly. The exercises are genuinely difficult and force you to think through problems rather than just copy code. I reference it constantly when something doesn't behave as expected.
The Path That Actually Works
Start with foundational statistics. Not the computational part, the conceptual part. Probability distributions, Bayes theorem, maximum likelihood estimation, bias-variance tradeoff. If you skip this, you'll spend months debugging models without understanding why they fail. Stanford's CS229 lecture notes on Coursera are freely available and sufficiently rigorous without requiring a math PhD. After that, move to scikit-learn. Build several complete pipelines on Kaggle datasets, but don't chase leaderboard positions. Focus on understanding why you're choosing certain features, why your model behaves a certain way under different conditions, and how to diagnose overfitting versus underfitting. The "Introduction to Machine Learning with Python" by Müller and Guido covers this practical layer well. Deep learning comes after you're comfortable with traditional ML. Andrew Ng's deep learning specialization on Coursera is the standard introduction, though I'd recommend supplementing it with François Chollet's "Deep Learning with Python" for actual implementation intuition. Chollet explains things in a way that sticks because he focuses on mental models rather than mathematical formalism.
A Problem I Hit That No Guide Mentions
Last year I was building a classification model for a dataset with roughly 15,000 samples and a 98-to-2 class imbalance. Standard stratified cross-validation kept giving me wildly inconsistent scores between folds. The problem wasn't the model — it was the data split. With rare positive class samples, random splits would sometimes put nearly all positives in the training set, leaving the validation set useless for measuring real performance. The fix was using repeated stratified k-fold with 50 repeats instead of the default 5-fold. This stabilized the variance significantly. More importantly, I switched to using the area under the precision-recall curve as my primary metric instead of accuracy or ROC-AUC. For imbalanced datasets, ROC-AUC is misleading because it treats false positives from the majority class too leniently. The PR curve forces you to confront what actually matters for your specific use case.
Get the Full Details

Pitfalls That Waste People Months
Data leakage is the most common and most expensive mistake. I once spent three weeks debugging a model that consistently showed 94% accuracy on holdout data, only to discover that a preprocessing step was inadvertently using information from the test set during training. The fix was wrapping the entire pipeline in a sklearn Pipeline object, which enforces that fitting only happens on training data. This alone prevented countless leakage scenarios in subsequent projects. Another thing nobody tells beginners: gradient descent isn't always the answer. For tabular data with mixed feature types and moderate dataset sizes, tree-based methods like XGBoost or LightGBM routinely outperform neural networks. I've seen engineers burn through weeks tuning neural network architectures on problems where a well-tuned random forest would have been better by a wide margin and taken a fraction of the training time. Don't default to deep learning. Measure first, decide second.
Deployment Is Where Everything Gets Harder
Training a model is the easy part. Getting it into production involves model serialization, API design, latency optimization, monitoring for data drift, and retraining pipelines. FastAPI combined with ONNX runtime for model serving is my current go-to stack. It's fast, lightweight, and doesn't require the overhead of a full Flask application. For scheduling retraining, simple cron jobs calling a Python script work fine for small-scale systems. Production ML systems need versioning for both data and models — I use MLflow for tracking experiments and model registry management. The Fast.ai practical deep learning course is genuinely excellent and free. Jeremy Howard teaches from first principles upward, which means you understand what's happening rather than just reproducing code. The lecture videos are dense but the accompanying materials and forums are very active. Hugging Face's NLP course and transformers documentation are the best starting point for any natural language processing work. Their course is structured, free, and includes hands-on exercises with current architectures. The library itself handles most of the boilerplate that used to take days to implement from scratch.
For ongoing practice, Kaggle competitions provide real datasets and immediate feedback through public leaderboards. The discussions and shared notebooks under each competition are often more valuable than the competition itself. You'll see how experienced practitioners approach problems, what feature engineering tricks they use, and where others make mistakes.
The Honest Downsides
Machine learning as a skill requires significant upfront investment with no guaranteed payoff. You can spend two weeks preparing data and still have a model that performs no better than a simple heuristic. The field moves fast enough that tutorials become outdated within months. What's considered state-of-the-art today will likely be superseded within a year. Budget accordingly for continuous learning rather than treating any single guide as definitive. Also, having access to ML tools doesn't make you an ML practitioner. Building production systems requires software engineering discipline — version control, testing, CI/CD, monitoring, and documentation. Most machine learning projects fail not because the models are bad but because the surrounding infrastructure is inadequate. Plan for the engineering work before you start modeling.