Setting Up a Machine Learning Tracker That Actually Survives Production
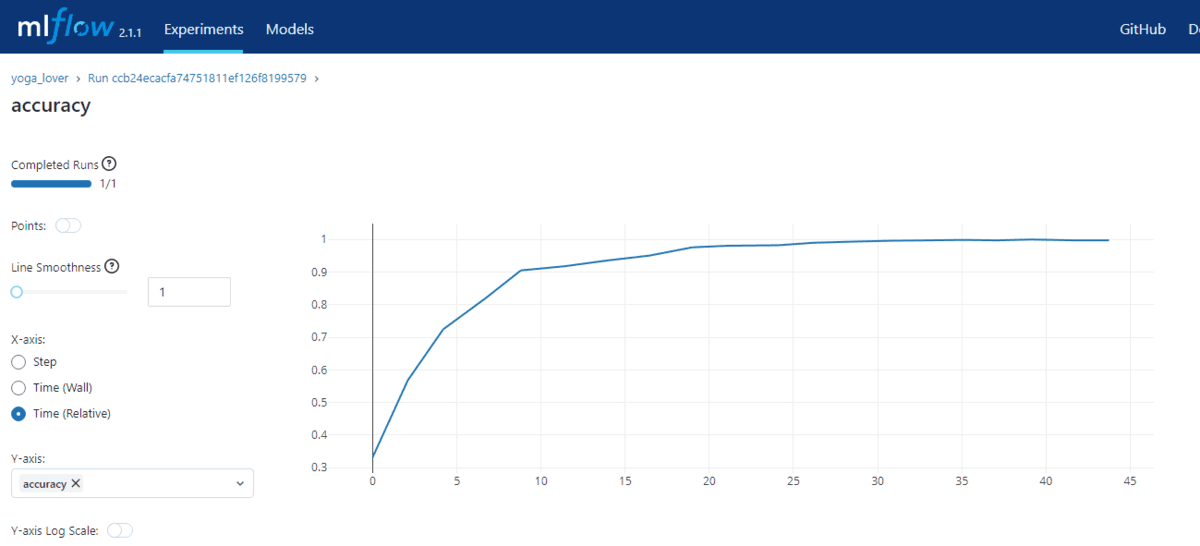
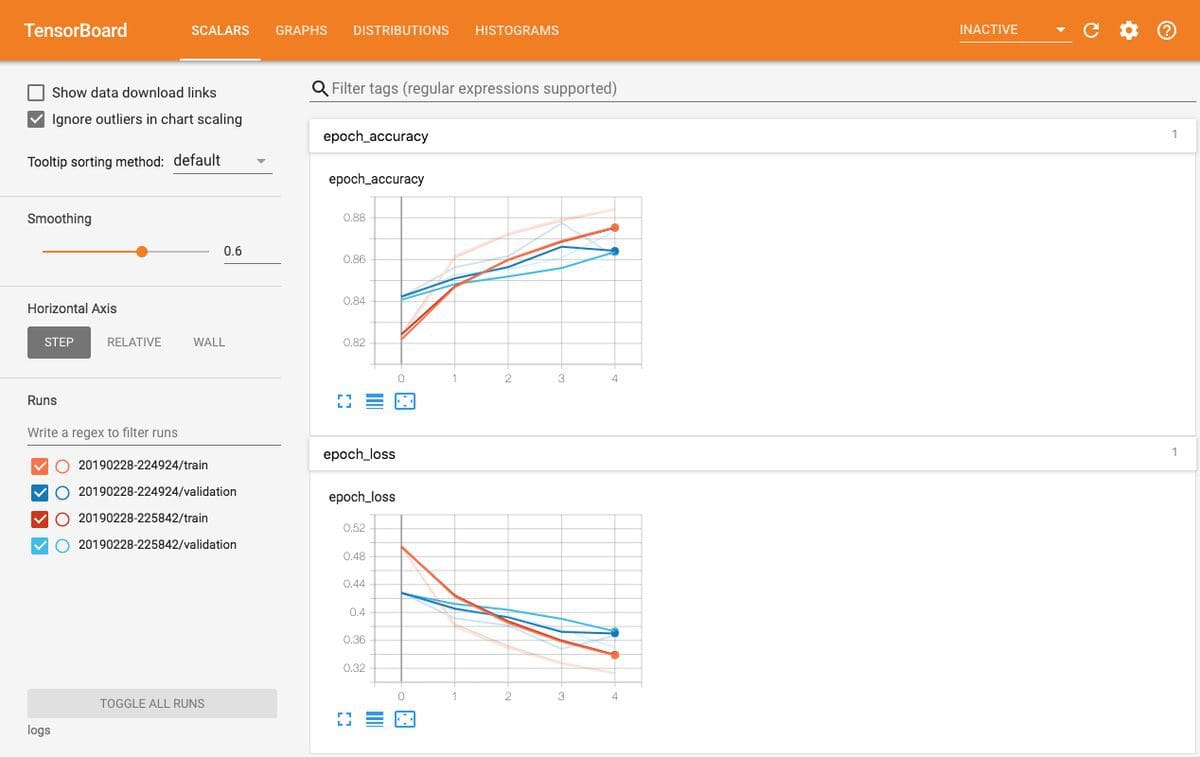
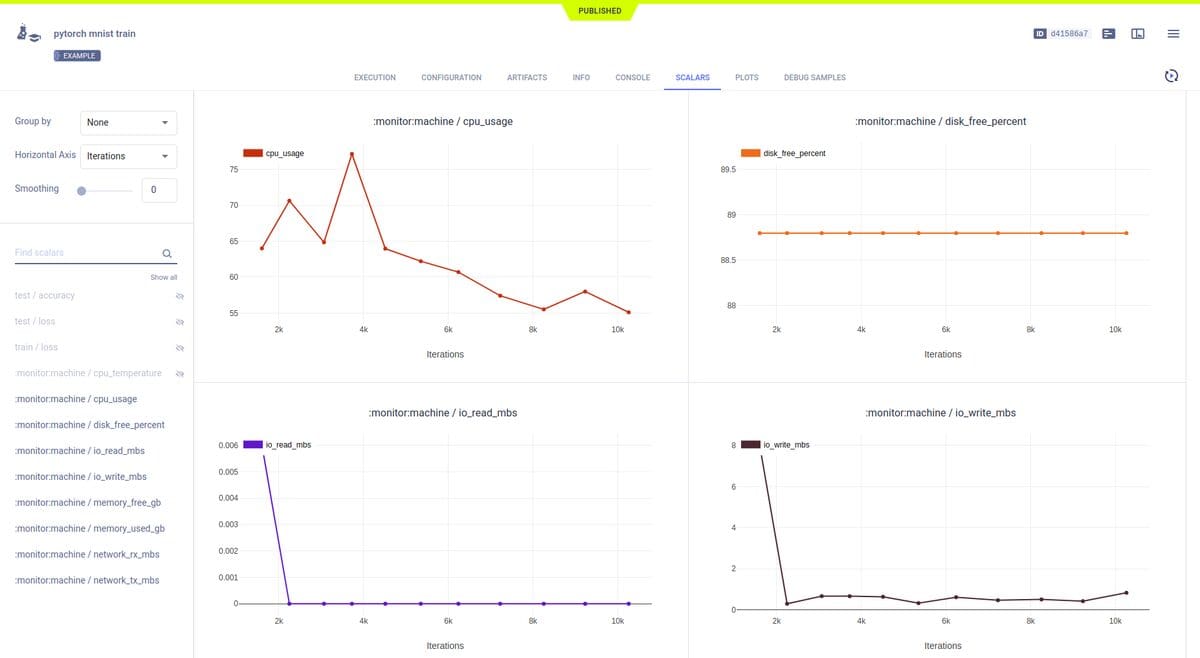
Most teams build experiment tracking infrastructure on top of hobby projects and then get burned when it fails under load. The gap between a notebook where everything works and a distributed training run that logs three terabytes of garbage is wider than people expect. I have spent enough years wrestling with this to know where the bodies are buried. The core concept is straightforward: you need a system that records hyperparameters, metrics, model artifacts, and system-level telemetry across training runs. What makes it difficult is that every team implements it differently depending on their stack, and most implementations are quietly wrong. The tooling landscape includes Weights & Wands, MLflow, TensorBoard, Neptune, sacred, and custom-built solutions. Each has tradeoffs that matter more than marketing pages admit. I started with TensorBoard because it was the path of least resistance. Early on it worked fine. Then a training run logged 84 million scalar events per step because someone left a gradient histogram dump enabled on a transformer model with 175 billion parameters. TensorBoard choked, the dashboard took forty seconds to render a single chart, and we lost three days of debugging time trying to figure out why experiments appeared missing. The fix was a filter config in the TensorBoard CLI and a hard rule that gradient logging only happens on validation steps, not every training step.
From that point forward I treated experiment tracking as an infrastructure problem, not a convenience feature. Here is the practical breakdown of how to set this up properly.
Choosing the Right Tracking Backend
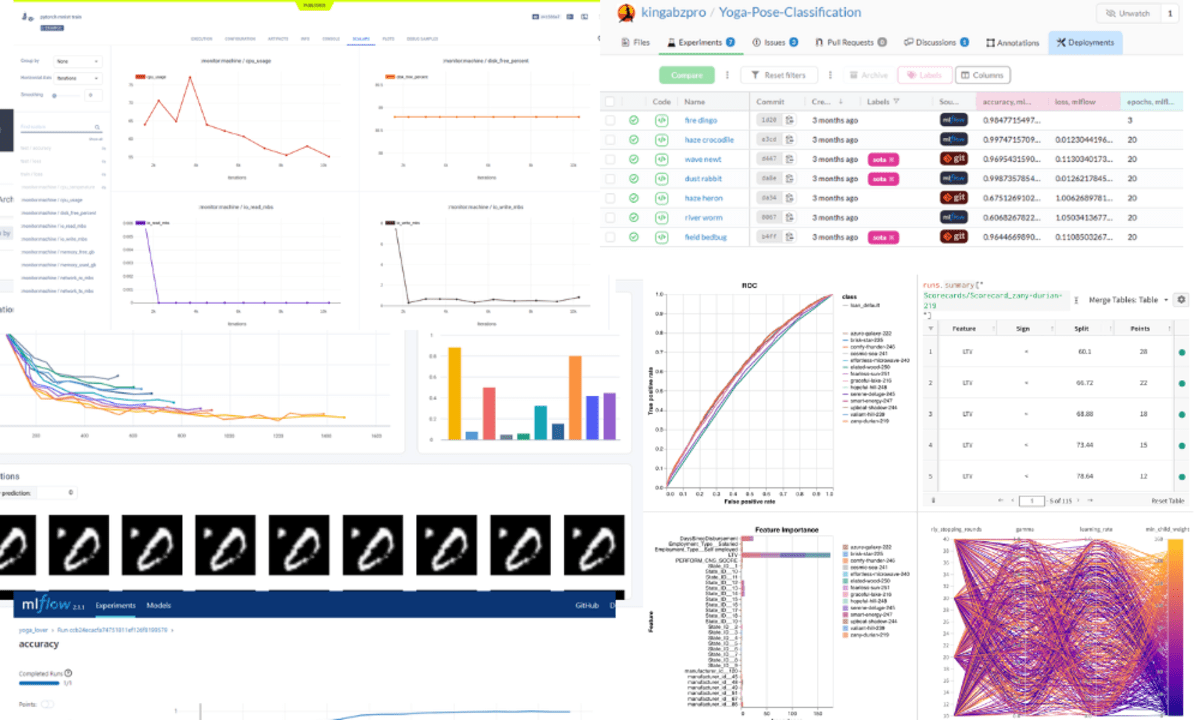
Your choice depends on three things: where your models live, how many concurrent runs you expect, and whether you need cross-team visibility. If you are running single-GPU experiments in Jupyter notebooks, TensorBoard stored locally is acceptable. Do not let anyone convince you otherwise. For multi-node distributed training across cloud VMs, you need a centralized backend. MLflow gives you an artifact store plus a tracking server with a REST API. The free tier is MySQL or Postgres under the hood, which means you can run it yourself on a small database instance. The paid Databricks-hosted version removes the operational burden but locks you into their platform. Weights & Wands is the most polished option for pure experimentation tracking. It handles artifact versioning, visualizations, and team collaboration out of the box. The downside is vendor lock-in and the fact that free tier storage gets restrictive quickly on long-running projects. Neptune is the quiet option that handles large-scale metadata well without the same storage aggression. It tracks datasets as first-class objects, which matters if you are doing data-centric ML rather than just model hunting. For teams already invested in AWS SageMaker, the native experiment tracking is decent but limited in visualization depth. Kubeflow Pipelines with its metadata store works if you are deep in Kubernetes but adds significant complexity for marginal gain.
Get the Full Details
Architecture Basics for a Functional Setup
Every tracking system needs four components: an experiment registry, a metric logger, an artifact store, and a query interface. The experiment registry is where you define runs, assign names, and tag them with branches or feature flags. The metric logger writes scalars, histograms, images, and text at configurable intervals. The artifact store handles model checkpoints, configuration files, and any binary outputs. The query interface lets you sort, filter, and compare runs. Here is a working Python implementation using MLflow as the backend: import mlflow\nimport mlflow.sklearn\nimport os\nfrom datetime import datetime\n\nmlflow.set_tracking_uri("http://your-tracking-server:5000")\n\nwith mlflow.start_run(run_name=f"exp_{datetime.now().strftime('%Y%m%d_%H%M')}"):\n mlflow.set_tag("dataset_version", "v2.3.1")\n mlflow.set_tag("gpu_type", "A100-80GB")\n mlflow.log_param("learning_rate", 3e-4)\n mlflow.log_param("batch_size", 32)\n mlflow.log_param("num_epochs", 50)\n mlflow.log_metric("val_loss", 0.0234, step=100)\n mlflow.log_metric("val_accuracy", 0.941, step=100)\n mlflow.sklearn.log_model(model, "model")
This is the skeleton. The details that make it production-ready are in the parameter and tag management, not the logging calls themselves.
The Problems Nobody Talks About
Logging frequency is the silent killer of tracking systems. If you log metrics every training step on a dataset with 50,000 samples and a batch size of 64, you are writing approximately 781 metric entries per epoch. Multiply that by 50 epochs and you have 39,050 rows per metric alone. Most tracking backends handle this fine for a handful of metrics. They do not handle this well when you are also logging gradient norms, weight distributions, and activation histograms at the same frequency. The workaround I use is step-based logging tied to validation intervals rather than training steps. Log metrics at epoch boundaries or every N validation steps. Use TensorBoard's built-in downsampling when you absolutely must log per-step data, and even then keep it to scalar losses only. Artifact management is the second landmine. Teams routinely accumulate terabytes of model checkpoints across experiment runs. A single fine-tuning job on a large language model can produce 12 checkpoints per run, each around 13 gigabytes. After two weeks of experiments you are sitting on nearly a terabyte of mostly redundant files. I solved this by implementing a retention policy: keep only the best checkpoint per run based on validation metrics, plus the final checkpoint. Everything else gets deleted after the run completes. The tracking system should not be your backup solution.
Environment reproducibility is the third problem. A tracked run is useless if you cannot reproduce it. I started logging full environment specifications including package versions, Git commit hashes, and CUDA driver versions. Before that change, we had three separate incidents where supposedly identical runs produced divergent results because someone had updated a dependency on the shared training node between runs. Now I use Docker containers with pinned base images and log the image digest as a run parameter.
Advanced Patterns That Save Hours
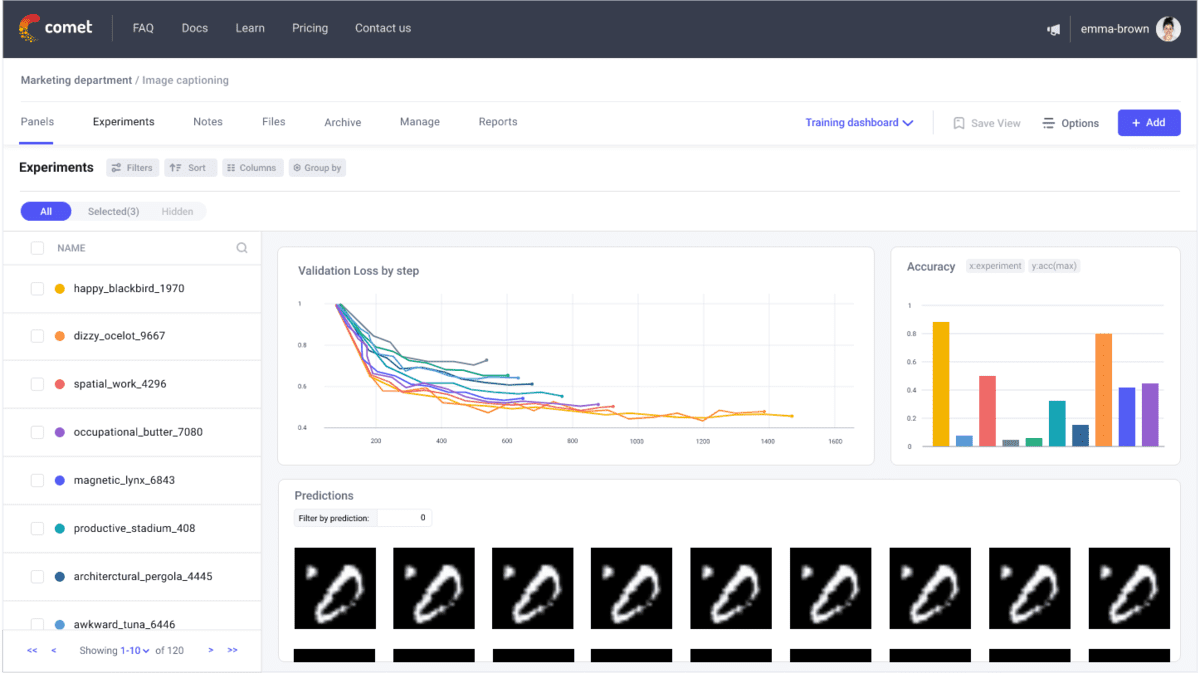
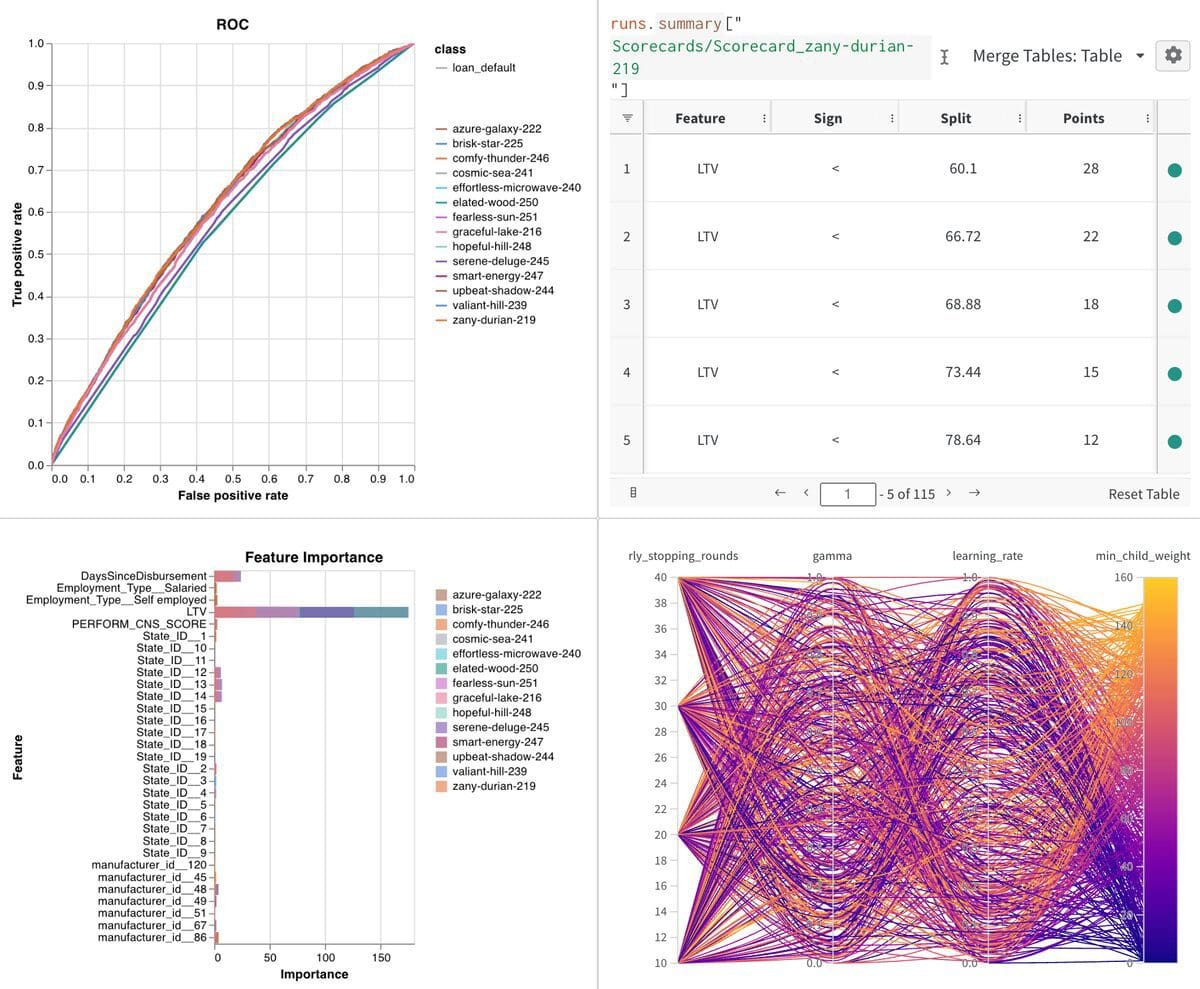
Run comparison workflows matter more than individual run tracking. When you are debugging why accuracy dropped from 94 percent to 89 percent across three experiments, you need to see parameter differences, metric trajectories, and loss curves side by side. MLflow's diff endpoint and W&B's table comparisons handle this well. Build a standard comparison template that auto-generates when you select multiple runs, so you are not manually pulling data each time. Hyperparameter sweep integration should be configured at the project level, not per experiment. Define your search space, sampling strategy, and early stopping rules once. MLflow supports Optuna and Ray Tune integrations. W&B has Sweeps built in. Configure the sweep config YAML file in your repository and version control it alongside your training code. Treating sweep configuration as code prevents the common failure mode where someone modifies a sweep parameter halfway through and cannot reproduce earlier results. Cross-environment tracking requires a centralized backend. Local TensorBoard files work for solo work but break the moment you have five people running experiments on different GPUs across different machines. A shared tracking server eliminates this. I recommend deploying MLflow or W&B on a small cloud instance with automated backups. The monthly cost is typically between twenty and fifty dollars depending on storage needs. The alternative is spending four hours per week reconciling which run happened on which machine.
When Tracking Systems Fail Completely
No tracking system handles the following scenarios well. First, real-time inference monitoring does not belong in your experiment tracker. These are different problems with different data characteristics. Use Prometheus and Grafana for production inference metrics. Mixing inference telemetry into your training tracking database corrupts query performance and makes it harder to find the signal you actually need. Second, unstructured research exploration resists tracking. When you are doing open-ended model architecture search with no clear hypothesis, rigid tracking frameworks add overhead without proportional value. Keep a simple log file and move on. The tracking infrastructure pays for itself when you are running systematic experiments with controlled variables, not when you are hacking together prototypes at 2 AM. Third, multi-cloud distributed training exposes tracking backend limitations. If your training spans AWS, GCP, and on-premise clusters, a single tracking server becomes a bottleneck or a single point of failure. The workaround is running a local tracking proxy on each cluster that syncs to a central backend when connectivity allows. Both MLflow and Weights & Wands support offline mode with later synchronization. Configure it explicitly rather than discovering the limitation when a critical experiment runs without any logged metrics.
A Working Configuration I Actually Use
For my current projects I run MLflow on a dedicated tracking server with PostgreSQL as the backend. The server handles artifact storage on S3 with lifecycle policies that transition old artifacts to Glacier after thirty days. Training scripts import a shared tracking module that handles connection retries, environment logging, and automatic run naming based on Git branch and commit. Validation metrics are logged every epoch. Model checkpoints are logged only at the end of each run and when validation loss improves. Early stopping triggers automatic run completion and artifact retention cleanup. The tracking dashboard is embedded in our internal wiki with read-only access. Query permissions are restricted to the ML team. This prevents the common failure mode where external stakeholders run heavy aggregation queries against the tracking database and slow it down for everyone else. The database runs on a moderate instance with read replicas for dashboard queries. Setup time for a new team member is approximately forty-five minutes: clone the tracking module, configure environment variables for the backend URI and artifact store credentials, and run the training script. Everything else is automatic. The tracking module captures Git information, system specs, Python version, GPU type, and all training parameters without requiring individual script modifications.
Experiment tracking is infrastructure. Treat it with the same seriousness you would treat your CI/CD pipeline or your database layer. Most teams underinvest here until something breaks during a critical experiment, and by then the damage is usually irreversible. The difference between a well-configured tracking system and a hastily assembled one is measured in hours saved during debugging, not in the initial setup effort.