Building something that actually trades is harder than the tutorials make it look
I spent three years building and tearing down trading models before I stopped treating it like a research project and started treating it like an engineering problem. The gap between backtest and live PnL is where most people get eaten alive. I still think about that gap every morning when I check the logs. The core idea behind a Machine Learning Trading Algorithm is straightforward on paper. You feed historical price data into a model, the model learns patterns, and you deploy it to predict whether a position should go long or short. What nobody tells you is that the "patterns" your model finds are usually just noise dressed up in a confidence interval. The real work happens in everything before and after the modeling step.
Where to start if you want this to be production-grade
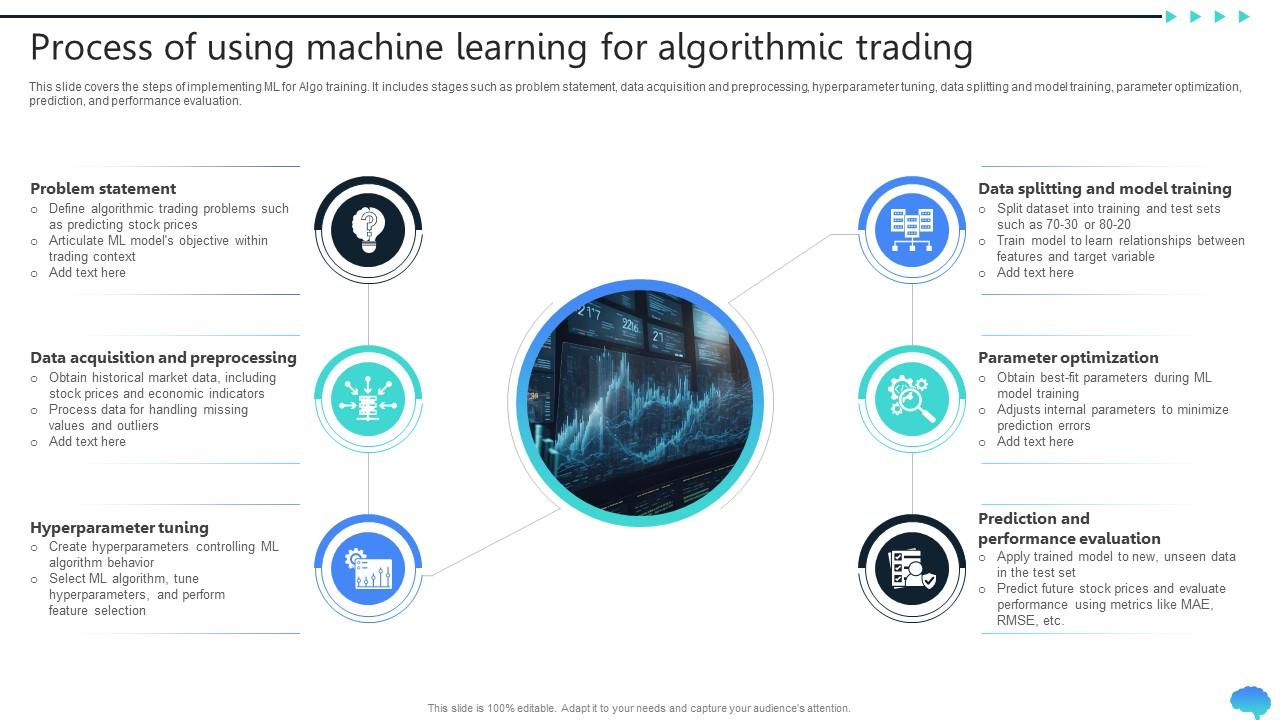
Don't begin with the model. Begin with the data pipeline. You need a system that can pull OHLCV data from your exchange or broker of choice, handle gaps, align timestamps across different instruments, and resample to whatever timeframe you're targeting. I use yfinance for quick prototyping and CCXT for anything that touches real exchange APIs. If you're trading crypto it's simpler because the data is messy in predictable ways. Traditional markets add things like corporate actions, splits, and dividend adjustments that will quietly destroy your backtest if you ignore them. Feature engineering is where you either make or break the model. Simple price data alone gets you nowhere. I pull rolling statistics like z-scores over multiple windows, volume imbalance ratios, order book depth metrics if your data source supports it, and macro regime indicators like VIX levels or bond yield curves. The feature space grows fast. I usually end up with 80 to 150 features depending on the asset class. After that comes dimensionality reduction. Principal Component Analysis works decently for linear structures, but I've found that tree-based feature importance from a quick XGBoost run followed by manual removal of correlated clusters tends to give cleaner results than any fancy autoencoder pipeline. Garbage in, garbage out applies here with unusual force.
The modeling phase
Gradient boosting models like LightGBM and XGBoost remain the workhorses. They handle non-linear relationships, are relatively fast to train, and don't require you to normalize every feature to zero mean and unit variance. Neural networks do have their place. I've used simple LSTM layers for sequence modeling on intraday data, but the performance gains over tree models are marginal and the training time is significantly worse. Transformer-based approaches are fashionable right now and you'll see papers claiming they outperform everything else, but most of those papers are backtested on data that was peeked at during feature selection. That's a whole separate problem. Here's the part most beginners skip. You need a proper walk-forward validation setup, not a simple train-test split. The market regime changes. A model trained on 2020 to 2023 data will likely fail on 2024 data if volatility structures shifted. I use expanding window walk-forward validation where I retrain the model on an increasing window of historical data and test on the next period. This takes longer to run but it's the only way to get a realistic sense of how your model degrades over time. A standard k-fold cross-validation will give you wildly optimistic results because future information leaks into your training folds.
Get the Full Details

One specific problem I ran into
I built a feature that measured the correlation between two highly liquid futures contracts to capture spread dynamics. The model loved it. Backtest showed a Sharpe ratio around 2.1 which is attractive until you actually try to trade it. The correlation feature was calculated using end-of-day closing prices from a static historical window, but in live trading the relationship between those contracts shifts intra-day based on roll dates and basis movements. The model was essentially trading on a label that was partially defined by the very price data it was trying to predict. That's lookahead bias and it's brutal to debug because the backtest looks perfect. The fix was to compute that correlation feature in a strictly rolling forward manner within the backtest engine, using only data available at the time of each signal. I also added a lag of one bar to every single feature to ensure no simultaneous information leaked through. This dropped the backtested Sharpe from 2.1 to 0.87 which was a painful but necessary correction. The live performance after that fix tracked much closer to the corrected backtest. Still not great, but at least it was honest.
Execution matters more than you think
Your model might generate accurate predictions but if you can't execute them profitably, the predictions don't matter. Slippage is the silent killer. In my experience with mid-cap equities, a model that shows a 55% win rate in backtest often drops to around 48% once you account for realistic slippage assumptions. I size slippage at roughly half the spread for liquid instruments and a full tick or two for less liquid ones. Commission costs compound quickly too. If you're trading frequently, even a few basis points per trade adds up to a material drag on annual returns. I also learned the hard way that position sizing based on raw signal confidence is dangerous. A model might be 99% confident on one signal and 51% on another, but both predictions could be wrong due to regime shifts. I switched to fixed fractional position sizing with a hard volatility cap. Each position gets sized so that a one standard deviation move against it never exceeds a small percentage of my total capital. This keeps you alive during the periods when every model in your pipeline is generating bad signals simultaneously.
What most people miss about feature decay
Features die. Not slowly. Sometimes they die overnight because some other participant figured out the same pattern and arbitrage it away. I track feature importance over time by retraining my model monthly and recording the top 20 features. When a feature that was consistently in the top 10 starts dropping below the median importance threshold, I remove it rather than waiting for it to become useless. This is expensive to maintain but it prevents your model from holding onto stale signals that used to work. The maintenance overhead is roughly four to six hours per month for a single strategy, which is significant if you're running this as a side project. You don't need a GPU cluster for a single strategy. A decent laptop with 16GB of RAM handles LightGBM training on daily data just fine. Intraday strategies are different. If you're working with minute-level or tick data, you'll want a proper machine or cloud instance. I run mine on a small AWS EC2 instance with an SSD for fast data reads. Containerizing the whole thing with Docker makes deployment and replication much easier. The first time your backtest server crashes at 3 AM because of a memory leak in your data loader, you'll appreciate having a script that can restart everything automatically. For data storage, parquet files are significantly faster than CSV for any non-trivial dataset. I store raw data in parquet with column pruning for features I don't need. This reduces read times from minutes to seconds on datasets larger than a few gigabytes. The initial conversion takes a while but it pays off immediately after.
Honest limitations
Machine Learning Trading Algorithm approaches have real constraints that aren't discussed enough. The primary limitation is that markets are adaptive systems. Any pattern your model learns is, by definition, something that existed in the past. As more participants learn the same pattern, its predictive power diminishes. This isn't theoretical. I've seen strategies with sharp backtested returns decay to near-random performance within 18 months of going live. The second limitation is overfitting. It is incredibly easy to build a model that memorizes historical noise instead of learning signal. You need out-of-sample testing, stress testing on known crisis periods, and ideally a holdout set that the model has never seen during any part of development. The third limitation is that ML models don't understand causality. They find correlations. If your model learns that a certain price pattern predicts a rally, it doesn't know why. When that pattern stops working for reasons your model can't anticipate, you won't know why until you're already losing money. I supplement my ML signals with fundamental filters and macro regime classification to add some contextual awareness. A random forest doesn't care if there's a Federal Reserve announcement tomorrow, but you should. If you're just starting out, I'd recommend beginning with a simple logistic regression or even a moving average crossover strategy as your baseline before jumping into deep learning. Knowing what a dumb model produces helps you understand whether your sophisticated model is actually adding value or just adding complexity. The delta between a well-tuned simple model and a complex one is often smaller than marketing materials would lead you to believe.
There's no download link or pre-built solution that works out of the box. The code has to be yours because your data, your execution environment, and your risk parameters are all different from anyone else's. I keep my stack open source with LightGBM for modeling, CCXT for data, and a custom backtest engine built on pandas and numpy. It's not elegant. It works well enough. The most useful resource I found wasn't a paper or a course, it was simply keeping a detailed journal of every model iteration, every failed experiment, and every unexpected behavior. That journal is worth more than any algorithm I've shipped.