How to Build a Map Of China Languages That Actually Works
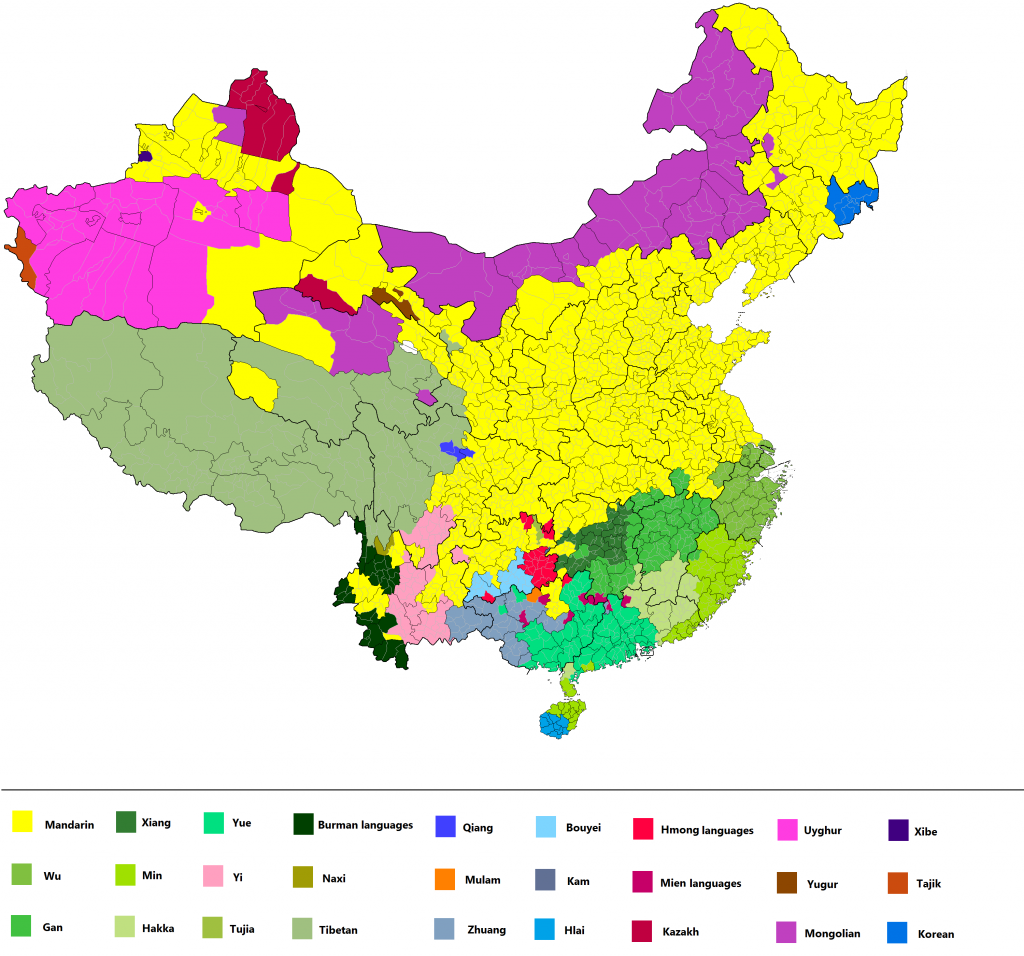
I've spent way too many late nights arguing with choropleth maps and ISO 639-3 codes. The core problem is that China has over 300 distinct language varieties — some classified as languages, some as dialects, depending on who you ask — and most mapping tools collapse them into a binary Mandarin/English grid. That ruins the data immediately. Start by defining your scope. Are you mapping official languages, minority languages, or a combination of both? China recognizes 56 ethnic groups, each with their own language situation, but the actual linguistic landscape is messier than any official count. Uighur, Tibetan, Mongolian, Zhuang, Korean, Kazakh, and Mandarin coexist alongside dozens of Sino-Tibetan, Altaic, and Austroasiatic varieties that don't always fit neatly into government categories.
Getting the Base Data Right
The first step most people skip is collecting the raw distribution data before opening any GIS software. Glotoindex lists roughly 315 languages for China, but that number fluctuates depending on whether you count sign languages, creoles, or language varieties split across borders. If you need hard numbers, Ethnologue is more stable but has a paywall after entry-level access. The Atlas of the World's Languages in Danger at UNESCO covers many of the endangered ones and is free. What actually saves time is combining three sources: the China Language Map Project (a domestic effort with solid provincial-level data), ISO 639-3 shapefiles from SIL International, and the PLSDB (the Pangloss Language Databank) for speaker population estimates. You won't get perfect overlap, which is where things get tedious. I spent two days once trying to reconcile administrative boundary files from the National Geomatics Center of China with Natural Earth boundaries because they simply didn't align at the county level. My workaround was to dissolve everything to the provincial level first, then refine only the provinces with high linguistic diversity — Yunnan, Xinjiang, Guizhou, and Inner Mongolia. The rest of the country could handle a simpler classification without losing much accuracy.
Choosing Your Projection and Color System
Most people default to a standard choropleth with a diverging color scheme. For a Map Of China Languages, this approach hides the signal you actually want to see. Languages aren't quantities with a midpoint. Mandarin has roughly 920 million speakers. Tibetan has maybe 6 million. A diverging scheme implies symmetry that doesn't exist here. Use a sequential or qualitative palette instead, depending on what you're emphasizing. If you're showing language families, go qualitative — Sino-Tibetan, Altaic, Indo-European, Austronesian, Austroasiatic. Each family gets a distinct hue. If you're showing speaker count, use a sequential scale with a log transform on the axis. Raw linear scaling makes every minority language invisible against Mandarin's overwhelming presence. The projection matters less than you'd think for this use case, but avoid anything that distorts area heavily in western China. The People's Republic of China's official map uses the China Albers Equal Area Conic, which is reasonable if you have access to those shapefiles. Otherwise, a standard Lambert Conformal Conic centered on China works fine for display purposes. Don't overthink it.
Get the Full Details

Handling the Dialect Problem
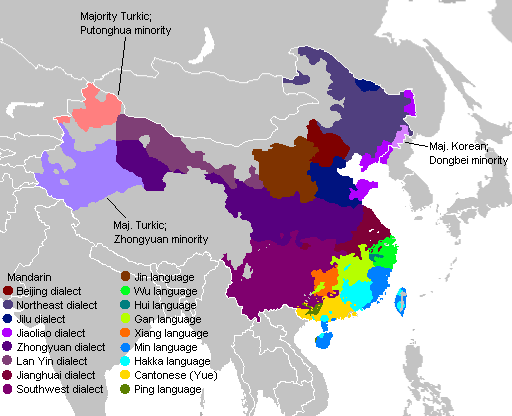
This is where most maps fail. Chinese "dialects" like Wu, Yue, Min, Gan, Xiang, and Hakka are not dialects in the linguistic sense. They are mutually unintelligible languages that share a writing system and a political framework calling them dialects. A map that labels these as "Mandarin variants" is misleading. A map that treats them as separate languages without context is confusing to readers who expect them to be dialects. The practical solution is to create a layered map. Layer one: official administrative languages. Layer two: major Sinitic varieties with a legend note explaining the terminology. Layer three: non-Sinitic minority languages. Most GIS platforms support this natively. If you're using QGIS, set up a rule-based renderer that assigns colors based on a category field, then toggle layers on and off. Export each version separately rather than trying to cram everything onto one static image. I ran into a specific issue once where a contributor had labeled "Hakka" as a single homogeneous block across Fujian, Guangdong, and Jiangxi. In reality, Hakka speech varies considerably between counties, and the border regions blend into neighboring Yue and Min varieties. I cross-referenced the county-level survey data from the Social Sciences Literature Database and found that only three of the six target counties had clear Hakka-dominant populations. The other three were mixed. I redrew those boundaries manually instead of relying on the original shapefile, and the difference was noticeable when zoomed in.
Adding Speaker Population and Vitality Data
A static language map is incomplete without indicating how viable each language is. Many of the languages on a China language map are in decline. Zhuang, for example, had roughly 1.85 million speakers in the 2000 census but has dropped significantly since, with Mandarin immersion programs in schools accelerating the shift. Uyghur remains robust in southern Xinjiang but faces pressure from Mandarin-only policies in education and public signage. Include an vitality index if possible. Combine UNESCO's language endangerment classifications with national census data. Color-code by endangerment level rather than by language family for a secondary overlay. This adds real analytical value without cluttering the main map. The bottleneck here is data recency. China's latest full census with detailed linguistic data is from 2020, and provincial-level breakdowns aren't always published in the same format. You'll encounter situations where a province reports total minority-language speakers but not per-language breakdowns. In those cases, fill gaps with the 2010 census data and flag them as estimated. Don't present old data as current without a note.
Export and Publication Notes
If you're publishing this map online, generate both a high-resolution PNG for print and an interactive SVG or GeoJSON-based web version. Static images can't convey the complexity of overlapping language zones. An interactive version with hover states showing language name, speaker count, and classification takes about 45 minutes to set up in QGIS with the Qwebexport plugin or in Leaflet if you have vector data ready. The final check before anything goes public: verify that your map doesn't inadvertently include disputed territory in a way that implies sovereignty claims. Taiwan's linguistic map should be clearly separated or noted. The South China Sea islands have negligible language data anyway, but border regions with India, Nepal, and Vietnam need careful boundary sourcing. Use the official Chinese government boundary files and cross-reference with OSGeo's country boundary datasets to catch discrepancies early.