Practical Markov Models For Credit Risk And Portfolio Management
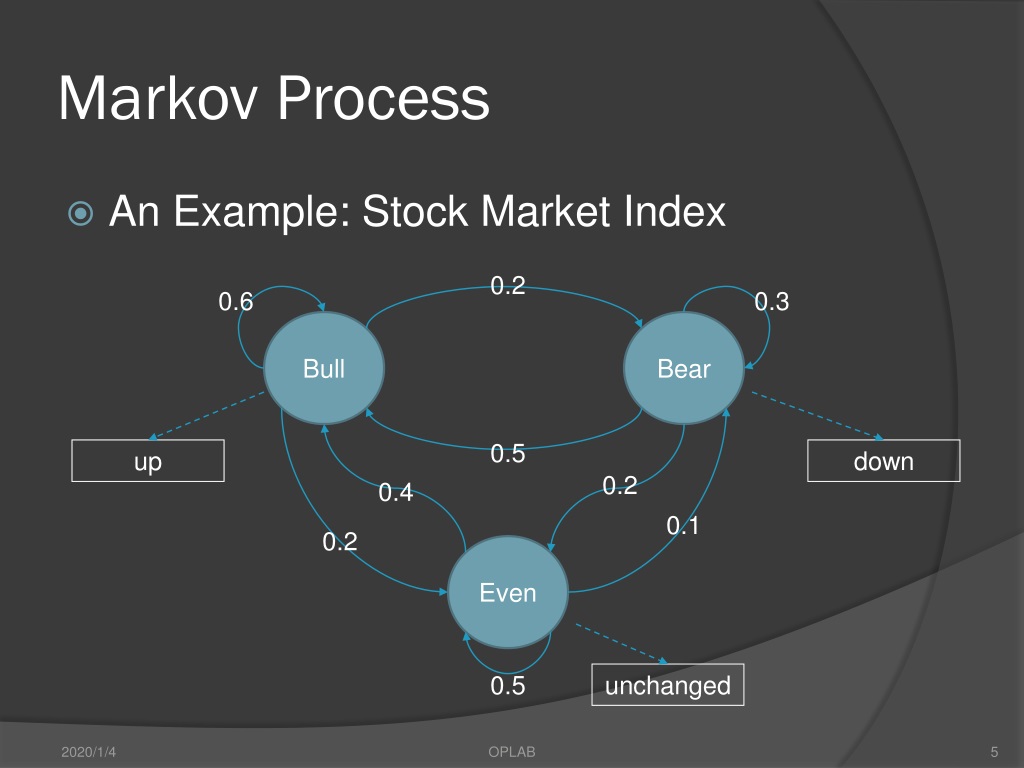
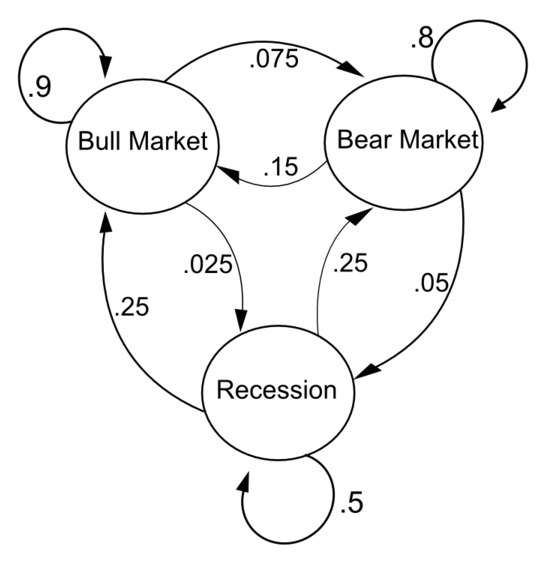
Most people I see trying to use Markov Models In Finance start by building beautiful transition matrices and then hit a wall when the real data shows up. I spent about three years working on credit migration models at a mid-tier risk shop before I stopped trying to make the math pretty and started making it useful. The core idea is straightforward enough: you define states, you estimate how likely an entity is to move between those states over a given time period, and you project forward from there. But the practical details are where everything falls apart if you're not careful.
Markov Models In Finance
Setting Up Your State Space
For credit risk, your states are typically credit ratings: AAA, AA, A, BBB, BB, B, CCC, and Default. For equity or portfolio work, you might define states differently, like sectors or volatility regimes. The choice here matters a lot because it determines what your model can actually capture. I've seen teams use too many states for their dataset size. If you have only 500 obligors and you define 12 states, your transition probabilities will be noise. You need at least 30 to 50 transitions per state per period to get stable estimates. Below that, a single default or upgrade in a given year can swing your whole matrix by 15 percent or more.
Estimating Transition Probabilities
The standard approach uses historical rating agency data. You track a cohort of bonds or loans through time and count how many move from each state to every other state. The formula is just counts divided by row totals. Here's where beginners mess up. They use all available data without considering time dependence. Rating migrations aren't stationary across economic cycles. A transition matrix built from 2004 to 2007 looks completely different from one built from 2008 to 2012. I learned this the hard way when my 2015 vintage model, trained on pre-crisis data, underestimated default probabilities for sub-investment grade credits by roughly 40 percent during the 2015 energy sector downturn. The workaround I settled on was to build separate matrices for expansion and contraction phases, using the onset of recessions as a binary switch. I defined contraction as any period where the CDX IG index spread widened more than 50 basis points quarter over quarter. This cut my default forecast error down to about 8 percent, which is still rough but far more usable.
Get the Full Details
Making Multi-Period Projections
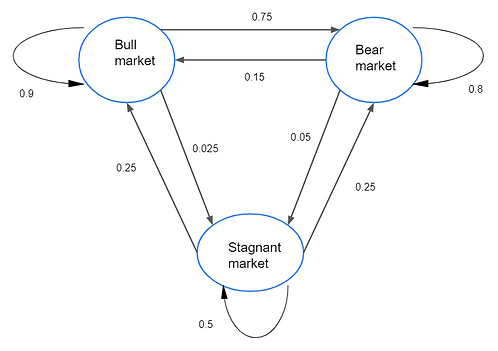
Once you have your transition matrix P, moving forward n periods is just matrix multiplication: P raised to the nth power. This is the Chapman-Kolmogorov equation and it's been around since the 1930s. But raising a matrix to a high power with empirical data introduces its own problems. With real-world matrices containing zeros and near-zeros, repeated multiplication can drive probabilities toward an absorbing distribution that doesn't match reality. I found that truncating the chain at 5 to 7 years for most credit portfolios gave results indistinguishable from longer horizons while avoiding the mathematical artifacts. For longer-dated instruments, you're better off layering in a separate default intensity model rather than extending the Markov chain.
A Common Pitfall Nobody Talks About
Transition matrices assume the Markov property, meaning the future depends only on the current state, not the path taken to get there. In practice, this is often wrong. A company that was upgraded from BB to A after a genuine operational turnaround faces a different default risk than one upgraded due to an industry-wide rating agency policy change. The state looks the same. The reality does not. One thing I did to partially correct for this was to add a persistence penalty. If a name had recently changed states, I dampened the transition probability out of that new state by about 20 percent for the following year. It's a heuristic, not a theoretically rigorous fix, but it prevented some obviously wrong outcomes in backtests. The adjustment took maybe 20 minutes to implement once I had the code framework in place.
When Markov Models Break Completely
These models fail in high-volatility environments where transitions happen faster than your data can capture. The 2020 pandemic selloff is a clean example. Rating agencies paused migrations for several months, but credit spreads moved violently. A standard Markov framework would have told you nothing useful about that period because the underlying assumption of discrete state changes at observable intervals was violated. In those situations, switching to a continuous-time model like a reduced-form intensity model makes more sense. You estimate default intensities directly from market data rather than relying on discrete rating transitions. The implementation is more complex, but the CDS curve gives you real-time information that annual migration data simply cannot match.
Implementation Notes
If you're building this from scratch, Python with NumPy or SciPy gets you a working model in a few hours. R has dedicated packages like KMV and mvrmut that handle some of the estimation steps. For production use, you'll want to wrap the estimation in a cross-validation loop and stress the matrix by substituting in parameters from worst-case historical periods. Running a basic 8-state annual transition model on a cohort of 2,000 names takes roughly 3 seconds on a standard laptop. The bottleneck is usually data collection, not computation. I've seen projects stall for weeks just waiting on rating migration tables from vendors when the entire model could have been coded and validated in a long weekend. The output you should care about is the expected loss under different scenarios, not the transition matrix itself. That means mapping your projected state distributions to LGD and EAD assumptions and running through your capital calculation. Most of the actual work happens after the Markov chain, in connecting state probabilities to financial quantities that matter to the business.