Why You're probably calculating your sample size wrong
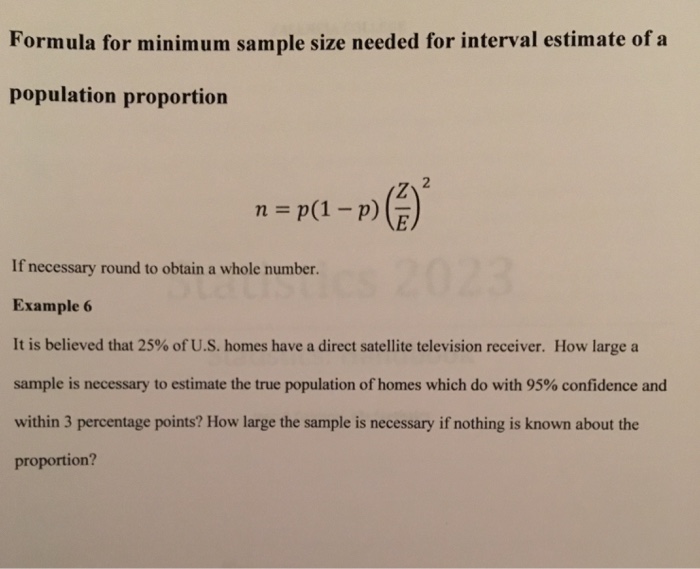
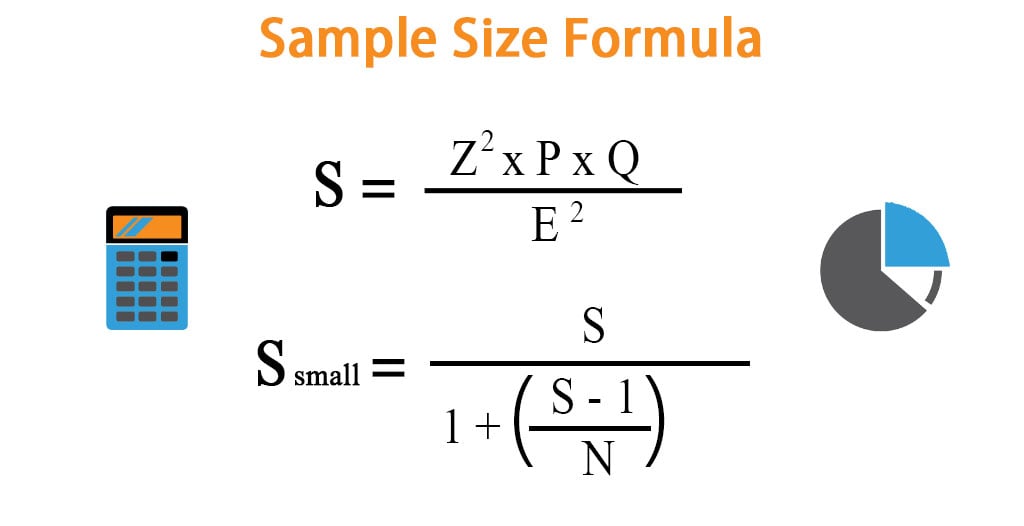
The Minimum Sample Size Formula is N = (Z² × p × (1-p)) / E², where Z is your z-score for the confidence level, p is the estimated proportion, and E is your margin of error. That's the textbook version you'll find in introductory stats courses. It works for big populations when you're estimating a single proportion. That's it. Most people stop there and wonder why their study looks nothing like their power calculations. I've been doing sample size work for clinical trials and market research for a while now, and the thing nobody tells you is that the textbook formula above assumes a normal approximation that breaks down fast when your proportions are near zero or one, or when your sample drops below a few hundred. I learned that the hard way on a clinical trial where I was estimating a rare adverse event rate around 2%. I plugged the numbers into the standard formula, got a sample size of roughly 600, and went with it. When the trial actually ran, the confidence interval was so wide it was essentially useless. The normal approximation had completely failed because the expected count of events was under 10. What I should have used was the exact binomial method, or at minimum a Wilson score interval approach. I ended up recalculating everything and increasing the sample to over 2,000 participants just to get a tight enough interval. It cost the study another four months of recruitment. So here's what I actually do now before I touch any formula. First, I clarify what parameter I'm actually trying to estimate. A mean? A proportion? A difference between groups? A correlation coefficient? Each one has its own calculation, and mixing them up is the most common mistake I see. For means, the formula shifts to N = (Z² × ²) / E², where is your population standard deviation. That's a different ballgame entirely, and now you need a decent estimate of variance, which usually comes from pilot data or published literature. If you don't have either of those, your sample size estimate is just a guess dressed up in math clothing.
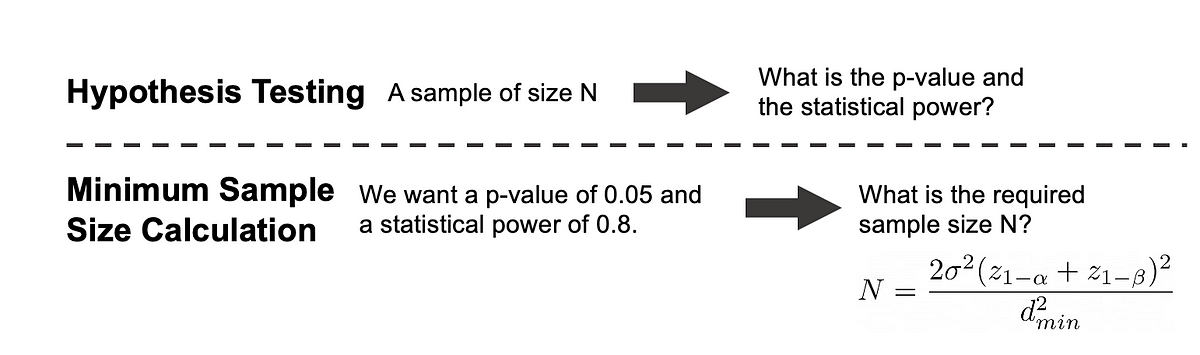
For comparing two proportions, you need the formula N per group = (Z/2 + Z)² × [p(1-p) + p(1-p)] / (p - p)². The addition of the power term Z is what separates a confidence interval calculation from a proper hypothesis test sample size. Beginners skip the power component all the time and produce studies that are guaranteed to be underpowered. An 80% power study with a small effect size can easily require thousands of subjects. A 90% power study on the same effect doubles that again. The difference between 80% and 95% power isn't trivial—it's often the difference between detecting an effect and publishing a null result that someone else will later debunk with a larger study.
The practical stuff they don't put in textbooks
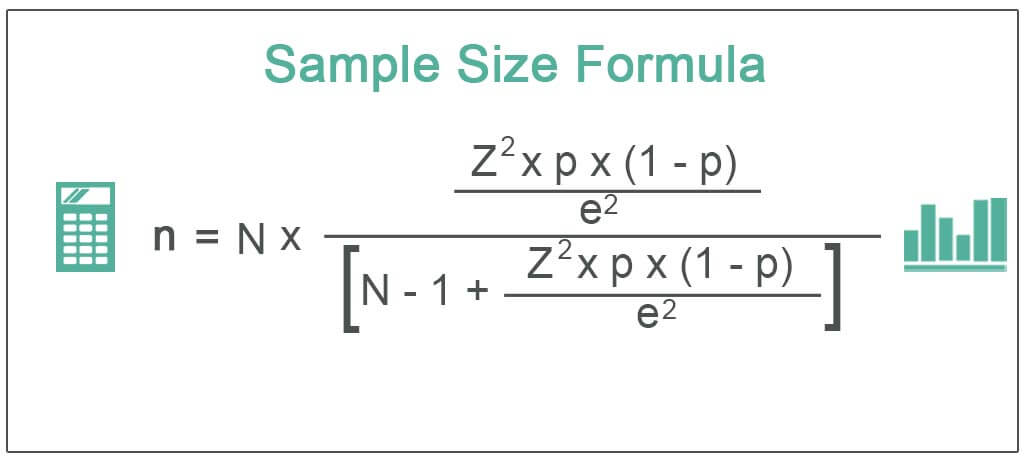
Let me walk through a realistic example from my recent work. I needed to estimate the prevalence of a behavior in a population where I had no prior estimate for p. The standard advice is to use p = 0.5, which maximizes the sample size and gives you the most conservative estimate. With a 95% confidence level (Z = 1.96) and a 5% margin of error, that gives you N = (1.96² × 0.5 × 0.5) / 0.05² = 384.16, rounded up to 385. Clean number. Easy. But then I had to account for design effects. My sampling wasn't simple random—the cluster sampling design inflated the variance by a factor of about 1.5. So I multiplied 385 by 1.5 and got 578. Then I factored in an expected 20% non-response rate by dividing by 0.8, landing at 723. Round up to 750 to be safe. That's the real sample size you need, not the 385 you'd get from the basic formula. Here's another counter-intuitive thing: sample size doesn't scale linearly with precision. Dropping your margin of error from 5% to 3% doesn't require 5/3 times more subjects. It requires (5/3)² = 2.78 times more. Going from 5% to 2% margin of error multiplies your sample size by 6.25. I've seen researchers request budgets for 3,000 subjects when their power calculation actually showed they needed closer to 12,000 because they wanted a 2% margin of error on a proportion estimate. The math doesn't lie, and it doesn't care about your timeline. Finite population correction is another thing people forget. If your total population is under 10,000 and you're sampling more than 5% of it, you need to apply the correction factor ((N-pop - n)/(N-pop - 1)). This shrinks your required sample size significantly. I had a project where the target population was 2,000 clinic patients. The basic formula said I needed about 370 subjects. After applying the finite population correction, the requirement dropped to roughly 160. That's a massive difference in effort and cost, and the formula is straightforward to apply once you remember it exists.
Get the Full Details

When the formula fails you
The Minimum Sample Size Formula assumes random sampling, independent observations, and known or well-estimated parameters. Violate any of those and the output is garbage. Cluster randomized trials, longitudinal studies, and complex survey designs all require specialized calculations. Software like G*Power, PASS, or R packages like pwr and WebPower handle many of these cases, but you still need to understand what you're telling the software to compute. Feeding the wrong effect size into G*Power is the fastest way to get a sample size that's either wildly oversized or dangerously undersized. For multivariate studies or regression models, the rule of thumb is at least 10 to 20 observations per predictor variable. That's a heuristic, not a formula, but it's one I've seen hold up reasonably well across dozens of projects. If you have 15 predictors and follow the lower bound, you need 150 subjects minimum. If you're doing factor analysis, you want a much higher ratio—typically 5 to 10 subjects per item, and some researchers argue for even more. There's no universal formula for exploratory factor analysis sample size because it depends heavily on factor loadings, communality estimates, and the number of factors you're extracting. The rule of thumb is your best friend here. Another area where the standard formula completely falls apart is when dealing with rare events or survival analysis. The log-rank test sample size formula for time-to-event data is N = (Z/2 + Z)² / (p × p × (lnHR)²), where HR is the hazard ratio and p and p are the proportions in each group. But you also need to account for the number of events, not just the number of subjects. If your follow-up is short or your drop-out rate is high, you might recruit 500 people and only observe 50 events, which completely undermines your power. I had a study where the sample size calculation based on events looked adequate on paper, but the actual accrual and follow-up timeline meant we'd never reach the required event count. We ended up extending the study by a year and recruiting from additional sites. The formula didn't account for operational reality.
What I actually recommend
Use the basic Minimum Sample Size Formula as a starting point, not a final answer. Run your numbers through dedicated software when you can. G*Power is free and handles t-tests, ANOVA, chi-square, correlation, and regression sample sizes. For survey sampling with complex designs, use thesampsize package in R. For clinical trials, consider the TrialCalc tool from the University of Cambridge. And always, always do a sensitivity analysis—run your calculation across a range of plausible effect sizes and parameter values to see how much your sample size estimate wobbles. If it wobbles from 200 to 2,000 depending on whether the effect is small or medium, you need to decide whether that uncertainty is acceptable or whether you need better prior data before you start.