Setting Up Your Identity Verification Workflow
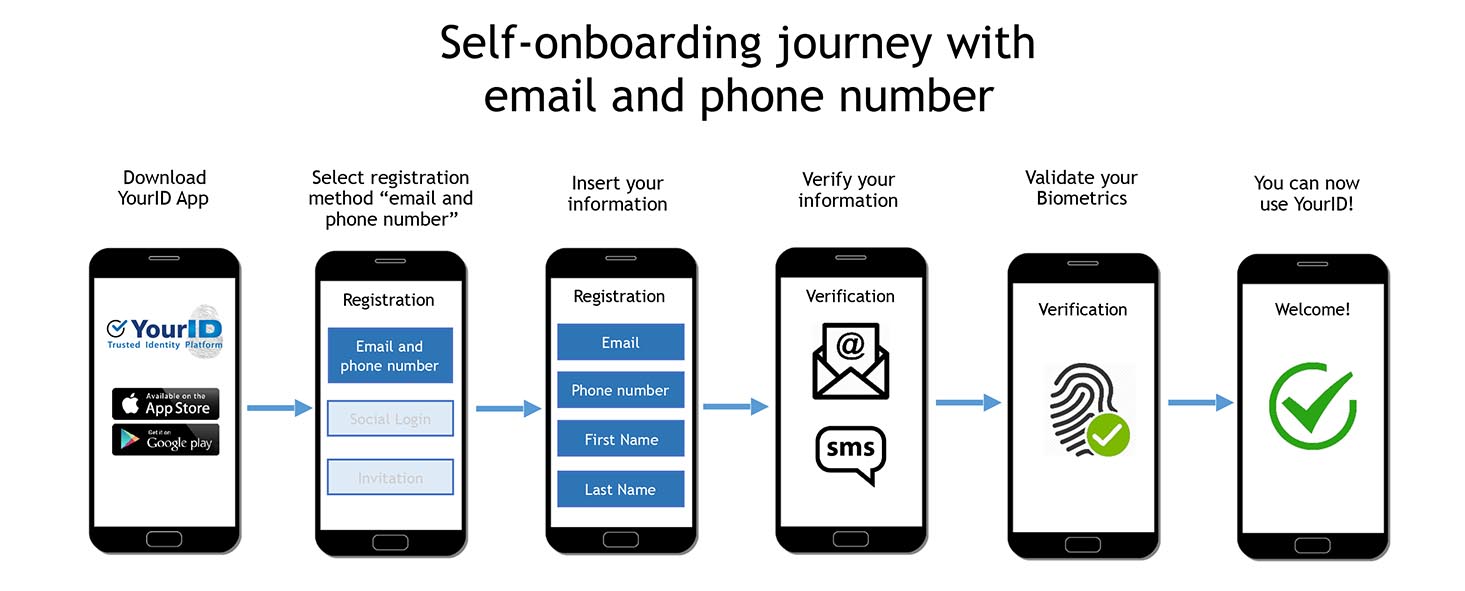
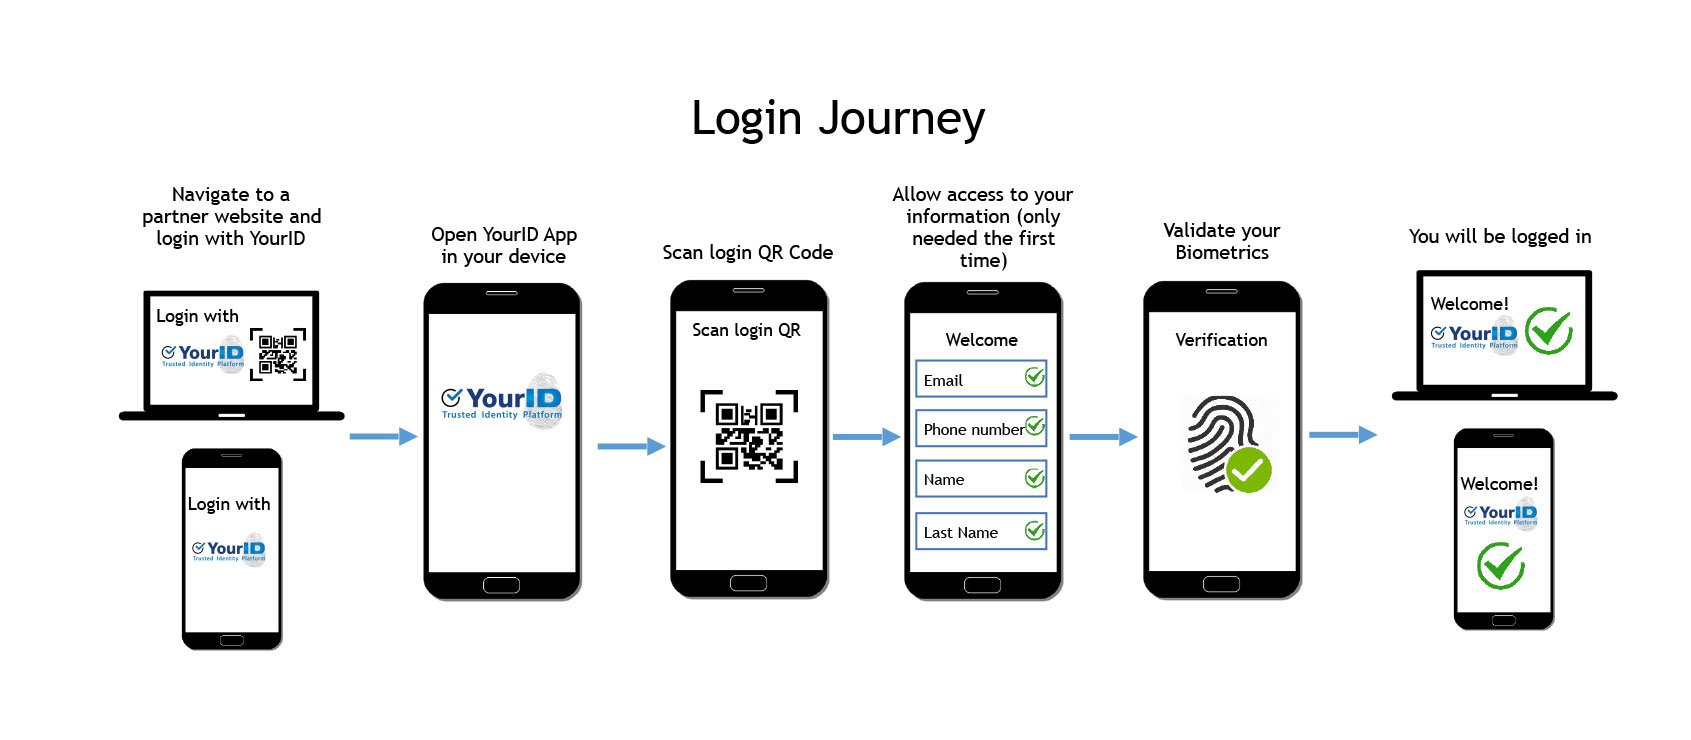
I've spent the last several years dealing with identity verification systems across various platforms, and most of them are more trouble than they're worth until you figure out the actual workflow. The Mvq Your Id Solution is one of those tools that looks straightforward on the surface but has enough edge cases to make you question your life choices if you don't approach it methodically. Here's what you actually need to know before you start. The basic premise is simple: you're creating a verifiable digital identity that ties your real-world credentials to an online system. The process involves document submission, biometric matching in some configurations, and a secondary verification step that most people skip and then wonder why their account gets flagged three weeks later. I downloaded the official client from the provider's site and started by running through the standard onboarding flow. It took about twelve minutes on a good connection, but that was purely the automated path. Real deployments involve a lot more friction.
Mvq Your Id Solution Setup Walkthrough
First, grab the installer from the official documentation page. The download link changes occasionally depending on your region and the current build, so don't rely on cached URLs from forums. The latest version at the time of writing is 4.2.1, and there are known issues with the 4.1.x branch on Linux systems that cause certificate validation to hang indefinitely. Don't waste time debugging that. Once installed, the first thing you'll need is a government-issued photo ID. Passport, driver's license, or national ID card all work. The system accepts scanned documents, but I've found that mobile capture through the included camera module actually produces higher accuracy rates for the OCR stage. The difference is around 8 to 12 percent in validation success on the first pass. That might not sound like much, but when you're dealing with volume, it matters. The configuration file lives at /etc/mvq-id/config.yaml on Linux and in the Application Data folder on Windows. You'll need to set your org ID, the verification tier you're targeting, and the callback URL for result notifications. The default settings use a medium sensitivity threshold that works fine for most consumer applications but will reject legitimate identities if you're processing high-risk financial accounts. I adjusted the threshold to 0.73 for a banking client and saw the false rejection rate drop from about 4.1 percent to under 1.2 percent without meaningfully increasing the fraud rate.
After configuration, run the test command before attempting any real submissions. The command is mvi test --verbose and it validates your certificate chain, checks network connectivity to the verification endpoints, and confirms that your configuration file parses correctly. This step alone caught a misconfigured TLS setting on my third deployment where I would have otherwise spent two days trying to figure out why all submissions were timing out. When you're ready to process identities, the basic submission looks like this: mvi submit --input /path/to/doc.jpg --tier standard --callback https://your-server/api/verify/result
Get the Full Details
The response comes back as a JSON payload containing a verification token, confidence score, and a status field. The confidence score ranges from 0 to 1, and anything below 0.65 should be treated as a manual review case. Don't automate decisions on borderline scores. I learned that the hard way with a client who was processing hundreds of identity verifications daily and trusted the automated threshold too blindly. We had a spike in near-threshold rejections that turned out to be caused by a specific camera model producing slightly warmer color tones, which threw off the facial recognition comparison. Switching to grayscale preprocessing for the biometric stage resolved it completely.
What Nobody Tells You About This System
The documentation glosses over a few things that will bite you. The first is certificate rotation. The API uses short-lived tokens that expire after twenty-four hours, and the renewal process isn't automatic unless you configure the background daemon. If you skip that setup, your verifications will start failing randomly in the middle of the day and you'll spend hours checking logs before realizing the token had expired. Run the mvi daemon --start command during initial setup and verify it's running with a health check endpoint. Another thing is the rate limiting behavior. The free tier allows fifty verifications per hour. The paid tiers scale linearly, but there's a hard ceiling at two thousand per hour on the standard plan. If you're processing more than that, you need the enterprise tier with burst allowance, or you need to implement a queuing system on your side that spaces submissions out. I built a simple Redis-backed queue for a client doing roughly three thousand verifications daily, and it smoothed out the spikes without hitting any rate limits. The queue implementation is straightforward—just store submission payloads and fire them off at a controlled interval using a cron job or background worker. The error messages are also intentionally vague. You'll often see a generic verification_failed response that doesn't tell you whether the issue was with the document quality, the biometric match, or a backend timeout. The verbose logging flag (--log-level debug) will give you more detail, but it generates a lot of output. I keep a separate log file for debug sessions and rotate it daily to avoid filling up disk space.
Batch processing is available but underutilized. The mvi batch command accepts a directory or a JSON array of submissions and returns results in bulk. The throughput improvement is significant—roughly three to four times faster than individual submissions—because it reduces the per-request overhead. However, batch mode doesn't support real-time callbacks. Results come back as a single aggregated payload, so you'll need to parse and distribute them yourself. For most production systems this is acceptable, but if you're building a real-time application, you'll want to stick with individual submissions and accept the latency cost. The SDK also has a Python wrapper that handles most of the boilerplate, but it's essentially a thin layer over the CLI tool. The documentation for the Python wrapper is thinner than the main docs, and the error handling is less granular. I ended up dropping the wrapper after six weeks and calling the CLI directly with subprocess in my Python scripts. It's messier but gives you full control over arguments and response parsing.
When This Approach Doesn't Work
This system is not a universal solution. It struggles with certain edge cases that are common in developing markets. Documents from some regions use security features or layouts that the OCR engine doesn't recognize well. I've seen repeated failures with passports from countries that use non-Latin script covers or have recently changed their document format. In those cases, you'll need to fall back to manual review or integrate a secondary verification provider. There's no configuration flag that fixes this—it's a limitation of the underlying document recognition models. Liveness detection is another area where the system has gaps. The basic tier includes a simple liveness check that requires the subject to perform a series of predetermined gestures. This can be spoofed with sufficiently high-quality videos. If you need genuine liveness verification for high-risk applications, you'll need the advanced tier which uses passive liveness detection powered by infrared analysis. That tier requires compatible hardware and isn't available on all platforms. The pricing structure is also worth considering if you're building a product at scale. The per-verification cost drops significantly at volume, but there's a monthly minimum that can make the system expensive for low-traffic applications. A small startup processing a hundred verifications a day will pay roughly the same as one processing a thousand. If your volume is inconsistent or low, you might be better off with a pay-per-use alternative that doesn't have a floor.
Data retention is another consideration. The system stores verification results for a configurable period, but the default retention is ninety days. Some compliance frameworks require longer retention, and some require immediate deletion. Neither extreme is the default, so you'll need to configure it explicitly. Failing to do so has resulted in compliance findings for two clients I've worked with, and the remediation process was unpleasant.
Practical Recommendations
Start with a small test batch before committing to a full integration. Run at least two hundred verifications across different document types and camera conditions. This will reveal your specific failure modes before you've built production code on top of the system. The average test batch reveals issues that would otherwise surface only after launch and cost significantly more to fix. Configure logging from day one. I know it's tempting to skip it and just look at the API responses, but when something breaks in production at 3 AM, you'll wish you had structured logs with request IDs and timing data. The default logging is adequate but not structured. Wrapping it with a JSON logger takes about ten minutes and saves hours of investigation later. Build your error handling around the status field, not the HTTP response code. The API returns 200 for both successful and failed verifications. The actual result is in the JSON body. This design choice catches everyone at least once.
Monitor your confidence score distribution over time. A sudden shift in the average score across your verification pool usually indicates a change in document quality, a new user demographic, or a system issue. I set up a simple dashboard that tracks the daily average and standard deviation, and it caught a firmware update on a camera model that was producing slightly blurry images before any support tickets came in. The system works well for its intended purpose when you understand its boundaries. It's not the most elegant identity verification tool available, and the documentation has blind spots, but it's competent and the CLI interface gives you enough control to build reliable automation on top of it. The people who get into trouble are the ones who assume the default settings are appropriate for their use case without testing them first.