The System That Actually Works
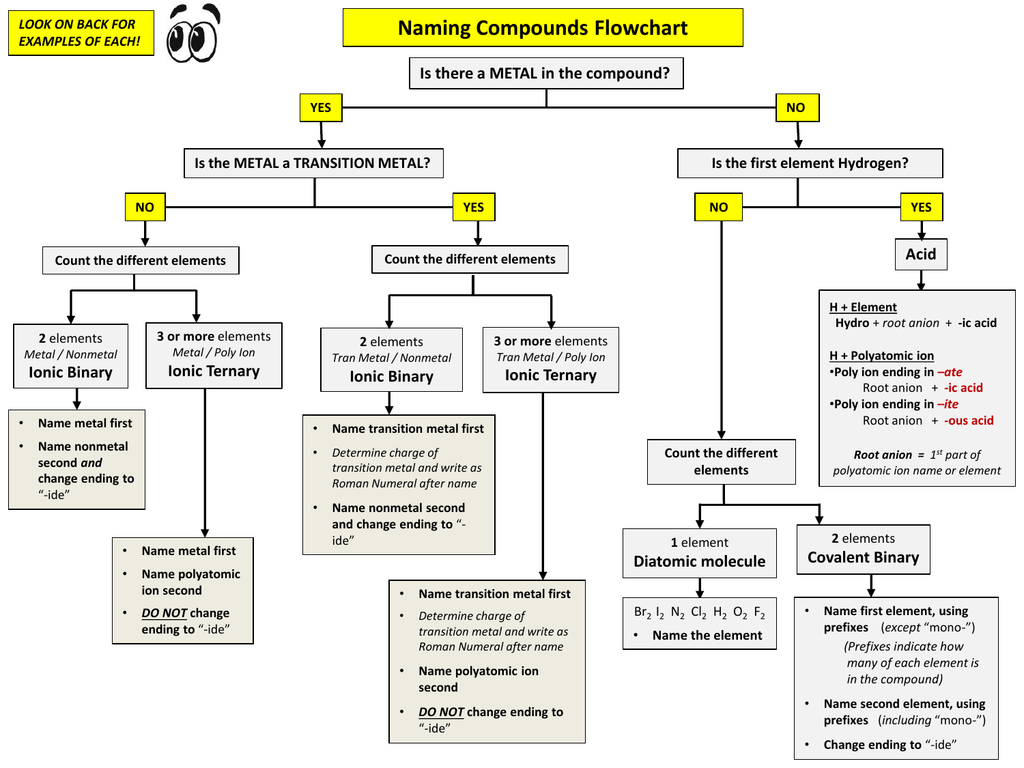
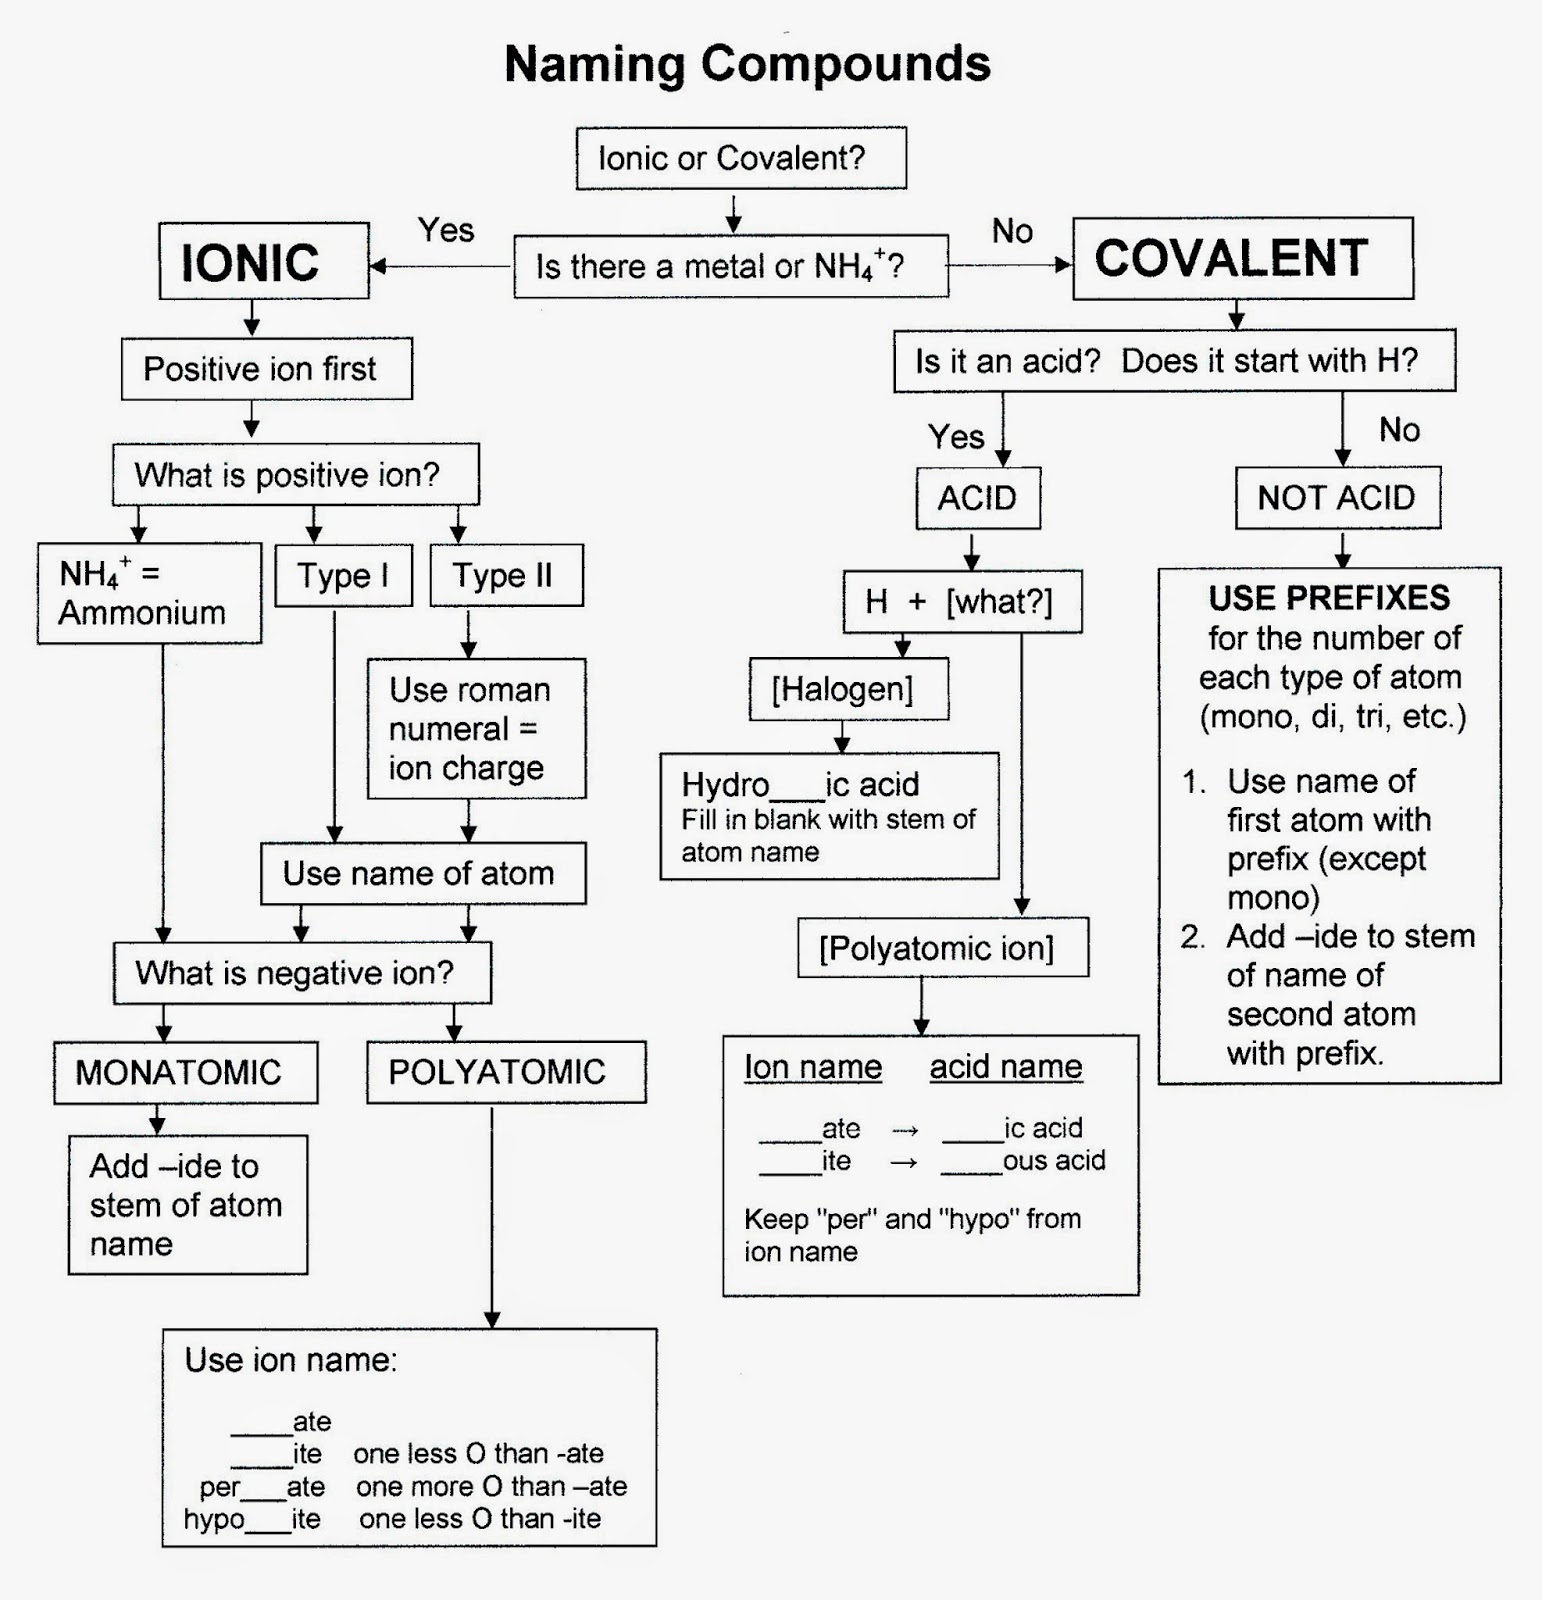
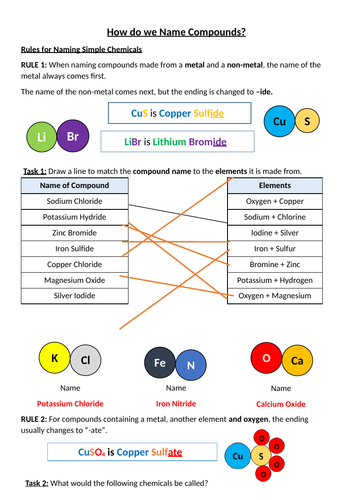
Naming A Chemical Compound sounds like it should be straightforward because IUPAC made it systematic, but it isn't. The rules are arbitrary in ways that trip people up constantly. I spent years fixing naming errors on lab reports and regulatory filings before I stopped second-guessing myself. The basics are easy enough, but the places where the system gets fuzzy are where real mistakes happen. Most beginners learn the simple ionic names—sodium chloride, calcium carbonate—and think they understand the whole system. Then they hit an organic molecule with multiple functional groups and everything falls apart. Here is what actually happens when you sit down to name something that isn't in a textbook example. The first rule you need to internalize is that functional groups have a priority order. It is not negotiable. Carboxylic acids beat esters, esters beat amides, amides beat nitriles, and so on. The highest priority group determines the suffix of the name. Everything else becomes a prefix. I once spent three hours tracking down why a compound I was naming came out wrong, and it turned out I had treated an amide as the principal group instead of the carboxylic acid sitting on the same carbon chain. The name was technically valid under an incorrect interpretation, which is worse than being obviously wrong because nobody catches it immediately.
The workaround is to write out the priority table every single time until it is memorized. Not from memory, from the official IUPAC document. There are PDFs of the Blue Book online. Print one. Keep it on your desk. I did this for about six months and never had to look it up again.
How The Naming Process Actually Works
Start by identifying the longest continuous carbon chain that contains the highest-priority functional group. This is different from what you might instinctively do. You might grab the longest chain in the molecule regardless of where the functional group sits. That is incorrect. The principal chain must include the carbon bearing the highest-priority group, even if a longer chain exists elsewhere in the structure. Once you have the principal chain, number it so that the principal functional group gets the lowest possible locant. If there is a tie, you move to the next priority consideration: the set of substituents gets the lowest numbers collectively. This is where people make errors. It is not about giving any single substituent a low number. It is about the entire set of locants being as low as possible when read in ascending order. Compare 2,3,5-trimethyl against 2,4,5-trimethyl. The first set is lower because at the first point of difference, three is less than four. After numbering, identify all substituents and list them alphabetically. Prefixes like di, tri, and tetra do not count toward alphabetization. You alphabetize based on the actual substituent name—methyl, ethyl, chloro, bromo, and so on.iso-propyl is alphabetized under i, not p. That is a common trap.
Get the Full Details
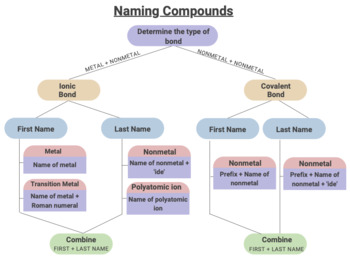
Assemble the name in this order: substituents (alphabetical, with locants and multiplicative prefixes), then the parent chain name, then the suffix from the principal functional group. Add locants for the principal group too, even if it is at position one. In older conventions you could omit the 1, but current IUPAC recommendations say you should include it when there is ambiguity, and including it never hurts while omitting it sometimes does.
A Real Example That Shows The Gaps
Take a molecule with a six-carbon chain, a carboxylic acid at one end, a ketone at carbon three, and a methyl group at carbon five. The carboxylic acid is the highest priority group, so the suffix is -oic acid. The ketone becomes an oxo prefix. The chain is numbered starting from the carboxylic acid carbon, giving you 5-methyl-3-oxohexanoic acid. Not hexan-3-one-something. The acid dominates. If you had prioritized the ketone, you would get a completely different and incorrect name. Now consider what happens when you have a carboxylic acid and an alcohol on the same chain. The acid still wins. The alcohol becomes hydroxy. Five-hydroxypentanoic acid, not pentanol-something. This comes up constantly in biochemistry and medicinal chemistry contexts because molecules often have multiple oxygen-containing groups.
Edge Cases That Break The System
Ring systems complicate things significantly. When a substituent is attached to a ring and the ring itself carries the principal functional group, you name the ring as the parent and the chain as a substituent. But if the chain is longer and carries the principal group, the chain becomes the parent and the ring is a substituent. I ran into this with a cyclohexylacetic acid derivative where the acetic acid chain was shorter than the ring but held the carboxylic acid. The correct name treated the acetic acid chain as the parent despite the ring being larger. Size of the carbon skeleton does not determine the parent. The functional group does. Stereochemistry is another area where naming gets messy. You need R/S designations for chiral centers and E/Z for double bonds. These go in parentheses at the front of the name. A full name for a compound with stereochemistry can look ridiculous, like (2R,3S)-2-bromo-3-chloropentanoic acid. That is fine. That is how it works. Omitting stereochemistry when it is known is a data quality issue, not a convenience issue. Regulatory submissions will reject names without it. Heterocycles add another layer. When the principal functional group is attached to a heterocyclic ring, the ring system often becomes the parent. But if the chain with the functional group is more complex, the chain can be the parent. There is no simple rule that covers every case, and the 2013 IUPAC recommendations shifted some of this in ways that confused a lot of people who learned the older system. I had a colleague spend a week relearning the heterocycle priority rules after a revision, and he is not someone who misses details.

What The System Cannot Handle Well
Bridged polycyclic systems, spiro compounds, and certain organometallic structures do not map cleanly onto standard IUPAC naming conventions. For these, you end up using complex ring fusion nomenclature that requires knowing nomenclature rules within nomenclature rules. The system starts to look less like a logical framework and more like a collection of historically accumulated workarounds. This is not a criticism of IUPAC. It is a description of what happens when you try to name every possible molecular topology with a single consistent system. Another limitation is that IUPAC names can be extremely long for complex natural products. A single steroid or macrocyclic lactone name can be thirty or forty words long. Nobody says these out loud in conversation. Researchers use trivial names or abbreviated codes in practice. The IUPAC name exists for unambiguous reference, not for daily communication. This is worth knowing if you are preparing documentation, because you do not want to write a thirty-word name into a field that has a character limit.
A Practical Checklist
Before you finish a name, run through this sequence. Identify the principal functional group and its priority position. Confirm the parent chain includes that group. Number the chain correctly. Assign locants to all substituents. Check the lowest-set rule for substituent locants. Alphabetize substituents correctly, ignoring multiplicative prefixes. Add stereochemistry descriptors. Verify the name against the structure one more time. This takes about two minutes for a typical organic molecule and saves you from the kind of error that shows up during peer review or regulatory audit. I used to skip the final verification step because I was confident in my process. I learned differently when a reviewer flagged a methyl group at position four as being misnumbered. The chain was correct, the substituents were correct, but I had numbered from the wrong end. The error would have been invisible to anyone who did not draw out the full structure and renumber it themselves. Taking two minutes to verify caught that. Not taking two minutes cost me credibility with a client who now double-checks every name I produce.
Resources That Are Actually Useful
The IUPAC Blue Book is the primary source, but it is dense and not organized for quick lookups. The Nomenclature of Organic Chemistry section is the relevant part for most chemists. For inorganic compounds, the Red Book covers the rules. Both are available free from the IUPAC website. The CAS nomenclature system is another reference point, particularly if you work with regulatory agencies that require CAS-style names alongside IUPAC names. They are not always identical, and that discrepancy causes problems in database management. Online tools exist, but they are not reliable for complex molecules. Automated name generators handle straightforward cases reasonably well, but they make systematic errors with stereochemistry, ring systems, and priority conflicts. I have seen tools produce names that are grammatically correct IUPAC-style strings but chemically wrong. Always verify machine-generated names against the structure, especially for anything going into a formal document. The chemical drawing software you use likely has a naming module. ChemDraw, MarvinSketch, and similar programs generate IUPAC names automatically. These are generally more reliable than standalone web tools because they parse the structure correctly first. But they are not perfect. I have caught errors in ChemDraw output on molecules with fused rings and stereocenters. Use the software as a starting point, not a final answer.