Working With Nucleic Acids: A Practical Guide
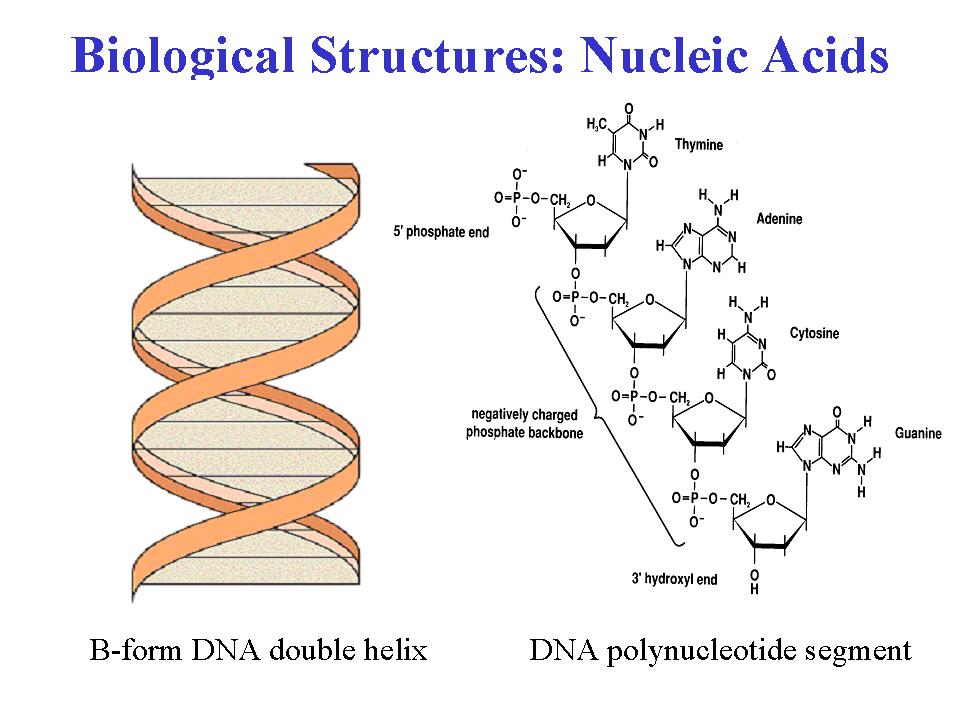
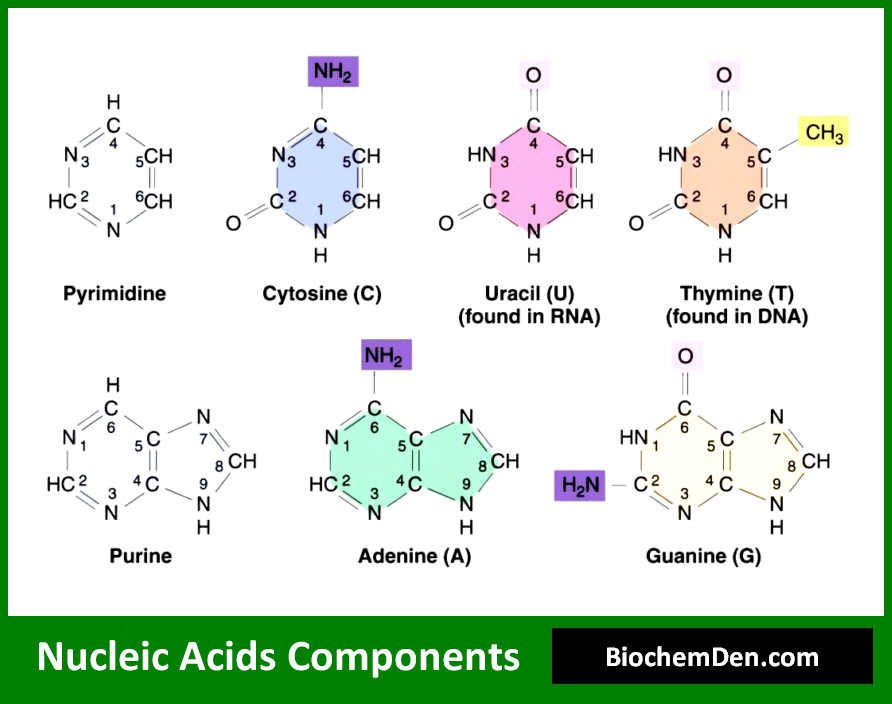
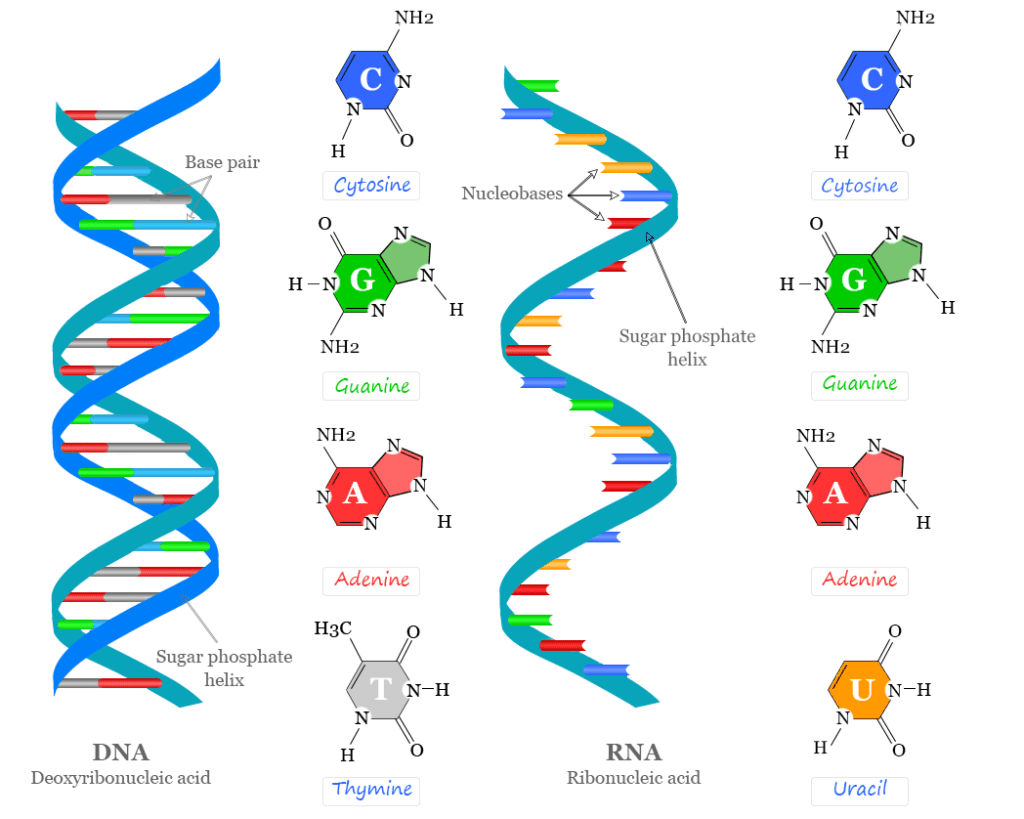
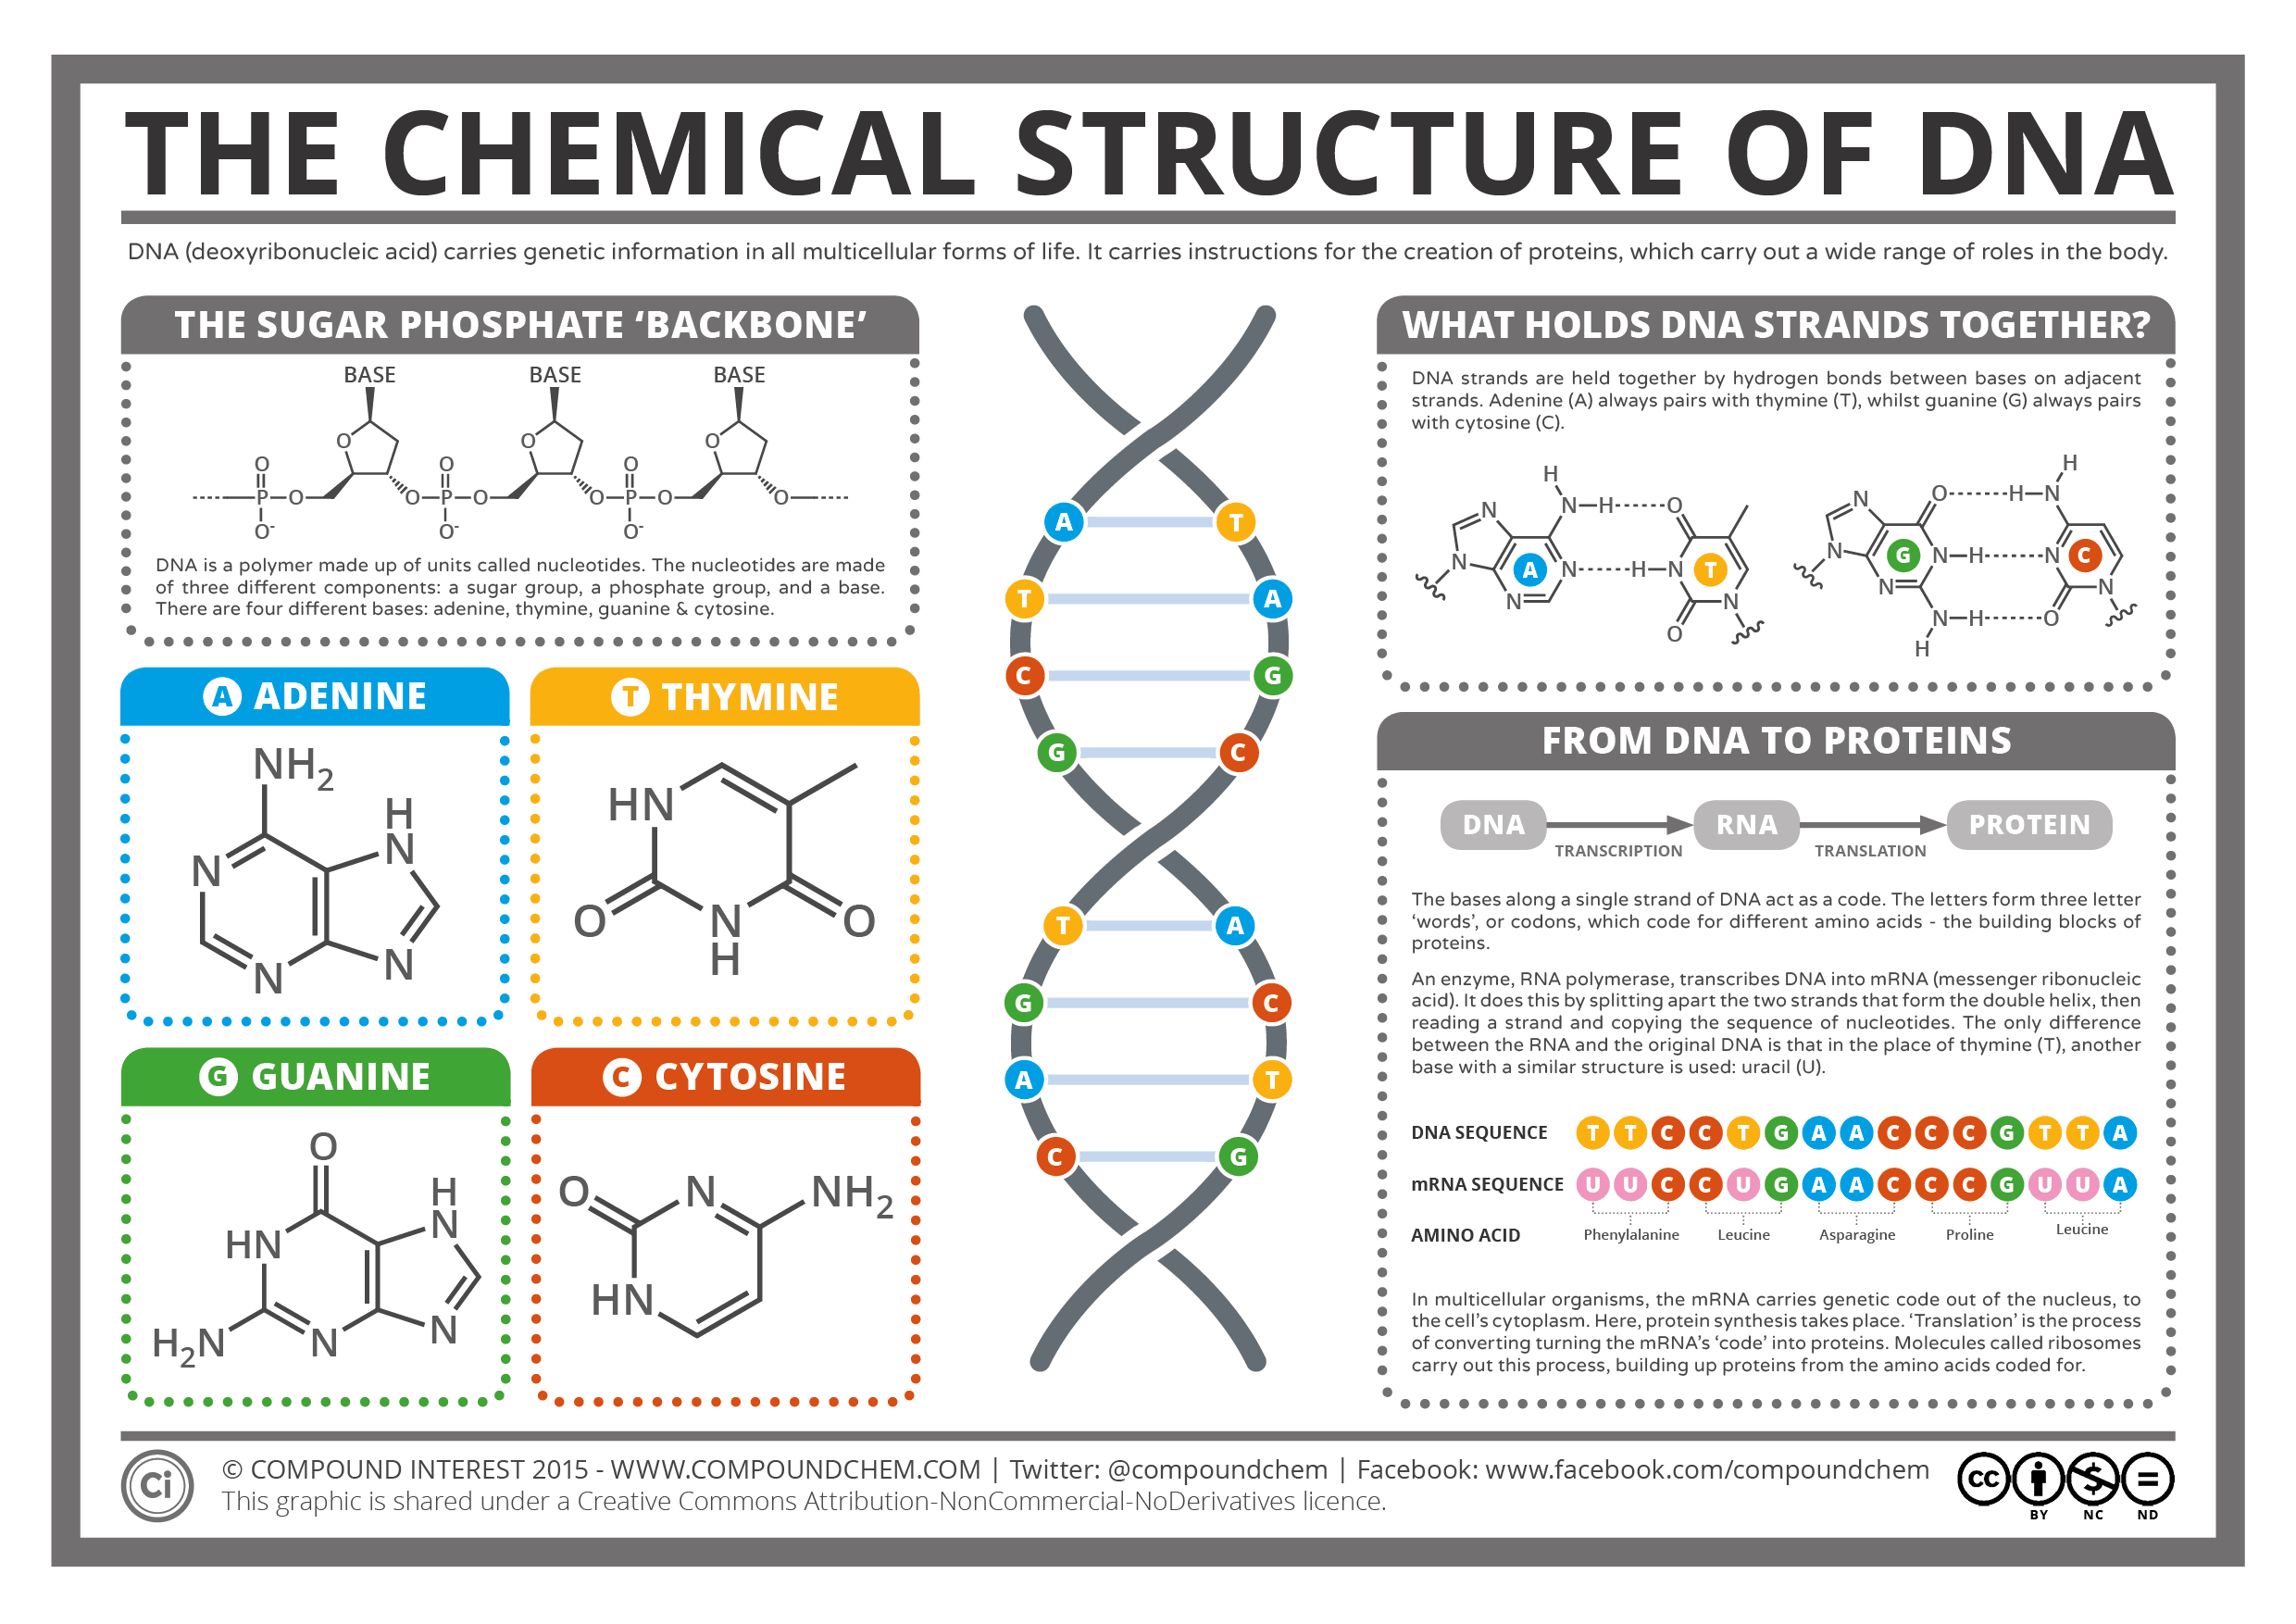
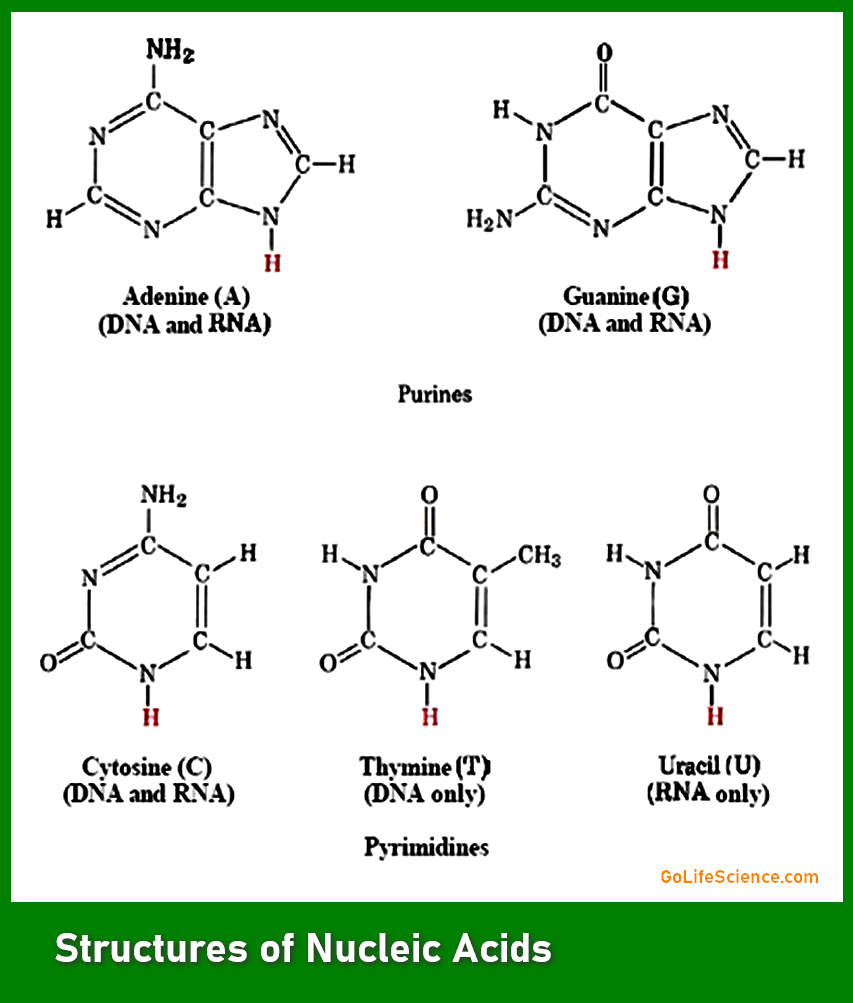
Nucleic acids are polymers made of nucleotides, each consisting of a phosphate group, a pentose sugar, and a nitrogenous base. Adenine, guanine, cytosine, thymine, and uracil are the five standard bases. DNA uses deoxyribose; RNA uses ribose. That's the textbook version. The practical version is messier. I've spent years working with these molecules in both academic and industrial settings. You quickly learn that textbook biochemistry rarely survives contact with a real lab bench. Buffers degrade. Contaminants show up where they shouldn't. Enzymes misbehave. I'm going to walk through what you actually need to know, not just what's in a textbook.
Nucleic Acids In Chemistry And Biology
Let me start with extraction because that's where everything begins. The standard phenol-chloroform method is reliable but brutal. I switched to column-based silica kits for routine work, but I learned the hard way that they have real limitations. One time, I was extracting RNA from a tissue sample rich in polysaccharides. The columns clogged immediately, and the yields were garbage. I ended up going back to a cesium chloride gradient purification. It took two days instead of thirty minutes, but the RNA was clean enough for downstream applications. If your sample has high polysaccharide or lipid content, don't bother with standard columns. Go straight to a method designed for problematic tissues, or use a CTAB-based protocol. The chemistry behind extraction is straightforward. Detergents lyse cells. Proteases digest proteins. RNases or DNases are either inhibited or inactivated. The nucleic acids are then separated based on solubility or binding properties. What's not straightforward is the edge cases. RNases are everywhere. They survive boiling. They stick to glass. They come off your skin. If you're working with RNA, you need DEPC-treated water, filtered tips, and gloves that you change frequently. Burn a tube of RNA and you'll carry that frustration with you for a while.
Common Applications and How They Actually Work
PCR is the most common application, but it's also the one people misunderstand the most. The idea is simple: denature, anneal, extend. Cycle. But the reality involves primer design, magnesium optimization, and dealing with secondary structures. Here's something most beginner protocols don't tell you. The annealing temperature matters, but the extension temperature is equally important. Taq polymerase works best at 72 degrees Celsius. If your cycle program spends significant time at lower temperatures during denaturation or annealing steps, nonspecific amplification increases dramatically. I've seen whole runs ruined because someone used a 68-degree extension instead of 72. Quantification is another area where things go wrong routinely. Spectrophotometry at 260 nanometers gives you concentration, but it doesn't tell you about purity. The 260-over-280 ratio is supposed to be around 1.8 for pure DNA and 2.0 for pure RNA. Those numbers assume you're working with clean samples. If your protein contamination is high, the ratio will be off, but the actual nucleic acid concentration might still be accurate enough for some applications. I learned this the hard way when I had a sample with a 260-over-280 of 1.4 that still worked perfectly fine in a PCR reaction. Absorbance ratios are a screening tool, not a verdict. For RNA quantification, fluorescence-based methods like Qubit are significantly more accurate than spectrophotometry, especially for low-concentration samples. The difference matters when you're doing RNA-seq and need precise input amounts. I've seen people run libraries with wildly varying RNA inputs because they relied on Nanodrop readings, and the resulting data quality was all over the place. Fluorescence-based quantification costs more per sample but saves far more in downstream troubleshooting.
Get the Full Details
Sequencing and Analysis Workflow
Next-generation sequencing starts with fragmenting nucleic acids. Sonication, enzymatic fragmentation, or nebulization are the common methods. Each has trade-offs. Sonication is efficient but generates heat that can damage RNA. Enzymatic fragmentation is gentler but introduces sequence bias. Nebulization is fast but hard to control precisely. For RNA-seq, I recommend enzymatic fragmentation with divalent cations at elevated temperature. It's reproducible and preserves RNA integrity better than physical shearing. Library preparation is where most errors accumulate. Adapter ligation efficiency varies depending on the concentration and purity of your input material. I once ran a batch of libraries where roughly 30 percent of the samples failed entirely. The issue traced back to a batch of adapters that had been reconstituted too many times. Each freeze-thaw cycle degrades the adapters. I now aliquot everything on first use and never refreeze. It's a small habit that prevents major headaches. Data analysis is a separate can of worms. Alignment algorithms like BWA for DNA and STAR for RNA handle most standard cases. But if you're working with non-model organisms or highly repetitive regions, alignment rates drop significantly. A common workaround is to use a reference genome from a closely related species, but that introduces its own biases. I've found that using multiple aligners and cross-referencing the results catches a lot of misalignment errors that no single tool would catch alone.
Storage and Stability Considerations
Storage seems simple until it isn't. DNA is relatively stable at minus 20 degrees Celsius for routine work, but long-term storage requires minus 80 degrees. RNA is far less forgiving. Even at minus 80, RNA degrades over time. I keep RNA aliquots at minus 80 and never thaw the main stock. Each freeze-thaw cycle degrades maybe 5 to 10 percent of the RNA depending on concentration and buffer conditions. After three or four cycles, you're working with significantly degraded material and wondering why your results look inconsistent. One thing worth noting about storage buffers. TE buffer, which contains EDTA, chelates magnesium and inhibits downstream enzymatic reactions. If you're storing nucleic acids that will go through PCR or reverse transcription, TE is fine for storage but needs to be diluted or exchanged before use. I use nuclease-free water for short-term storage when the samples will be used within weeks. For long-term storage, TE is still the standard, but plan for a dilution or cleanup step before enzymatic work.
Quality Control That Actually Matters
Agarose gel electrophoresis is the basic QC method everyone learns. You run a gel and look for intact bands. But gels are qualitative at best. For rigorous work, you need more information. Bioanalyzer or TapeStation traces give you electropherograms with concentration, fragment size distribution, and degradation metrics. The RNA Integrity Number or RIN is the standard metric. Samples with a RIN below 7 are generally considered degraded and unsuitable for most downstream applications, though some protocols tolerate lower quality. I should mention a practical issue here. Bioanalyzer chips are expensive, roughly 200 dollars per chip, and the runs consume consumables that add up quickly. If you're processing dozens of samples routinely, the cost is significant. A good alternative is agarose gel electrophoresis combined with fluorometric quantification. It's cheaper and gives you enough information for most standard applications. You only need the Bioanalyzer when you're doing something sensitive like single-cell RNA-seq or when your samples are of unknown quality.
A Note on Contamination
Contamination is the silent killer of nucleic acid work. Amplified DNA is extremely stable and extremely easy to spread. A single drop from a previous PCR run can contaminate an entire experiment. I've seen labs deal with this issue repeatedly because they don't dedicate separate areas for pre- and post-PCR work. The solution is spatial separation, not just good technique. Pre-PCR areas for setup and post-PCR areas for analysis should be physically isolated. UV irradiation of workspaces helps, but it doesn't eliminate contamination. It reduces surface DNA, which is different from eliminating it. For RNA work, the contamination concern is different. Environmental RNases are the problem, not carried-over RNA.RNase contamination from previous experiments is rare because RNA degrades quickly outside of protective conditions. But RNases from your hands, from dust, from reagents that weren't properly treated, those are constant threats. I treat every reagent that contacts RNA with care, use dedicated pipettes and tubes, and change gloves frequently. It's tedious, but skipping any of these steps usually costs more in the long run.
When Things Go Wrong
Here's a specific scenario I dealt with recently. I was preparing genomic DNA from plant tissue with high polyphenol content. The standard extraction protocol produced DNA that looked fine on a gel but failed in restriction digest reactions. The polyphenols were co-precipitating with the DNA and inhibiting the enzymes. The fix was adding PVPP, polyvinylpolypyrrolidone, to the lysis buffer. It binds polyphenols and keeps them out of the final prep. I wish I'd known that earlier. It cost maybe five dollars in extra reagent and saved me days of troubleshooting. Another common failure mode is incomplete reverse transcription in RNA-to-cDNA workflows. This happens frequently when RNA has secondary structure that the reverse transcriptase can't bypass. Using a higher reaction temperature, around 50 to 55 degrees Celsius, helps denature secondary structures. Also, random hexamers plus oligo-dT priming gives better coverage than either primer type alone. I use a mix of both in my standard protocols, and the cDNA quality improves noticeably. There's no universal solution for every problem you'll encounter with nucleic acids. The molecules behave differently depending on source, buffer composition, salt concentration, temperature, and a dozen other variables. The best approach is understanding the underlying chemistry and being willing to adjust protocols rather than blindly following them. Most published methods are starting points, not final answers. The people who do this well are the ones who understand why each step exists and what happens when it goes wrong.