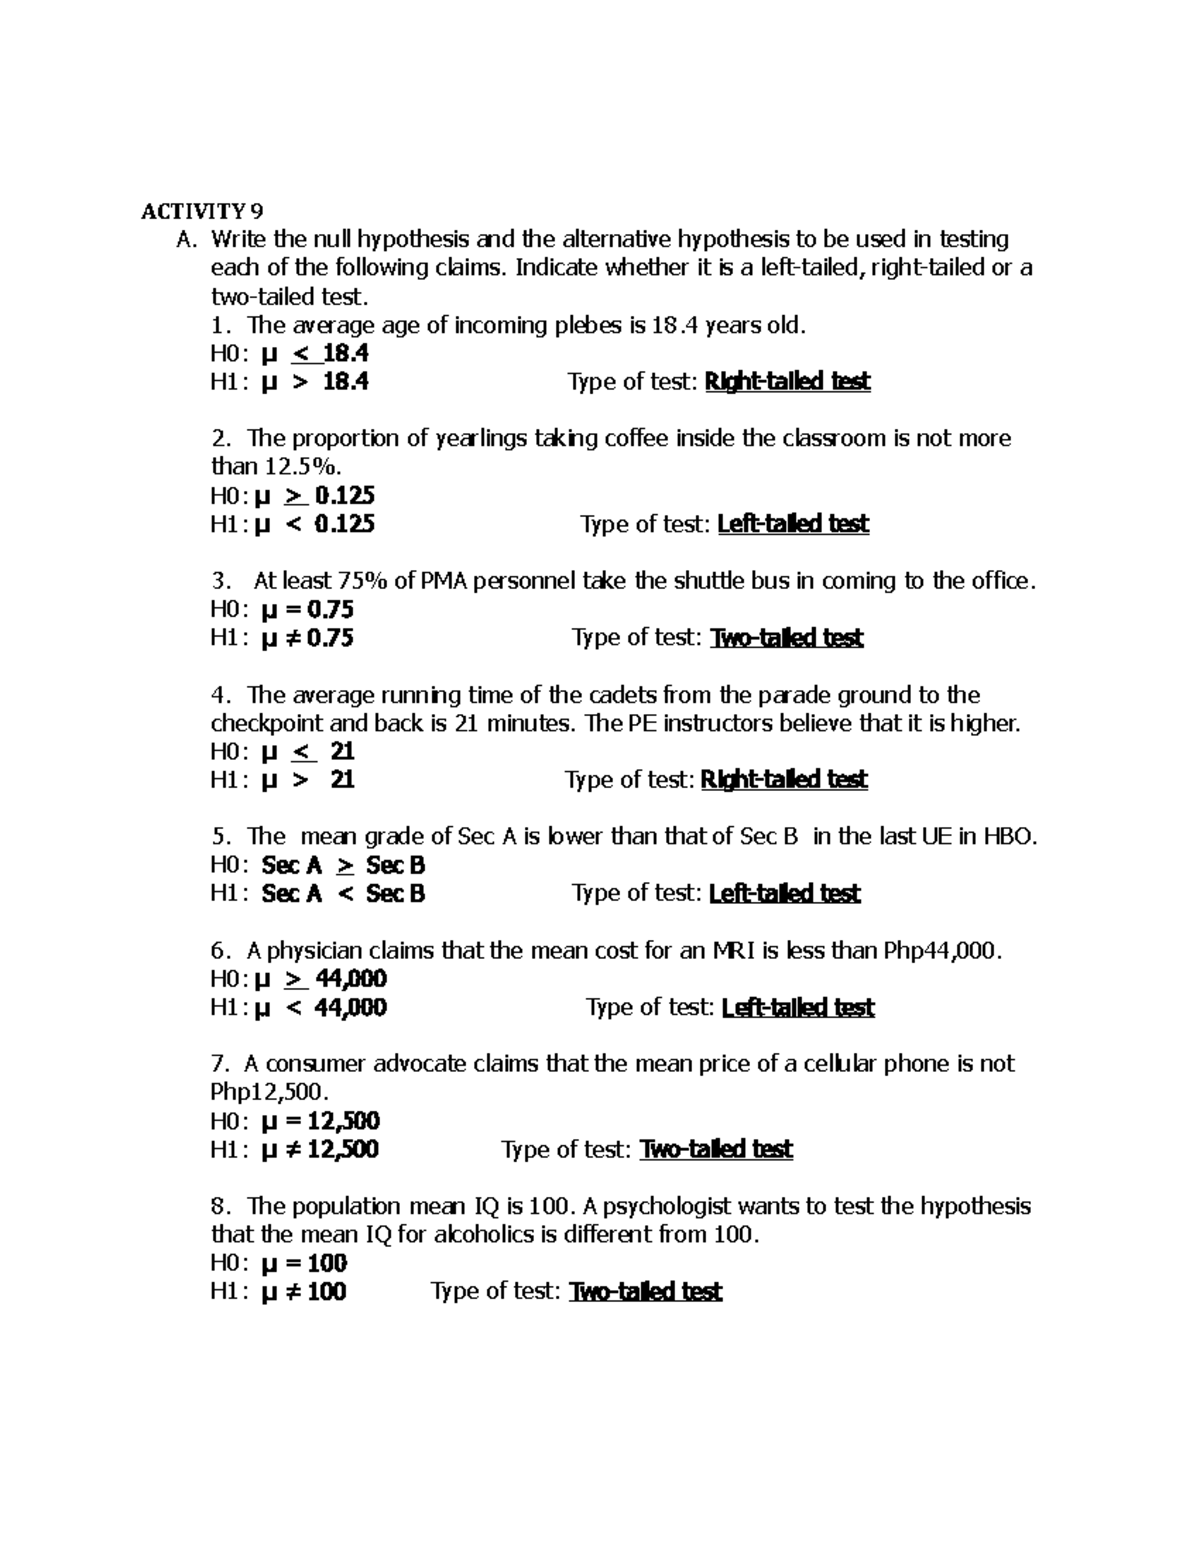
Working Through Null Hypothesis Practice Problems
Most people stumble on the same mistakes when they start doing hypothesis testing. They memorize the steps but never actually understand what's happening under the hood. I've been grading these for years and the patterns are always the same. Let me walk you through some actual practice problems so you can see where things usually go wrong. Let's start with a straightforward example. A pharmaceutical company claims their new medication lowers blood pressure by at least 10 points on average. You take a sample of 50 patients and find the average reduction is 8.2 points with a standard deviation of 3.5. Test the claim at the 5% significance level. First, set up your hypotheses. The null hypothesis is the status quo or the claim you're testing against. In this case, the company's claim becomes H: 10. The alternative is H:
10. This is a left-tailed test because we're checking if the effect is less than claimed, not just different. Students regularly mess this up by writing a two-tailed test when the wording clearly indicates directionality. The word "at least" is your signal that the null should contain the equality condition.
Now calculate the test statistic. Since n = 50, you can use a z-test approximation even though the population standard deviation is unknown. The formula is z = (x - ) / (s/n). Plugging in your numbers: z = (8.2 - 10) / (3.5/50) = -1.8 / 0.495 = -3.64. That's a pretty extreme value. The critical value for a one-tailed test at = 0.05 is -1.645. Since -3.64 falls well into the rejection region, you reject the null hypothesis. The data provides strong evidence that the medication's average effect is less than 10 points. Here's where most people get sloppy: they stop at "reject H" and don't actually interpret the result in context. The conclusion isn't just a statistical statement. It's that there is sufficient evidence at the 5% level to conclude the medication's true mean blood pressure reduction is below 10 points. The p-value here is approximately 0.0001, which means if the true mean were actually 10, you'd see a sample result this extreme only about 1 in 10,000 times. Let me give you a slightly more complicated problem that trips up a lot of students. A factory produces metal rods with a target length of 25 cm. Quality control takes random samples of 30 rods and checks if the mean length differs from the target. In your first trial, the sample mean is 25.12 cm with a sample standard deviation of 0.8 cm. Test at the 1% significance level whether the process is off-target.
This is a two-tailed test because any deviation in either direction is problematic. H: = 25 and H: 25. The test statistic is t = (25.12 - 25) / (0.8/30) = 0.12 / 0.146 = 0.822. Using the t-distribution with 29 degrees of freedom, the critical values at /2 = 0.005 are approximately ±2.756. Since 0.822 falls between these bounds, you fail to reject the null. The process doesn't show statistically significant deviation at the 1% level. Notice something important here: failing to reject is not the same as accepting. The process could still be slightly off-target. You just don't have enough evidence to say it is. The confidence interval for this data would be roughly 25.12 ± 0.43, or (24.69, 25.55). The target value of 25 falls inside this interval, which is consistent with the hypothesis test result. These two approaches should always agree, and when they don't, you've made a calculation error. Now let me tell you about a specific edge case that burned me once. I was working with a client who had paired data — before-and-after measurements on the same subjects. Someone on the team ran an independent two-sample t-test instead of a paired t-test. The p-value came out to 0.08, which they considered "not quite significant but worth investigating." When we switched to the correct paired analysis, the p-value dropped to 0.003. The pairing reduced the within-group variability dramatically because each subject served as their own control. The conclusion flipped entirely. Always check whether your data is independent or paired before choosing your test. This mistake costs people real money and wasted research time.
Get the Full Details
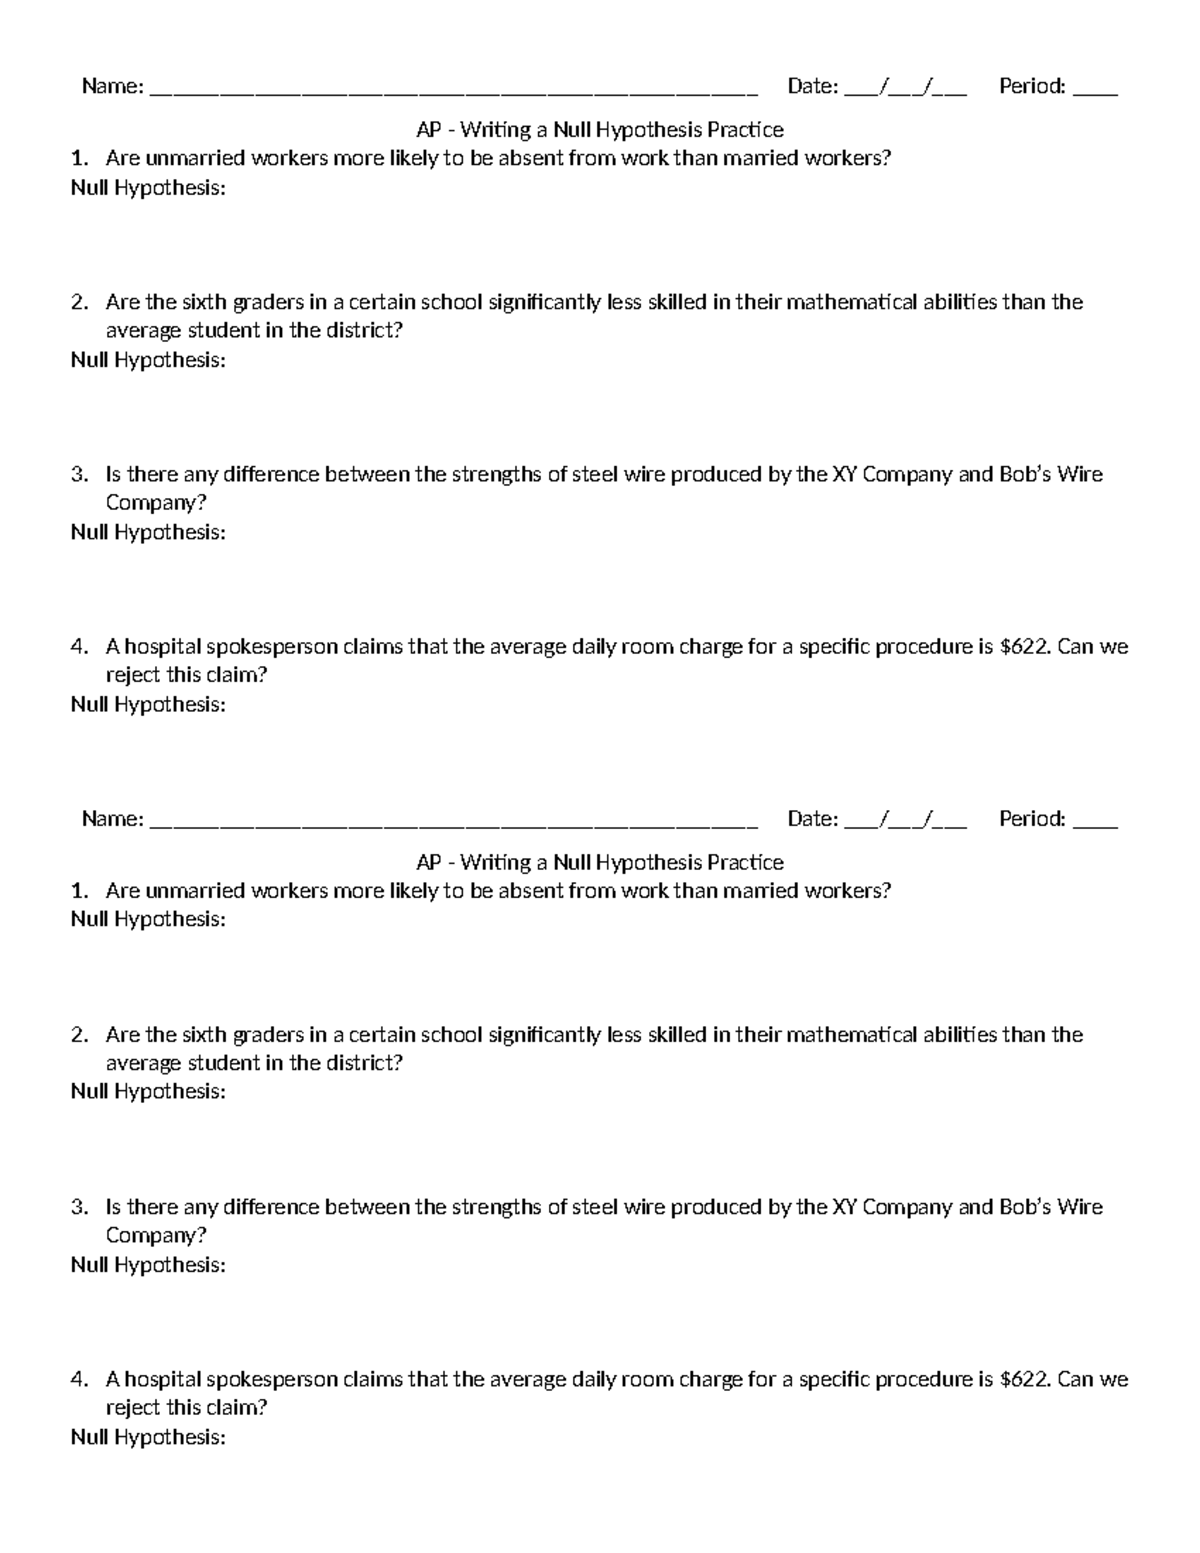
Here's another common problem type that seems simple but has hidden traps. A researcher claims that more than 60% of customers prefer product A over product B. In a survey of 200 customers, 132 said they prefer product A. Test the claim at the 5% level. This is a test about a population proportion. H: p 0.60 and H: p > 0.60. The sample proportion is p = 132/200 = 0.66. Check the success-failure condition: n·p = 200·0.60 = 120 and n·(1-p) = 200·0.40 = 80. Both are above 10, so the normal approximation is valid. The test statistic is z = (p - p) / (p(1-p)/n) = (0.66 - 0.60) / (0.60·0.40/200) = 0.06 / 0.0346 = 1.734. The critical value for a one-tailed test at 5% is 1.645. Since 1.734 exceeds this, you reject the null. There is sufficient evidence to support the claim that more than 60% prefer product A. But here's the nuance beginners miss: this doesn't tell you the true proportion. It only tells you the data is inconsistent with a proportion of 0.60 or lower. A 95% confidence interval for the proportion would be 0.66 ± 1.96·0.034 = (0.593, 0.727). The lower bound barely exceeds 0.60, which explains why the p-value is right around the significance threshold rather than being extremely small. Small effects with moderate sample sizes produce borderline results that are easy to overinterpret.
I should mention the limitations of these approaches. Null hypothesis significance testing has genuine problems that textbooks rarely emphasize. First, the arbitrary 0.05 cutoff encourages binary thinking. A p-value of 0.049 and 0.051 are treated as fundamentally different conclusions when they're essentially the same result. Second, statistical significance is not the same as practical significance. With a large enough sample, even trivially small effects become statistically significant. A study with 10,000 participants might find a statistically significant difference of 0.1 units on a 100-point scale. That's technically real but completely meaningless in practice. Third, p-values don't tell you the probability that the null hypothesis is true. They tell you the probability of observing data this extreme or more extreme if the null were true. This is a subtle but important distinction that even experienced researchers sometimes conflate. If you want to make probability statements about hypotheses themselves, you need Bayesian methods, which operate on a different framework entirely. When these tests fail, they usually fail because of violated assumptions. The normality assumption matters most with small samples. If your data is heavily skewed or has outliers, a t-test or z-test can give misleading results. In those cases, nonparametric alternatives like the Wilcoxon signed-rank test or the Mann-Whitney U test are more appropriate. They don't assume normality but they do assume your distributions have similar shapes. There's no free lunch in statistics.
For your practice, work through problems in this order: start with a single-mean z-test with known population standard deviation. Move to a single-mean t-test where you estimate the standard deviation from the sample. Then try a two-sample independent test, followed by a paired test. Finally, tackle proportion problems. Each step adds a layer of complexity without changing the fundamental logic. The logic is always the same: assume the null is true, calculate how likely your data is under that assumption, and decide whether the data is unlikely enough to warrant rejecting the null. If you want practice problems, the OpenStax Statistics textbook has a solid chapter on hypothesis testing with worked examples and exercises. Khan Academy covers the basics clearly if you need to fill gaps. For more advanced material, the R project has vignettes on power analysis and effect size interpretation that will help you move beyond mechanical calculation toward actual statistical reasoning. Download the R code examples and run them on your own data. Hands-on practice beats passive reading every time. The biggest thing I can tell you is that you'll get better at this by doing it repeatedly until the process becomes automatic. Set up hypotheses correctly on the first try. Choose the right test based on your data structure. Calculate the statistic without looking it up. Interpret the result in the context of the original question. When you can do all four steps in under five minutes without errors, you've actually learned this material rather than just memorizing it for a test that you'll forget next week.