The Hidden Math Underneath Modern AI Systems
Most people think artificial intelligence works through magic or consciousness. It doesn't. At every layer, every decision an AI makes is a chain of mathematical operations. Vectors, matrices, probabilities, derivatives. If you want to understand what is actually happening when a model generates text, predicts a classification, or clusters data, you need to look at the mathematics first. I spent several years building and debugging ML pipelines before I stopped treating the math as background noise. It changed how I approach everything. A gradient that isn't converging usually traces back to a learning rate problem that can be solved with a simple change in numerical precision. A model that seems overfit might just have an imbalanced loss function because the class weights weren't normalized properly. These aren't philosophical questions. They're calculable problems.
Understanding Of Mathematics And Artificial Intelligence
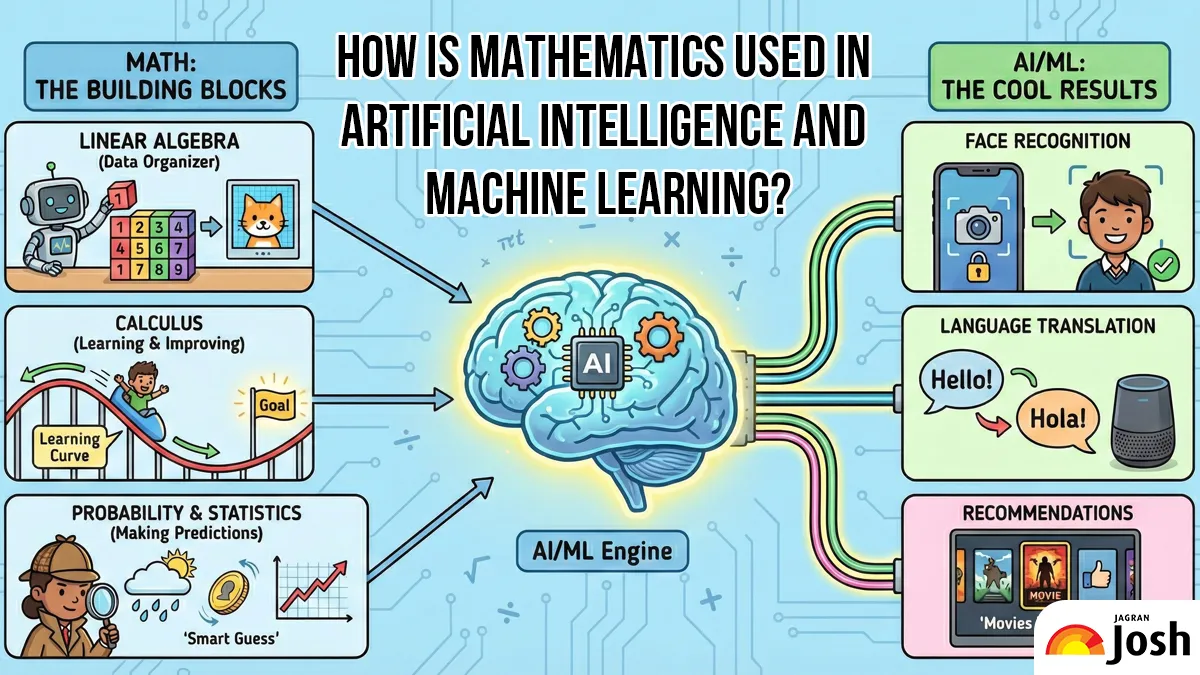
The intersection of mathematics and artificial intelligence isn't a single field. It's multiple fields working together. Linear algebra handles the data transformations. Calculus powers the optimization through backpropagation. Probability and statistics govern uncertainty and inference. Discrete math underlies the algorithmic structures. Information theory explains compression and entropy-based losses. They each contribute something essential, and none of them can be skipped without creating holes in the system. Here is something most tutorials don't make clear: you do not need a PhD in mathematics to build competent AI systems. What you need is functional understanding. Knowing how to take a derivative is useful. Knowing exactly how it applies to your loss landscape matters more. I once had a model that refused to train beyond a certain point. The issue wasn't the architecture. It was a vanishing gradient caused by using sigmoid activations in a deep network instead of ReLU variants. Fixing that involved understanding the derivative behavior of the activation function, not rewriting the entire training loop.
Practical Steps to Bridge Math and Implementation
Start with linear algebra if you haven't already. Vectors, matrices, dot products, eigenvalues. These are the building blocks of everything else. A neural network layer is literally a matrix multiplication followed by a bias addition and an activation function. That's it. Understanding that at a fundamental level makes debugging infinitely easier. Next, learn the mechanics of optimization. Gradient descent isn't mysterious. It's finding the direction of steepest descent on a multidimensional surface and taking a step. The variants—Adam, RMSprop, AdaGrad—are just refinements to how that step is calculated. When I was tuning hyperparameters for a recommendation system, I noticed that Adam was giving inconsistent results across different runs. Switching to SGD with momentum stabilized training and improved generalization. The math behind why momentum helps with saddle points made the switch feel less like a guess and more like a decision. Probability theory is where things get interesting. Bayesian inference, maximum likelihood estimation, expectation-maximization. These show up everywhere. Naive Bayes classifiers, Gaussian mixtures, hidden Markov models, variational autoencoders. If you're working with any kind of uncertainty in your predictions, probability isn't optional. It's the framework.
Get the Full Details

I ran into a particularly nasty edge case once while building a fraud detection model. The dataset had extremely rare positive cases—less than 0.1 percent of the data. Standard cross-validation kept giving me misleadingly high accuracy scores because the model learned to predict everything as negative. The workaround was to use stratified k-fold splitting combined with a custom loss function that applied heavier penalties to false negatives. I also switched from standard accuracy to F1-score and PR-AUC for evaluation. The model didn't become perfect, but it became actually usable. That experience taught me more about the math behind evaluation metrics than any course ever did.
Common Pitfalls and What They Reveal
One of the most persistent mistakes I see is treating mathematical concepts as interchangeable when they aren't. Regularization techniques like L1 and L2 sound similar but behave very differently. L1 induces sparsity by driving coefficients exactly to zero. L2 shrinks coefficients toward zero without eliminating them. Choosing between them depends on whether you believe your relevant features are sparse or distributed. Picking the wrong one won't crash your code. It will just produce worse results, and you might not even notice immediately. Another issue is numerical stability. Floating point arithmetic has limits. When training deep networks, you can encounter overflow or underflow in exponentials, logarithms, or normalization layers. The softmax function is a classic example. Subtracting the maximum value from all inputs before exponentiating is a standard trick that prevents overflow, but beginners often skip it. Similarly, log(0) produces negative infinity, which breaks loss calculations. Using log-sum-exp tricks or adding small epsilon values are practical fixes that come directly from understanding the underlying math. There are also scenarios where pure mathematics falls short. Some optimization landscapes are simply too complex for analytical solutions. In those cases, you rely on numerical approximations, heuristics, and empirical testing. No amount of mathematical elegance guarantees a good model. Sometimes the best approach is the one that works, even if you can't fully explain why. That tension between theory and practice is something you learn through experience rather than textbooks.
Resources That Actually Help
For linear algebra, I found Gilbert Strang's MIT OpenCourseWare lectures to be genuinely useful despite their age. The mathematical intuition built there transfers directly to understanding weight matrices and transformations in neural networks. For optimization, "Convex Optimization" by Boyd and Vandenberghe is dense but thorough. You don't need to read it cover to cover. Working through specific chapters on gradient methods and duality gives you enough to reason about training behavior. For probability, "Pattern Recognition and Machine Learning" by Bishop remains one of the better texts. It's rigorous without being inaccessible. The chapters on Bayesian methods and graphical models are particularly strong. If that feels too heavy, "Introduction to Statistical Learning" is more approachable and covers the same ground with practical examples. It's freely available online as well. The most underrated resource is implementing things from scratch. Writing a simple linear regression from scratch using only NumPy forces you to confront the matrix operations and gradient computations directly. Building a shallow neural network without any framework library teaches you more about backpropagation than any explanation can. I did this early in my career and it paid off every time I needed to debug a custom layer or understand a framework's behavior.
When the Math Isn't Enough
It's worth noting that mathematical understanding has limits. Modern deep learning systems often involve architectures and training procedures that even their creators don't fully understand theoretically. The emergence of capabilities in large language models, the success of transformer architectures, the behavior of overparameterized networks—these are areas where practice leads theory. You can know all the math and still encounter situations where the expected behavior doesn't match reality. In those cases, experimentation becomes the primary tool. A/B testing, learning rate scheduling, early stopping, data augmentation, ensembling. These are practical strategies that compensate for theoretical gaps. The mathematics gives you a foundation and a vocabulary. It doesn't solve every problem for you. Accepting that limitation saves time and frustration. You start treating math as a lens for understanding what's happening rather than a crystal ball for predicting outcomes. The relationship between mathematics and artificial intelligence is foundational but not exhaustive. It shapes how you build, debug, and improve systems. It doesn't replace intuition, experimentation, or engineering judgment. The best practitioners I know treat all three as necessary.