Working with Ohio River flood records isn't as straightforward as you'd think
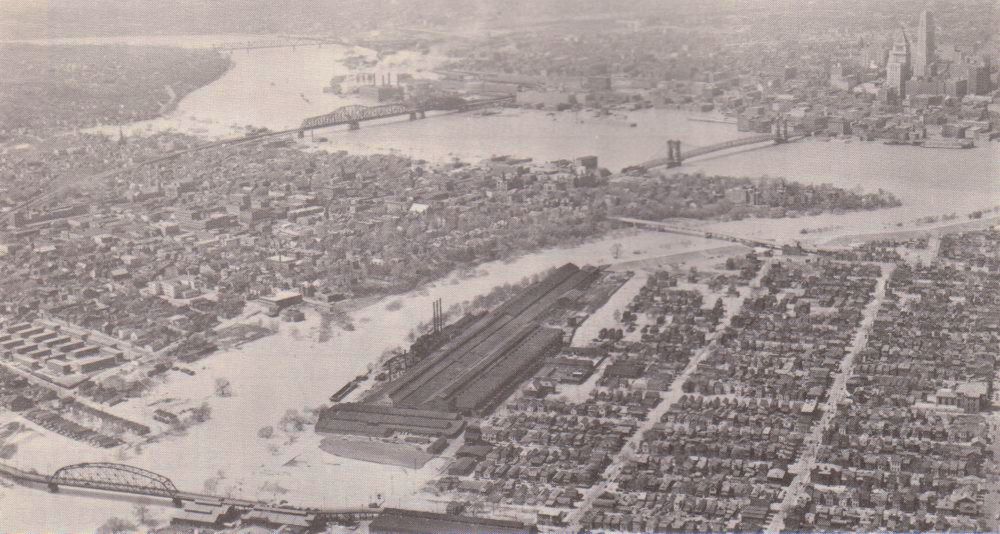
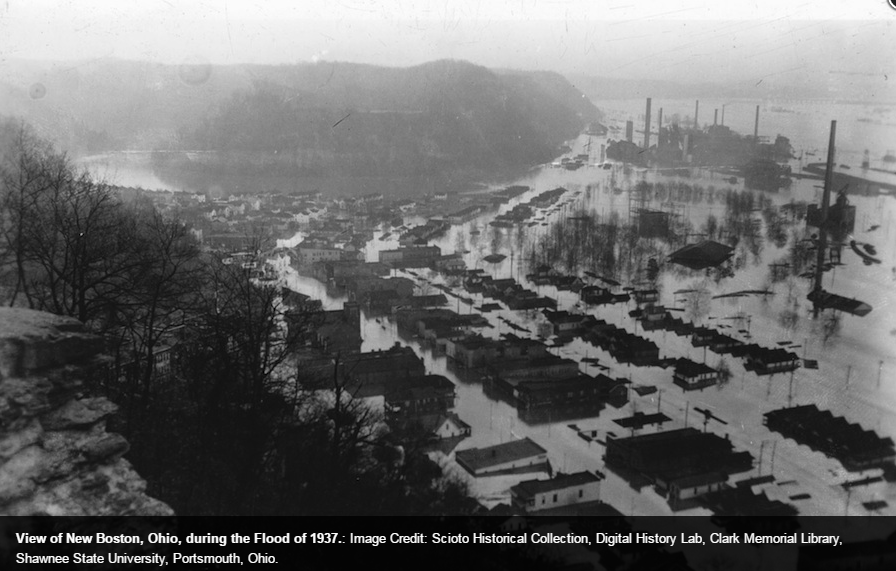
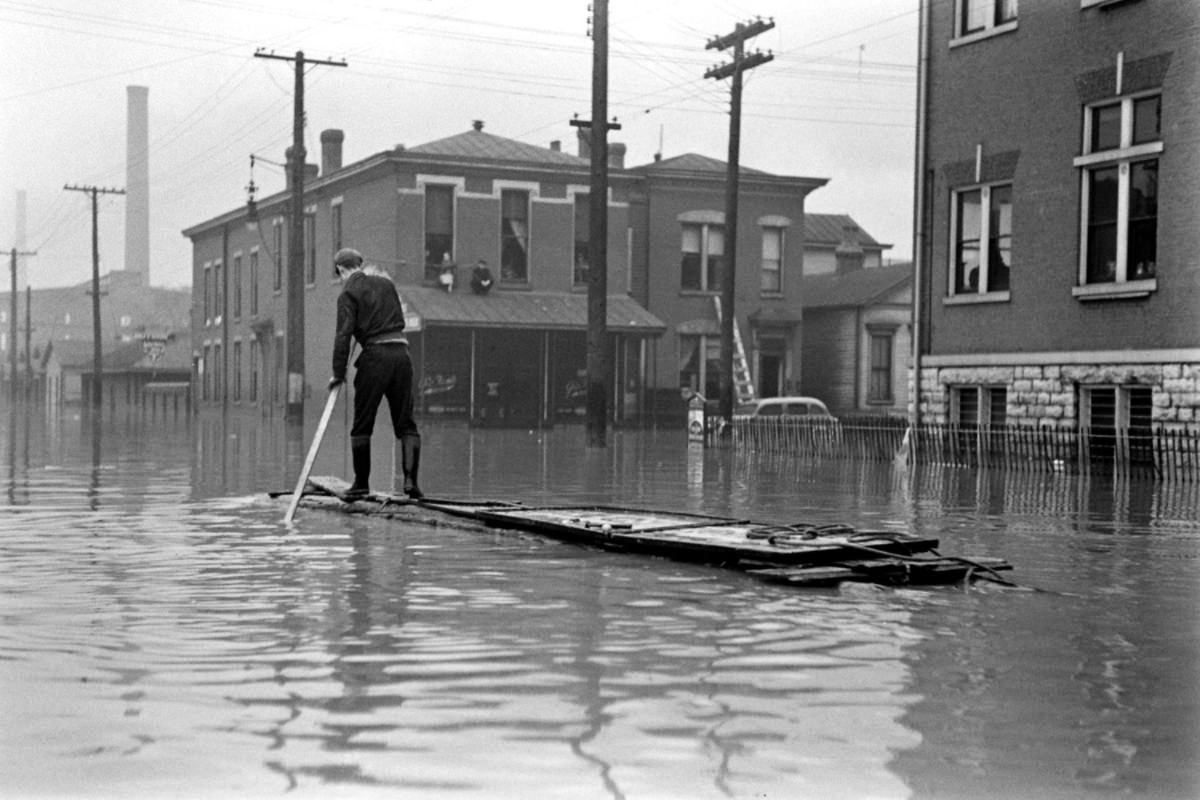
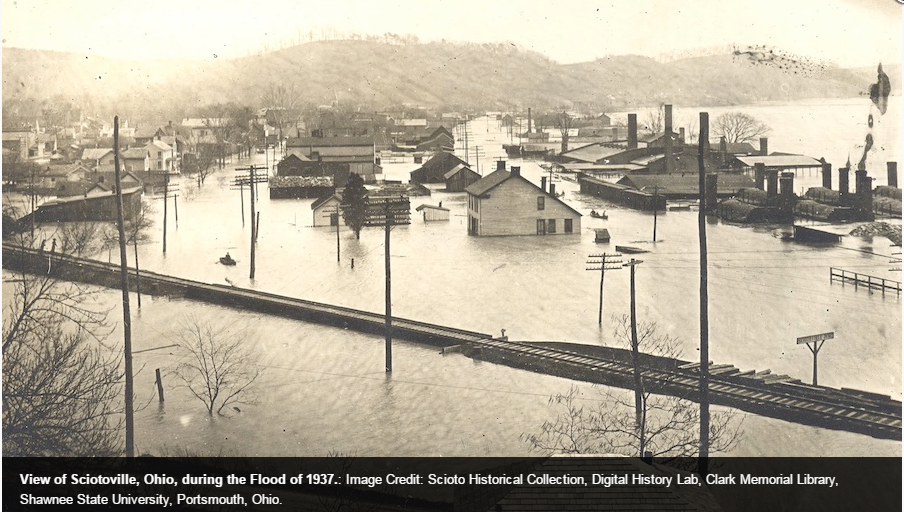
If you're looking at Ohio River Flood History for anything beyond a casual glance, you're going to run into friction pretty quickly. The USGS operates the gauge network along the river, and they've been collecting streamflow data since the early 1900s in some places. That's useful, but the records are scattered across multiple databases, different formats, and frequently revised after the fact when later measurements correct earlier estimates. I spent a few years pulling this data for flood risk assessments on properties along the lower Ohio, and one of the first things I learned is that the official peak stages at key gauges like Owensboro, Louisville, and Cincinnati don't always match what local emergency managers were seeing on the ground during major events. The 1937 flood, for example, is the benchmark event everyone references. The Owensboro gauge hit 52.72 feet, which was 13.22 feet above flood stage. That number is well documented. But when I was cross-referencing USGS data with Kentucky Transportation Cabinet records for a road elevation study near Clarksville, the published flood stages in the two datasets disagreed by roughly two feet on a few intermediate stations. Turns out the USGS recalibrated several gauges after the 1982 flood when they got better topographic surveys. The older stage-discharge relationships were baked into decades of published reports, so if you're working with legacy documents, the numbers you find may not reflect current official values.
How to actually dig into Ohio River Flood History
Start at the USGS National Water Information System. The web interface at nwis.waterdata.usgs.gov lets you pull daily mean flow and peak stage data for any gauge. For the Ohio River main stem, the important gauges run from Pittsburgh down to Cairo, Illinois, where the Ohio meets the Mississippi. The key station IDs you'll need include 03335500 for the Ohio at Louisville, 03344500 near Owensboro, and 03357500 at Cincinnati. Each one has its own FTP and web interface endpoints if you need to automate pulls. The USGS also publishes the National Flood Heights and Times document every few years, which lists the highest recorded stages at every gaging station. That's the single best source for raw historical peaks. But it only goes back to about 1950 in most digital form. For earlier events, you're looking at published USGS Water-Supply Papers and professional papers from the 1930s through the 1960s. The 1937 flood has entire monographs devoted to it. Those are publicly available through the USGS Publications Warehouse, but they're PDFs written in an era when data presentation meant printed tables and hand-drawn hydrographs. Scanning and OCR-ing them is usually more trouble than it's worth. Just download the originals. Here's something most people miss: the Ohio River is a backwater-influenced system below the mouth of the Tennessee River, which means flood peaks at downstream gauges don't just reflect local runoff. They're modulated by the Mississippi River's stage. During the 1937 flood, the Mississippi was running high, and that backwater effect actually held water in the Ohio instead of letting it flush out. The result was a longer-duration flood at Cincinnati and Evansville that wouldn't show up if you only looked at peak discharge numbers. If you're doing anything that involves estimating flood frequency or designing around the Ohio, you need to look at both the hydrograph duration and the stage, not just the single highest reading. A flood that crests at 45 feet for three days does more damage than one that hits 48 feet and drops in twelve hours, even though the latter has a higher peak.
For the pre-1950 data I needed for a project near Madison, Indiana, I ended up digging into the Kentucky Geological Survey's historical flood files. They maintain a digitized collection of USGS field notes and original measurement sheets that predate the NWIS database. It's not officially linked from the USGS site, so you have to find it through the KGS publications page. The data is in scanned image format, which means no copy-paste. I wrote a small Python script using pytesseract to batch-OCR the station ID, date, and stage columns from about 200 scanned pages. It took me roughly three hours to get through the stack, and the accuracy was maybe 85 percent. I manually verified every entry that fell within the 1920 to 1940 range because that's where the 1937 flood data lived. The workaround that saved me was ignoring the OCR output for anything that looked like a round number like 30.0 or 35.0. The OCR kept misreading handwritten decimal points as commas, so I filtered for those and pulled up the original scans manually. That caught about forty incorrect readings that would have otherwise slid into whatever analysis I was building. The Army Corps of Engineers also maintains flood risk data through their HEC-RAS models and the National Flood Hazard Layer. If you need mapped flood zones rather than gauge-level data, the FEMA Map Service Center is the place to go. But the flood zones on those maps are based on engineering models that combine Ohio River flood history with rainfall-runoff assumptions, and they get updated infrequently. The 2015 and 2020 map revisions for several Ohio River counties changed flood plain boundaries significantly, mostly because new LiDAR topography revealed areas that previous surveys had missed. If you're relying on old flood zone maps for a property evaluation, check the revision date first. An unused map from 2008 could be underestimating risk by a full zone classification in certain stretches. One more thing that trips people up: the Ohio River flood stages are referenced to different datums at different gauges. Most are on NGVD 29, but several were converted to NAVD 88 during the 1990s datum modernization. The difference is small, usually less than a foot, but if you're comparing stages across gauges or combining historical data with current models, mixing datums will introduce errors that are hard to spot because they're consistent in one direction. The USGS station descriptions list the vertical datum for each gauge. Look there before you trust a comparison.
Get the Full Details
The USGS Waterservices API at waterservices.usgs.gov lets you pull data programmatically, which is worth learning if you need more than a handful of gauges. The NLDI tool linked from the same site is useful for finding which gauges are tributary to a specific reach of the river. I use both together when I'm building a basin-wide flood analysis. The API returns data in CSV or XML, and the response time is usually under two seconds per request unless you're pulling more than ten years of daily data for multiple stations, in which case it throttles you. Rate limiting kicks in around twenty requests per second, so if you're scripting bulk downloads, space them out with a simple time.sleep call and you won't get blocked. The biggest limitation you'll hit with Ohio River Flood History is simply the incomplete record. The most reliable continuous gauge data starts in the 1930s for the major stations. Before that, flood evidence comes from tree-ring studies, sediment core analysis, and occasional diary entries or newspaper accounts that the USGS compiled informally. The paleoflood work along the Ohio is sparse compared to the Colorado River system, for instance. If you need flood frequency estimates that go back two hundred years, you're working with a lot of uncertainty, and the USGS typically won't publish formal frequency curves that extend that far for the Ohio main stem without a strong caveat attached. The agency's standard approach is to use the available gaged record, fit a log-Pearson Type III distribution, and call it done. That works reasonably well for return periods up to about 100 years. Beyond that, the estimates drift, and the confidence intervals widen considerably. I've seen a couple of engineering reports that interpolated 500-year flood stages for the Ohio by borrowing parameters from the nearby Indiana Ohio River gauge and applying them to an upstream reach with different geometry. That's not how it should work, and it introduces errors I've seen as large as four feet at the 0.2 percent annual exceedance probability level. For a practical workflow, I'd start with the USGS peak flow database to get the ranked list of highest stages at your station of interest, then pull the daily time series from NWIS for the years surrounding those peaks to understand duration and recession characteristics. Cross-reference with the Corps HEC-RAS results if you need modeled water surface profiles. And if you're going back past 1950, plan to spend time on the KGS and USGS Publications Warehouse sites rather than expecting everything to be neatly digitized and searchable.