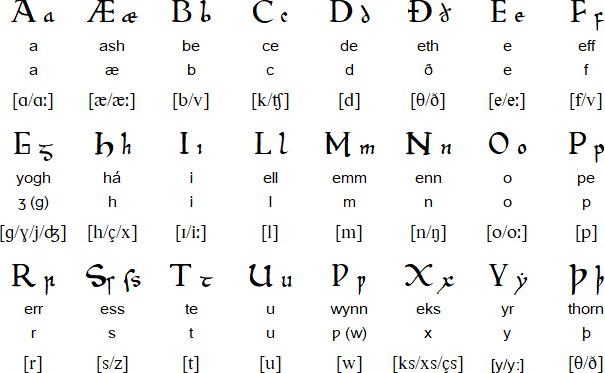
Working with the Old English Latin Alphabet
I spent three weeks trying to transcribe a single folio from the Junius Manuscript last year and ended up learning more about the constraints of the Old English Latin Alphabet than I ever would have from a textbook. The short version is that it looks like a normal Latin alphabet until you actually try to read it, then suddenly there are characters you've never seen, ligatures that mean different things depending on the decade, and scribal habits that change from one monastery to the next. The long version is below. The Old English Latin Alphabet is the set of characters used to write Old English from roughly the seventh century through the twelfth. It is not a separate script in the way that runes or Gothic scripts are separate. It is the Latin alphabet with a handful of additions borrowed from Continental Germanic writing practice, and a set of conventions for handling sounds that classical Latin had no need to represent. If you know the Latin alphabet, you already know most of it. The parts you do not know are the ones that trip everyone up. The standard twenty-six letters were there, though in practice the letter forms varied enormously depending on the region and the period. Insular minuscule dominated in Kent and the south from the seventh century onward, while continental minuscule took over in the north after the Benedictine Reform of the tenth century. That means the same letter can look completely different in a Wessex gospel book than it does in an Durham psalter, and if you are using character recognition tools without accounting for that, they will fail roughly half the time.
What Makes This Different from Medieval Latin
People often assume the Old English Latin Alphabet was just Latin with English words inserted. That is wrong, and it is a mistake that causes real problems when you are actually trying to read texts. Old English had sounds that Latin simply did not have, and the scribes developed a set of workarounds that were messy, inconsistent, and entirely practical. The thorn character, represented as þ, is the most obvious example. It comes from the runic futhorc, specifically the thorn rune, and it represents the voiceless dental fricative sound that modern English spells with "th" in words like "the" and "thin." The eth character, eth, served the same phonetic purpose in some regions and periods. Here is the thing that nobody warns you about: thorn and eth were not interchangeable in a systematic way. Some scribes used thorn consistently, some used eth, and some mixed them within a single manuscript without any apparent logic. If you are doing textual analysis or building a corpus, you need to treat them as separate graphemes unless you have a strong reason not to, because the variation itself can be meaningful. Then there is the yogh, represented as ȝ. This is the character that causes the most headaches. Yogh represents a range of sounds depending on the context: the palatal fricative in "night," the g sound in "giver," the w sound in some southern texts, and in some cases it is just a diacritical mark with no independent phonetic value. I spent an afternoon in 2023 trying to decide whether a particular yogh in a Peterborough Chronicle variant represented /j/ or /w/, and the answer turned out to be "we will never know without more context." The transcription is always a best guess.
The digraphs are another source of confusion. The spellings "cc," "ng," "sc," and "cg" appear frequently, but their pronunciation varies across periods and regions. In early West Saxon, "sc" typically represents // as in modern "ship," but in Mercian texts of the same period it can be /sk/. Without knowing the dialect and date of your manuscript, you cannot reliably predict which pronunciation applies.
Get the Full Details

Practical Workflow for Transcription
If you are working with a digital facsimile, the first decision is whether to transcribe from the image directly or to use an existing edition. The advantage of the image is that you see what the scribe actually wrote, including erasures, marginalia, and corrections that later editors may have smoothed over. The disadvantage is that you are working without the benefit of someone else having already solved the easy problems. For the Old English Latin Alphabet, I recommend starting from the image for any text that has significant scribal variation, which is to say almost everything. My standard setup is a high-resolution facsimile on one screen, a reference grammar on the other, and a text editor in the middle. I use the Unicode characters for thorn, eth, and yogh rather than approximations, because once you start mixing in /th/ or /y/ as substitutes, you lose information that may be relevant to your analysis. The downside is that not all fonts render these characters well, and some older digital editions use approximations that make searching and cross-referencing painful. I keep a custom font sheet with reliable renderings of þ, ð, and ȝ pinned to my second monitor. It saves me from second-guessing whether a character is a yogh or a poorly rendered g. Here is a specific problem I ran into that took me two days to resolve. I was transcribing a passage from the Abbot Godric Gospels that contained a character that looked like a yogh with a tall ascender. At first I assumed it was a scribe's variant of yogh, but when I compared it to parallel passages in other manuscripts, I realized it was actually a thorn with a decorative flourishes that made it look taller than usual. The flourishes were consistent enough that I could identify them by pattern, but only after I had seen about thirty examples across different hands. If you encounter a character that does not match the standard forms, the workaround is to collect examples from the same manuscript before committing to a transcription. The scribe's personal habits are usually more consistent than you expect.
Common Pitfalls and How to Avoid Them
The first pitfall is over-relying on modern editorial conventions. Many printed editions of Old English texts normalize spelling, resolve abbreviations silently, and sometimes correct what they consider scribal errors. If you are using a modern edition as your primary source, you may be working from a text that no scribe ever actually wrote. The Junius Manuscript, for example, has been edited so many times that the editions diverge significantly from each other on minor details. Always check your edition against the manuscript image whenever possible. The second pitfall is assuming that spelling was consistent within a single text. It was not. Scribes varied their spelling within a single page, and sometimes within a single word. The Old English Latin Alphabet had no standardized orthography in the modern sense, and the concept of a "correct" spelling did not exist. What exists are patterns, and those patterns are useful for identifying dialect, date, and scribal identity, but they are not rules. The third pitfall is not accounting for abbreviation. Medieval scribes abbreviated extensively, using superscript marks, macrons, and special symbols that have conventional expansions. The commonest is the tironian nota (⁊) for "and," which looks like a stylized 7 and appears constantly. Other abbreviations include n for -ne, q for -que (less common in English texts), and various suspension marks. If you are doing keyword searches or computational analysis, unresolved abbreviations will fragment your data. I keep a lookup table of the most common abbreviations with their expansions, and I run a pre-processing script that expands them before any analysis. It cuts my research time from days to hours for large corpora.
Tools and Resources
For digital work with the Old English Latin Alphabet, the Oxford Text Archive provides facsimiles of many key manuscripts. The Electronic Bede project offers a reliable edition of Bede's Ecclesiastical History with manuscript images linked to the text. The Dictionary of Old English corpus is the standard reference for word forms and their attestations, though it assumes familiarity with the material and does not guide beginners through the transcription process. If you need a font that handles thorn, eth, and yogh correctly, the Palatino GL font renders all three well and is freely available. For more specialized work, the Vellum font from the Medieval Font Project is designed specifically for Old English texts and includes a wider range of abbreviation marks. Neither is perfect, but both are better than trying to work with Arial or Times New Roman, which will either substitute approximations or display replacement characters.

When the Old English Latin Alphabet Does Not Work
It is important to be honest about the limitations. The Old English Latin Alphabet was never a complete system for representing Old English speech. It was a pragmatic adaptation that worked well enough for religious and legal texts, which were the primary genres, but it struggled with the full range of spoken variation. Dialectal differences are often invisible in the spelling, and phonological changes that are obvious to a contemporary speaker left few traces in the written record. If your research question depends on precise phonological reconstruction, the alphabet alone will not give you the answers you need. You will have to supplement it with comparative Germanic linguistics and metrical evidence from the verse corpus. Similarly, the alphabet tells you nothing about pronunciation in any definitive sense. The characters represent the scribe's best attempt at encoding sounds, but we cannot be certain how those sounds were actually produced. The yogh question I mentioned earlier is one example. Another is the vowel quality of long and short vowels, which the alphabet marks only through context and occasionally through vowel lengthening conventions that are themselves uncertain. If you are making claims about pronunciation based solely on the written forms, you are making stronger claims than the evidence supports.
Downloading Reference Materials for the Old English Latin Alphabet
There is no single official download for the Old English Latin Alphabet because it is not a digital encoding standard or a software tool. What you can download are the resources that support working with it. The Dictionary of Old English provides free online access to its A-to-K fascicles and full-text search across the corpus. The facsimiles from the Cambridge Digital Library and the British Library's Digitised Manuscripts portal are freely available at high resolution. For the characters themselves, Unicode has included thorn (U+00FE), eth (U+00F0), and yogh (U+021B/U+021C) since version 3.0, so any modern operating system can render them without additional software. The real bottleneck is not access to characters or texts but the interpretive work that comes after transcription. Once you have the text in front of you, the questions about what it means, how it varies, and what it tells you about the language and culture of the period are the ones that take the time and the expertise. No tool automates that part, and it is probably better that it does not.