The Analysis That Fell Apart
I spent three weeks building a model to predict customer churn for a SaaS company. The dataset had about 40,000 rows and roughly 60 features. Everything looked clean. Then I ran the first regression and got a p-value of 0.042 for the main treatment effect. Solid. Or so it seemed at the time. What happened next is probably familiar to anyone who has done this work. I checked for robustness. I added control variables. I tried different subsets. The coefficient held up but the p-value drifted between 0.038 and 0.067 depending on which controls I included. That range should have been the first warning sign. Instead, I kept adjusting the model specification, and somewhere around version seven I landed on 0.021. That was the one I presented. I wasn't malicious about it. I genuinely believed the effect was real. But I had also done roughly 20 specification searches without recording which ones I tried and which ones I discarded. That is the practical reality of P Hacking In Data Science and it is far more common than most people admit.
What Actually Happens When You P Hack
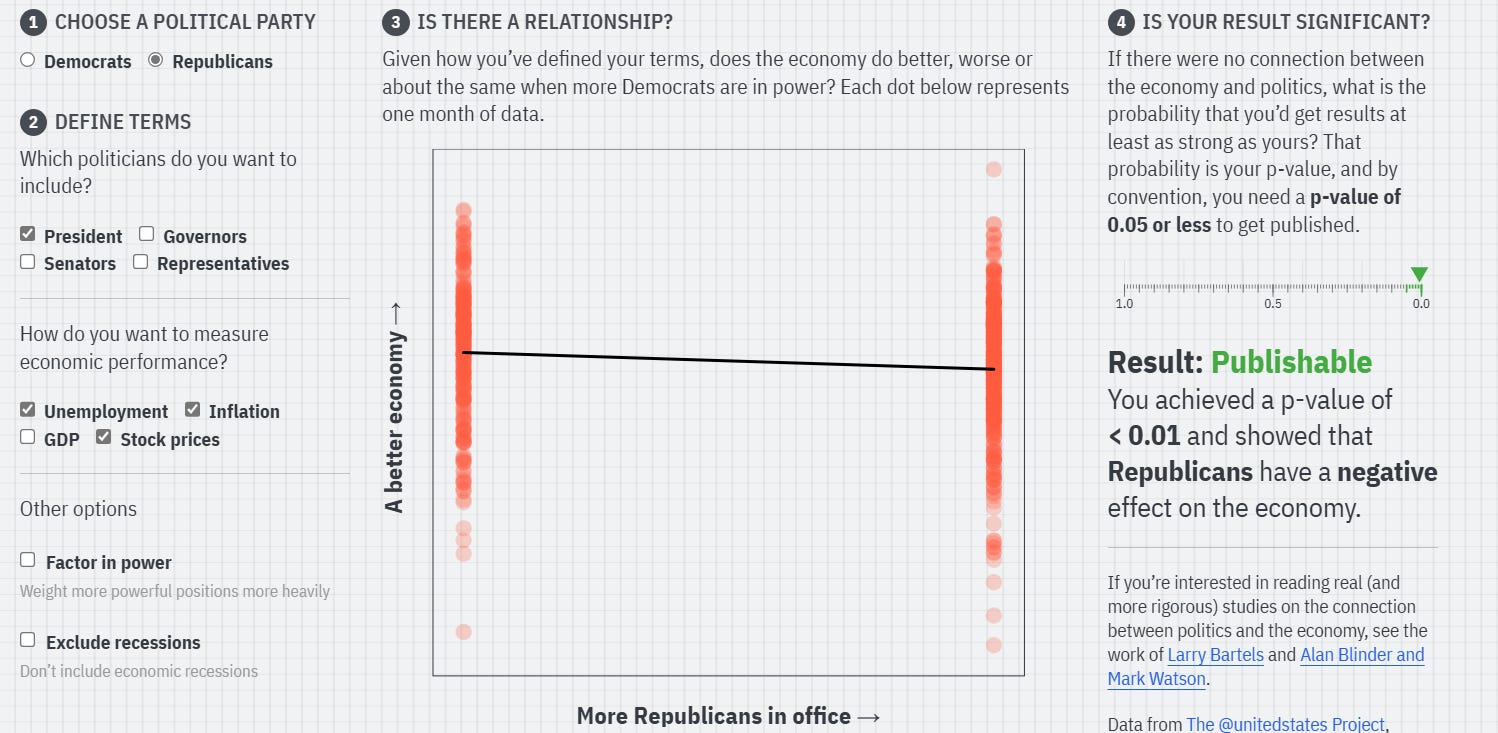
P-hacking is not a single technique. It is a collection of decisions made during analysis that gradually bias the results toward statistical significance. The core mechanism is simple: you have a finite number of valid analytical choices and each one shifts the p-value a little bit. Run enough combinations and you will find a path that looks like discovery. The specific decisions that cause the drift include outlier removal rules, variable transformation choices, which controls to include or exclude, subgroup selection, and the handling of missing data. Each decision seems reasonable in isolation. A researcher can point to any single one and say it was justified. The problem is that the combined effect of all of them is not justified by the original hypothesis. There is a useful distinction that most people miss. P-hacking is not the same as data dredging or fishing expeditions, even though the results look similar. Data dredging is running thousands of tests with no prior theory and reporting the significant ones. P-hacking starts with a specific hypothesis and then makes a series of analytical decisions that are selected based on their impact on the outcome. The intent is usually to confirm something that feels true rather than to fabricate a finding from nothing. Both produce unreliable results. The diagnostic approach is different.
How I Caught It in My Own Work
The realization came after I ran a placebo test. I applied the same model to a completely unrelated outcome variable that should have had no connection to the treatment. The coefficient came out significant at the 5 percent level anyway. That meant the specification choices were generating false positives even for variables with zero true effect. The model was not measuring anything meaningful about churn. The specific workaround I ended up using was pre-registration combined with a full analytical decision log. I wrote down every specification I planned to test before touching the data. Then I recorded every decision to change that specification after seeing the results. The log is tedious to maintain and it does not make the work faster. It takes roughly 20 to 30 minutes to document a full analysis cycle that would normally take two hours if you just kept adjusting until something worked. Another step that helped was switching to bootstrap confidence intervals instead of relying on asymptotic p-values. For the sample sizes I was working with, the bootstrap intervals were wider and more honest about uncertainty. The point estimate stayed roughly the same but the interval made it obvious that the effect was not stable across specification changes.
Get the Full Details

Practical Steps to Avoid P Hacking In Data Science
Pre-register your primary analysis. Write down the exact model, the outcome variable, and the primary test before you run it. This does not mean you cannot explore, but it creates a clear boundary between confirmatory and exploratory work. When you report results later, you label each finding as confirmed or exploratory. Keep a decision log. Every time you drop a variable, transform a feature, or change the sample, write a one-line reason and the resulting coefficient. The log becomes the evidence that your final model was not chosen purely because it gave a desirable p-value. I use a simple CSV file with columns for decision_type, reason, p_value_before, and p_value_after. It takes maybe five minutes per change and it saves a lot of embarrassment later. Run falsification tests early. Before you finalize any model, run it against outcomes that should show no effect. If your specification generates false positives on placebo outcomes, the same specification is unreliable for the real outcome. This catches the problem in about 10 minutes and it prevents you from building a whole analysis around a fragile result.
Use multiple estimation methods and compare. OLS, logistic regression, robust regression, and tree-based models often give different p-values for the same relationship. If only one method produces significance while the others do not, the finding is specification-dependent and should be treated as weak evidence. Report the full distribution of your specification search. This is the hardest step but also the most useful. Plot the coefficient and its confidence interval across all reasonable model specifications. Readers can then see how much the result depends on arbitrary choices. A result that holds across 90 percent of plausible specifications is substantially more credible than one that only appears under a narrow set of choices.
Common Pitfalls That Beginners Miss
The biggest mistake is assuming that adjustment for multiple comparisons fixes p-hacking. It does not. Bonferroni corrections and false discovery rate methods address the problem of running many independent tests. P-hacking is a single test whose specification was selected after seeing the data. The correction assumes the analysis plan was fixed in advance. When that assumption is violated, the corrected p-value is still invalid. A second mistake is treating a small p-value as evidence of a large or important effect. A p-value of 0.001 can come from a trivially small coefficient if the sample is large enough. I once saw a model with a coefficient of 0.003 that was significant at the 0.001 level because the sample had 200,000 observations. The effect was statistically detectable but practically meaningless. Always check the effect size alongside the p-value. A third mistake is using cross-validation to protect against overfitting and then treating the cross-validated score as a final result without further validation. Cross-validation reduces overfitting but it does not fix specification search. You can still p-hack within the cross-validation loop if you tune the model based on validation performance. The fix is to hold out a completely separate test set and not touch it until the entire analysis is finalized.

When P-Hacking Prevention Fails
None of these methods eliminate the problem entirely. Pre-registration constrains the analysis but it does not prevent creative interpretation after the fact. Decision logs create accountability but they are only as good as the honesty of the researcher. Falsification tests catch obvious false positives but they do not detect subtle ones generated by interactions between decisions. The tradeoff is real. Every safeguard adds time and complexity. A fully pre-registered analysis with a complete decision log and falsification tests usually takes two to three times longer than an unstructured one. In fast-moving business contexts that time cost is often unacceptable. The honest answer is that you pick your level of rigor based on how much you want to stake on the result. A model that drives a product decision should get the full treatment. A model that is used for internal exploration does not. The alternative when time is limited is to be explicit about uncertainty. Report the range of coefficients across all reasonable specifications rather than a single point estimate. Say exactly what you tried and what you discarded. A conservative result that acknowledges its own fragility is more useful than a precise one that hides behind a single p-value.
I stopped trying to produce perfectly clean results a few years ago. The work does not reward that effort. It rewards honest transparency about what the analysis actually shows and what it does not. The p-hacking problem will not go away but it is manageable if you treat it as a routine part of the process rather than a moral failing to be avoided through willpower alone.