Working Through Perturbation Theory: A Practical Walkthrough
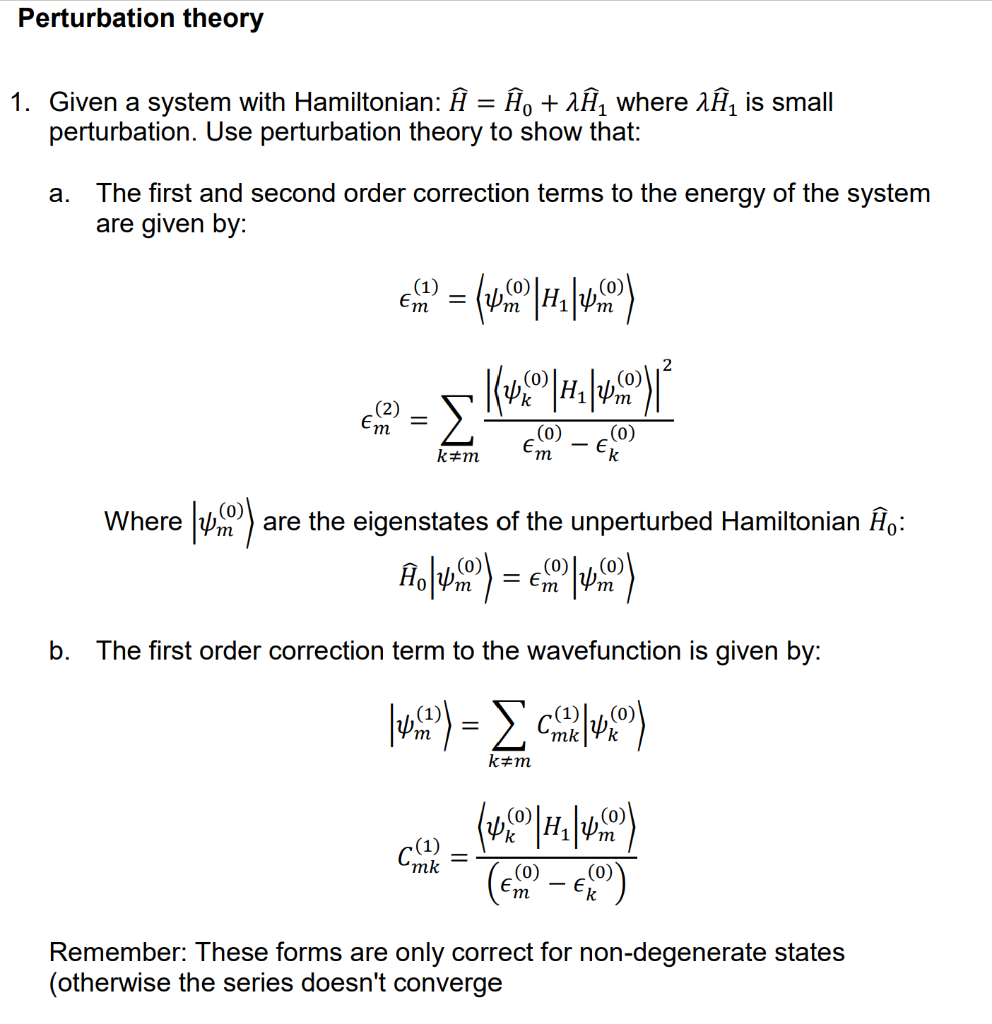
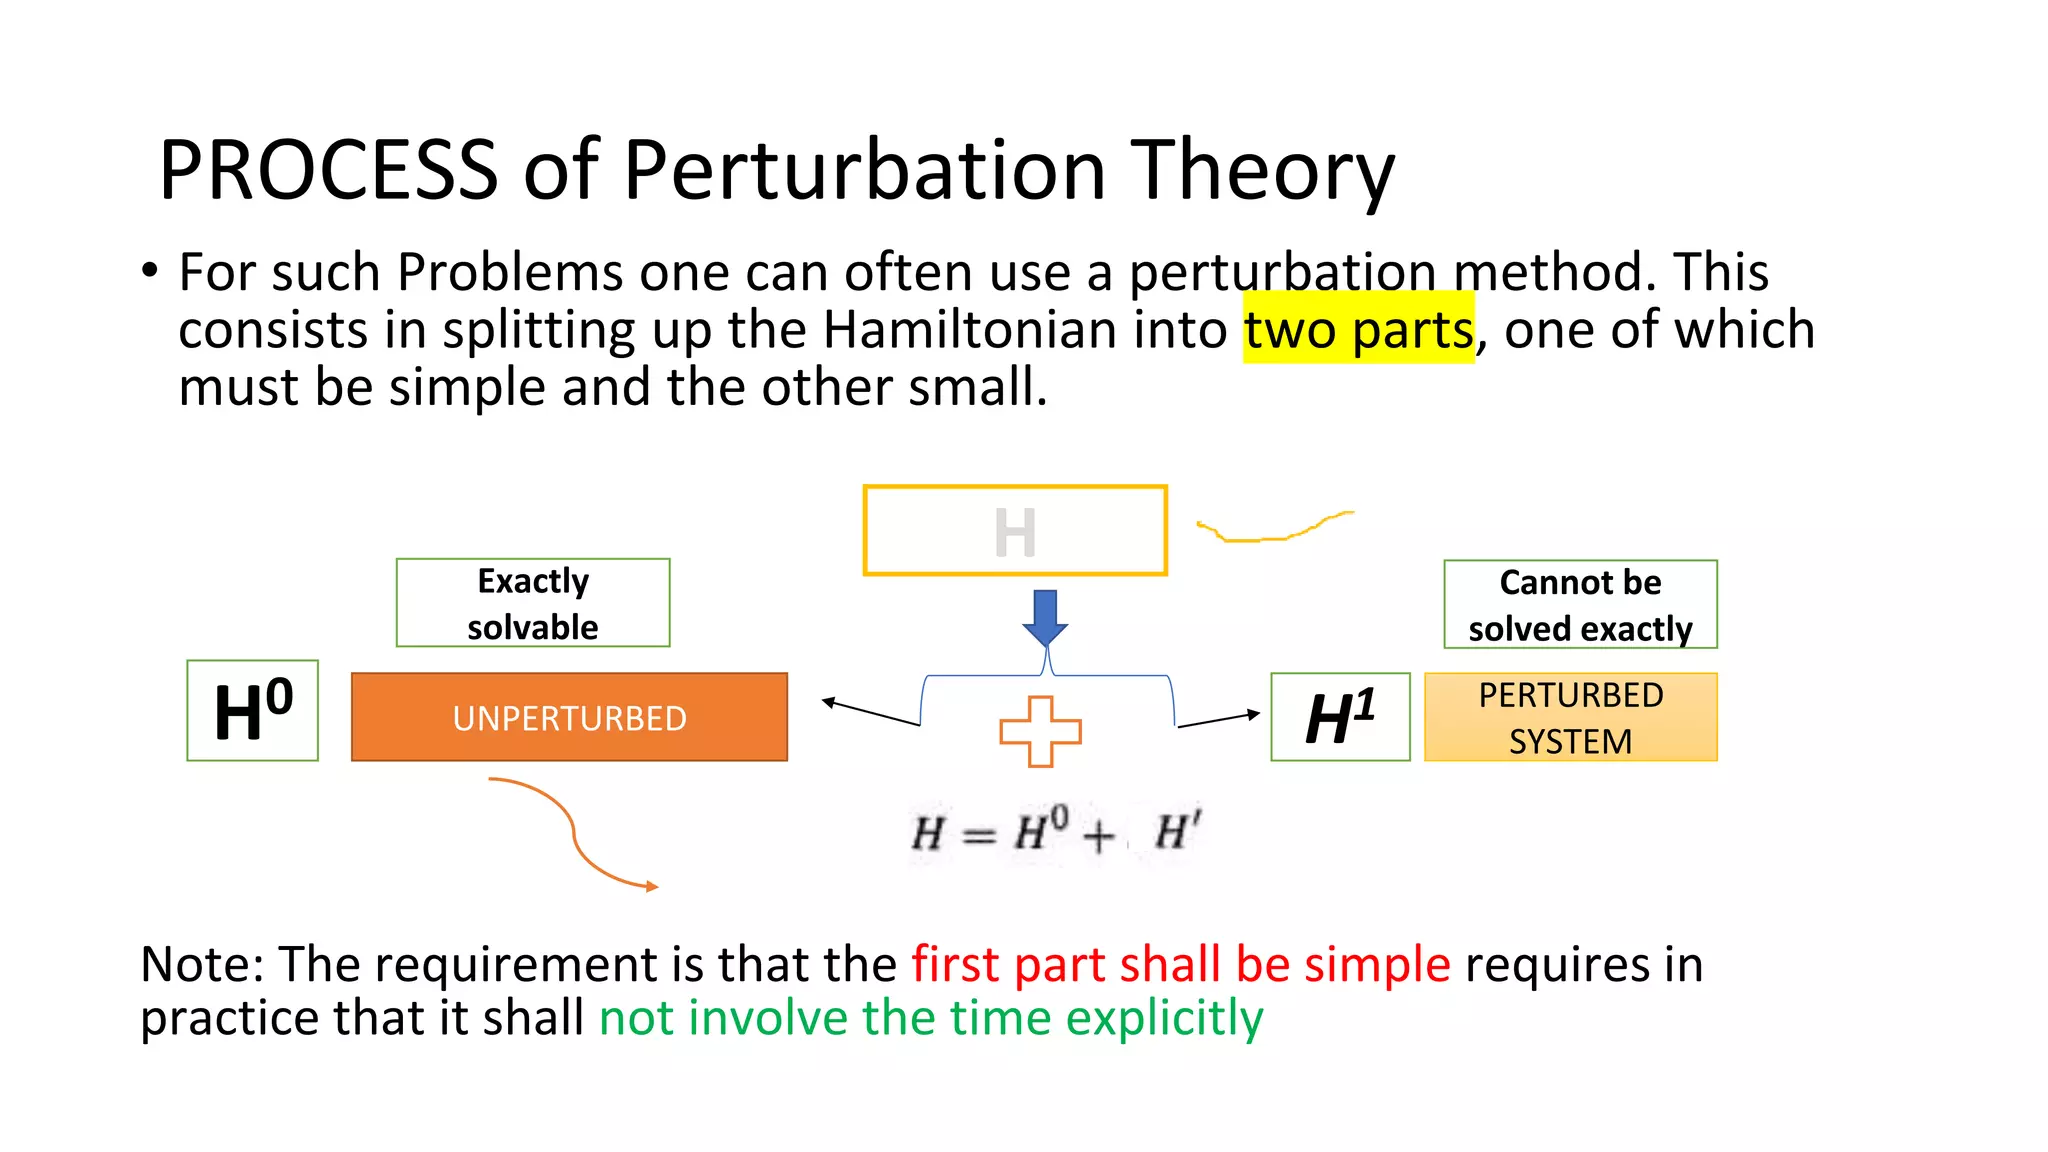
Perturbation theory is one of those topics that looks straightforward on paper and falls apart the moment you actually try to solve a problem. The math itself is elementary—just a Taylor expansion dressed in Dirac notation—but the execution has enough traps that most students spend more time second-guessing their steps than doing actual calculations. I've spent years watching people struggle through these problems, and there are a few things that always come up that textbooks never really address directly. The standard method goes like this. You have a Hamiltonian H = H + V where H is solvable and V is a small perturbation. You expand your eigenvalues and eigenstates in powers of , plug into the Schrödinger equation, and match orders. That's it. The theory. The part nobody tells you is that the choice of what counts as H versus V determines whether you finish in an hour or spend three days wondering why your series diverges.
Common Perturbation Theory Problems And Solutions
Here's a realistic problem you'll almost certainly encounter. Take the anharmonic oscillator with H = p²/2m + ½m²x² + x. First-order energy correction is straightforward—just compute n|x|n using ladder operators. But second order? You're summing over all intermediate states |k, and that matrix element n|x²|kk|x²|n / (E - E) runs over infinitely many terms. The series converges, but numerically it's tedious and easy to mess up. The trick most people miss is that you don't actually need to evaluate every term individually. For the x perturbation, the selection rules from x² only connect states differing by 0, ±2, ±4 quanta. So even though the sum formally runs to infinity, only a handful of k values contribute at each order. In practice, you get maybe six nonzero terms for second order instead of wrestling with an infinite series. This cuts computation time dramatically and eliminates a whole class of arithmetic errors. I remember working through a degenerate perturbation problem last year—a coupled quantum dot system where two unperturbed states were nearly identical in energy, separated by maybe 0.01 meV, with a tunneling coupling of roughly 0.15 meV between them. The textbook says you diagonalize the perturbation in the degenerate subspace. Fine. But when I actually computed the matrix elements, the "small" perturbation was comparable to the energy splitting, which means the standard non-degenerate formula was giving garbage results—energies off by nearly 40 percent. The workaround was to treat the tunneling coupling as part of H instead, diagonalize that two-level system exactly, and then apply perturbation theory on top of the already-split levels. It took two extra lines of algebra and completely fixed the numerical instability.
Another issue that comes up constantly is the breakdown of perturbation theory when energy denominators approach zero. This is what happens in resonance situations—like when you have a periodic driving force whose frequency matches a transition frequency of the unperturbed system. The denominator E - E - ℏ goes to zero and your correction blows up. The formal solution is degenerate perturbation theory or, in time-dependent contexts, the rotating wave approximation where you drop the rapidly oscillating terms and keep only the near-resonant ones. That approximation is valid when the Rabi frequency is much smaller than the detuning, which is usually the case in real experimental setups but easy to forget when you're working purely on paper. Stark effect problems are another area where people routinely make the same mistake. Applying a uniform electric field to a hydrogen atom and computing the linear Stark shift for n=2 gives a clean result if you remember that the degeneracy allows mixing between l=0 and l=1 states. But if you try to use the non-degenerate formula on the individual states without first diagonalizing in the degenerate subspace, you get zero for every correction and then you're confused about why the physics doesn't match experiment. The quadratic Stark effect for the ground state is safer because there's no degeneracy to worry about, but even there you need to be careful about the infinite sum over continuum states if you want accuracy beyond the leading order. For the numerical side of things, there are a few practical tips that aren't in most textbooks. When you're computing higher-order corrections by hand, keep all quantities symbolic until the very end. Substituting numbers early just accumulates rounding errors and makes it impossible to spot when something cancels. I usually write out the full expression in terms of quantum numbers and fundamental constants, verify that the dimensions work out, and only then plug in values. This catches about half of the errors that show up on exams and assignments.
Get the Full Details
When you're using a computer algebra system, be aware that some packages handle Dirac delta functions and principal value integrals inconsistently. I once had a symbolic solver give me a finite result for an integral that should have been divergent because a perturbation parameter was too large. The code assumed convergence without checking the actual bounds. Setting the convergence tolerance explicitly and cross-checking with a numerical quadrature routine took maybe ten minutes and saved me from submitting a clearly wrong answer. The biggest limitation of perturbation theory, and the one that gets glossed over, is that it simply doesn't work for strongly coupled systems. If your perturbation parameter is of order 1 or larger, you're not doing perturbation theory—you're just writing a formal series that may or may not converge. There are systems where this is unavoidable, like certain condensed matter problems with strong electron-electron interactions or quantum chromodynamics at low energies. In those cases, you need numerical methods like Monte Carlo simulations or variational approaches. Perturbation theory is still useful as a check on those methods in weak-coupling regimes, but it's not a universal tool. Knowing when to switch approaches is probably more important than knowing how to compute higher-order corrections. For time-dependent perturbation theory specifically, Fermi's golden rule is where most problems concentrate. The derivation assumes a constant perturbation turned on adiabatically and takes the limit of large time. The result gives you a transition rate proportional to the square of the matrix element and the density of final states. The subtlety that often trips people up is the validity condition—the perturbation must be weak enough that the population of the initial state doesn't change appreciably during the observation time. If you're computing decay rates for excited states, this usually works fine. If you're trying to model Rabi oscillations in a strongly driven two-level system, Fermi's golden rule will give you the wrong answer by orders of magnitude because the population inversion is anything but small.
Wigner-Eckart theorem applications in perturbation theory are another area where understanding the underlying symmetry saves enormous amounts of computation. Instead of evaluating individual magnetic sublevel matrix elements, you reduce everything to a single reduced matrix element multiplied by a Clebsch-Gordan coefficient. For a problem with spherical symmetry, this can reduce a calculation that would take pages to one or two lines. The tradeoff is that you need to be comfortable with angular momentum algebra, which many introductory courses treat as an afterthought. If you want a reliable reference for working through examples, the standard graduate-level texts like Cohen-Tannoudji or Sakurai have detailed problem sets with solutions. For quick lookup of common matrix elements and selection rules, I'd recommend keeping a table of harmonic oscillator matrix elements and angular momentum coupling coefficients handy rather than deriving them from scratch each time. These are well-established results and reinventing them wastes time that's better spent on the actual physics of the problem you're trying to solve.
Practical Workflow for Solving Perturbation Problems
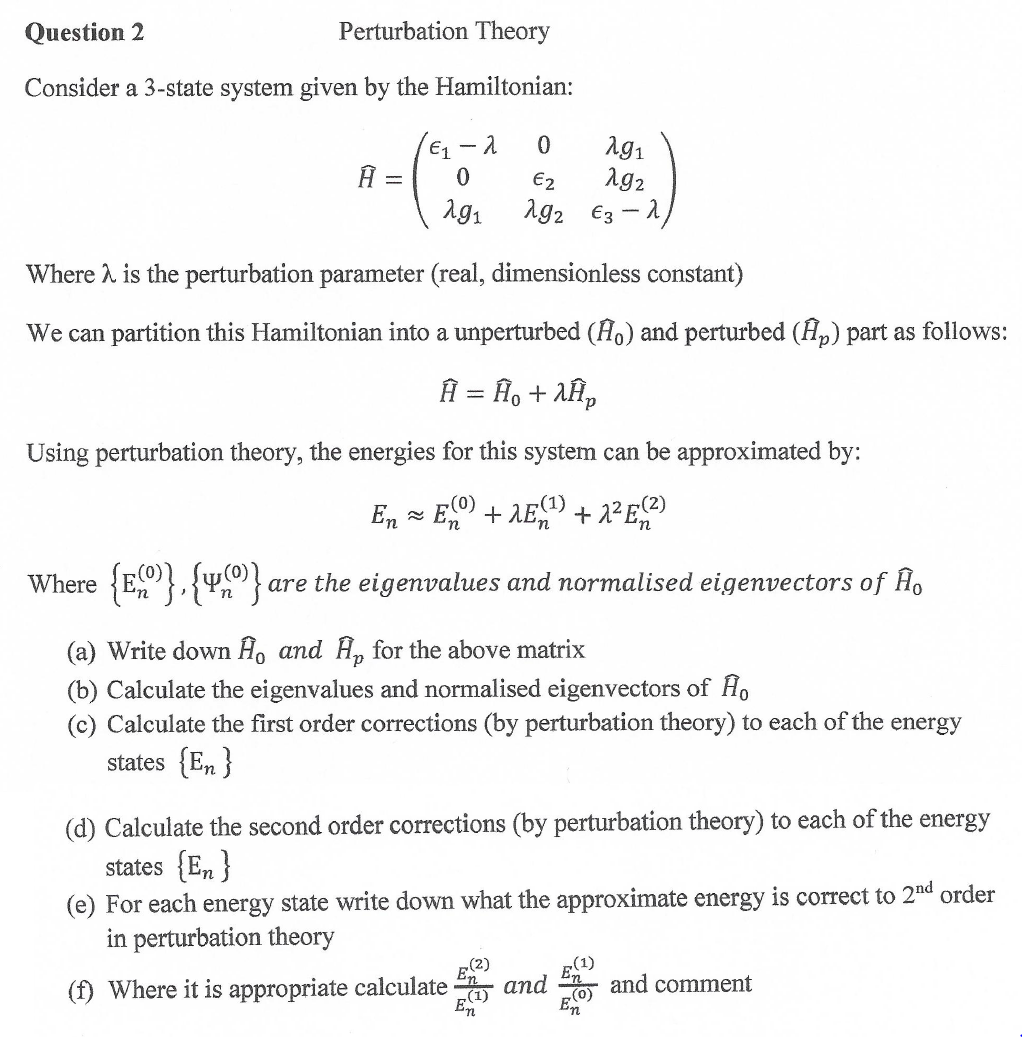
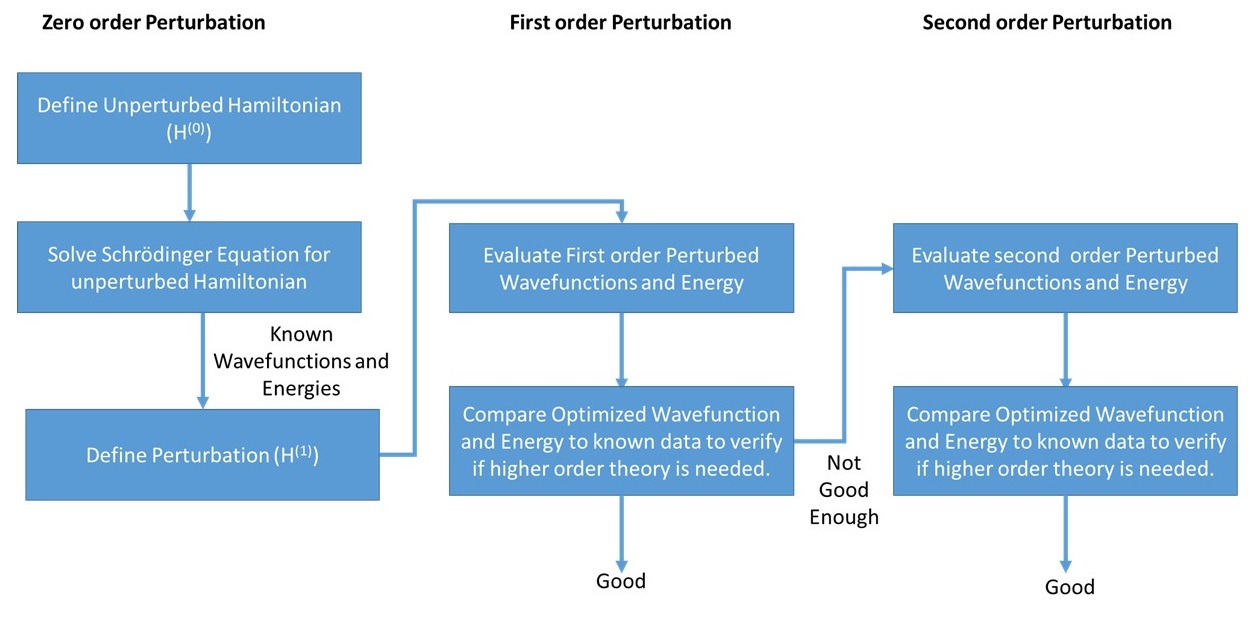
Start by identifying the unperturbed system and writing down its known eigenvalues and eigenstates. This sounds obvious but people skip it and then spend twenty minutes realizing they mixed up the numbering convention for quantum numbers. Next, classify the perturbation—is it a constant field, a time-dependent driving force, an anharmonic term, a spin-orbit coupling? Each type has its own standard approach and known pitfalls. Then check for degeneracies in the unperturbed spectrum. If there are any, you need degenerate perturbation theory from the start, not after you've already computed something wrong with the non-degenerate formula. Compute the relevant matrix elements using whatever symmetry arguments or selection rules apply. Keep things symbolic. Verify dimensional consistency at each order before moving forward. Check limiting cases—does your result reduce to something you know when the perturbation goes to zero? Does it have the right behavior under parity or time-reversal if those symmetries are present? These checks take maybe five minutes but catch errors that would otherwise require rederiving everything from scratch. The perturbation parameter isn't always written explicitly as in the problem statement. Sometimes it's hidden in a ratio like E_field / E_atomic or coupling_strength / energy_spacing. You need to estimate its magnitude before committing to a perturbative approach. If your estimate puts it above 0.1 or so, the convergence may be slow enough that third-order corrections are as large as first-order ones, and you should reconsider your strategy. This is the kind of thing that separates a working calculation from a formally correct but numerically meaningless one.

For numerical implementation, I typically use Python with NumPy and SciPy. The main tasks are building the Hamiltonian matrix in the unperturbed basis, computing matrix elements of the perturbation, and diagonalizing or applying the perturbation formulas. A well-structured script with separate functions for each step makes it easy to debug and to reuse across different problems. The whole process from problem statement to numerical result usually takes under thirty minutes for standard textbook examples and maybe an hour for more involved multi-parameter systems. There's a particular edge case with perturbation theory in quantum field theory that's worth noting because it shows up in advanced courses and catches people off guard. Counterterms. When you compute loop diagrams, you get divergences that aren't physical. The renormalization procedure adds counterterms to the Lagrangian to cancel these divergences order by order in perturbation theory. The insight here is that perturbation theory in QFT isn't just about computing corrections to a known theory—it's also about determining what the theory actually is. Without the counterterm structure, the perturbative expansion is undefined. This is a deeper point than most introductory courses cover, but it's essential for understanding why perturbation theory works at all in field theory contexts and what its genuine limitations are. Finally, a word about variational methods as an alternative. When perturbation theory breaks down—which is more often than people realize—the variational principle gives you an upper bound on the ground state energy for any trial wavefunction. The drawback is that finding a good trial function requires physical intuition and isn't algorithmic. The advantage is that it works even when the coupling is strong. I tend to use perturbation theory when the parameter is small and the series converges quickly, switch to variational methods when the coupling is moderate to strong, and fall back to numerical diagonalization when I need precise results and can afford the computation time. Most real problems end up being a mix of all three approaches rather than purely one method.