Getting Your Data on a Scatter Plot Without Losing Your Mind
Plotting a scatter plot is one of those things everyone learns early and almost nobody actually does well. You have two variables, you want to see if they relate, and so you reach for your plotting library of choice. The result is often a mess of overlapping dots, unreadable axes, and a legend that explains nothing. I've watched people spend hours adjusting markers and colors only to end up with something worse than what they started with. The basic mechanics are trivial. You map one variable to the x-axis, another to the y-axis, and each observation becomes a point. But the practical reality involves decisions that matter more than the syntax itself. You need to think about scale, overlap, color, and what your audience actually needs to extract from the visual.
How to Plot A Scatter Plot Without Making It Unreadable
Here is how I actually do it. Start by loading your data and checking for missing values or obvious outliers before you even open the plotting function. I use Python with matplotlib and seaborn most of the time. Sometimes I reach for ggplot2 in R. The library doesn't matter as much as the workflow. I typically start with a simple base call, then layer adjustments. A common mistake beginners make is applying transparency and small markers too late in the process. If your data has more than a few thousand points, you need alpha blending and reduced marker size from the start, not after you realize the chart looks like a solid blob. Setting alpha to around 0.4 and using small point sizes usually handles moderate-overlap cases within the first attempt. Axis scaling is where most scatter plots go wrong. Linear scales work fine when your data is roughly normally distributed across both dimensions. When you have skew, log transforms on the axes often reveal relationships that linear plots completely hide. I log-transform axes before I even think about colors or annotations. It changes the story your plot tells.
Color should encode information, not decoration. A common failure I see repeatedly is using categorical colors for continuous variables or using rainbow colormaps. Stick to sequential colormaps for ordered data and qualitative palettes for true categories. Viridis is safe. I use it by default unless there is a strong reason not to. Here is a practical example. Say you are looking at the relationship between household income and years of education across a sample of 5,000 respondents. You load the data, drop rows with missing values in either column, and check the distribution of each variable. Both are right-skewed, so you apply a log transform to income and plot education on the raw scale. The scatter plot immediately shows a clearer upward trend with less compression at the lower end. You add a lowess or LOESS smooth line to give viewers a sense of the central tendency without forcing a linear assumption. The code takes maybe twenty lines, but the thinking takes longer. Labels matter. Axis titles should specify units. A point labeled "50000" on the income axis means nothing without a dollar sign or clear indication of currency. Title the plot with the actual relationship you are investigating, not just "Scatter Plot of X vs Y." Readers will forget which is which if you make them search for it.
Get the Full Details

I encountered a specific problem once that still comes to mind. I was plotting GPS coordinates for delivery drivers across a dense urban area. The data had hundreds of points clustered in the downtown core, making individual points indistinguishable. Standard jittering and transparency didn't help because the overlap was too extreme. My workaround was to create a hexbin overlay using the hexbin function and then layer the raw points on top with very low alpha. The hexbin showed density, the points showed individual locations, and the combination was actually interpretable. This took about five minutes once I knew hexbin was an option, but I had spent roughly forty-five minutes trying different combinations of alpha values and marker sizes before finding it. Another thing people miss is the difference between correlation and visual clustering. A scatter plot can show a pattern even when the correlation coefficient is near zero. If your data has two distinct groups mixed together, the overall correlation might be misleading. Splitting the plot by category or adding faceting can clarify this. I frequently use FacetGrid in seaborn when I have a categorical variable that might explain structure in the data. This is faster than creating multiple separate plots and comparing them side by side. Interactivity deserves mention if your audience needs it. Static scatter plots are fine for papers and reports. For dashboards and exploratory work, plotly or similar libraries give you hover tooltips and zoom. The tradeoff is file size and rendering time. A static matplotlib plot of ten thousand points generates a PNG in under a second. A comparable interactive plotly visualization can take several seconds to load in a browser and produce a much larger file. Know your audience before you invest in interactivity.
There are situations where a scatter plot simply fails. If you have more than roughly twenty thousand points, even hexbin and alpha blending struggle to produce a clean result. The alternative here is a contour plot or a 2D density estimate. If both variables are discrete with many unique values, a scatter plot becomes a cloud of isolated points with little visual structure. In that case, consider a heatmap or a correlation matrix instead. Scatter plots are not a universal tool. They are a specific tool for a specific type of question. Download links and code repositories are useful when they match your environment. If you work in Python, the standard libraries are available through pip. Matplotlib, seaborn, and plotly all install with a single command. R users can install ggplot2 and plotly from CRAN. I don't maintain a personal download link for the plots themselves since they are generated from your own data, but I do keep a small collection of template scripts that handle the typical setup steps. Those scripts save me about ten minutes per plot by handling the defaults, font settings, and axis formatting automatically. The core insight that separates a usable scatter plot from an unreadable one is that you plan the encoding before you write the code. Decide which variables map to position, which to color, whether you need a smooth line, and what scale each axis uses. Write that down. Then code it. Most of the time I fix a bad plot by changing the encoding, not by tweaking aesthetics. A bad encoding cannot be saved by better colors or prettier fonts.
One counter-intuitive detail: sometimes removing the grid lines improves readability. Grids help with precise reading of values, but they also add visual noise that competes with the data points. I turn the grid off by default and only re-enable it when the plot is intended for precise value extraction rather than pattern recognition. It is a small change, but it makes a noticeable difference in most cases. Another thing worth noting is that scatter plots are sensitive to marginal distributions. If one variable has a narrow range and the other spans several orders of magnitude, the plot will look unbalanced regardless of how you adjust markers. Rescaling one or both variables before plotting is usually the fix. This is not a limitation of the plot type itself, just a limitation of how humans perceive compressed versus expanded ranges on the same visual field. I've found that presenting a scatter plot alongside a small table of summary statistics increases credibility with technical audiences. They want to see the sample size, the correlation coefficient, and perhaps the slope from a simple regression. The plot shows the shape. The numbers confirm the magnitude. Together they are more useful than either alone.
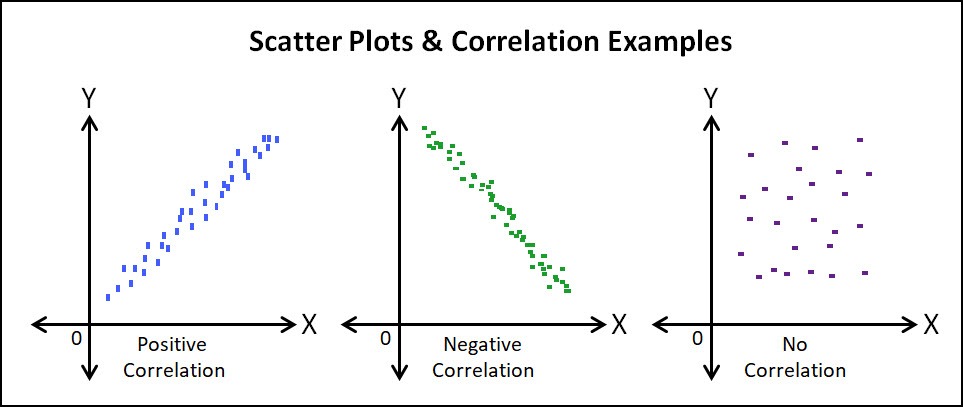
If you are new to this, start with a small dataset, five hundred points or fewer, and build from a clean base. Add one encoding layer at a time. Check the output after each addition. This approach reduces the debugging time significantly compared to building a complex plot and then trying to isolate which element broke it. Most plotting errors are additive. Fixing them is easier when you know exactly what you added last.