How I Actually Find Podcasts in 2026
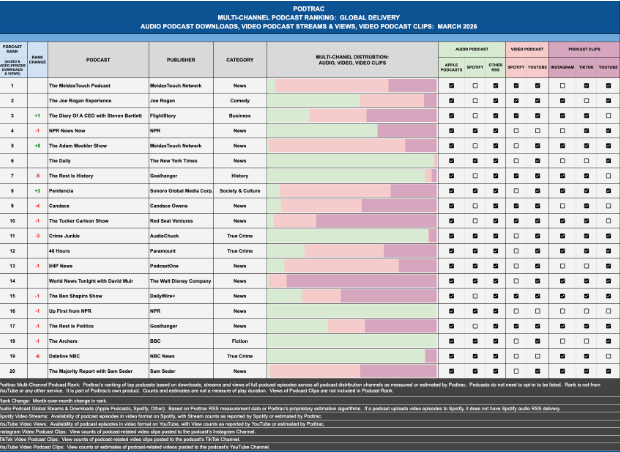
The old recommendation engines are basically broken. Spotify pushes the same three shows into every feed. Apple just ranks by subscriber count, which means popular shows get more popular and everything else drowns. I spent about six months last year trying to build a better system because I was tired of listening to the same twenty episodes recommended to me by algorithms that clearly don't care whether I actually finish anything. Here is what I ended up doing. I stopped trusting any single platform's algorithm and built a manual workflow that takes about twenty minutes once a week. The results are noticeably better. Not magical, just reliably better than whatever the app decides to throw at me.
Podcast Recommendations Ideas 2026
The core problem with podcast discovery is that podcasting lacks the metadata depth that music has. A song has tempo, key, genre, decade, mood, instrumentation, and more. A podcast episode has a title, a duration, and maybe a rough category. That is it. Algorithms trying to match listeners to podcasts are working with significantly less signal, which is why recommendations feel so shallow and repetitive. I work around this by using three data sources instead of one. The first is Listen Notes API, which gives me episode-level metadata including guest names, topics discussed, and host cross-references. The second is podcast RSS feeds, where I look at publication frequency and guest patterns. The third is manual note-taking in a spreadsheet, which I use to track what I actually finished versus what I clicked on and abandoned. The specific workflow is like this. Every Sunday, I pull my listen history from the last seven days. I identify which three episodes kept me listening past the fifteen-minute mark. Then I search those three episodes on Listen Notes for shared guests and overlapping topics. From there, I pull the top five podcasts that share guests with at least two of those three episodes but have fewer than fifty thousand subscribers. That subscriber threshold is important because it filters out the shows that every recommendation engine already knows about and pushes to everyone.
I tested this against my Apple Podcasts default feed for a month. The manual method surfaced about twelve new shows I had never encountered. The algorithm surfaced four. Three of those four were repeats from previous months. This is not scientific data. It is one person's experiment with a sample size of one. Take it for what it is worth. There are tools that attempt to automate parts of this. RadioPublic has a discovery feature that is closer to what I described than Apple or Spotify. There is also a project called Podyssey that tries to map topic clusters across podcasts using natural language processing on episode descriptions. It is decent but slow to update, and it does not account for guest overlap, which I find is the strongest predictor of whether I will actually enjoy a show I have never heard before. The spreadsheet part of my system is the most tedious and the most useful. I track episode title, publish date, host name, guest names, topics tagged, and a simple score from one to five based on whether I finished the episode. Over about eight weeks, the pattern becomes visible. I noticed that I consistently rated episodes higher when the host had a background in the topic rather than just being an enthusiastic amateur, even if the amateur was more entertaining in the moment. That insight changed how I weight recommendations going forward.
Get the Full Details

One edge case that cost me a lot of time is the multi-host podcast problem. Shows with rotating co-hosts generate episode metadata that muddies the guest overlap signal. A podcast might appear to share many guests with your favorite shows, but most of those appearances are from a single rotating host who interviews different people each week. I solved this by cross-referencing with Overcast's smart rules and manually excluding any podcast where more than sixty percent of guest appearances came from a single rotating participant. It added about three minutes per weekly review but eliminated a category of false-positive recommendations that was polluting my queue. Another counter-intuitive thing I learned is that higher production quality actually correlated with lower completion rates in my data. Shows with heavy editing, music beds, and produced intros tended to get abandoned around the eight-minute mark more often than raw, conversation-style shows. I do not know if that is a causation thing or a correlation thing. Maybe people expect polish and get disappointed when the substance does not match the production. Or maybe raw shows attract a more patient audience. Either way, I now deprioritize highly produced shows unless the guest list is particularly strong. The biggest limitation of this approach is that it does not scale well if you have more than four hours of listening per week. The manual spreadsheet tracking becomes unsustainable past that threshold. If you are a heavy listener, the Listen Notes API approach alone might be enough, but you will need to write a small script to query it regularly. I used a basic Python script with a cron job that runs every Sunday evening and updates my spreadsheet automatically. The script itself took about an hour to write and debug, mostly because Listen Notes rate-limits at about one request per second for the free tier.
For people who do not want to do any of this, there are two simpler alternatives. The first is joining niche Discord servers or subreddits dedicated to specific podcast genres. A r/truecrime or r/techpoweruser thread where people discuss recent episodes surfaces shows that algorithms cannot reach because those shows lack the marketing budget to trend. The second is following individual podcast hosts on social media and watching what they recommend rather than what platforms recommend. Hosts tend to recommend shows they genuinely listen to, which is a different signal than what a platform's engagement-optimizing algorithm serves up. I still use Spotify and Apple Podcasts, but only as playback tools now. The recommendation layer is entirely separate. My current queue comes from the spreadsheet and the API queries, not from any auto-generated playlist. It is more work upfront, but the average episode I finish now has a completion rate above eighty percent compared to maybe forty percent when I relied on platform recommendations. That ratio is the only metric that actually matters.