Working With Amino Acid Polarity in Real Lab Conditions
Most people learning biochemistry get told that amino acids split into two neat buckets — polar and nonpolar — and that's it. The reality is messier. When you're actually running assays or designing peptides, the distinction matters a lot more than any textbook diagram suggests. I've spent years dealing with peptide synthesis, protein purification, and solubility problems, and the polarity classification is where most projects go off the rails without anyone noticing until it's too late.Understanding Polar And Nonpolar Amino Acids
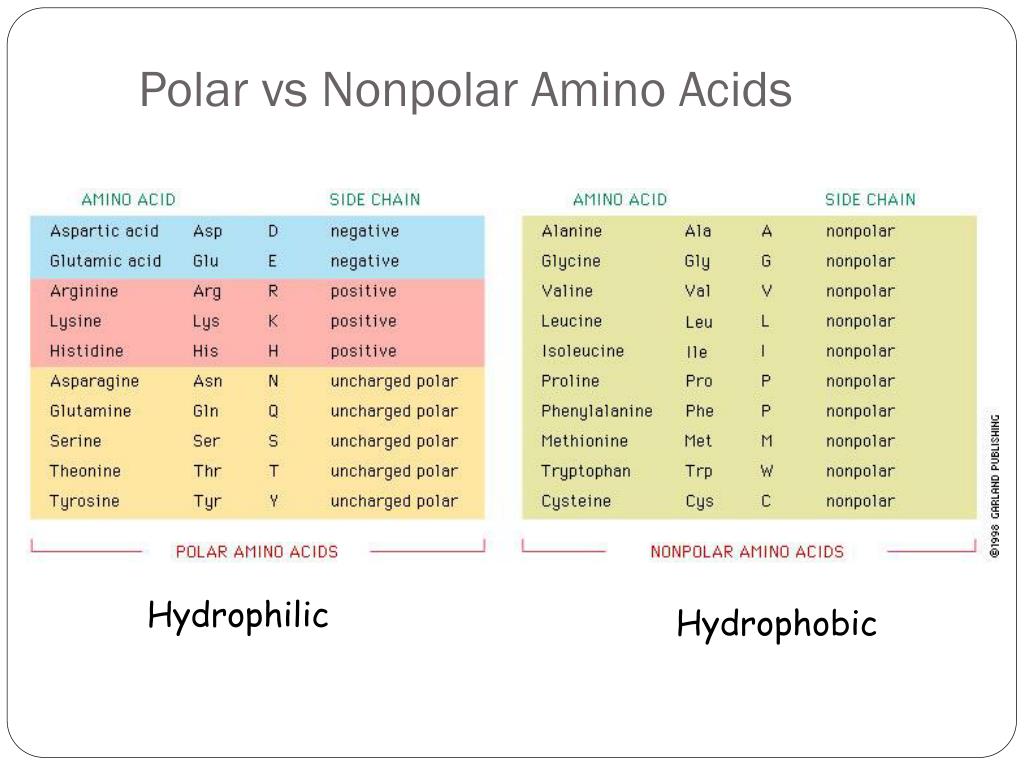
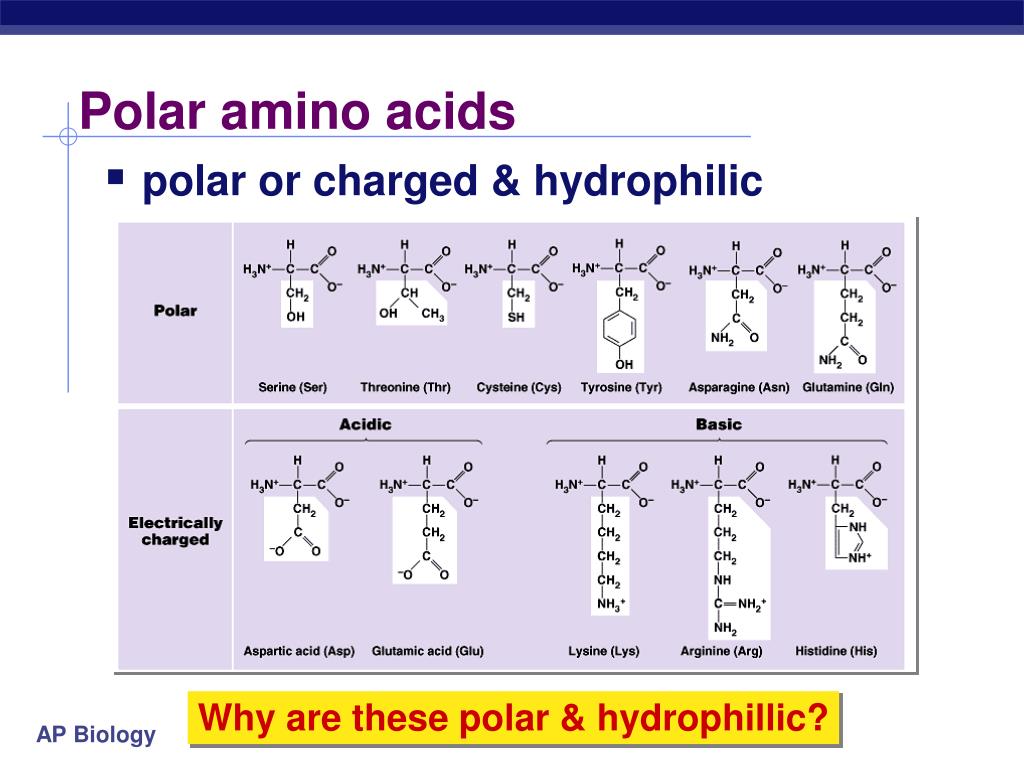
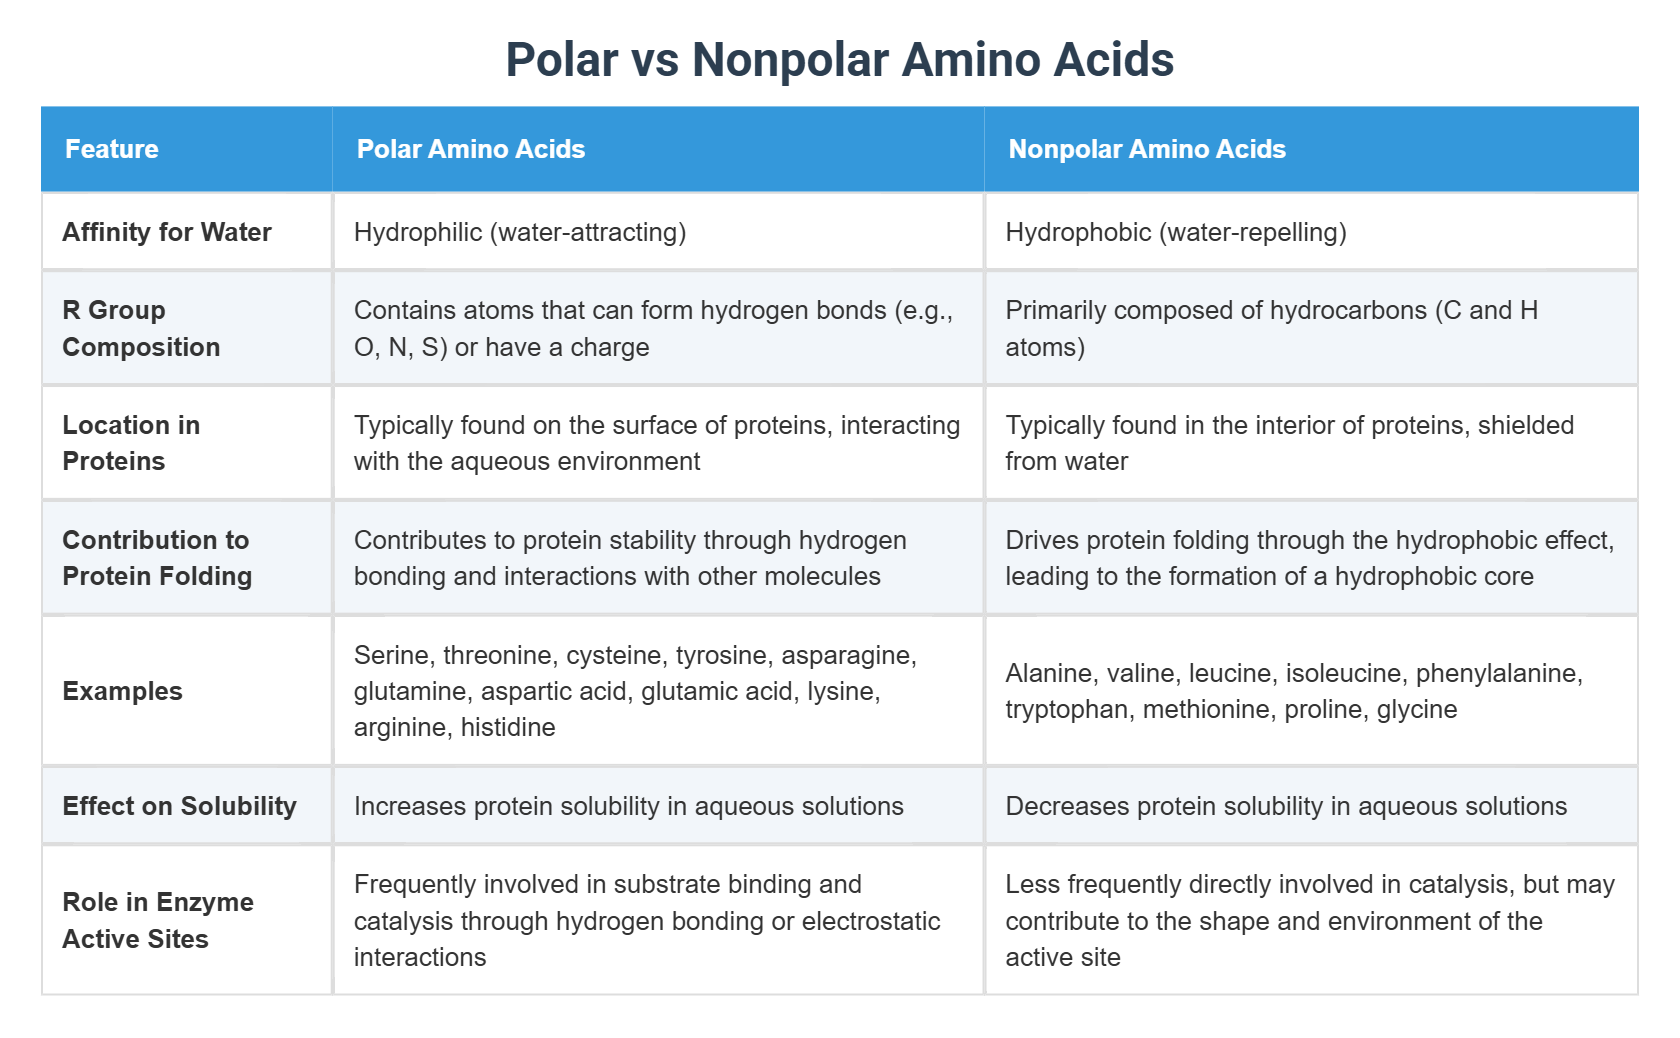
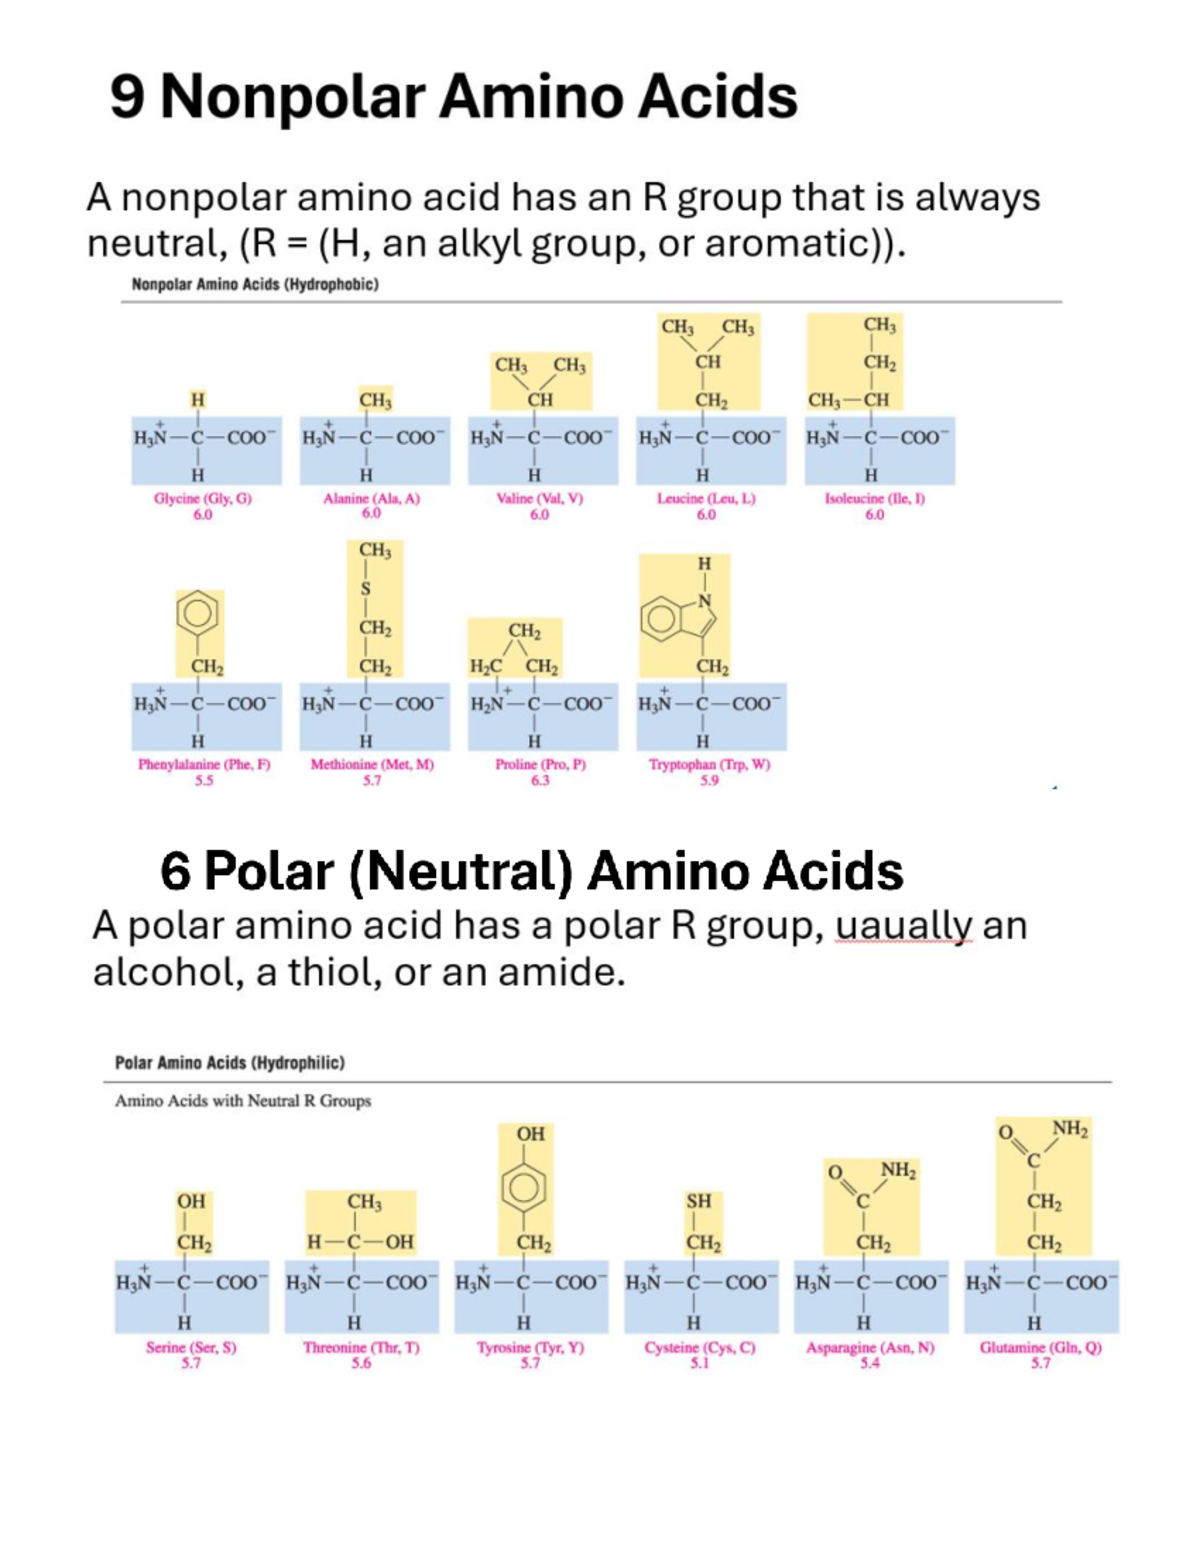
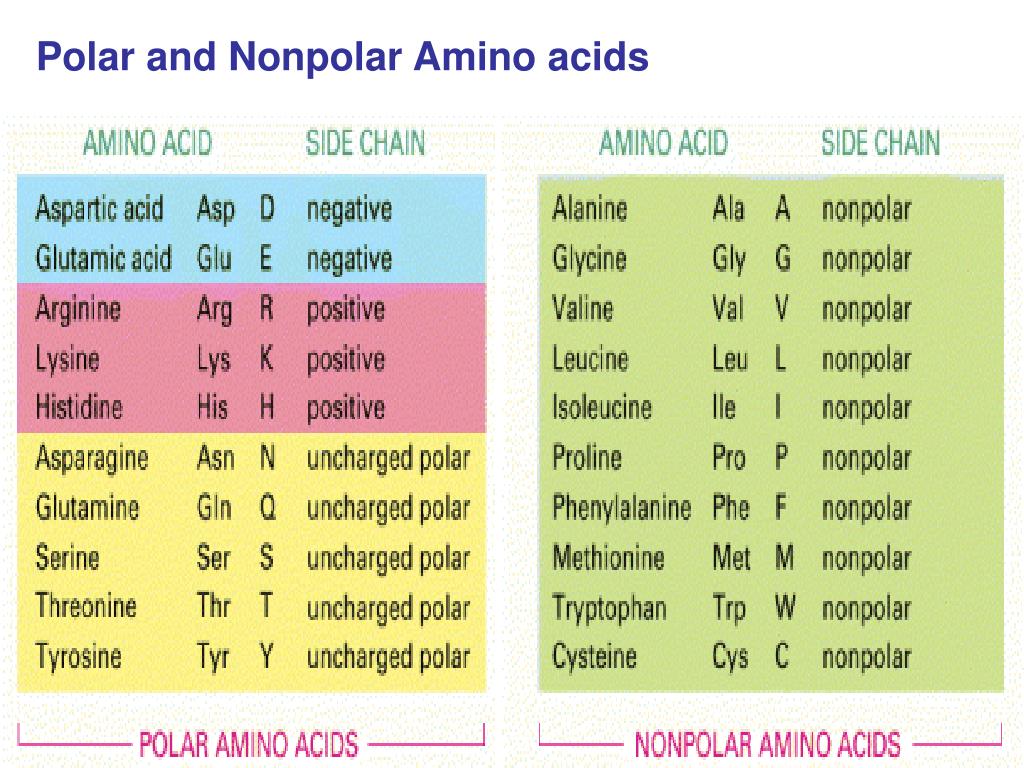
The standard twenty amino acids break down roughly into three groups if you want to be accurate: nonpolar, polar uncharged, and charged (which is its own subset of polar). The nonpolar ones — alanine, valine, leucine, isoleucine, proline, phenylalanine, tryptophan, and methionine — have side chains that don't interact well with water. They cluster together inside folded proteins to avoid aqueous environments. The polar uncharged group includes serine, threonine, cysteine, tyrosine, asparagine, and glutamine. Their side chains can form hydrogen bonds but don't carry a full charge at physiological pH. Then there's the charged set: aspartate, glutamate, lysine, arginine, and histidine. What most people miss is that "polar" doesn't automatically mean "soluble." Tyrosine has a hydroxyl group and is technically polar, but its bulky aromatic ring makes it borderline insoluble in aqueous buffers. I once spent three days trying to keep a tyrosine-rich peptide in solution before realizing I needed to add a small percentage of acetonitrile and adjust the pH down to around 3. That peptide would have precipitated right out during a standard SDS-PAGE loading step if I'd run it at neutral pH. The polarity classification alone didn't predict that behavior.
How This Actually Shows Up in Practice
When you're purifying a recombinant protein, the distribution of polar and nonpolar residues across the surface determines whether it will stick to a hydrophobic interaction chromatography column or pass right through. I remember working on a batch of GST-fusion protein where the construct kept precipitating during the overnight induction. The sequence analysis showed a dense patch of phenylalanine and leucine residues clustered near the N-terminal tag region. Swapping out just two of those residues for serine completely solved the solubility issue. It wasn't a global redesign, just targeted mutations in a small hydrophobic stretch. Cysteine deserves special attention here because it sits in an awkward middle zone. It's classified as polar uncharged due to its thiol group, but it also has moderate hydrophobic character. More importantly, the thiol can oxidize into disulfide bonds, which effectively removes it from the "free polar" category and changes how the whole peptide behaves in solution. If you're working with cysteine-containing sequences and you're not maintaining reducing conditions, your solubility predictions based purely on polarity will be wrong every time.
Practical Implications for Peptide Design
If you're designing a synthetic peptide for any purpose — drug candidate, probe, or research reagent — the hydropathy index is more useful than a simple polar/nonpolar label. The Kyte-Doolittle scale assigns each amino acid a numerical value. Positive values indicate hydrophobic character, negative values indicate hydrophilic character. Alanine comes in at 1.8, which is mildly hydrophobic. Arginine is -4.5, strongly hydrophilic. Glutamine is -3.5. These numbers let you predict behavior much better than categorical labels. Here's a concrete example. Say you need a 15-mer peptide that will dissolve readily in PBS at room temperature. If your sequence has a net hydropathy score above roughly +1.0, you should expect precipitation or aggregation within hours. I usually aim for something below +0.3 for intracellular targets and below -0.5 for extracellular applications where salt concentration is higher. This isn't a hard rule — sequence context and neighboring residues matter — but it's a reliable first filter. One thing that catches people off guard is the behavior of proline. It's nonpolar by classification, but its rigid ring structure disrupts alpha-helices and beta-sheets. If you're modeling protein structure and you treat proline like any other hydrophobic residue, your predictions will be wrong at turn regions. Proline is often found in loops and reverse turns precisely because it destabilizes regular secondary structure. I've seen multiple people overlook this when doing homology modeling and end up with models that look correct on paper but fail in wet lab validation.
Get the Full Details
Charged Residues and Salt Bridges
Aspartate and glutamate carry negative charges at physiological pH. Lysine and arginine carry positive charges. Histidine is the problematic one — its side chain pKa is around 6.0, which means at pH 7.4 it's partially protonated, maybe 10 percent charged. At pH 6.0 it's roughly 50 percent charged. This partial charge state makes histidine behave unpredictably in purification and crystallization. I once ran an ion exchange column at pH 7.4 and got terrible resolution on a histidine-rich protein. Dropping the pH to 6.5 doubled my binding capacity because histidine picked up enough extra positive charge to interact properly with the resin. Salt bridges — the electrostatic interactions between oppositely charged side chains — are another area where textbook explanations fall short. They're stabilizing, yes, but they're also context-dependent. A salt bridge between lysine and glutamate on a protein surface might contribute only 1 to 2 kcal/mol of stability, while the same interaction buried in a hydrophobic core could contribute 5 kcal/mol or more. The dielectric environment matters enormously. When I'm mutagenizing a protein to test stability, I don't just swap a charged residue for a neutral one and assume the effect is straightforward. The surrounding residue network often compensates in ways that are hard to predict.
Common Pitfalls
The biggest mistake I see is treating polarity as a binary property when it exists on a spectrum. Tryptophan is classified as nonpolar, but its indole nitrogen can act as a hydrogen bond donor. In membrane proteins, tryptophan residues often sit at the lipid-water interface because that indole group can interact with both the hydrophobic tail region and the aqueous headgroup region. Calling it simply "nonpolar" misses that functional nuance entirely. Another frequent error is assuming that polar amino acids on a protein surface are always accessible. In practice, surface-exposed polar residues can be buried by post-translational modifications, bound water molecules, or adjacent side chains that fold over them. X-ray crystallography sometimes shows solvent-accessible polar groups that are actually inaccessible in solution due to dynamic conformational changes. If you're relying on a static structure to predict reactivity or binding, you're already working with incomplete information.
What to Do When Things Don't Match the Theory
When your peptide won't dissolve, your protein precipitates, or your chromatography behaves unexpectedly, don't start redesigning the entire sequence. Run a quick hydropathy plot first. Identify the problematic regions. Then make conservative substitutions — swap a leucine for a valine if you need to reduce hydrophobicity slightly, or swap an asparagine for a glutamate if you need to add a charge without drastically changing size. Small changes tend to work better than sweeping alterations because they preserve the overall fold and function. For synthesis purposes, incorporating non-natural amino acids can solve problems that natural polarity classifications can't address. Fluorinated phenylalanine analogs, for example, increase lipophilicity in a predictable way without adding bulk. PEGylated lysine derivatives can dramatically improve solubility for difficult sequences. These aren't cheap options, and they require validation, but they save time compared to iterative round-after-round of failed expression constructs. The polarity of amino acids is a useful framework, not a law. It works well enough for general predictions and educational purposes, but real work demands attention to edge cases, numerical scales, and the specific experimental conditions you're operating under. If you ignore the nuances, the chemistry will correct you, usually in the most inconvenient way possible.