Why Your Mendelian Charts Keep Failing You
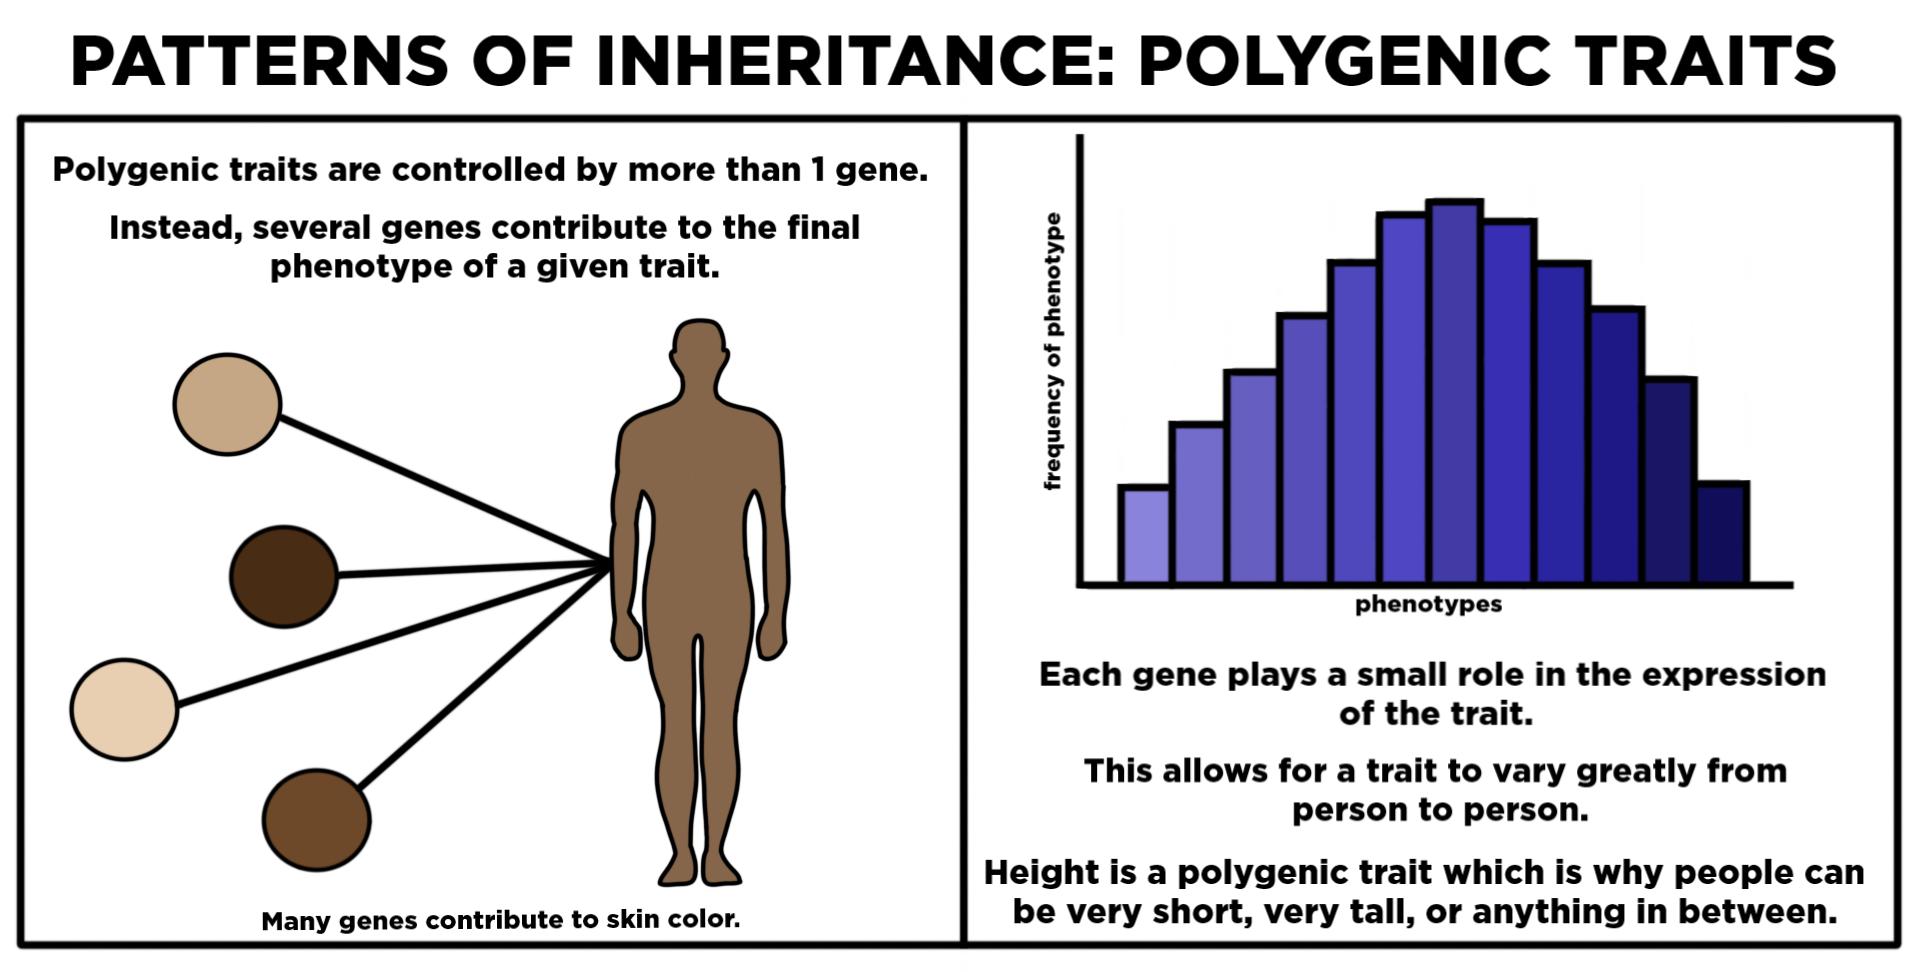
I spent three weeks trying to force a simple Punnett square to work on a dataset for crop yield, and it was useless. The F2 generation didn't produce the neat 3:1 ratio I expected, and I couldn't figure out what I was doing wrong until I realized the trait wasn't controlled by a single gene pair at all. It was polygenic, meaning multiple loci were contributing small effects that added up. I ended up having to map quantitative trait loci instead, which is a whole different workflow than classical genetics. Polygenic inheritance describes any trait that is governed by two or more genes, typically located at different loci across one or more chromosomes. Each gene contributes an additive effect to the phenotype, and because the individual contributions are small, the resulting trait shows continuous variation across a population rather than falling into discrete categories. Height in humans, skin pigmentation, and grain weight in wheat are standard examples you will find in any textbook. What distinguishes it from simple Mendelian inheritance is the shape of the phenotypic distribution. A single-gene trait with complete dominance produces discrete classes, and you can draw clean ratios. A polygenic trait produces a bell-shaped curve because the number of possible allele combinations grows exponentially with each additional locus involved. If three gene pairs each contribute additively, you get seven distinct phenotypic classes in the F2 generation, and as you move to five or six loci, the curve becomes effectively continuous and indistinguishable from normal distribution.
How the Additive Model Actually Works
The most straightforward way to think about it is additive allele effects. Each "contributing" allele adds a fixed increment to the phenotype, and the total phenotype is the sum of those increments across all relevant loci. This is why twin studies and heritability estimates exist in the first place — they try to partition phenotypic variance into genetic and environmental components, and the broad-sense heritability formula H² = V_G / V_P is the baseline calculation researchers use when they encounter this kind of trait. I learned this the hard way when working with a university project on maize ear length. We had initially assumed two gene pairs were responsible, so we set up crosses expecting four phenotypic classes. The data showed a smooth gradient instead. What we discovered was that at least four loci were involved, plus there was a measurable environmental effect from soil nitrogen variation across the field plots. The heritability estimate came out to about 0.65, which meant roughly a third of the phenotypic variance was environmental noise. That environmental component is something beginners consistently underestimate, and it is the reason polygenic traits in real populations rarely match theoretical expectations.
Common Misconceptions That Waste Time
The biggest mistake I see is conflating polygenic inheritance with multifactorial inheritance. All polygenic traits are technically multifactorial if environment plays any role, but not all multifactorial traits are purely polygenic in the way the term is used in classical genetics. Some traits involve gene-environment interactions that change the expression pattern entirely, and the statistical models required for those are fundamentally different. If you are running a GWAS, you need to account for population stratification, cryptic relatedness, and multiple testing corrections like Bonferroni or false discovery rate adjustment, otherwise your significant hits are mostly noise. Another issue is the assumption of purely additive effects. Epistasis, where one gene modifies the expression of another, is common in polygenic systems and it breaks the simple additive model. I had a case where a suppressor locus masked the effect of two contributing genes, and the phenotypic ratios looked random until I mapped the suppressor separately. Without knowing about epistatic interactions, you can spend considerable effort fitting an additive model to data that will never fit well.
Get the Full Details

Practical Approaches for Working With Polygenic Traits
When you need to actually analyze a polygenic trait, the most reliable starting point is a quantitative trait locus mapping experiment. You cross two parental lines that differ in the trait, generate an F2 or recombinant inbred population, genotype the individuals across the genome, and then perform QTL analysis using software like R/qtl or MapManager QTX. This gives you chromosomal regions associated with phenotypic variation and an estimate of the effect size for each QTL detected. For human populations where controlled crosses are impossible, genome-wide association studies are the standard approach. You genotype thousands of individuals at hundreds of thousands of SNP markers and test each marker for statistical association with the trait. The output is a Manhattan plot, and peaks above the significance threshold indicate loci likely involved in the trait. The limitation here is that most common variants identified this way have very small effect sizes, often explaining less than one percent of phenotypic variance individually. You need very large sample sizes to detect them reliably, and even then, the cumulative predictive power of identified SNPs frequently falls short of what heritability estimates would suggest. I once tried building a polygenic risk score from published SNP associations for a complex trait and found that the score predicted only about twelve percent of the variance in my validation cohort, while the reported narrow-sense heritability was closer to forty-five percent. The gap between what GWAS signals capture and the true genetic architecture is called missing heritability, and it remains one of the unsolved problems in this area. Linkage disequilibrium, rare variants not captured by standard arrays, and epistatic interactions all contribute to that gap.
When Polygenic Models Break Down Completely
The additive model works best when gene effects are truly independent and environmental variance is low. In breeding programs with controlled environments and large population sizes, you can make reasonably accurate predictions about offspring phenotypes using estimated breeding values. But in wild populations or complex human cohorts, those assumptions rarely hold. Population structure creates spurious associations, pleiotropy means a single gene affects multiple traits simultaneously, and selective pressure can shift allele frequencies faster than your model accounts for. If you are working with a trait that appears polygenic but shows threshold behavior — where the phenotype is essentially binary despite an underlying continuous liability — you need a liability threshold model rather than a standard quantitative genetic model. Conditions like cleft lip or type 2 diabetes follow this pattern, and treating them as purely additive polygenic traits will give you misleading results. The underlying liability is polygenic and continuous, but the observed phenotype crosses a clinical threshold, which requires completely different statistical handling.
Key Takeaways for Anyone Dealing With This
Polygenic inheritance means multiple genes contribute additively to a continuously varying trait. That is the core definition, but the practical implications are much broader than the textbook summary suggests. Heritability estimates tell you how much of the variation is genetic in a specific population under specific environmental conditions, and they do not predict individual outcomes. Mapping approaches matter because the method you choose determines what kind of genetic architecture you can actually detect. Additive models are useful approximations but they fail when epistasis, rare variants, or environmental interactions dominate the variance. For students learning this material, the useful exercise is to take a supposedly Mendelian trait and test whether it actually behaves one. If your chi-square test consistently rejects the expected ratio and the F2 distribution looks bell-shaped, you are probably looking at polygenic inheritance. Then you move to QTL mapping or GWAS depending on your organism and available resources. For anyone doing applied work, the main takeaway is that polygenic traits require larger sample sizes, more sophisticated statistics, and a willingness to accept that your model will always capture only a fraction of the true genetic variance.