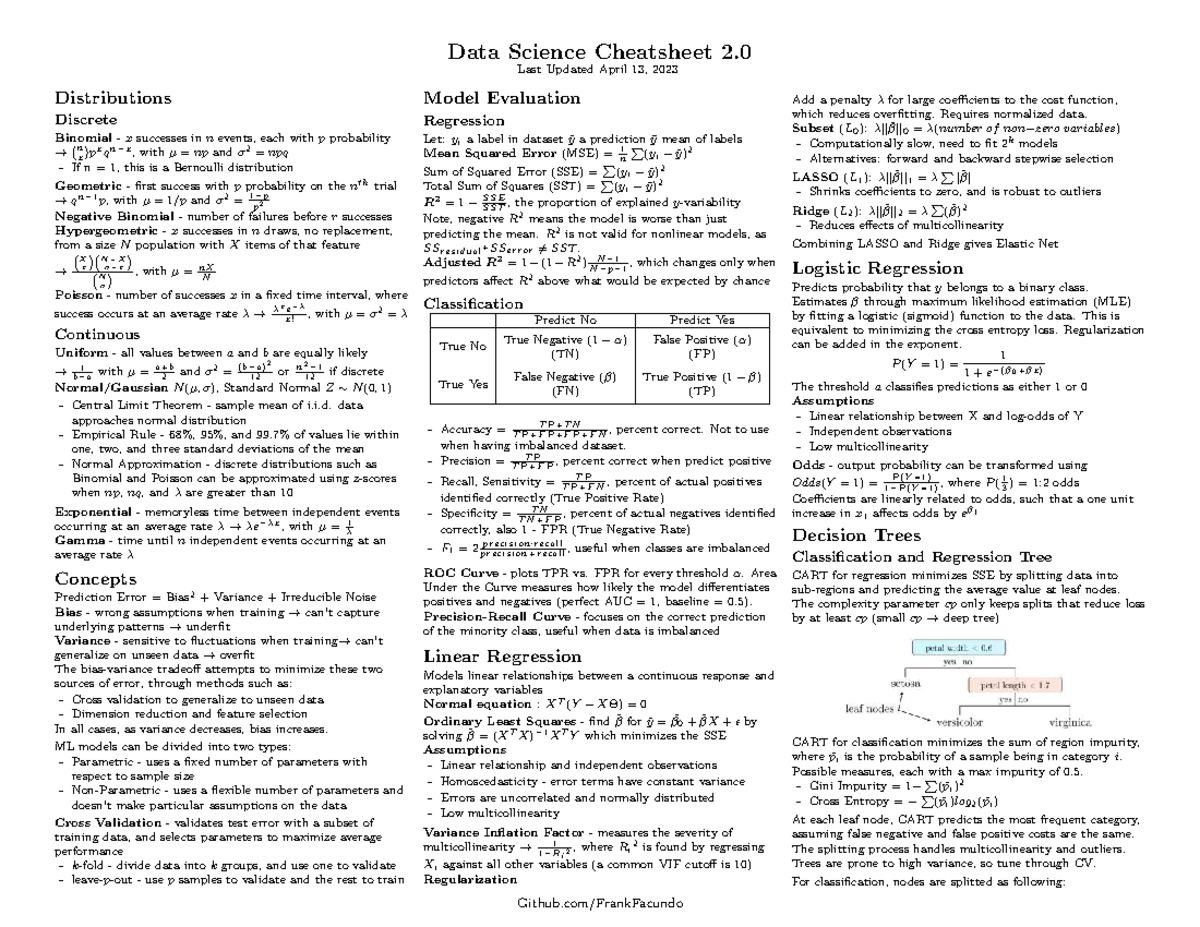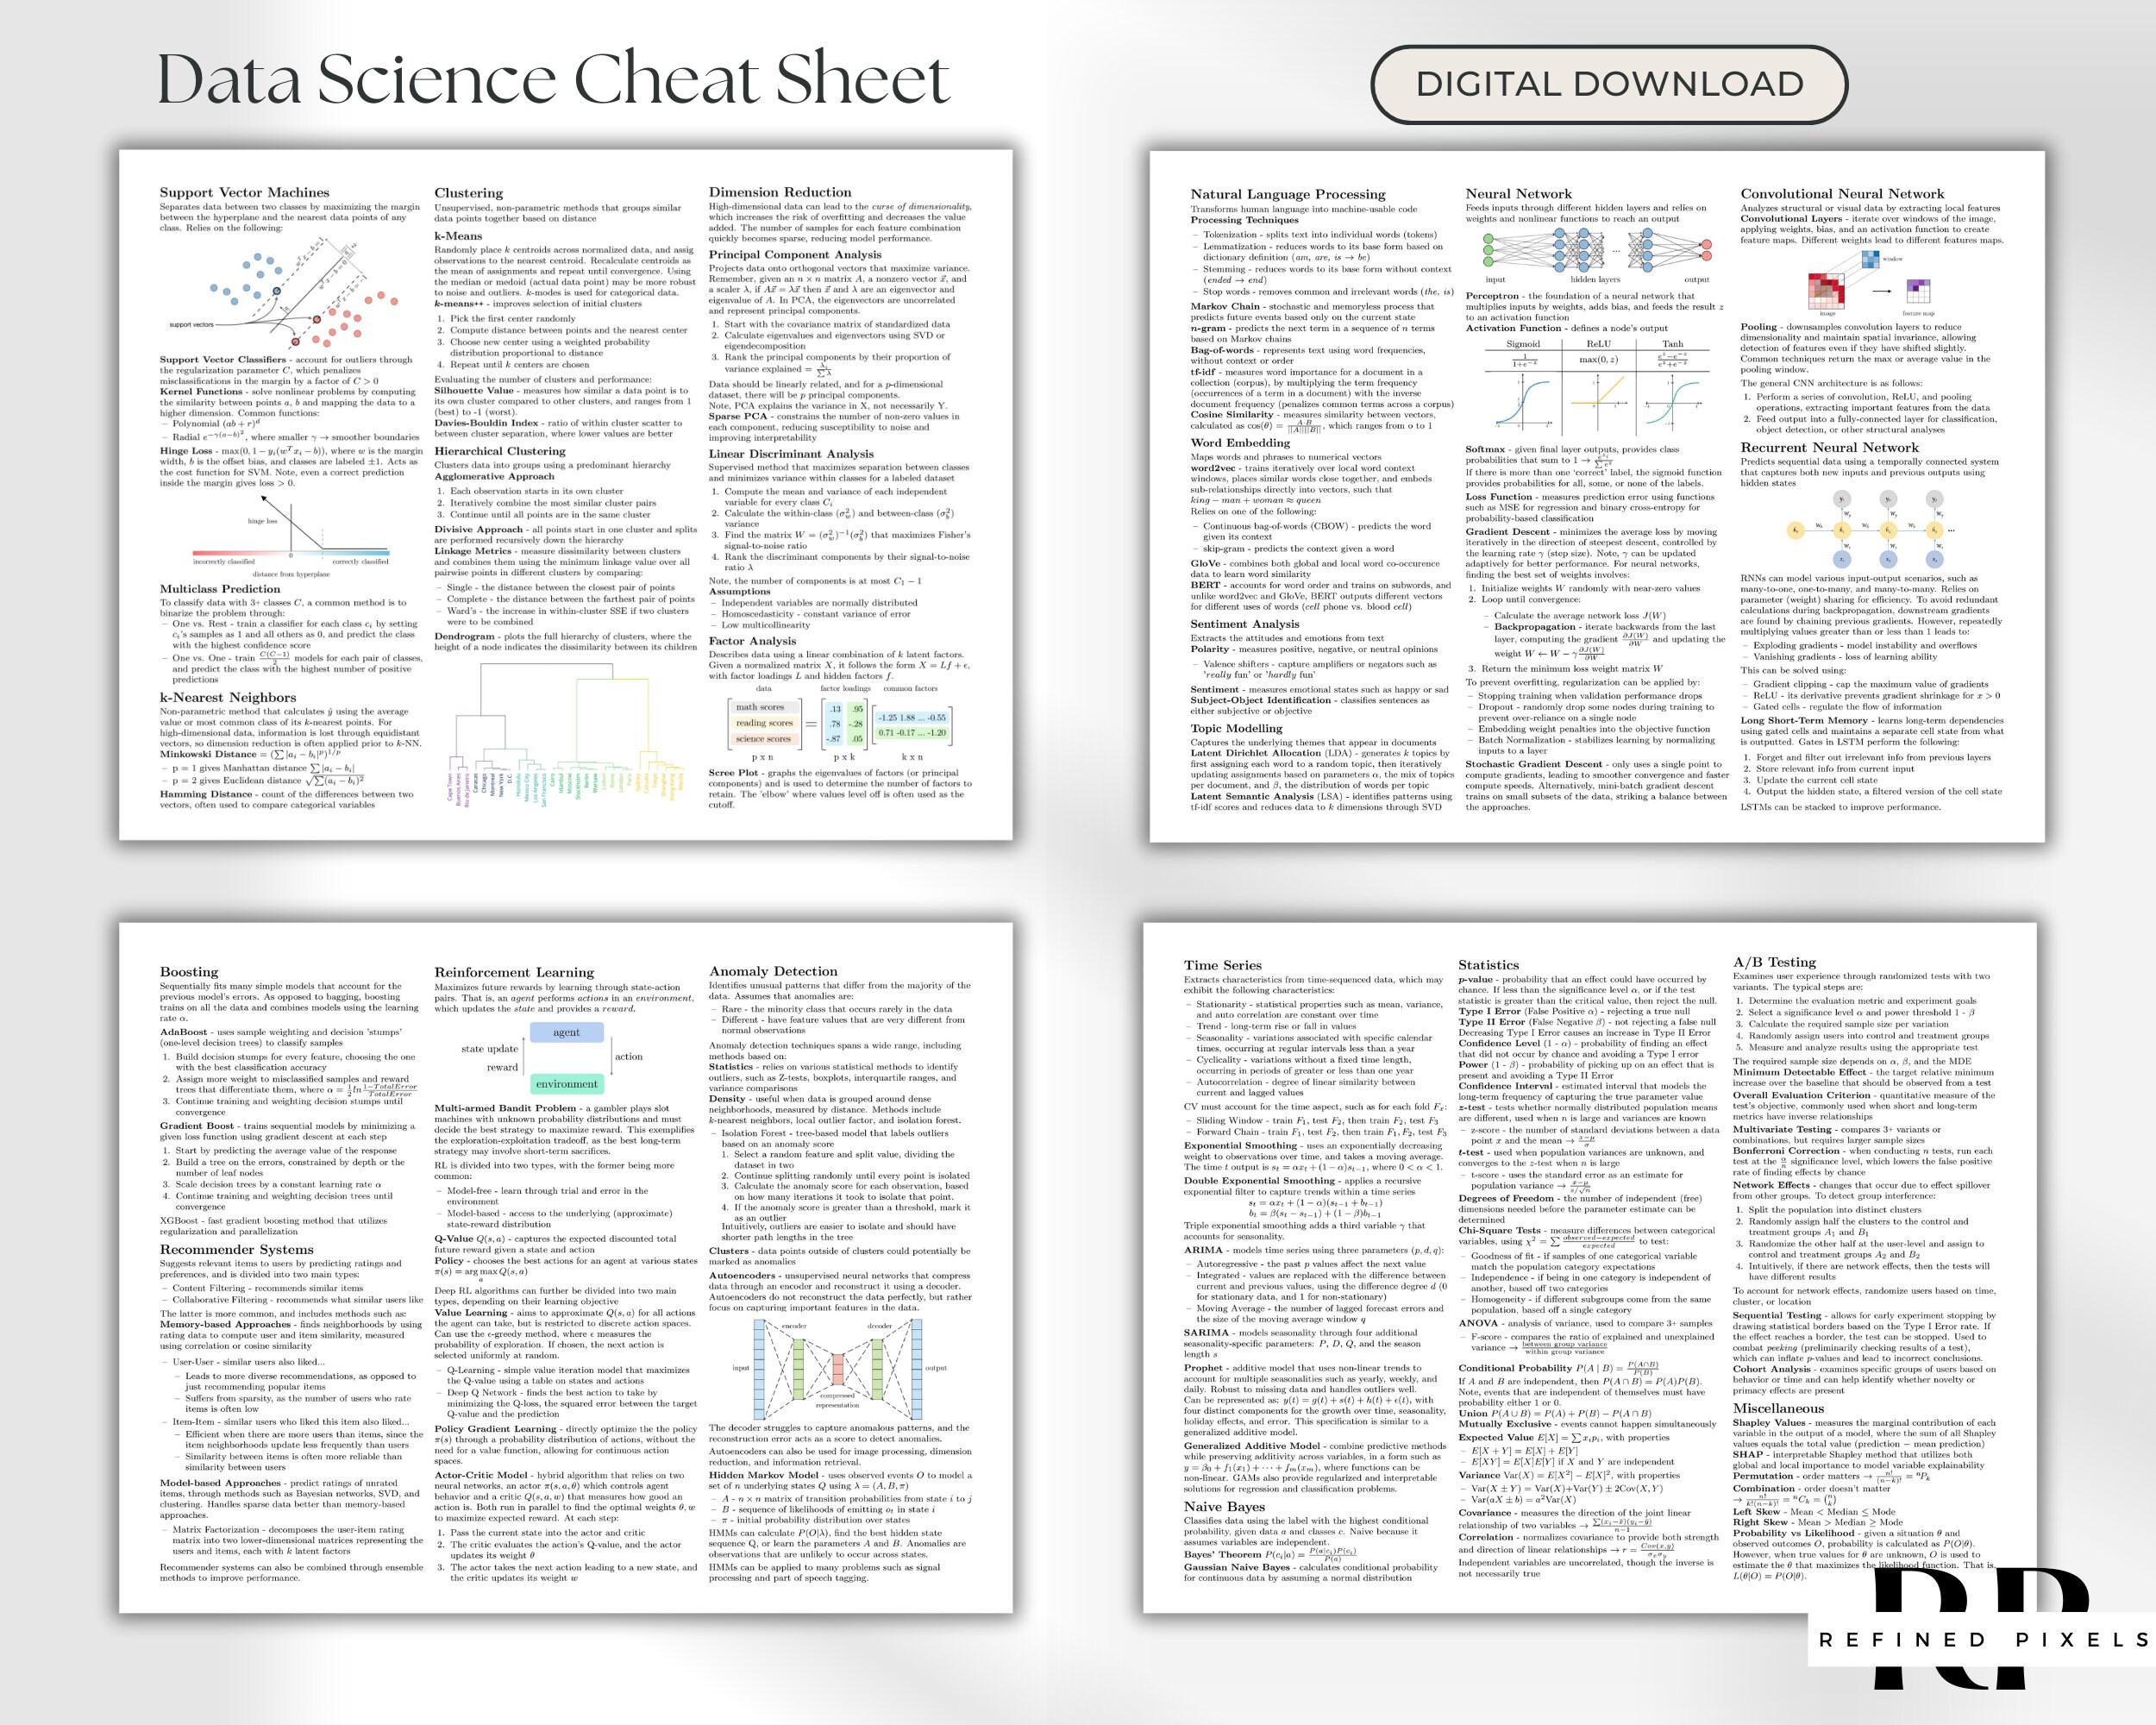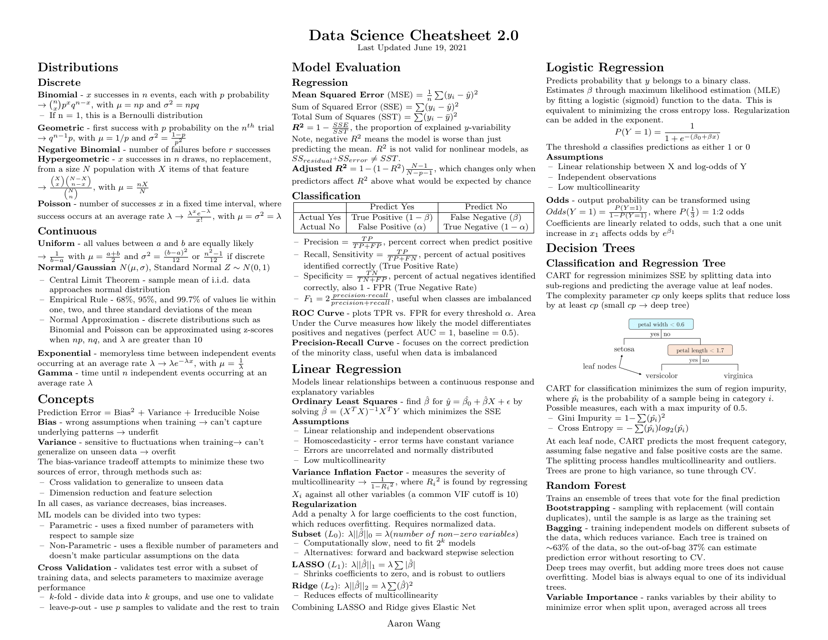
Data Science Cheatsheets Are Useful, But Only If You Use Them Right
I spent years collecting downloadable PDFs and one-pagers for pandas, scikit-learn, matplotlib, NumPy, and SQL. At some point I realized the ones I actually referenced were the ones I'd annotated myself, not the pristine originals from someone else's website. A Printable For Data Science Quick reference is only valuable when you've forced it through your own brain at least once. Here is what I found over the years that actually sticks, and what tends to rot unused in a Downloads folder.
How to Use a Printable For Data Science Quick Reference Without Wasting It
The most common mistake I see is downloading three or four "ultimate cheat sheets" and never opening them again. The second most common is printing them out and leaving them laminated in plastic where nobody can write on them. The third, and the one I did for about a year, is trying to memorize syntax by staring at a wall of code blocks. My method was boring. I picked a single sheet for the library I was actively working with, opened it in a PDF reader, and used the annotation tool to highlight the sections I reached for most. After that, I printed it double-sided on cheap paper and used a black pen to cross out everything I already knew cold. The ones I kept circling back to became the de facto index. This usually cut my lookup time from five minutes to under thirty seconds per operation. Don't collect more than two reference sheets at a time. Your working memory is not a hard drive. It behaves more like a desk that fills up and then you ignore it until it becomes impossible to work on.
What to Include When You Build Your Own
I stopped buying pre-made sheets around 2021. The versions that survived were the ones I could edit when a library updated and broke three functions in a single release. A static PDF from three years ago is basically a time capsule at this point. Pandas dropped the old string accessor behavior, scikit-learn changed how pipelines serialize in some edge cases, and matplotlib moved label positioning logic in a way that silently broke half the examples online. The core content should cover, at minimum, the operations you perform more than once a week. For pandas that means merging strategies, groupby aggregation patterns, and the difference between loc and iloc with concrete shape examples. For scikit-learn it means the estimator interface, pipeline syntax, and the most common hyperparameters for the models you actually use. For matplotlib and seaborn it means figure setup, subplot grids, and common plot customization. Skip the fancy stuff unless you are building dashboards for a living. I keep a personal master template in Markdown, convert it to PDF with pandoc, and archive each version with a date in the filename. When something breaks in production, I can pull the exact sheet that matches the environment version. This matters more than people admit.
Get the Full Details
One Edge Case That Cost Me Half a Day
I had a script that produced different correlation values depending on whether I ran it from a Jupyter notebook or a plain Python file. The Printable For Data Science Quick reference I was using showed the same formula for both, so I blamed floating point precision. It took me about six hours before I realized the issue was the default random state in the test set splitting function and the fact that I was importing a cached results directory from a previous run. The cheat sheet never covered import-side effects or stale caches. I added a small section after that to my own version about execution context, and I never lost a day to that again. This is the kind of thing that does not appear in summary sheets. It appears in the errors.
Counter-Intuitive Things Beginners Miss
Most people treat a reference sheet like a dictionary, looking up functions in alphabetical order. That is slow and inefficient. The faster approach is to treat it like a flowchart, organized by the problem you are trying to solve rather than the library name. When you are stuck, you do not want to find "merge"; you want to find "combine two tables on a shared key with mismatched rows." The label you search for is your problem, not the API call. Another thing that surprises people: a well-made single-page sheet beats a forty-page document every time, assuming it is well organized. Humans do not read dense reference documents under time pressure. We scan them. If the layout forces a visual search, it has failed before you open it. I also recommend against including every parameter for every function. That is documentation, not a quick reference. A quick reference should show the ten parameters that cover ninety percent of daily work, nothing more. If you need the full parameter list, open the docs. That is what they are for.
Where These Sheets Fall Apart
A printable reference cannot replace reading source code when you hit an error inside a library function. It cannot teach you how to debug a shape mismatch during a matrix operation, and it will not explain why a model diverges during training. Those skills come from reading traceback output, running diagnostic lines, and understanding the math at a conceptual level. A sheet is a map, not the terrain. They also become outdated quickly. If your organization pins dependencies to a specific version range, make sure your reference sheet matches that exact range. I once shipped a patch using a syntax from a 2022 reference while the production environment was locked to an older pandas release. The function signature had shifted, and the error was not obvious from the traceback alone. After that, I started including the dependency versions at the top of every sheet.
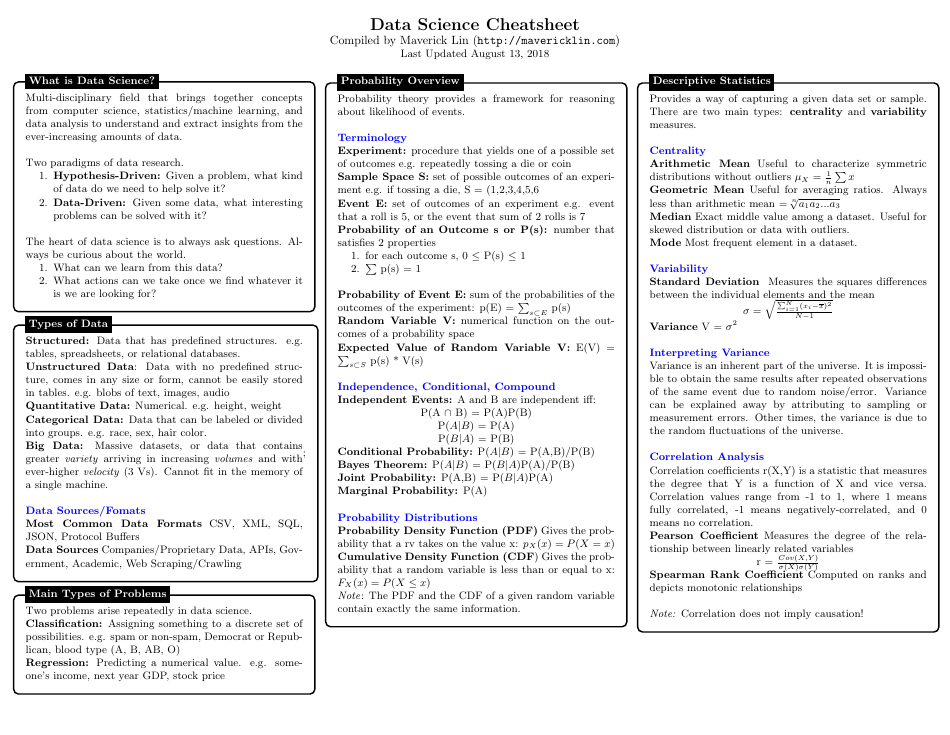
Practical Download and Setup Guidance
There are a lot of free resources available, but the ones I rely on come from a few reliable sources. Official library documentation often has printable reference pages for core APIs. Community-maintained GitHub repositories tend to be more current because contributors update them when breaking changes land. Some data science blogs publish cleaned-up PDFs, but those require a trust check before you adopt the content. When you download a Printable For Data Science Quick sheet, do three things before relying on it. Open it and verify the library versions listed match your environment. Run one example from each major section to confirm the syntax is correct in your setup. Then annotate it with your own notes within the first week, or skip it entirely. If you are short on time, start with a single page for pandas DataFrame operations, a single page for scikit-learn model fitting and evaluation, and a single page for matplotlib common plots. That covers roughly eighty percent of routine work for most analytics tasks. Anything beyond that is specialty material, and specialty material deserves its own focused resource rather than being crammed into a general sheet.
The Short Version of What Actually Works
Pick two or three sheets max. Annotate them immediately. Print a physical copy and mark it with a pen so your brain treats it as a working document instead of a museum piece. Keep the digital version in a single folder with dated filenames. Add a dependency version line at the top. When a library updates and something breaks, fix the sheet, not the other way around. I still keep a handful of printed references on my desk, and I still reach for the PDF reader when I need a clean copy. The habit matters more than the collection. A reference you actually use is worth more than twenty you archive and forget.