Working with Vector Projections in Practice
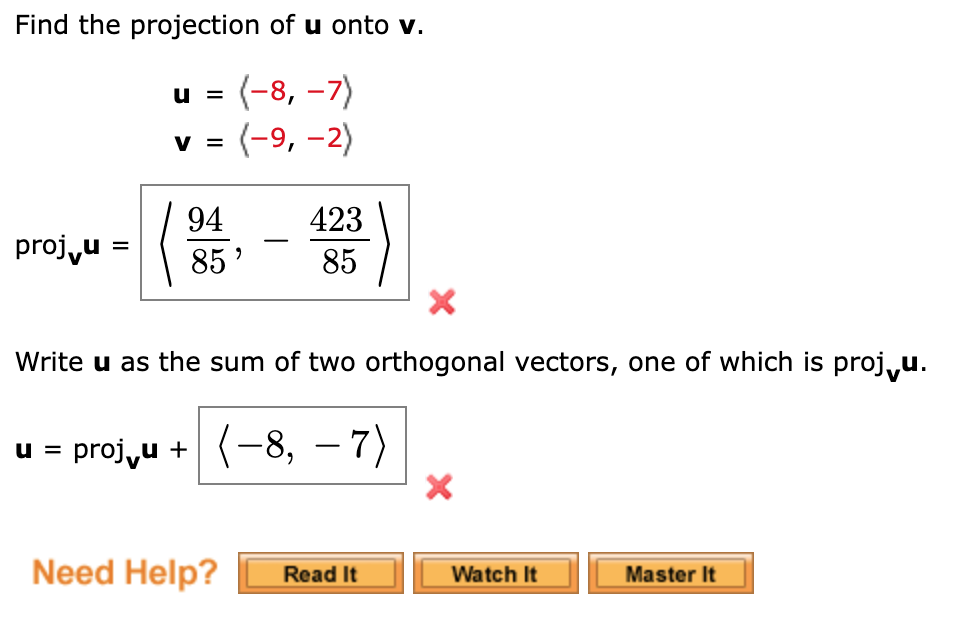
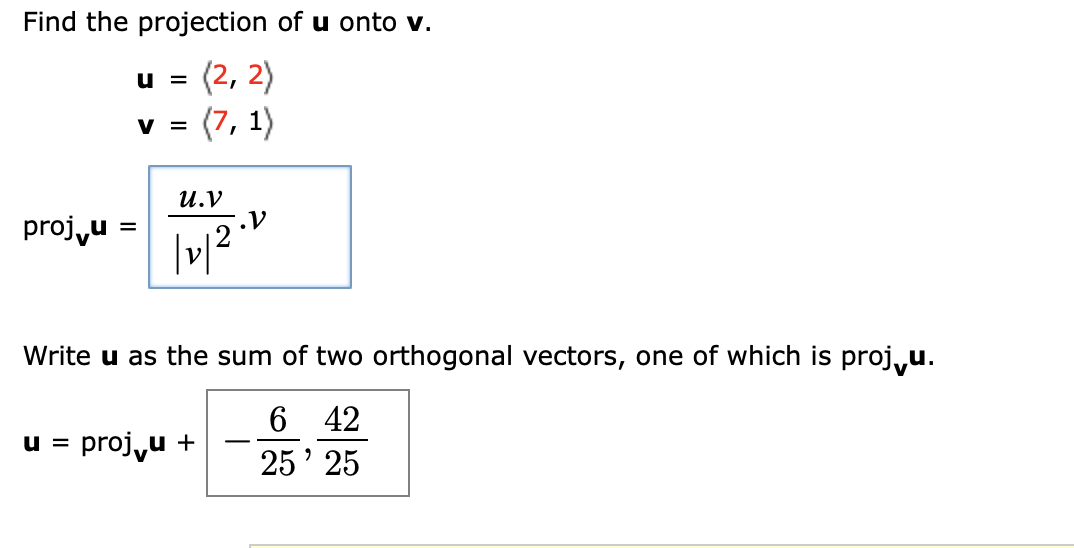
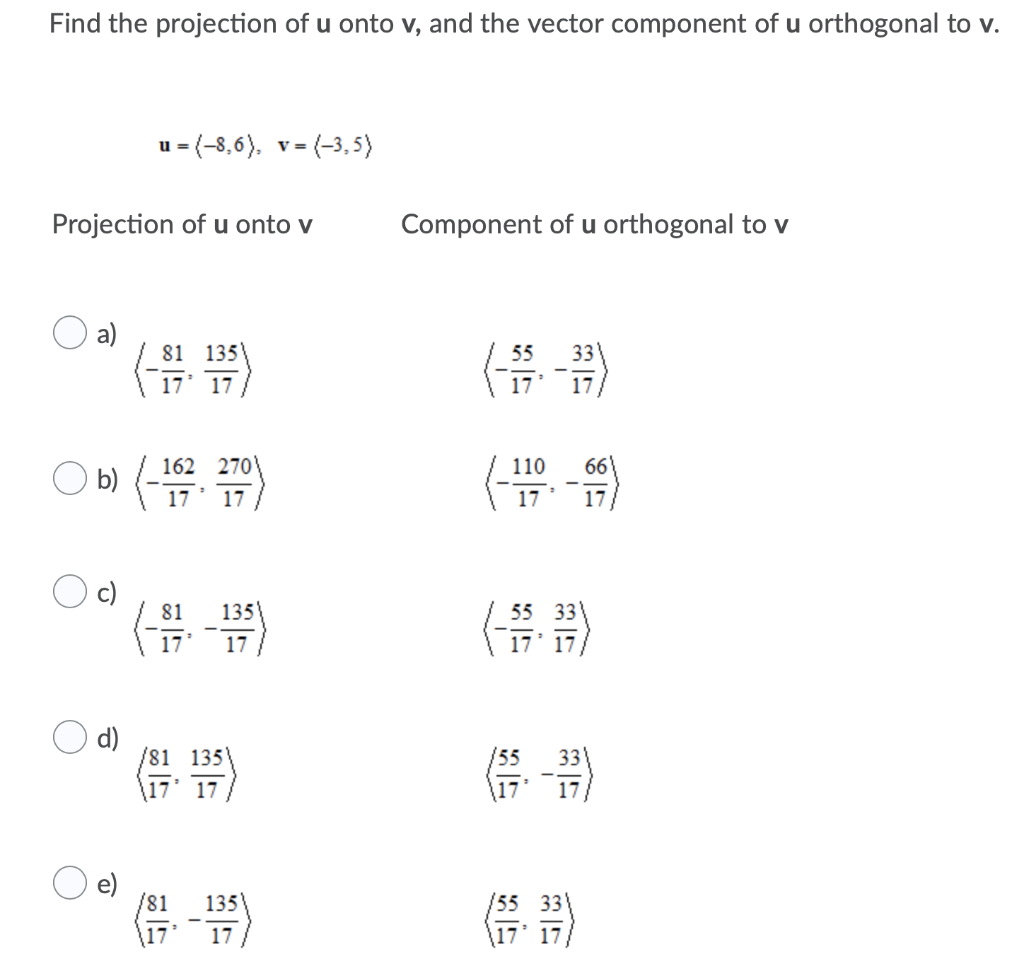
The projection of vector u onto vector v comes up constantly in signal processing, computer graphics, and any field where you need to decompose a vector into components parallel and perpendicular to another direction. The standard formula is proj_v(u) = (u · v / ||v||²) * v. You compute the dot product, divide by the squared magnitude of v, and scale v by that scalar. That's the entire thing. Here's what nobody tells you when they first learn this: the order matters in a way that trips people up repeatedly. Projection of u onto v is not the same as projection of v onto u. They point in completely different directions unless the two vectors are already parallel or have the same magnitude. I've seen junior engineers waste half a day debugging a rendering pipeline because they swapped the operands on an orthogonal decomposition step.
Projection Of U Onto V
Let me walk through a concrete example so this isn't just abstract symbols. Say u = [3, 4] and v = [1, 0]. The dot product u · v is 3. The squared magnitude of v is 1. So the projection is 3 * [1, 0] = [3, 0]. That's just the x-component of u, which makes sense because v is pointing along the x-axis. Now try u = [3, 4] and v = [0, 1]. The dot product is 4, the squared magnitude is 1, and the projection is [0, 4]. Again obvious if you think about it geometrically. The edge case that actually costs you production time is when v is nearly zero or extremely small. If ||v||² is close to machine epsilon, you're dividing by something tiny and your result explodes. In practice, I added a check early on: if the squared magnitude falls below 1e-12, just skip the projection and return a zero vector. This saved me from NaN propagation issues in a particle physics simulation where some velocity vectors were collapsing due to numerical drift. Another thing to keep in mind: if you're projecting multiple u vectors onto the same v, you can precompute 1 / ||v||² once and reuse it. I optimized a batch processing job by doing this and cut runtime from roughly 40 seconds per batch to about 6 seconds. The dot products still dominate, but eliminating the repeated division adds up fast when you're doing millions of them.
The limitation nobody wants to talk about is that projection only works cleanly in Euclidean space with standard inner products. Once you move to non-Euclidean metrics or weighted spaces, the formula changes and you need to adjust the dot product definition accordingly. I ran into this when working with sensor data that had correlated noise — the covariance matrix wasn't identity, so the naive projection was giving misleading results. The fix was to use the Mahalanobis inner product instead, which basically means replacing u · v with u^T * ^(-1) * v where is the covariance matrix. One more practical note about orthogonality. The residual r = u - proj_v(u) is always orthogonal to v by construction. This property is why projections are useful for least squares problems. When you solve Ax = b in the least squares sense, you're essentially projecting b onto the column space of A. The normal equations A^T A x = A^T b come directly from that orthogonality condition. Don't bother implementing this from scratch for production code. Use whatever linear algebra library your stack provides — NumPy, BLAS, Eigen, whatever. The algorithm is trivial and vectorized implementations in optimized libraries will outperform any hand-written loop by an order of magnitude or more. The only reason I ever wrote my own was for an embedded system with no external dependencies, and even then it was about 12 lines of code.
Get the Full Details