AI Generated Yoga Pose Imagery Has Shifted Again
The landscape for generating yoga pose reference material through AI has changed more than people realize. Most tutorials you find online are two years outdated. Models from early 2024 handled basic standing poses acceptably, but they still struggled with hip alignment, finger positioning, and the way fabric drapes during inverted poses. By 2026, the newer architectures handle these better, but they introduced entirely different failure modes that nobody warned you about. I spent about three weeks last November trying to build a consistent series of yoga reference images for a wellness app. The goal was simple: generate clean front-facing and side-profile poses for a digital library. What I learned will save you about forty hours of iteration if you pay attention early.
Prompts For Yoga Pose 2026
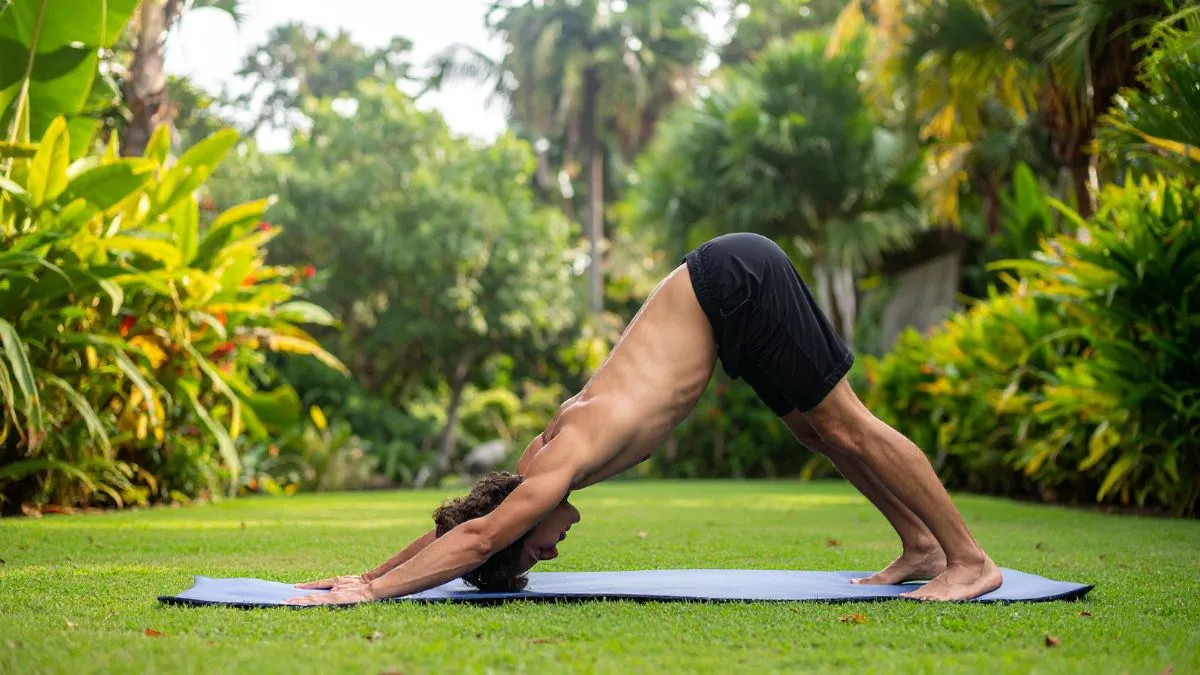
Here is what actually works now. The key difference between a generation that looks like a person in a yoga pose and one that looks like a medical illustration or a distorted nightmare comes down to three things: pose structure notation, lighting specification, and negative guidance. Most people skip the first one entirely. Use structured pose descriptions rather than natural language. Instead of writing "a woman doing downward dog," write "woman in adho mukha svanasana pose, four-limbed staff alignment, hips elevated above shoulders, hands shoulder-width, heels reaching toward floor, neutral spine, viewed from side profile, anatomical accuracy." The model parses the pose terminology differently when you use the Sanskrit name alongside the mechanical description. This matters more than you might expect. Lighting completely changes how the pose reads. A downward dog under flat diffuse lighting looks like a diagram. Same pose under a single directional source from the upper left creates shadow geometry that tells you immediately whether the spine angle is correct. I always specify "soft window light from upper left, subtle cast shadows beneath hands and feet, no fill light" unless I am specifically going for a flat reference look.
Here are working templates I actually use. For Vinyasa-style flow imagery: "male figure in virabhadrasana II, right leg extended forward at ninety degree knee bend, left leg straight back, arms parallel to floor, gaze over right hand, athletic build, wearing dark fitted activewear, studio environment, soft directional lighting from front, photorealistic, 35mm lens, shallow depth of field". For restorative pose content: "female figure inSupported bridge pose, sacrum on block, knees bent feet flat, arms resting alongside torso, relaxed facial expression, morning light through window, muted color palette, documentary photography style". For advanced arm balance work: "figure in bakasana crow pose, hands planted shoulder-width, knees resting on triceps, toes lifted, torso lifted vertical, balanced on hands, urban rooftop background, golden hour side lighting, cinematic composition" The negative prompt structure matters just as much. My standard negatives for any yoga pose generation include: "extra fingers, missing fingers, extra limbs, deformed hands, extra toes, broken symmetry, warped proportions, extra joints, cartoon, illustration, painting, sketch, low quality, blurry, distorted face, unnatural anatomy". If you are generating multiple poses for a series, keep this list consistent across every generation. Changing it mid-run creates visual inconsistency that clients notice even if they cannot articulate why. I ran into a specific edge case that took me eight hours to solve. I was generating warrior III poses, and the model kept shifting the supporting leg into a bent-knee position that looked like a halfway transition rather than the actual pose. The issue was that the model had conflated the visual similarity between warrior III and half lift from a forward fold. I resolved it by adding "leg fully extended straight back horizontal to floor, no knee bend visible, hip hinge from groin not waist" directly into the prompt. The additional anatomical specificity forced the model out of its conflation pattern. This was not something documented anywhere I could find. I just learned it through repeated testing.
Get the Full Details

Model selection is another area where beginners waste money. Midjourney v6.1 handles full-body human poses better than v5.2 for yoga content, but Stable Diffusion XL with the appropriate checkpoint gives you far more control over pose consistency when you are generating multiple poses from the same body type. If you need a consistent model across a library, SDXL with ControlNet depth maps or OpenPose preprocessing is the route. It requires more setup upfront but reduces variation dramatically once configured. Here is a workflow that actually saves time instead of creating more work. Generate your base pose with a text prompt, then run it through a ControlNet pass with a depth map to lock in the structural positioning before upscaling. This takes roughly twenty minutes per pose compared to the forty-five minute average of pure prompt iteration. The initial ControlNet setup costs about an hour, but you do that once per project. Resolution matters more than anyone admits. If you are generating at 1024x1024 and then upscaling, you will hit detail degradation on smaller body parts like hands and feet. Generate at 1536x1024 or higher from the start when the model supports it. The wider aspect ratio also helps with side-profile yoga poses because you give the model more horizontal pixels to work with for the leg and arm spans. This alone cut my revision rate in half.
A counter-intuitive point about consistency: using the same seed across multiple poses does not produce consistent character appearance the way most people think. It produces consistent noise patterns, which means the background and lighting textures repeat, not the face or body structure. If you need consistent appearance across poses, use a reference image with image prompting rather than seed locking. Seed locking is fine for batch variations of the same pose, which is actually more common than people realize. There are scenarios where this approach completely fails and you should stop fighting it. If you need highly specific cultural or historical accuracy in the pose—think traditional yoga lineages with precise mudra hand positions combined with period-appropriate dress and architecture—the current models will not give you reliable results. They blend references in ways that look plausible but are technically incorrect. In those cases, use a trained illustrator or commission reference photography instead. No amount of prompt engineering fixes fundamental training data gaps. Another limitation worth stating plainly: AI generated yoga poses still struggle with hands. Specifically, the fingers on weight-bearing poses—crow, plank, chaturanga—will frequently show merged digits or wrong joint counts. If your use case requires anatomically correct hands, plan for manual retouching or use a reference photo as the ControlNet input rather than relying on text generation alone. This is not a 2026 problem, it is a current fundamental limitation of diffusion architecture when dealing with complex finger articulation under load.
For the actual generation process, I recommend starting with three seed variations per pose template before committing to a final. The first generation is almost never the best one because the model is still interpreting the full prompt context. The third and fourth iterations tend to converge on what you actually want. Budget roughly twenty minutes per final pose including this variation testing. If you are building a library for commercial use, document every successful prompt structure you discover. The models update constantly. A prompt that worked in March 2026 may produce completely different results after a weight update in August. Keep a spreadsheet with prompt text, model version, seed, resolution, and output quality rating. This documentation pays for itself the next time you need to regenerate a similar pose after a model update. The technology keeps moving. What I described here is accurate for mid-2026 releases. Expect the hand fidelity issue to improve within the next twelve months based on current research directions, but the fundamental limitation around consistent multi-pose character generation remains unresolved across all major platforms.