How the recommendation engines actually work underneath the interface
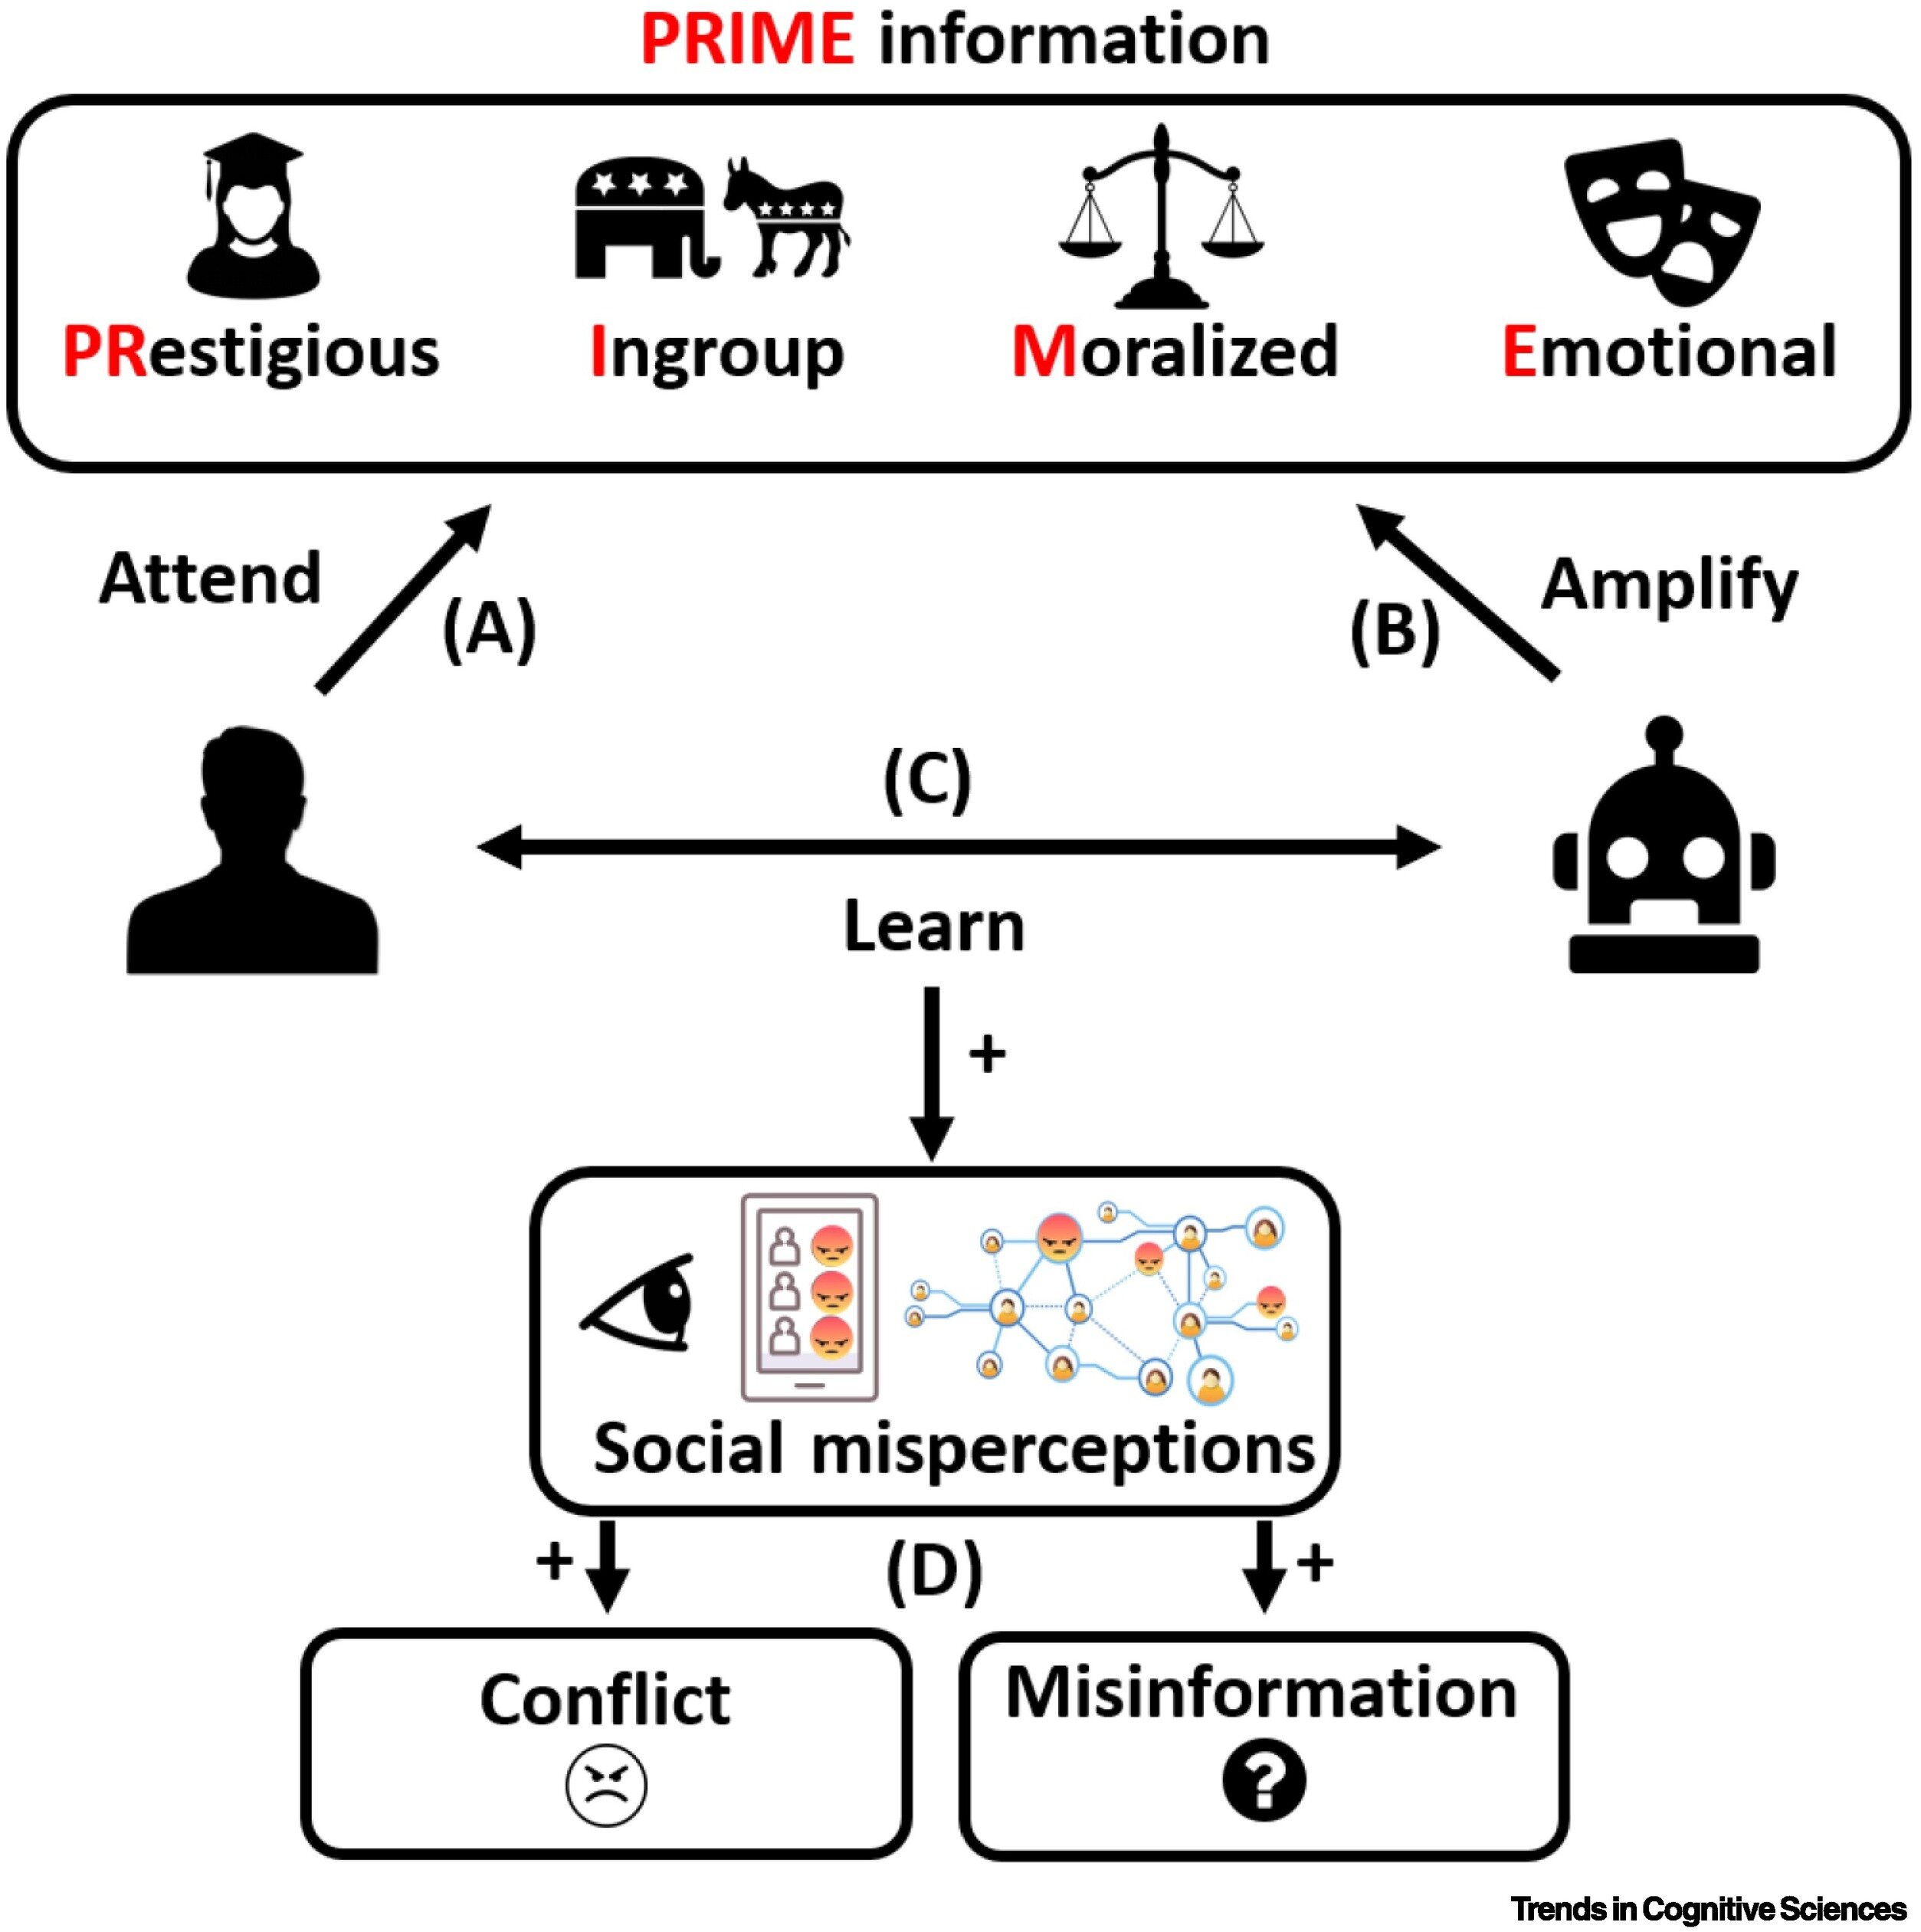
You probably already have a vague sense that social media feeds are driven by something algorithmic, but the gap between knowing that and understanding how it actually plays out in practice is where most people get stuck. When I first started trying to understand why certain content would go nowhere while complete garbage would get picked up, I spent weeks tearing apart what I could observe. The answer wasn't a single mechanism. It was a stack of scoring models working in sequence, each one filtering and reshaping what the layer below produced. The first layer is always retrieval. A user profile sits somewhere in memory with signals about their history, their relationships, and their inferred preferences. When they open the app, the system pulls thousands of candidate items from the pool of everything published recently enough to matter. This is not personalized yet. It is just a broad net. Then a ranking model scores each of those candidates against the user's likely interest level. The final display you see is a cut-down selection ordered by predicted relevance. What most people miss is that the Psychology Behind Social Media Algorithms is really about what the ranking models are trained to optimize for, and that objective function is usually engagement measured in a narrow way. That doesn't mean quality. It means the thing the model learned correlates with continued scrolling. You might watch a video, hover over a post, or tap a comment without liking anything. The model treats those as signals too. It doesn't know if you loved the content. It only knows your attention didn't drop immediately.
What the Psychology Behind Social Media Algorithms Actually Optimizes
Engagement proxies include dwell time, rewatching, sharing, commenting, and sometimes just whether you opened the notification at all. Different platforms weight these differently. TikTok leans heavily on watch completion rate and rewatches. Instagram rewards saves and shares alongside likes. X puts more emphasis on reply velocity and quote tweets. LinkedIn favors dwell time and profile clicks. These differences matter because they shape what type of content the system learns to promote. Here is a practical detail that catches people off guard. The model does not optimize for satisfaction. It optimizes for retention within the app. There is a meaningful difference. A post that makes someone angry might still keep them scrolling longer than a post that makes them feel good and then close the app. That is why outrage content often outperforms calm content even when users claim to hate it. The metric doesn't care about your claim. It cares about what you do. I ran into a specific problem a few years ago that exposed this clearly. I was managing a small creator account and noticed that posts with higher comment counts were getting dramatically more distribution, even when the comments were negative. At first I assumed the algorithm just preferred engagement broadly. Then I tracked the data myself over several months and realized something more precise. Comment threads with replies triggered a secondary notification cascade. Each reply sent a push notification to other participants, bringing them back into the conversation and generating additional engagement that fed back into the ranking model. The system wasn't rewarding "more engagement." It was rewarding a self-sustaining loop of return visits. I adjusted my posting strategy around that insight and stopped chasing generic engagement. Instead, I focused on prompts that generated nested replies from people who weren't already in my follower graph, because that pattern produced a wider second-order distribution than repetitive likes or positive but shallow comments ever did.
Common Pitfalls When Trying to Game the System
One frequent mistake is treating virality as something you can engineer directly. It isn't. Virality is an emergent property of a model picking up a signal it hasn't seen before and testing it across a broader audience. Your job is to create content that produces a strong early signal, not to force distribution. The strongest early signals tend to come from rapid watch completion and immediate interaction within the first hour of posting, so the format itself matters more than any trick. Another pitfall is chasing trends that don't match your actual audience. Trending topics pull in new viewers, but those viewers don't stick around if the content doesn't align with what they originally followed you for. The model notices that mismatch quickly and reduces reach. I've seen accounts try to ride a viral sound or meme format and then wonder why their engagement dropped for weeks afterward. The algorithm had already recategorized them as general entertainment rather than their niche, and the wrong audience didn't convert well enough to sustain the earlier momentum. There is also the false belief that posting frequency alone drives growth. More posts give the model more data points, yes, but only if the new posts produce signals at least as strong as your existing ones. If your newer posts perform worse, you are diluting your account's overall signal profile. Posting four times a week with solid retention beats posting twelve times a week with mediocre numbers. The model averages performance over time, so consistency with quality wins. Random bursts of quantity don't help unless each post clears the engagement bar.
Get the Full Details

What Actually Moves the Needle
Watch time remains the single most reliable predictor across platforms. If people finish your content and often rewatch parts of it, the model interprets that as a strong positive signal. Structure your content to hold attention through the first few seconds and avoid long intros that cause early drops. Even on short-form video, the first two seconds determine whether the rest of the clip gets shown to anyone beyond your immediate followers. Comment quality matters more than comment quantity. Threads with multiple levels of replies keep the notification engine active and bring people back. Questions that ask for opinions or experiences generate deeper replies than requests for simple agreement. Asking someone to share a story or take a position tends to produce more return visits than asking for a thumbs-up reaction. Shareability is another lever. Content that people send to friends or save for later tells the model it has value beyond immediate consumption. Saved posts are especially strong because they indicate the user plans to return. That future return is exactly what the platform wants to encourage, so the model rewards it by showing the content to similar users who are likely to save it too.
Where This Breaks Down
None of this guarantees results. The ranking models are proprietary and change frequently. What worked six months ago may not work today. New features get introduced, test groups shift, and platform priorities pivot without public explanation. Trying to reverse-engineer exact weights is impossible because the underlying models are constantly updated and rarely disclosed in detail. There is also a structural limitation worth acknowledging. Relying on algorithmic optimization means building your presence on land you don't own. When the model changes, your reach can drop sharply regardless of how well you adapted before. That is not a flaw in strategy. It is a fact of the platform. The safer approach is to treat algorithm optimization as a way to grow within the system while building your audience elsewhere, through email lists, direct community channels, or owned platforms that don't depend on third-party ranking models. If you want a tangible starting point, focus on the three things you can control directly. Make sure people watch your content fully. Design it to spark nested conversations. Give it a reason to be saved or shared. Those signals align with what the models reward, and they don't require inside knowledge of the exact scoring formula. Everything else is speculation dressed up as advice.