Why Quadrant Classification Gets Messy In Practice
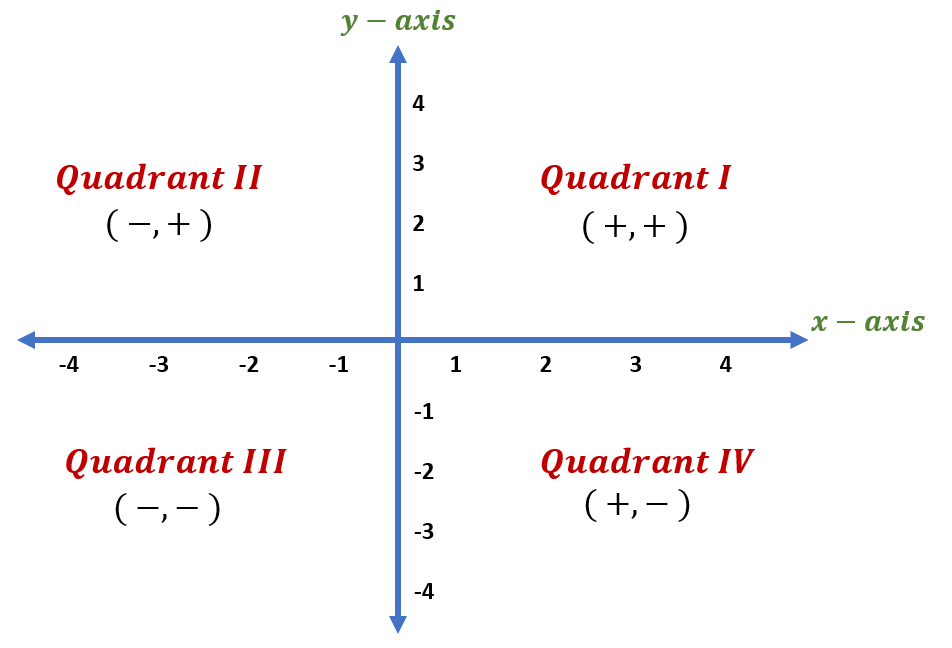
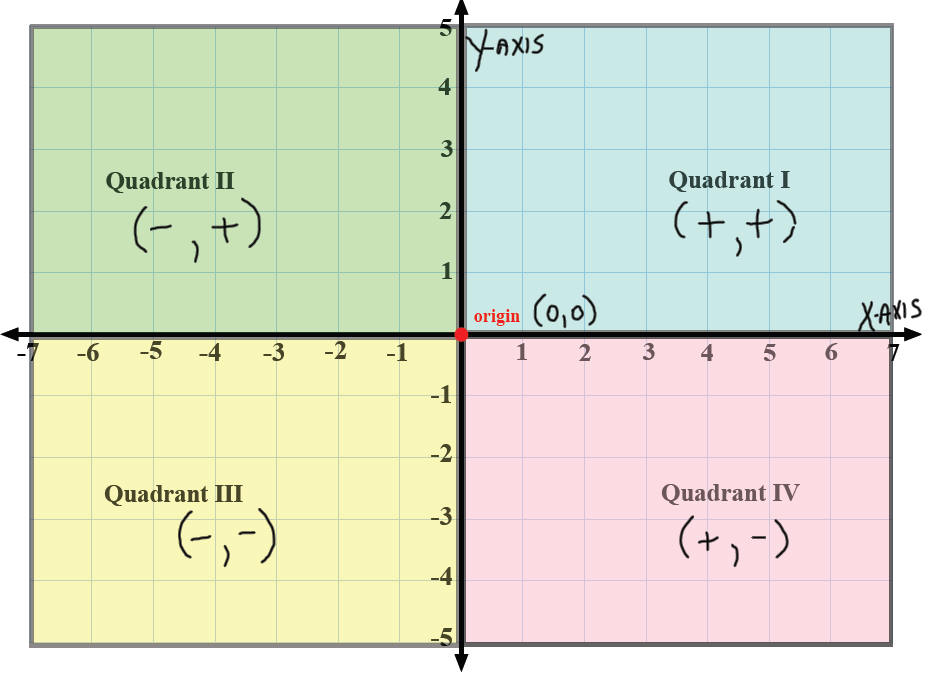
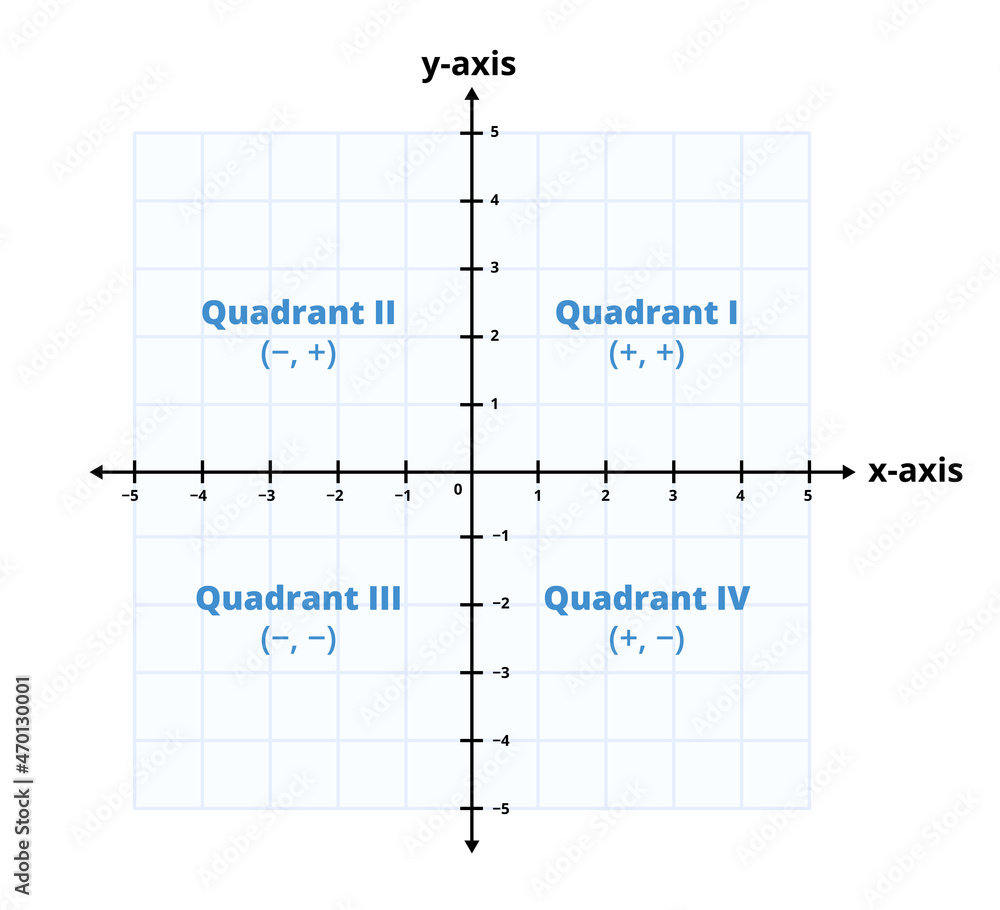
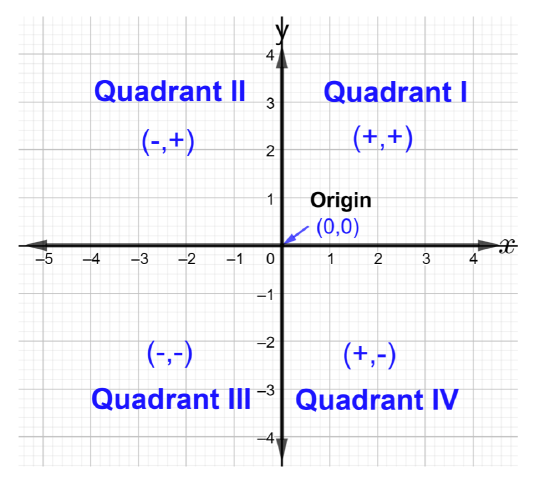
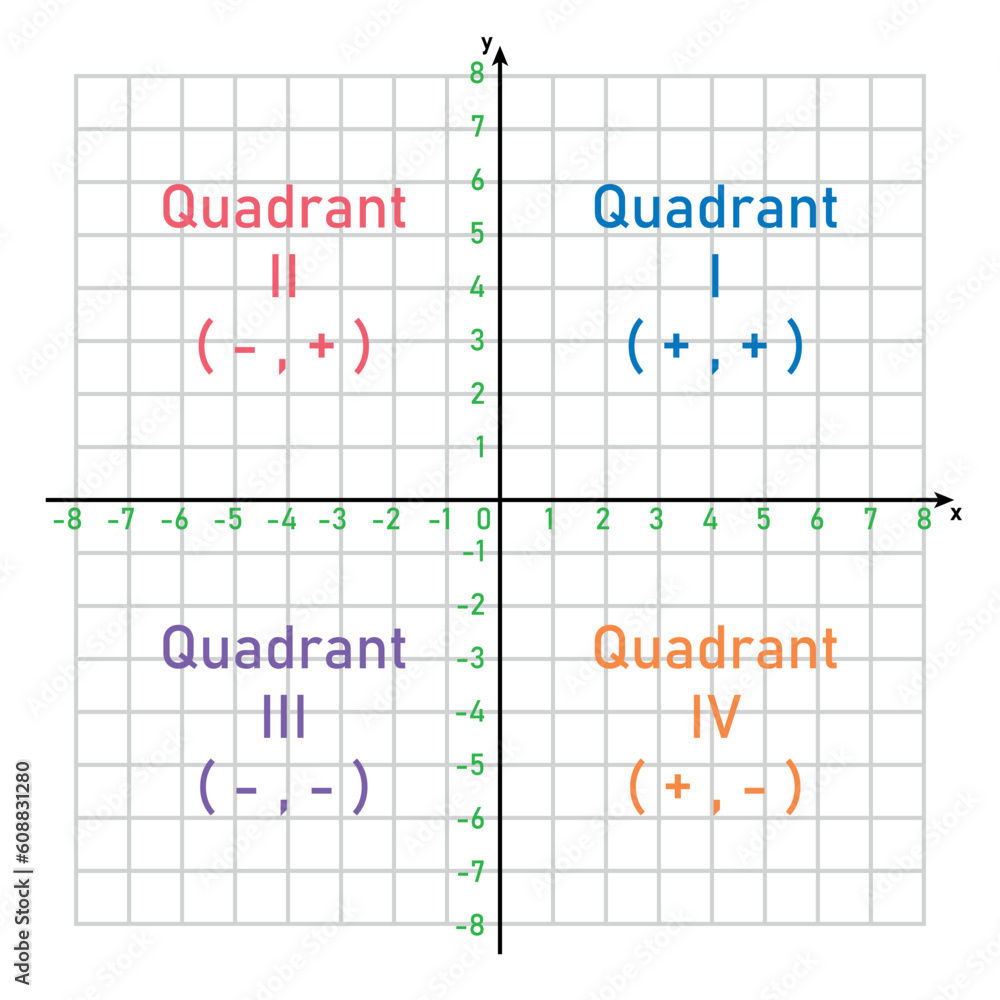
You plot your points. You get the x and y values. Then you realize half your data points are sitting exactly on the axes and technically don't exist in any quadrant. This happens more often than you'd think, especially with real-world data that isn't perfectly distributed. The standard approach is straightforward. Draw a horizontal x-axis and a vertical y-axis crossing at the origin (0,0). These two lines divide the plane into four regions called Quadrants On A Graph. Quadrant I is upper right (positive x, positive y). Quadrant II is upper left (negative x, positive y). Quadrant III is lower left (negative x, negative y). Quadrant IV is lower right (positive x, negative y). Counterclockwise from the top right, always. That's the textbook version. Here's where it gets practical. When I was working with a client's sales vs. growth dataset last year, we had about twelve points landing exactly on either axis. Revenue was zero for some entries, or growth rate was exactly zero. The automated script I wrote to categorize them all threw errors because zero isn't positive and it isn't negative, so the conditional logic had no branch to execute. The workaround was simple but easy to miss: treat zero as its own category before running the quadrant check. I wrote a quick pre-filter that flagged anything on an axis separately, then ran the quadrant classification on the remaining points. Took about twenty minutes to restructure the function instead of debugging why half my points were silently vanishing from the output.
Practical Quadrants On A Graph Workflow
The most common use case I see is business matrices — things like BCG-style product analysis or SWOT-style mapping. You pick two metrics, scale them, plot everything, and look for clusters. The quadrant assignment is the boring mechanical step that everyone rushes through, which is exactly when mistakes happen. My usual process: define the midpoint thresholds for both axes based on your actual data distribution, not arbitrary values. Calculate the median or mean for each metric across your dataset. Use those as your axis crosspoint instead of (0,0). This shifts your quadrants away from the origin to whatever region actually matters for your data. If you're plotting stock price change versus volume, the origin might sit in completely empty space and your quadrants become meaningless. Use the actual median split. Another thing nobody mentions: axis points. A point where x equals exactly zero sits on the y-axis. It belongs to no quadrant. Same for y equals zero. Your classification logic needs to account for this explicitly. In Python it looks like this — check for zero on either axis before checking sign combinations:
if x == 0 or y == 0: return "axis"\nelif x > 0 and y > 0: return "Q1"\nelif x < 0 and y > 0: return "Q2"\nelif x < 0 and y < 0: return "Q3"\nelif x > 0 and y
0: return "Q4" This handles the edge case cleanly. Without it, your quadrant counts will be off and you won't notice until someone asks why the totals don't add up. A more advanced issue that comes up in financial modeling: when your thresholds are themselves derived from the same dataset you're plotting, you introduce a selection bias. Half your points will land above the median by definition, and half below. The quadrant distribution becomes artificially balanced rather than reflecting actual concentration. If your data is skewed — and most real data is — this makes Quadrant I and III look artificially populated while the other two appear sparse. The fix is to use external benchmarks or percentiles instead of raw medians when defining your quadrant boundaries.
Get the Full Details

One more thing worth noting. Some plotting libraries automatically exclude axis points from quadrant calculations. Others silently assign them to the nearest quadrant. You need to check your tool's behavior before trusting the output. I lost a afternoon once to a library that silently pushed axis-aligned points into Quadrant I because it used strictly greater than instead of greater than or equal for its classification logic. The visual looked fine. The numbers were wrong. Quadrant analysis works well for rough segmentation and visual communication. It breaks down when you need precise categorical boundaries or when your data clusters near the axis thresholds. In those cases, consider using density-based clustering or hexagonal binning instead, which handles overlap and edge cases without the hard cutoff problem entirely.