Writing Quadratic Forms in Matrix Notation
You have a polynomial with squared terms and cross-product terms. You want to represent it compactly. That's where the matrix form comes in. It turns out most of these expressions can be written as x^T A x where A is a symmetric matrix and x is your variable column vector. The direct method is straightforward enough. Take each squared term coefficient and put it on the diagonal. For cross terms like bxy, split that coefficient in half and put one half in the off-diagonal position and the other half in the symmetric position. So bxy becomes b/2 in both A[1,2] and A[2,1]. That's really all there is to the basic conversion. Do it mechanically and you'll get it right every time.
Getting comfortable with Quadratic Forms Linear Algebra
I remember working through a problem a while back involving a quadratic form in five variables with a messy interaction term structure. I tried the standard diagonalization approach first and ended up with floating point garbage because the matrix was nearly singular in a way I hadn't expected. What I ended up doing was switching to the eigenvalue decomposition using a numerically stable routine rather than trying to complete the square by hand. The hand-completion method works beautifully on paper but falls apart quickly when your entries are around 10^-4 and you are working with double precision. Computing the eigenvalues and checking their signs gave me the classification I needed without the arithmetic nightmare. If your matrix is larger than three or four variables and the coefficients aren't clean integers, just go straight to eigenvalue analysis and skip the manual completion of squares. Here is a concrete example to walk through. Consider the expression 3x^2 + 4xy + 5y^2. The diagonal entries are 3 and 5. The cross term coefficient is 4, so you split it to 2 and 2. The matrix is [3, 2; 2, 5]. Multiply it out and you recover the original expression. Nothing fancy about it. Another thing people routinely mess up is the ordering of variables. Make sure x is always the same column vector in both the row and column positions. Swap them in your head and you will transpose the matrix incorrectly and get a different quadratic form entirely. I have seen this happen more often than I care to admit in homework submissions.
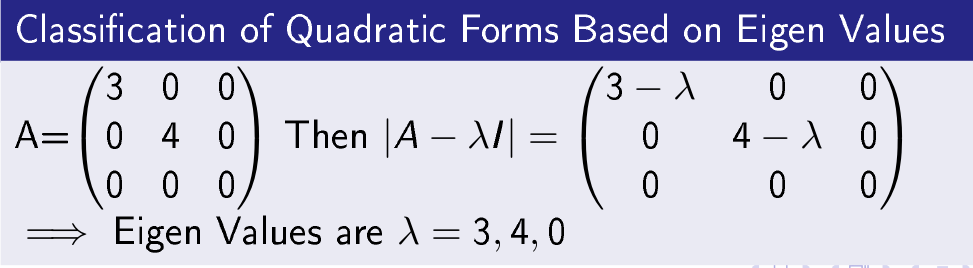
The classification of a quadratic form depends entirely on the eigenvalues of its associated symmetric matrix. Positive definite means all eigenvalues are strictly positive. Negative definite means all are strictly negative. Indefinite means you have a mix of positive and negative eigenvalues. Semidefinite cases sit right on the boundary with at least one zero eigenvalue. The easy way to check is to compute the eigenvalues numerically or use Sylvester's criterion if you are working with small matrices by hand. Leading principal minors give you the answer for positive definiteness without ever touching an eigenvalue calculator. First minor positive, second minor positive, and so on. All of them must be positive. One counter-intuitive point that trips people up: the matrix representation is not unique unless you enforce symmetry. You can construct a non-symmetric matrix that still produces the same quadratic form when you compute x^T A x, but the off-diagonal entries will be wrong in a way that cancels out during multiplication. Always symmetrize your matrix by averaging A and its transpose. That removes any ambiguity and makes the eigenvalue interpretation valid. Working with a non-symmetric A and then claiming eigenvalue properties apply to it is a mistake that shows up in grading feedback pretty regularly. Constrained optimization is where quadratic forms become actually useful. Think about maximizing or minimizing x^T A x subject to ||x|| = 1. The extrema occur at the eigenvectors and the values are the corresponding eigenvalues. This is not a theoretical curiosity. It comes up in principal component analysis, in elasticity theory, and in various control problems where you need to understand the energy landscape of a system. If you are doing any of that work, you will be computing Rayleigh quotients regularly. The quotient x^T A x divided by x^T x gives you a scalar that sits between the smallest and largest eigenvalues for any nonzero x. That bound is useful on its own.
Get the Full Details

There are limitations you should keep in mind. Quadratic forms only capture second-order behavior. If your actual function has significant higher-order terms, approximating it as a quadratic form will give you wrong answers away from the expansion point. Taylor expansions do this kind of thing constantly, and the region where the quadratic approximation is reasonable can be surprisingly small depending on the curvature. Also, for large sparse systems, forming the full dense matrix explicitly can waste memory and slow things down unnecessarily. In those cases, working with the sparse structure directly or using iterative methods like Lanczos is usually better than building the complete matrix and running a dense eigensolver. Change of basis is another practical application. If you substitute x = Py into x^T A x, you get y^T (P^T A P) y. The new matrix is P^T A P. When P is orthogonal, this is just a similarity transformation and the eigenvalues stay the same. When P is not orthogonal, you are doing a congruence transformation, which preserves inertia by Sylvester's law but changes the actual eigenvalue magnitudes. Confusing congruence with similarity is a common error. They look similar algebraically but have different implications for what stays invariant. If you want to practice, start with simple 2x2 and 3x3 forms where you can verify by hand that expanding x^T A x recovers your original polynomial. Then move to problems where you classify the form using both the eigenvalue method and Sylvester's criterion and confirm they agree. After that, try a constrained optimization problem where you compare the Lagrange multiplier approach with the eigenvalue result. The agreement between the two methods is a good sanity check that you have set things up correctly.
For implementation, any standard numerical library will handle the symmetric eigenvalue problem reliably. In Python, numpy.linalg.eigh is the right choice because it exploits symmetry. In MATLAB, eig works but eig with a symmetric input is fine too. If you are writing code that runs repeatedly on matrices of varying size, caching the symmetric property and using the dedicated routine saves time and reduces rounding error compared to a general purpose solver. The geometry is worth keeping in mind alongside the algebra. A positive definite quadratic form equal to a constant describes an ellipsoid. Negative definite does the same shape but with the sign flipped. Indefinite forms give you hyperboloids or saddle surfaces depending on the signature. Visualizing these in two or three variables helps build intuition that the eigenvalue tests alone do not provide on their own. When you can see that the cross term tilts the ellipsoid axes away from the coordinate directions, the whole off-diagonal splitting story stops feeling arbitrary.