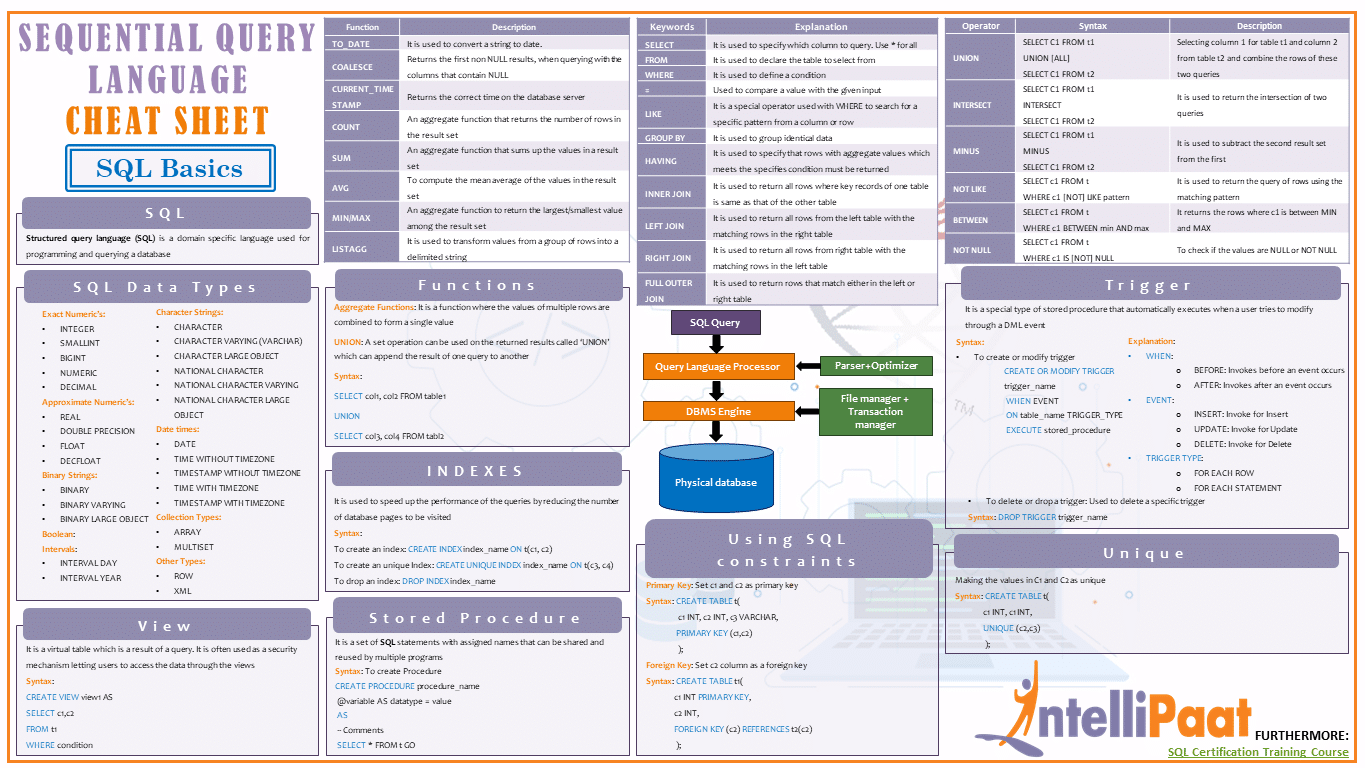
SQL Cheat Sheet for Everyday Use
A query language cheat sheet is just a one-page reference that lets you look up syntax without opening the documentation. Most people keep one pinned to a second monitor or keep it bookmarked. The truth is you don't need anything fancy. You need the basic clauses, the grouping rules, and the aggregation functions that come up 90 percent of the time. Everything else you can figure out by looking it up once and remembering it happened. The standard SELECT statement starts with the columns you want, then the table, then the conditions. WHERE filters rows before grouping. HAVING filters after grouping. That distinction matters more than most people realize. You can't put an aggregate function in a WHERE clause. It will error out. Use HAVING instead. For JOINs, LEFT JOIN keeps every row from the left table and matches where possible. INNER JOIN drops rows that don't have a match on either side. People default to INNER because it's simpler, but you lose data quietly. I've seen reports generated from INNER JOINs where 40 percent of the records disappeared because the key didn't match. The query ran fine. The output was just wrong.
CASE expressions handle conditional logic inside a query. They look like this: CASE WHEN condition THEN result ELSE other END I use them for pivoting status values into readable labels, or for categorizing timestamps into buckets without doing it in application code. Subqueries in the FROM clause are basically temporary result sets. You can reference them by alias and join against them. That's how you stack logic without building actual temporary tables.
LIMIT and OFFSET control pagination. LIMIT 20 OFFSET 40 gives you the third page of results at 20 items per page. Deep pagination gets expensive fast. Once you go past a few thousand rows, the database has to scan and discard more rows to reach the offset. That's why production systems often use keyset pagination instead, ordering by a unique column and using WHERE id > last_seen_id. I had a job once where we used a SQL query language cheat sheet we kept updating in Google Docs. We hit a wall with MySQL's GROUP BY behavior before version 5.7 defaulted to ONLY_FULL_GROUP_BY. If you had an old config, queries like SELECT user_id, email, COUNT(*) FROM users GROUP BY user_id would run without errors even though email wasn't aggregated or grouped. The results were non-deterministic. You'd get one value for email one run and a different one the next. It took me three days to track down a report that was subtly wrong because the database was picking random email values for each user_id group. The workaround was to enable ONLY_FULL_GROUP_BY on the server or wrap email in an aggregation function like MAX(email). I added that to the cheat sheet. Window functions change how you think about grouping. ROW_NUMBER() assigns a unique row number within a partition. RANK() assigns the same rank to ties but skips the next number. DENSE_RANK() assigns the same rank to ties and continues consecutively. These three look similar and are frequently confused. Use them when you need rankings, running totals, or moving averages without collapsing rows.
Get the Full Details

INDEX hints aren't something I recommend relying on. They lock your query into a specific access plan and break when schema changes. But knowing they exist helps when you're debugging a query that's doing full table scans on a large table and you need temporary relief while someone figures out why the index isn't being used. Parameterized queries are non-negotiable for anything touching user input. String concatenation for query construction is how injection happens. Most frameworks have built-in parameter binding. Use it. I've audited codebases where the "cheat sheet" had a warning at the top: never build SQL strings with .concat() or format strings. Some limitations are worth noting. A cheat sheet will never replace understanding your query execution plan. You can memorize every JOIN type and still write a query that scans millions of rows because of a missing index or a bad type conversion. EXPLAIN PLAN is faster to learn than most people expect and it reveals the actual problem. Cheat sheets also don't help with dialect differences. PostgreSQL does things differently from MySQL, which differs from SQL Server. A cheat sheet for one will mislead you on another. I keep separate notes for Postgres and MySQL at work. The syntax for string concatenation alone is different between them.
If you want a downloadable version, I keep a minimal one at query-language-cheat-sheet.pdf. It covers SELECT, WHERE, JOINs, GROUP BY, HAVING, ORDER BY, LIMIT, CASE, subqueries, common window functions, and a short section on transaction isolation levels. It's aimed at SQL-92 compatible databases. If you're using MongoDB, BigQuery, or something else, the concept transfers but the syntax won't match. The best cheat sheets stay under two pages. Anything longer stops being a reference and becomes a textbook. You won't read it during a debugging session. Keep it tight. Update it when you hit something new enough times that you wish you'd remembered it from the last time.