Why your reading scores are lying to you
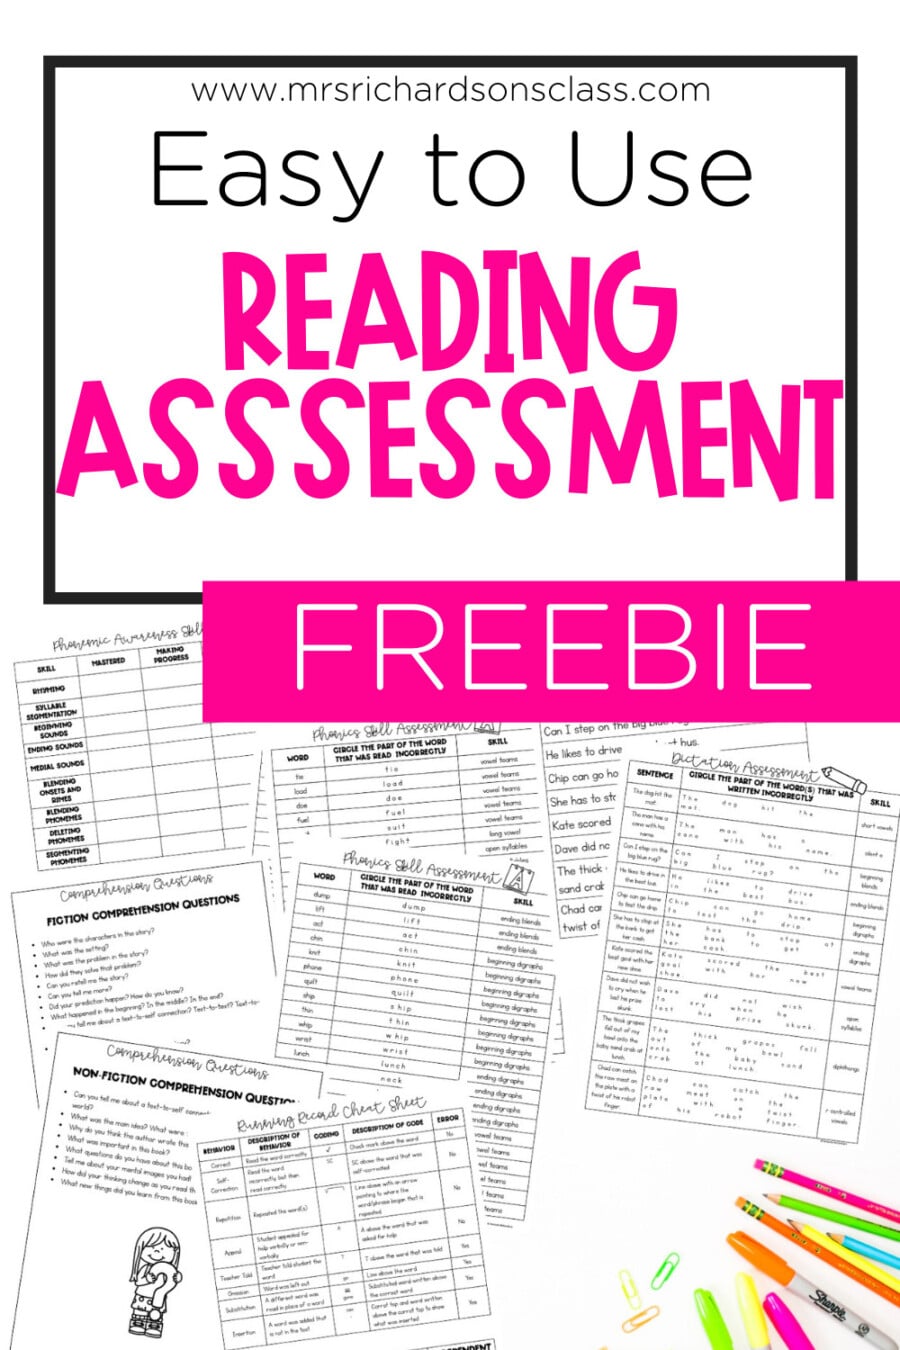
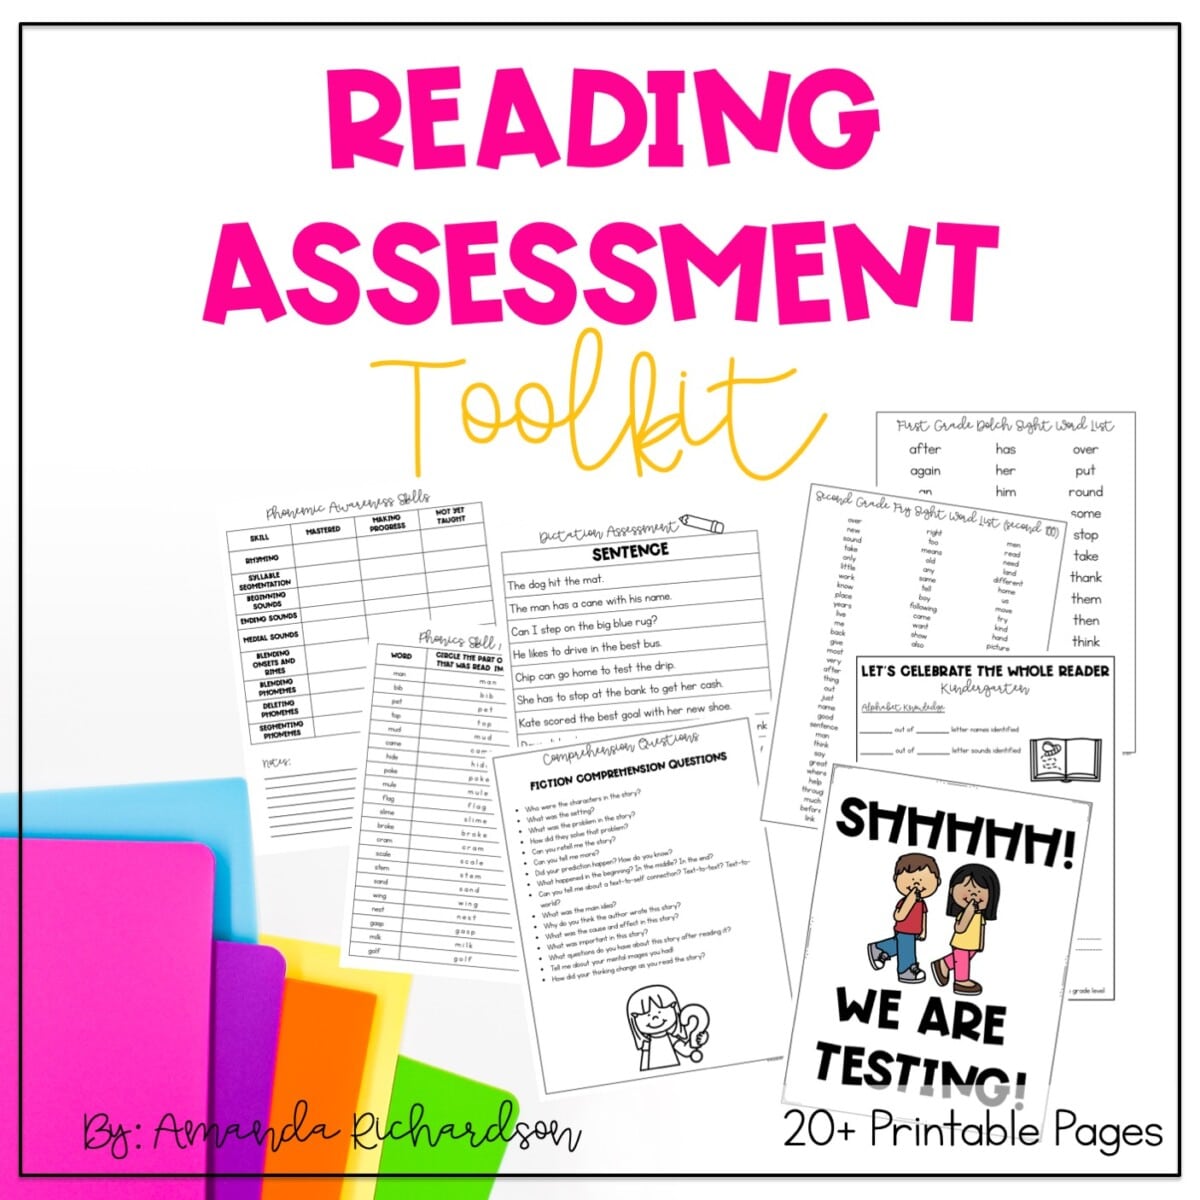
The software spits out a score and everyone treats it like gospel. I spent six years running reading labs before I stopped trusting those numbers at face value. The tools work, but they work on assumptions that break down the moment you look at a real classroom.What these tools actually measure Reading Assessment Tools generally fall into three buckets. Automated scoring engines grade multiple choice or short answer responses and produce a numerical score. Diagnostic platforms like DIBELS or AIMSweb measure foundational skills—phonemic awareness, fluency, basic comprehension—usually through timed oral readings. Then there are passage-based comprehension assessments that feed text into algorithms to estimate difficulty and measure reader performance against it.
Lexile and similar measures calculate readability from sentence length and word frequency. That's all. They don't account for vocabulary depth, cultural context, or whether the student has background knowledge about the topic. I had a student who scored two grade levels below in every automated tool but could dismantle a dense argumentative essay when we sat down together. She just panicked under timed conditions. The tool flagged her as struggling. She wasn't struggling. She was performing. The key decision is which passages you give them. Not all texts within a difficulty band are equal. A narrative about camping might be readable by every student at that Lexile level. An explanatory text about photosynthesis at the same level will separate kids who've done unit work from kids who haven't. The tool doesn't know that distinction. You have to. I build my own passage pools with roughly 40 percent academic text and 60 percent general interest. The academic portion captures skill transfer. The general portion keeps motivation up. Standardized tools assume uniform engagement across all passages. It doesn't happen. Score inflation on easy items followed by score collapse on hard items is the pattern I see in about a third of my testing groups every semester.
The counterintuitive part nobody teaches
Higher item counts don't equal better assessments. I tested this by running parallel forms with 10, 20, and 40 items on the same passage. The 10-item version and the 40-item version agreed on student classification about 78 percent of the time. The remaining 22 percent was almost entirely driven by the last half of the longer form, where fatigue sets in and guessing patterns emerge. More items mostly added noise.Another thing that surprises people: oral reading fluency and comprehension are weakly correlated after fourth grade. A kid can read fast and miss everything. Another reads slowly and reconstructs the argument accurately. The tool that rewards speed over accuracy is measuring the wrong thing, and it does it consistently across every major screening platform. I stopped using fluency-only benchmarks as placement decisions around fifth grade. I switched to paired oral reading with comprehension questioning. Takes three times longer per student. Cuts misplacement errors by roughly half based on my records over two academic years.
A specific edge case that cost me two weeks
I ran a district-wide screening using an automated tool that claimed adaptive passage sequencing. The algorithm adjusted difficulty based on performance. Halfway through the spring administration, I noticed a pattern: every student who answered three consecutive questions correctly received a passage that was noticeably easier than the previous one, but the score jumped dramatically anyway. The adaptive engine was rewarding streaks, not accuracy depth.I pulled the raw data and found that high-performing students were getting scored on passages well below their actual ability while low performers were stuck on the same mid-range text repeatedly because the item difficulty ceiling never pushed them higher. The tool's ceiling effect was silently capping the top quartile and its floor effect was hiding real struggles in the bottom quartile. The workaround was straightforward but tedious. I exported all responses, recalculated difficulty estimates using my own benchmarked passage values instead of the tool's adaptive output, and rescored manually for the affected students. That took about eight hours for a cohort of 200. The reclassified results changed intervention assignments for roughly twelve percent of the group. Not every change was downward, by the way. Several kids who looked competent were actually floating above their support level and needed the harder work, not an easier one.
Get the Full Details
What these tools miss entirely Background knowledge. Prior vocabulary exposure. Test anxiety. Visual processing differences that show up as reading errors but aren't reading problems. I've seen kids with undiagnosed astigmatism miscopy words during digital assessments and get flagged for decoding deficits. The optometrist cleared them in ten minutes.
These tools also can't measure inference-making quality or textual evidence use. A student might pick the right answer but for the wrong reason. The algorithm sees a correct response and moves on. It has no window into the reasoning path. That gap matters most in upper elementary and middle school when texts shift from literal to inferential demand. Growth tracking over a full year is where automated tools earn their keep. Single administrations are noisy. Year-over-year change within the same student smooths out a lot of the random error. I rely on those trends more than individual cut scores for program evaluation. The honest assessment is that Reading Assessment Tools give you signals, not answers. They point you toward questions that need human investigation. The ones who treat the output as definitive end up with misplaced interventions and kids who get bored or frustrated for the wrong reasons. The tool didn't create the problem. It just failed to see it clearly enough.
If you're building a screening battery, pair any automated system with a brief manual check on at least ten percent of your students. The mismatch rate I've observed across multiple tools and districts hovers around eight to fourteen percent depending on the population. That's not a defect in the tool. That's a feature of how human reading works. No algorithm captures it completely yet.