Why Ordinary Least Squares Fails With Counts
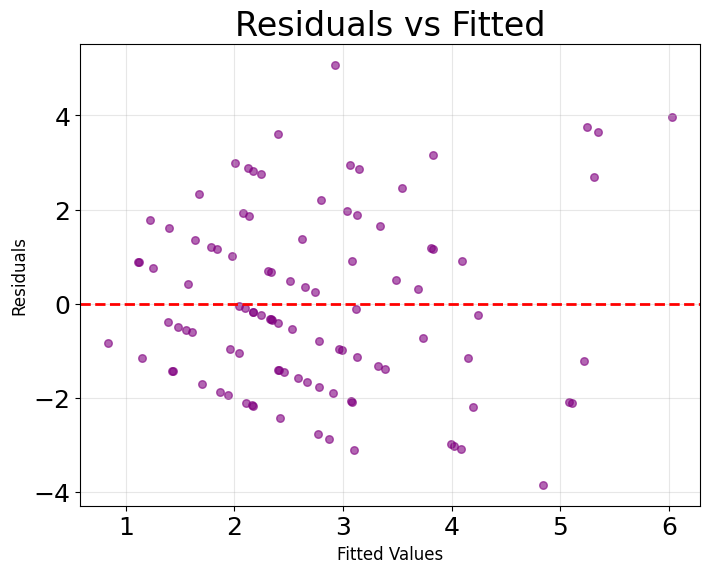
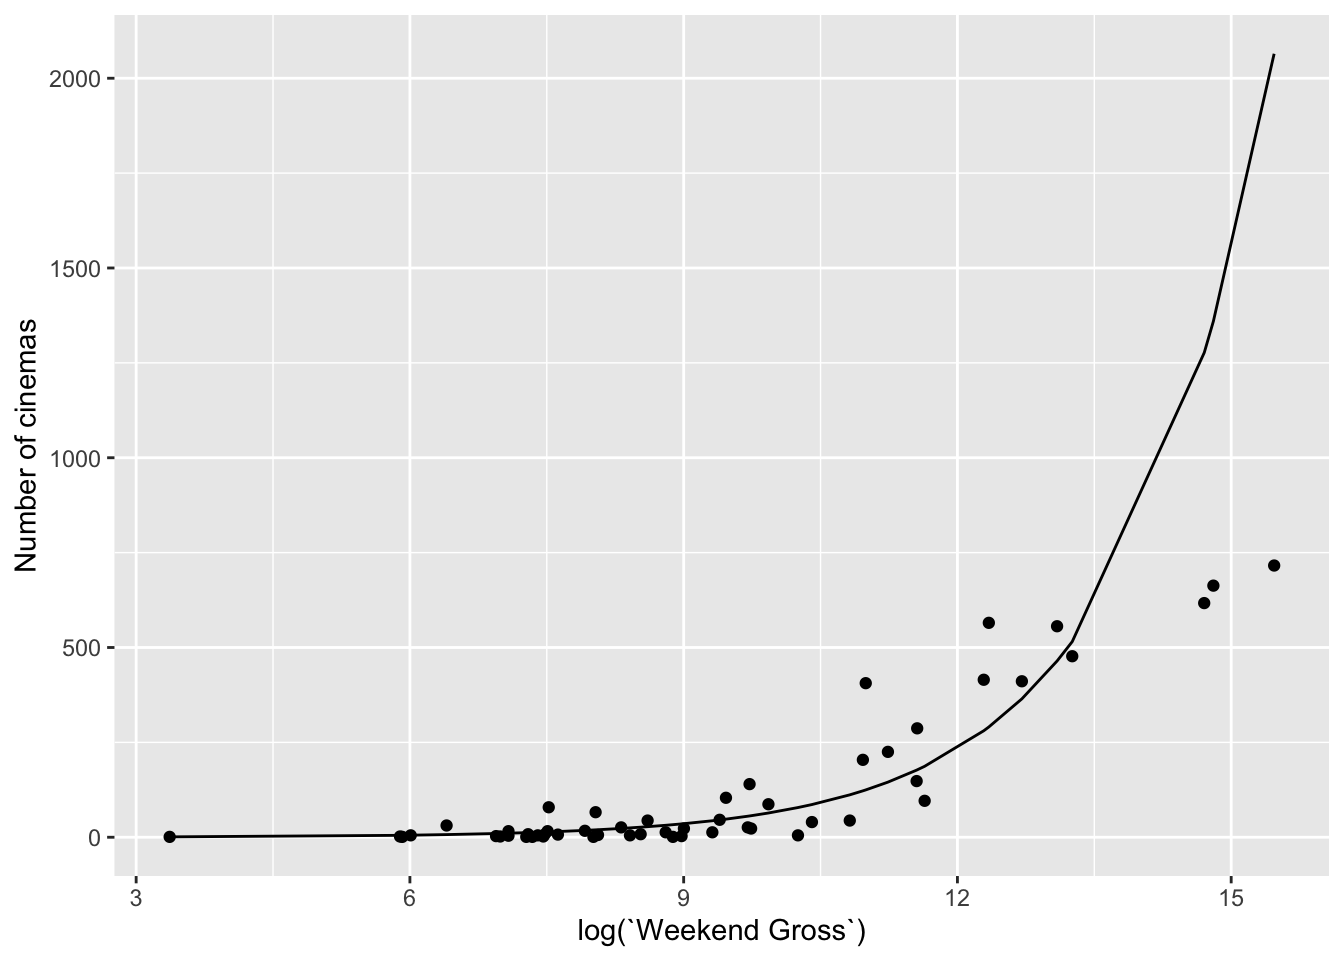
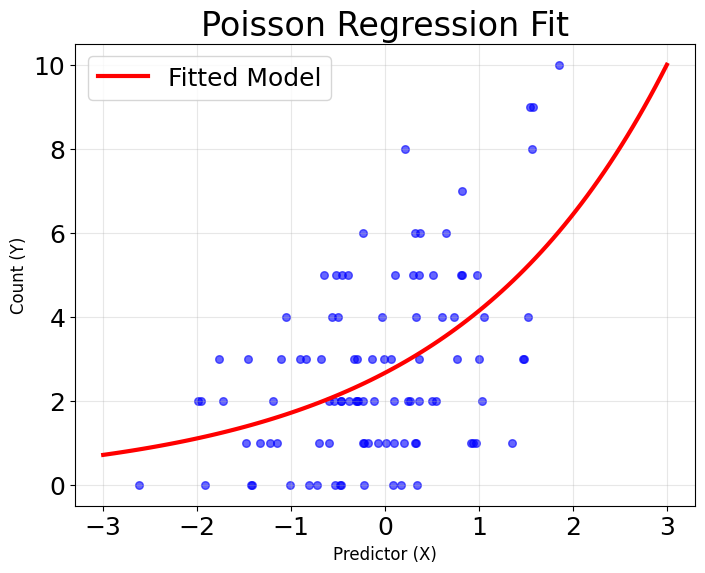
You run a Poisson regression on your data and the residual plot looks like a fan spreading open. The variance grows with the mean. Your standard errors are nonsense. This is the most common mistake I see in applied work, and it usually happens because someone tried to model a count outcome with regular linear regression anyway. Count data has a discrete support. It can't go below zero. The variance is tied to the mean by definition in a Poisson model, which means your residual diagnostics need to be interpreted differently than you're used to from OLS. The core idea is straightforward. You model the logarithm of the expected count as a linear combination of your predictors. This is the canonical link function for Poisson regression. The model outputs a rate parameter lambda for each observation, and the observed count follows a Poisson distribution with that parameter. In practice, you fit it with maximum likelihood estimation, usually through iteratively reweighted least squares. Most statistical packages will handle the fitting without any special configuration beyond specifying the family argument. The thing that trips people up is overdispersion. Your counts will often show more variability than the Poisson assumption allows. When the dispersion parameter phi is significantly greater than one, your standard errors are too small. You get inflated t-statistics. You think you have significant effects when you really don't. I spent three weeks debugging what I thought was a coding error before I realized my negative binomial model had the same fixed effects structure and the significance completely dissolved. The coefficients were in the same direction, just nowhere near as impressive.
Zero inflation is another real problem. If your data has more zeros than the Poisson or even the negative binomial would predict, standard models will systematically underestimate the probability of observing a zero. A zero-inflated Poisson or zero-inflated negative binomial adds a separate binary process that determines whether an observation comes from a structural zero group or from the count process. That's two models in one. The interpretation changes completely. The coefficients from the count portion tell you about the non-zero generating process only. You need to decide whether your zeros are meaningful structural zeros or just excess zeros from overdispersion. They are not always the same thing.
Fitting the Model in Practice
I use glm.nb from the MASS package in R for most work. It handles the dispersion parameter estimation alongside the regression coefficients, which saves you from having to manually calculate quasi-likelihood adjustments. The formula interface is identical to glm, so the transition is minimal. If you're working in Python, statsmodels has the Poisson and negative binomial families built in. The syntax is clean, but the diagnostic tools are less polished than what you get in R. Here's a concrete example from my own analysis last year. I was modeling the number of support ticket escalations per customer over a 90-day window. The raw data had a mean of 2.3 but a variance of 18.7. That's a dispersion ratio of roughly 8.1. A Poisson model would have given me confidence intervals that were maybe a quarter of their actual width. I switched to negative binomial immediately. The AIC dropped by about 400 points. The likelihood ratio test against Poisson was overwhelmingly significant. This is the kind of overdispersion that makes Poisson estimates practically unusable. When I initially fit the zero-inflated version out of habit, the Vuong test didn't favor it. The extra parameters weren't justified by the data. That's an important point that gets missed. Zero-inflation is not a default setting. You test for it. The Vuong test compares the standard negative binomial against the zero-inflated version. A non-significant result means you should stick with the simpler model. Parsimony matters here because zero-inflated models have identification issues. The two latent processes can absorb each other's effects, making coefficient interpretation unstable.
Get the Full Details
Diagnosis That Actually Matters
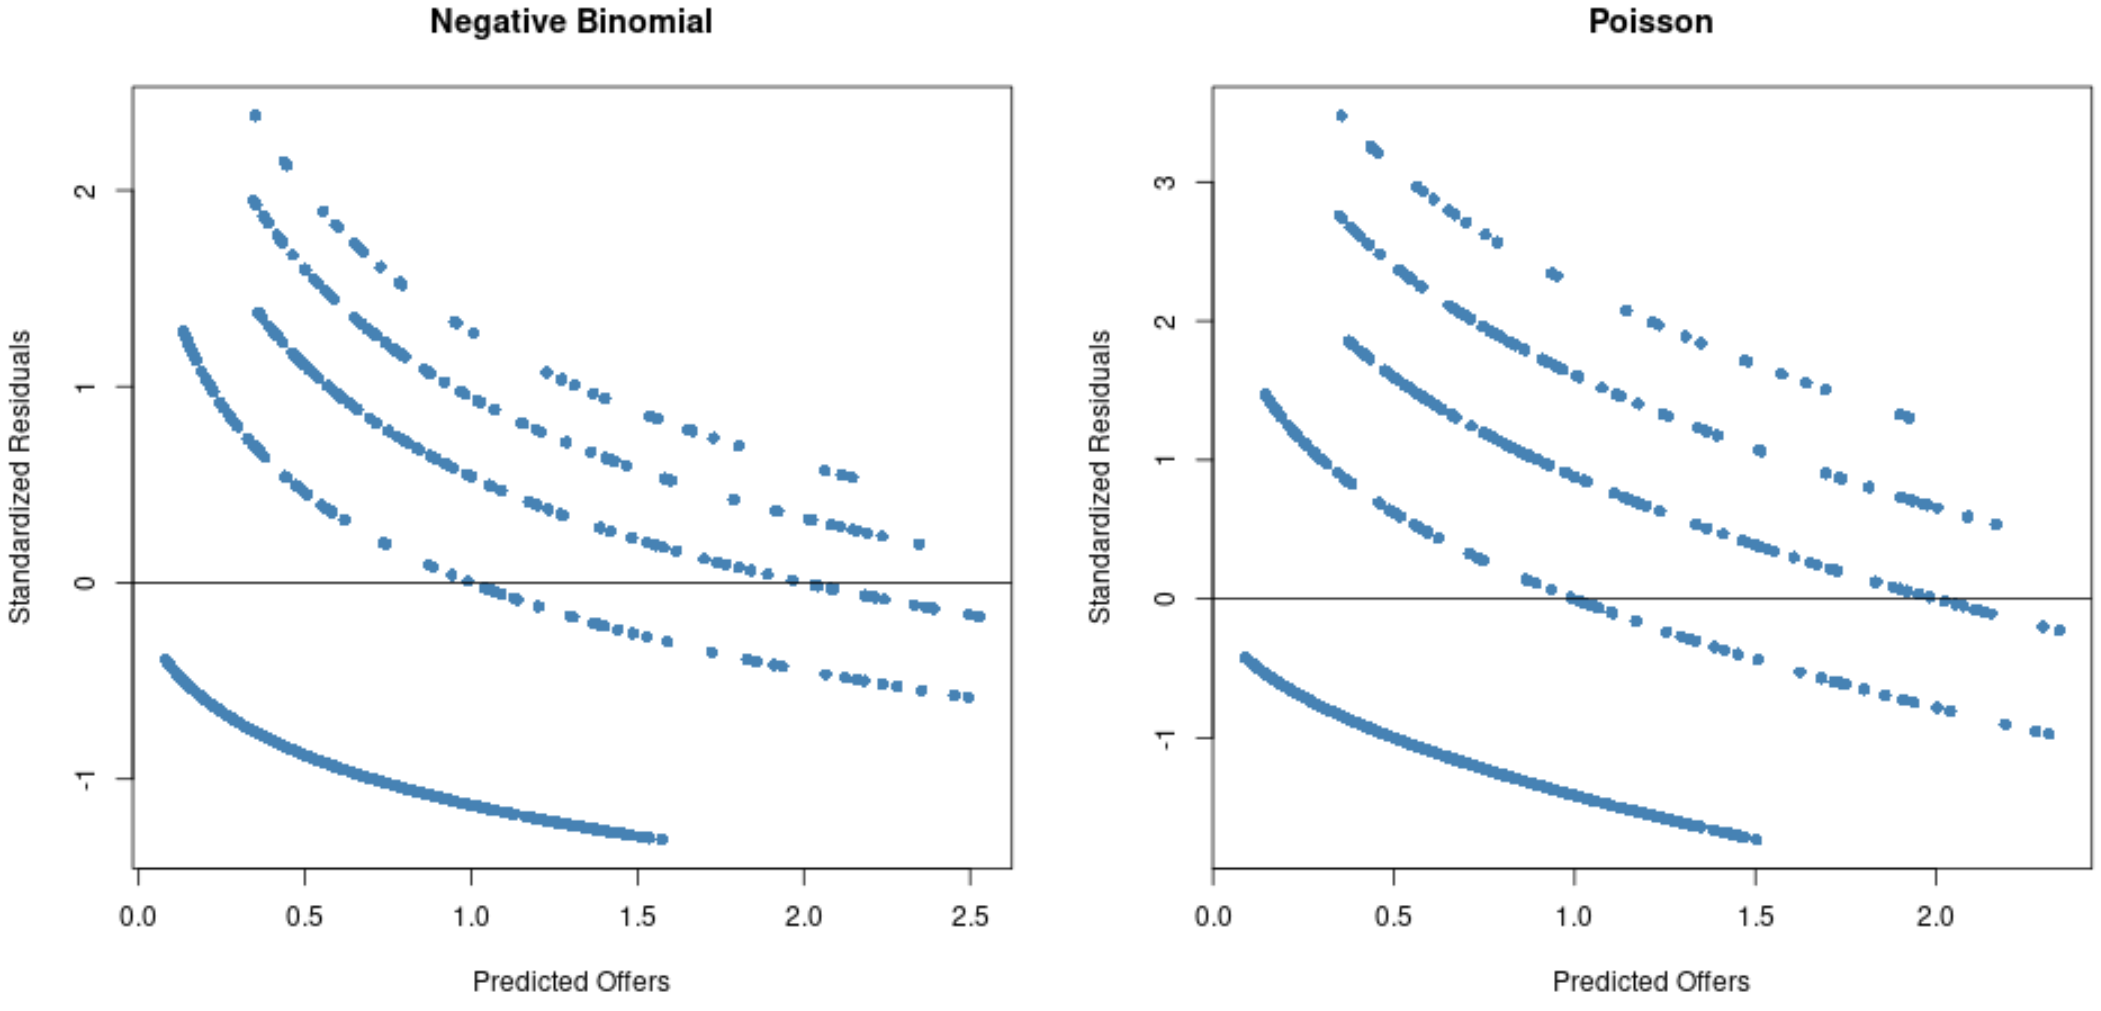
Don't just look at deviance residuals. Plot them against the fitted values using a Pearson residual instead. The standard deviance residual can be misleading with highly overdispersed data because it assumes the Poisson variance structure. Pearson residuals standardize by the actual fitted variance, which gives you a more honest picture. Check for influential observations with Cook's distance, but use the working weights from the last iteration of IRLS, not the raw data weights. Another thing I learned the hard way: check your dispersion parameter before you publish anything. In R, you can calculate it as the sum of squared Pearson residuals divided by the residual degrees of freedom. If it's above 1.5, you need a quasi-likelihood or a negative binomial model. Below 1.5 is usually fine for Poisson. Between 1.5 and 2.0 is a gray zone where both approaches might be defensible, but the negative binomial is the safer bet. Above 2.0, the Poisson is essentially wrong and you should move on.
When Count Regression Breaks Completely
There are scenarios where even the negative binomial won't save you. If your counts have a hard upper bound, like a maximum rating scale of 5 stars or a cap on daily transaction limits, the model will produce predicted values above that bound, which is impossible. In that case you're dealing with bounded count data and need a different approach entirely, such as a beta-binomial or a cumulative link mixed model depending on your structure. I ran into this with survey data where respondents could select between 0 and 10 complaints. The negative binomial predictions regularly exceeded 10. Switching to an ordinal logistic model was the right call, though it changes the interpretation from a rate to a latent threshold process. Panel data with fixed effects and count outcomes introduces the incidental parameters problem. The within-group transformation that eliminates fixed effects doesn't work cleanly for Poisson models. The conditional maximum likelihood approach exists but requires specialized software. Many analysts just ignore the problem with short panels, and while the bias is technically there, it becomes negligible once you have more than about 10 time periods per unit. With fewer periods than that, the fixed effects estimates will be biased toward zero, which again means you'll understate your effects.
Working Code
For anyone starting out, here's a minimal working example in R that covers the common cases. library(MASS)
library(sjPlot) Fit negative binomial
model_nb <- glm.nb(count ~ predictor1 + predictor2 + offset(log(exposure)), data = mydata)

Check dispersion
pearson_residuals <- residuals(model_nb, type = "pearson")
phi <- sum(pearson_residuals^2) / df.residual(model_nb)
print(phi) If phi > 1.5, stick with nb. If you suspect zero-inflation:
library(pscl)
model_zip <- zeroinfl(count ~ predictor1 + predictor2 | predictor3, data = mydata, dist = "negbin")
vuong.test(model_nb, model_zip) The offset term is important if your exposure varies across observations. Without it, you're modeling total counts rather than rates. If every observation has the same time window, you can skip it. If some customers were observed for 30 days and others for 90, the offset corrects for that difference. It's the difference between explaining why one customer has more complaints and explaining why they have a higher complaint rate.
Interpreting Output
Coefficients from a log-linked count model are on the log scale. Exponentiating them gives you incidence rate ratios. An IRR of 1.5 means a one-unit increase in the predictor multiplies the expected count by 1.5, holding everything else constant. This multiplicative interpretation is usually what people actually want, even when they ask for coefficients. Report both the raw coefficient and the exponentiated value with confidence intervals. The raw coefficient is needed for model comparison and prediction. The IRR is what your audience actually understands. Prediction with count models is tricky because of Jensen's inequality. The expected value of the exponentiated linear predictor is not the exponentiated expected value. If you need predictions on the original count scale, use the predict function with type = "response" and let the package handle the back-transformation through the link function. Don't manually exponentiate the linear predictor. You'll systematically underestimate the mean. I've seen this mistake in peer-reviewed papers.